Dancing with Qubits — From qubits to algorithms, embark on the Quantum Computing journey shaping our future: http://
amzn.to/4bJNwFj [2nd Edition] v/ @PacktDataML Covers Quantum Machine Learning and AI ——————
#ComputerScience #ComputationalScience
COMPUTING
-

Quantum Computing and Machine Learning: Practical Guide
By
–
-
Supply Chain Dependency and Non-Intermittent Energy Requirements
By
–
So you missed the whole point about supply chain dependency, and the need for high density non intermittent energy.
-
Buy a GPU to Run Your Entire System Locally
By
–
a person interviewing an ai
— Yohei (@yoheinakajima) 19 mars 2026
this is a format we're going to see a lot more of https://t.co/pvfF3nbNeJa person interviewing an ai this is a format we're going to see a lot more of
-
NumPy and APL: Understanding Different Programming Models
By
–
No, numpy has some overlaps with APL, but it's a vastly different programming model.
-
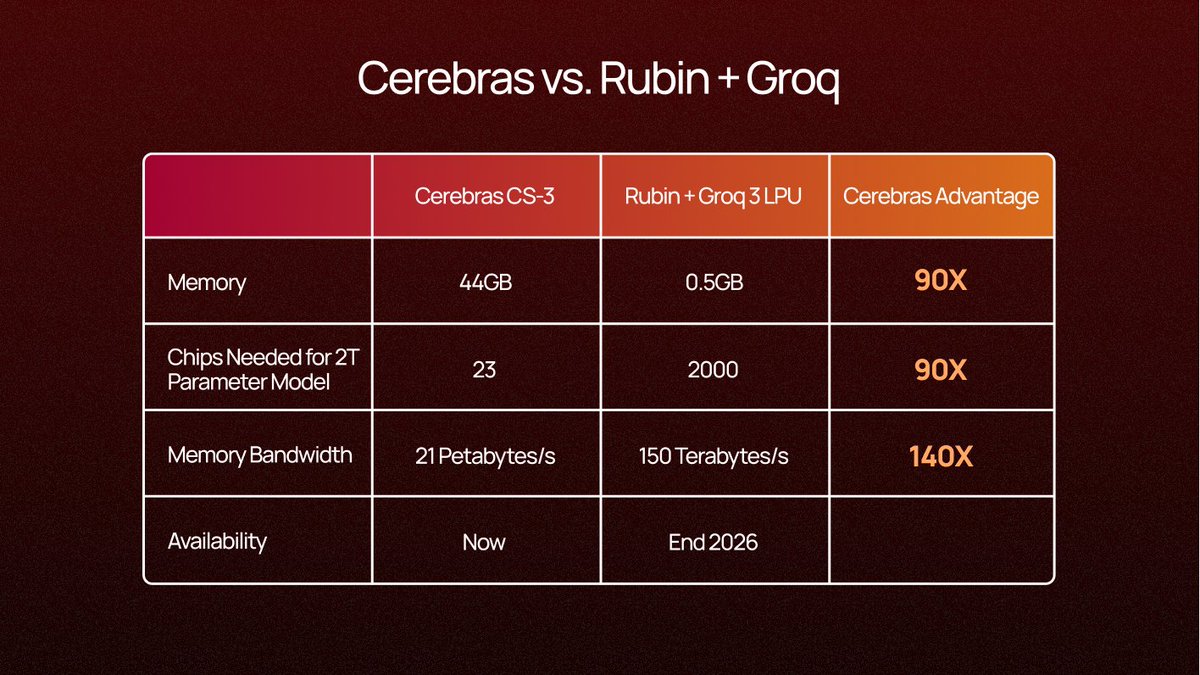
Cerebras Wafer Scale Advantage Over NVIDIA Groq Inference Chips
By
–
Problem solved. ✅ Andrew Feldman (@andrewdfeldman) NVIDIA's biggest GTC announcement was a $20 billion bet on the same problem we solved 6 years ago. Their next-gen inference chip – not available yet – has 140x less memory bandwidth than @cerebras. To run a single 2 trillion parameter model, you need 2,000+ Groq chips. On Cerebras, that's just over 20 wafers. Even paired with GPUs, Groq maxes out at ~1,000 tokens per second. We run at thousands of tokens per second today. And every day. In production now. Why? When you connect 2,000 chips together, every interconnect has latency. Every cable has overhead. It doesn't matter what your memory bandwidth is on paper if you're bottlenecked by the wiring between thousands of tiny chips. We solved this with wafer scale. One integrated system. Little interconnect tax. Jensen told the world that fast inference is where the value is. He’s right – it’s why the world’s leading AI companies and hyperscalers are choosing Cerebras. — https://nitter.net/andrewdfeldman/status/2034015373595672594#m
-
Microsoft Fabric Guide: Discovery to Unified Data Platform
By
–
The Definitive Guide to Microsoft Fabric — From discovery to building a unified, secure, and scalable data platform: http://
amzn.to/3MdE1Xk v/ @PacktDataML Table of Contents: Getting started with Fabric From Lakehouse to First Analysis Unifying Data in OneLake -

RTX PRO GPU: Why Unified Memory Limits Multi-Agent Concurrency
By
–
RTX PRO for sure, the below is relevant as to why Unified Memory isn’t ideal for concurrency/multi-agents
-
Cutting-Edge Hardware Inference Stack Delivered at NVIDIA GTC
By
–
Our crew had a blast at @NVIDIAGTC this week The biggest takeaway? We're delivering exactly what the ecosystem needs: a cutting-edge hardware inference stack built for speed, scalability, and efficiency.
-
Perplexity Health Computer Integrates Wearables and Medical Records
By
–
Perplexity Health Computer https://t.co/TL01ZSjSpK
— Aravind Srinivas (@AravSrinivas) 19 mars 2026Perplexity Health Computer Perplexity (@perplexity_ai) Perplexity Computer now connects to your health apps, wearable devices, lab results, and medical records. Build personalized tools and applications with your health data, or track everything in your health dashboard. — https://nitter.net/perplexity_ai/status/2034668608375382346#m
→ View original post on X — @aravsrinivas, 2026-03-19 18:04 UTC
-
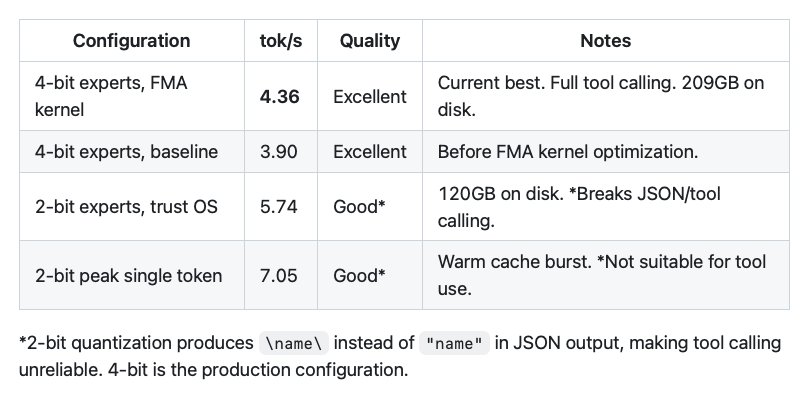
4-bit Quantization Fixes Tool Calling Performance Issues
By
–
Dan found that the 2-bit quantization broke tool calling but upgrading to 4-bit (at 4.36 tokens/second) got that working