Scaling laws help AI developers predict the performance of large language models, but they require expensive compute power. Stanford scholars developed a new method that reduces training demands:
COMPUTING
-
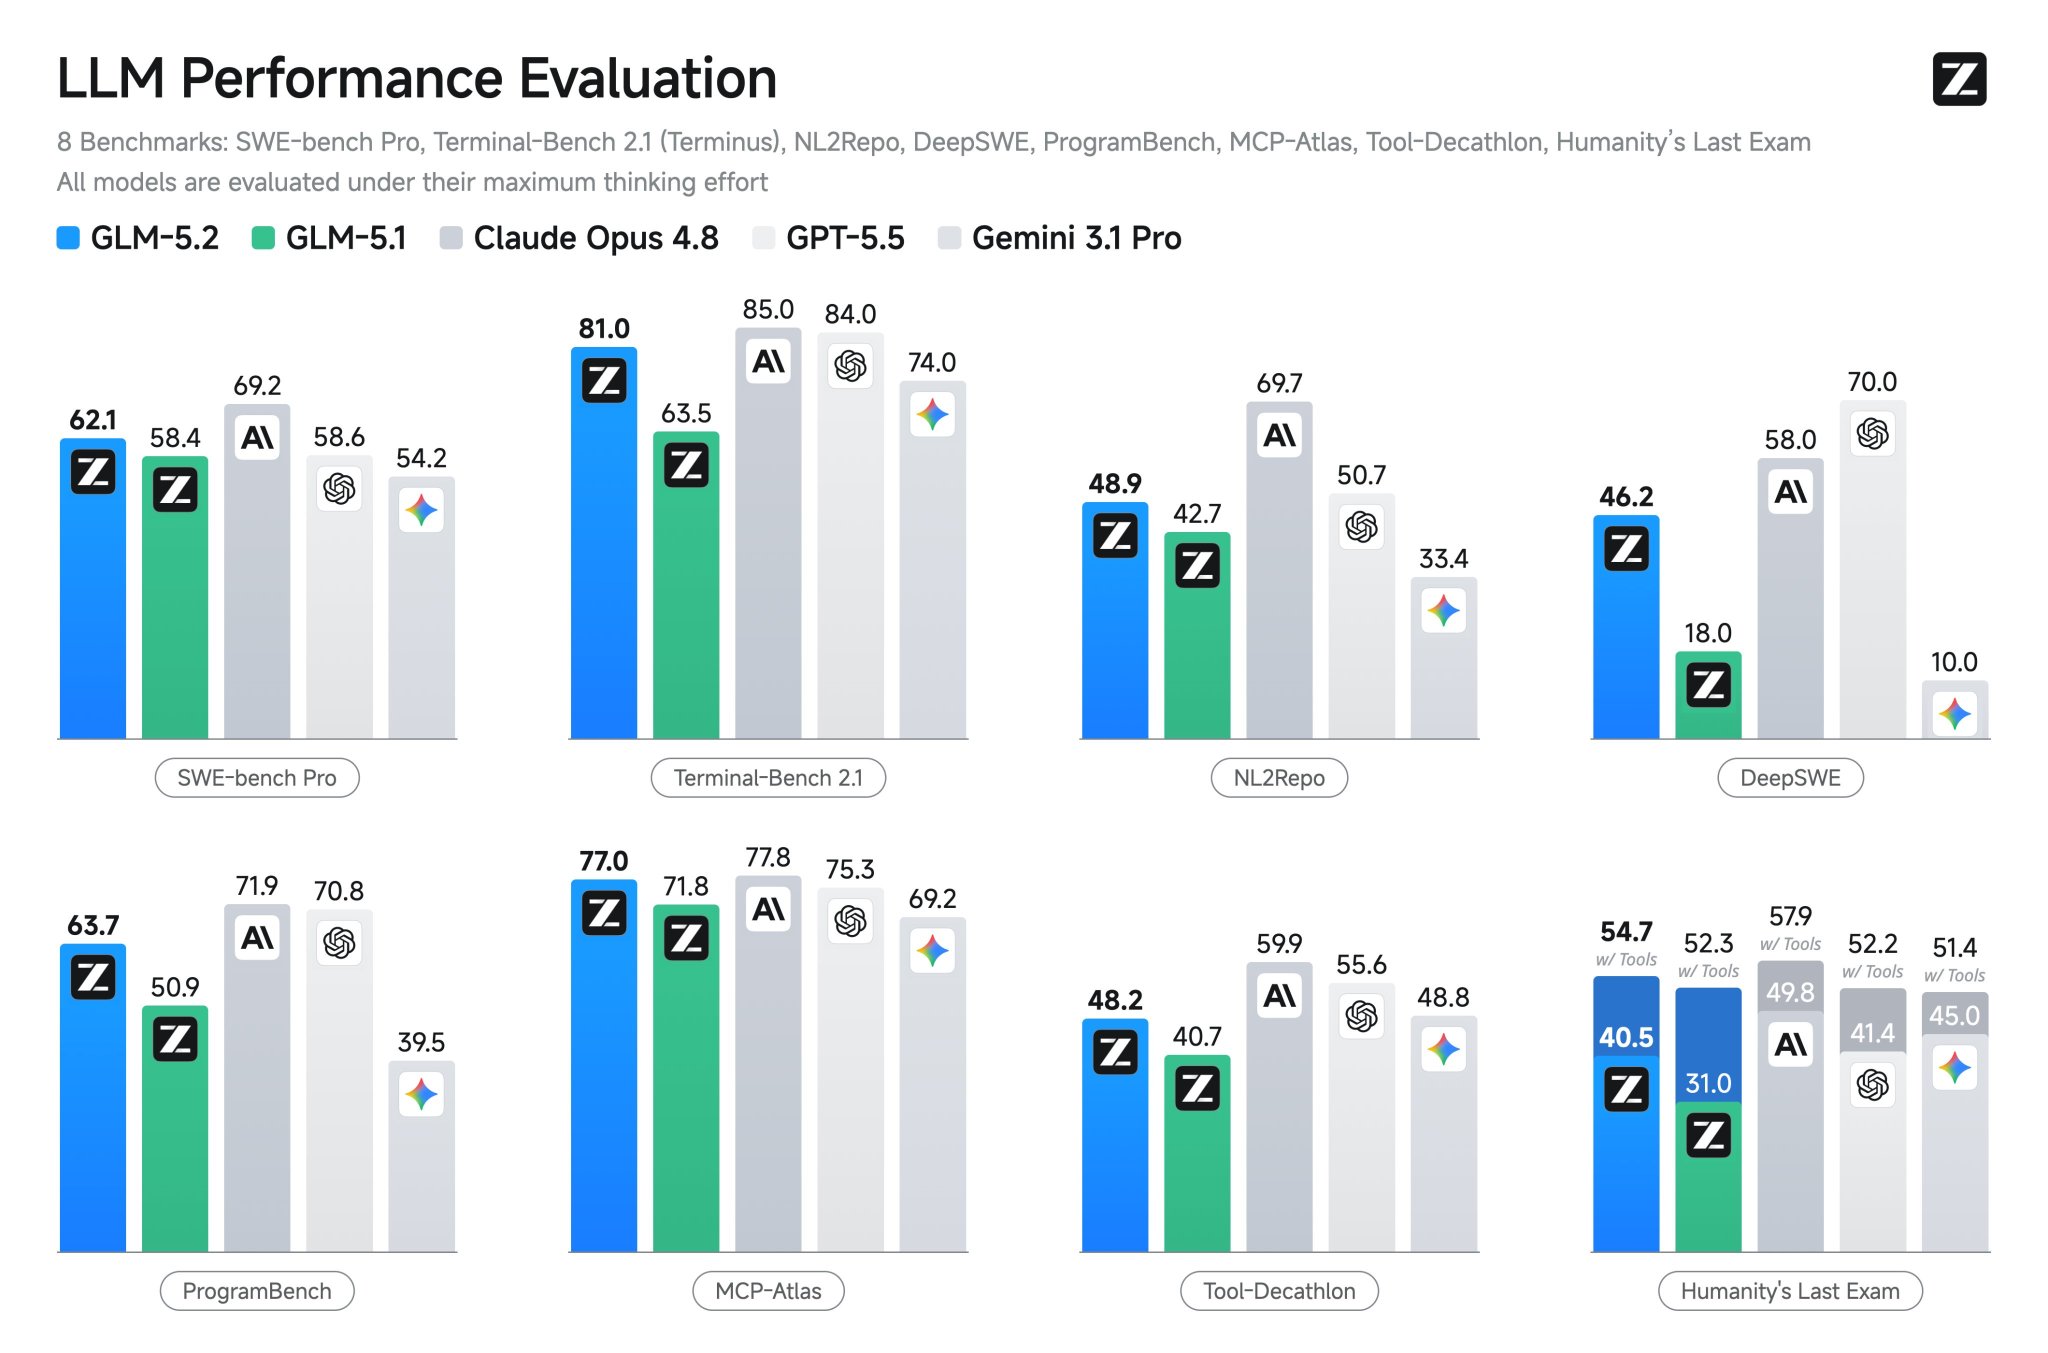
GLM-5.2 open-source model matches Claude Opus 4.8
By
–
@ZAI_ORG JUST DROPPED GLM-5.2, AND IT IS PUNCHING RIGHT AT THE LEVEL OF CLAUDE OPUS 4.8 The kicker? It’s a 753B parameter model with a true 1M-token context, released fully open-source under an MIT license What makes this release technically interesting: → IndexShare
-
GB300 NVL72 delivers 1.6x performance on DeepSeekV3 pretraining
By
–
Correction: GB300 NVL72 delivers 1.6x performance on DeepSeekV3 pretraining at 512 GPU scale. (Ref: results 6.0-0022 and 6.0-0101)
-
Model crumbles due to weak infrastructure and pipelines
By
–
Even a flawlessly tuned model crumbles under real-world production demands if the underlying data pipelines and legacy enterprise infrastructure can't support the required latency and continuous deployment cycles.
-
Detecting infrastructure gaps early ensures AI production success
By
–
Spotting infrastructure gaps early makes all the difference when dealing with data volume and legacy bottlenecks. Building that strong foundation is exactly what separates successful production AI from permanent pilots.
-
Models Will Disrupt Workflows; Infrastructure and Hardware Are Permanent Moats
By
–
Models will eat into Workflows Infra and Hardware are forever
always needed, always evolving Everything else has no real moat -
IneffableLabs builds super-learner with NVIDIA Vera Rubin NVL72
By
–
@IneffableLabs builds a super-learner that learns from experience, requiring enormous compute scale. They chose NVIDIA Vera Rubin NVL72, one of the largest clusters on @GoogleCloud, to power their mission to achieve superintelligence.
-
Comment on Microsoft’s fine-tuned version of DS4 on Azure
By
–
yeah, but a MSFT fine-tuned version of DS4 on azure
-
Nemotron 3 Ultra and the Open Model Landscape broadcast
By
–
Nemotron 3 Ultra and the Open Model Landscape | Nemotron Labs https://
x.com/i/broadcasts/1
rGmqqeRorDGy
… -

Long video reasoning with DeepSeek sparse attention and multimodal MoE
By
–
"Kwai Keye-VL-2.0 Technical Report" This paper makes long-video reasoning much more feasible by adapting DeepSeek Sparse Attention to a GQA-based multimodal MoE, reaching 256K context with only 3B active parameters. As dense attention makes hour-level context way too expensive,