
@IEEE Life Member conference begins in Austin!
COMPUTING
-

Data AI Summit Early Bird Registration Discount Ends April 30
By
–
Early bird catches the worm Save $400 by registering for #DataAISummit before April 30! You’ll explore the latest advances in #ApacheSpark, Delta Lake, MLflow, LangChain, PyTorch, dbt, and more: https://
bit.ly/3UlaDA7 -
Programmers vs Mathematicians: Variable Naming Philosophy
By
–
Programmers: Always use descriptive variable names
Mathematicians: Single letter variable names always, ideally from obscure/dead alphabets -

NLP Cross-Field Engagement Declined Significantly Since 1980
By
–
10/ The Influence Between NLP and Other Fields – aims to quantify the degree of influence between 23 fields of study and NLP; the cross-field engagement of NLP has declined from 0.58 in 1980 to 0.31 in 2022…
-
AWS reliability advantage: 15-year track record stability matters
By
–
That's one of AWS's biggest advantages in my mind – they have about a 15 year track record of not breaking stuff Anyone else who wants to build up that kind of track record needs to spend 15 years doing it
-
AWS Reliability and Product Trust in Cloud Computing
By
–
Yeah that's true, AWS are uncommonly good at keeping their stuff working – not just boto3 but all of their AWS products in general I don't trust anyone else though!
-
Client Libraries Breaking Changes: Trust Issues in API Wrappers
By
–
… which is a bit unintuitive because one would expect that part of the promise of client libraries would be insulating their users from breaking changes made to the JSON APIs that they wrap I have been burned enough times now: I don't trust vendor client libraries not to break
-
PyTorch Optimization: torch.compile vs Vanilla Performance
By
–
this isn’t comparing to torch.compile, which is the torch-native optimized version, it’s comparing to vanilla pytorch which is notoriously bloated and slow 🙂
-
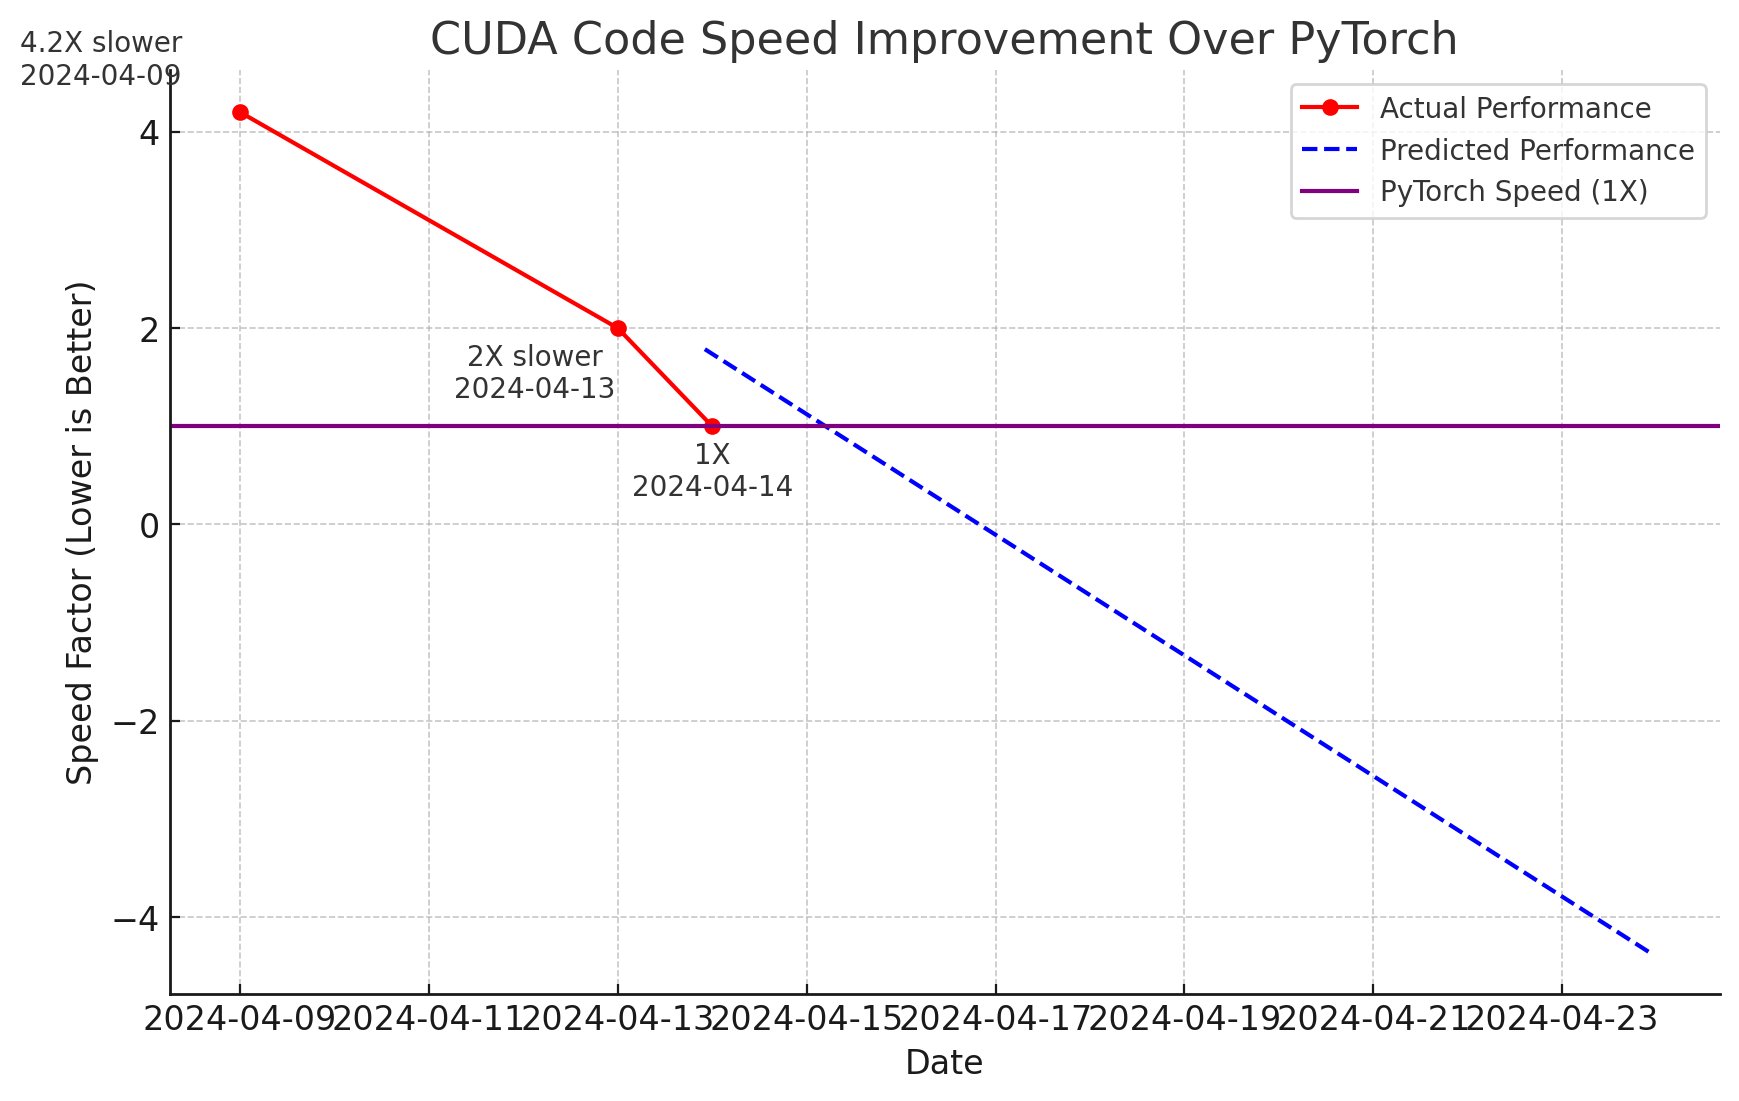
llm.c Optimization: Matching PyTorch Performance After Bug Fix
By
–
Highly amusing update, ~18 hours later: llm.c is now down to 26.2ms/iteration, exactly matching PyTorch (tf32 forward pass). We discovered a bug where we incorrectly called cuBLAS in fp32 mathmode . And ademeure contributed a more optimized softmax kernel for very long rows
-
ONNX WebAssembly Trade-offs in AI Model Deployment
By
–
i’m very skeptical that that’s a better decision than just using onnx wasm or whatever else is available