don't spoil my next vibe coding project please
CODE
-

Mitigating LLM Repetition via Probabilistic Sampling
By
–
LLMs have a repetition problem. ask for a joke → same joke every time ask to roll dice → always returns 4 ask for creative ideas → predictable garbage Try this instead: Generate 5 responses with their corresponding probabilities, sampled at random from the tails of the
-
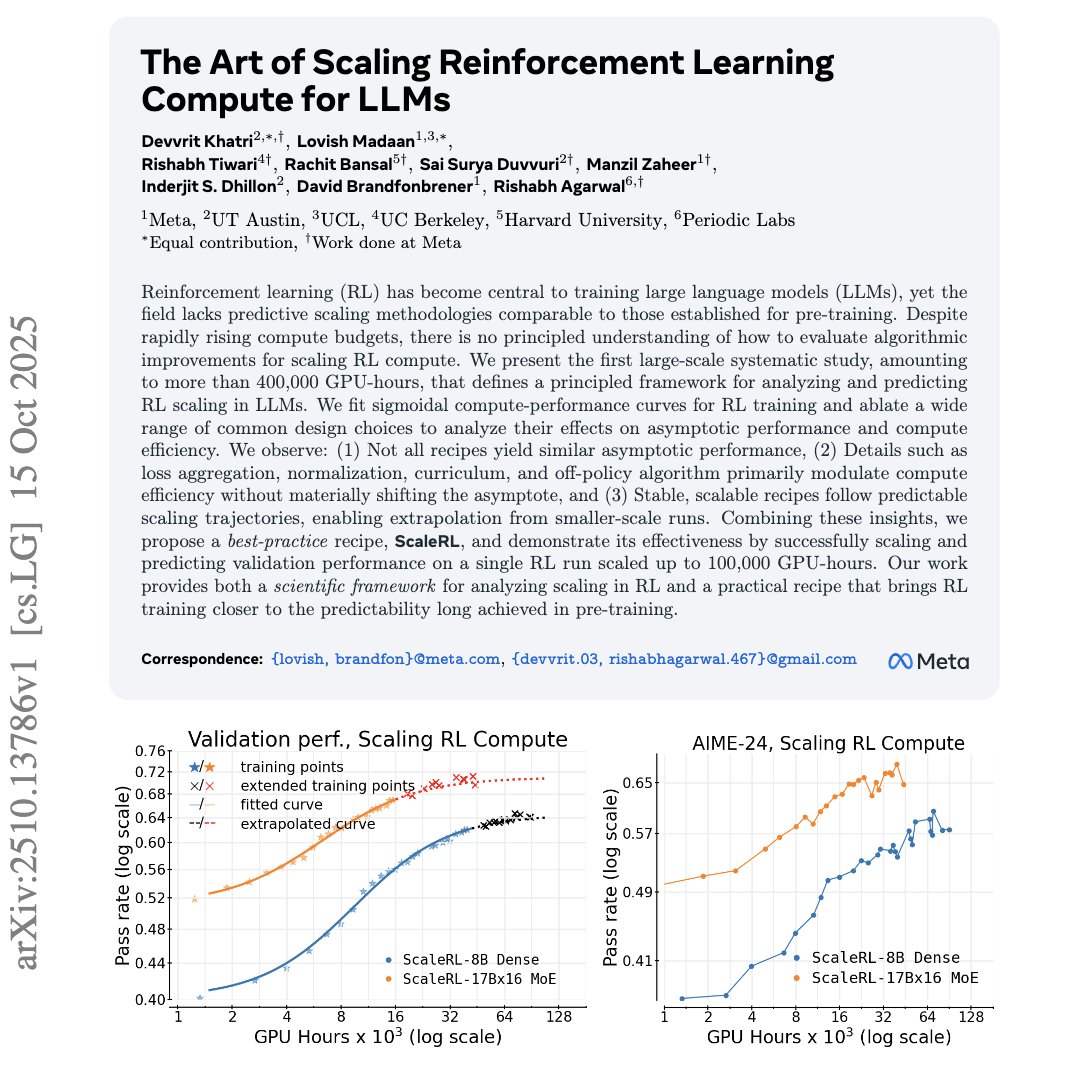
Meta’s ScaleRL reveals predictable RL scaling laws
By
–
Holy shit… Meta just cracked the art of scaling RL for LLMs. For the first time ever, they showed that "reinforcement learning follows predictable scaling laws" just like pretraining. Their new framework, 'ScaleRL', fits a sigmoid compute-performance curve that can forecast
-
Zed Now Supports Codex Integration Through ACP
By
–
Codex @zeddotdev As of today, Zed supports Codex out-the-box via ACP!
-
Python Skills and Workflow Automation for LLM Reliability
By
–
The ability to save Python scripts as skills is brilliant. We did something similar with @Lutra_AI where you can save workflows that work as playbooks (which are essentially python functions). You get the flexibility of the LLM, with the reliability of code when you reuse it.
-
Windsurf launches SWE-grep for faster context retrieval
By
–
Windsurf announced SWE-grep and SWE-grep-mini models for faster context retrieval. These models are now available on Windsurf!
— 🚨 AI News | TestingCatalog (@testingcatalog) 16 octobre 2025
TPS 🤯 https://t.co/E3QgCw8ndK pic.twitter.com/VMWuFaUDRrWindsurf announced SWE-grep and SWE-grep-mini models for faster context retrieval. These models are now available on Windsurf! TPS
-
Release AI Models and Datasets to Community
By
–
Really cool! You should release some models or datasets in open-source for the community!
-
1B Parameter Model: 128K Context, Int4 Quantization, Llama 4 Distilled
By
–
chat is this real??? 128K context, int4 quantisation, 1B params, distilled from Llama 4
-
Rubrics: Framework for Structured LLM Evaluation and Dataset Quality
By
–
Rubrics are the framework that make this possible. They connect human insight, LLM evaluation, and measurable outcomes — turning expert judgment into structured, repeatable metrics that drive confidence in every dataset.
-
Anthropic Releases Agent Skills for Extended Claude Capabilities
By
–
New on the Anthropic Engineering Blog: Our tips for developers on using Agent Skills, a new way to extend Claude's capabilities with instruction folders, scripts, and resources: