
"As of May 2026, more than 80% of the code we merge into Anthropic’s codebase was authored by Claude." Matches independent measures. There really is no sign this is slowing down (which doesn't mean there aren't organizational challenges to absorbing this much productivity gain)
CODE
-
New course on serving LLMs efficiently with Red Hat
By
–
New course on serving LLMs efficiently — how do you serve models to many concurrent users at low latency and reasonable cost? This short course is built with @RedHat and taught by @cedricclyburn.
— Andrew Ng (@AndrewYNg) 4 juin 2026
Efficient LLM serving requires efficient memory management. A 70B-parameter model… pic.twitter.com/KeKveT2IicNew course on serving LLMs efficiently — how do you serve models to many concurrent users at low latency and reasonable cost? This short course is built with @RedHat and taught by @cedricclyburn
. Efficient LLM serving requires efficient memory management. A 70B-parameter model -

AI Research: Claude’s Improved Decision-Making Outperforms Humans
By
–
AI research is a series of next-step decisions. We looked at sessions where a human researcher took a wrong turn, showed Claude the session up to that point, and asked it what to do next. Mythos Preview improved on humans 64% of the time—up from 22% in 2024.
-
AI Self-Improvement Plausible if Trends Continue, But Research Judgment Lacks
By
–
None of this guarantees recursive self-improvement is on the horizon. It’s not yet clear that Claude is capable of research judgment—of choosing the right problems to work on. But if these trends continue, AI systems designing and building their own successors is plausible. This
-
Anthropic’s AI models show massive speedup in code training tasks
By
–
Each time we release a model, we run the same test: give it code that trains a small AI model, ask the new model to speed it up. It takes a skilled human 4-8 hours to reach 4x faster. In May 2024, Claude Opus 4 averaged a ~3x speedup. This April, Mythos Preview achieved ~52x.
-

Claude’s coding success jumps 50 points, rivaling human quality
By
–
The speedup isn’t just in volume. On open-ended coding problems where answers are unclear, Claude’s success rate is now 76%—a 50 point jump in just 6 months. Many engineers also say Claude’s code quality is now on par with human code; we expect it to be better within the year.
-
Clippy is back, powered by new Microsoft MAI models for code judgment
By
–
CLIPPY 👏 IS 👏 BACK 👏
— Charly Wargnier (@DataChaz) 4 juin 2026
but this time he’s powered by frontier AI models ready to judge your code 🙈
Microsoft’s new MAI models just dropped on @aimlapi
They recreated Windows XP using MAI-Thinking-1 + @crewAIInc, and brought our fave assistant to life using MAI-Image 2.5 👀↓ https://t.co/AkCibYJJFyCLIPPY IS BACK but this time he’s powered by frontier AI models ready to judge your code Microsoft’s new MAI models just dropped on @aimlapi They recreated Windows XP using MAI-Thinking-1 + @crewAIInc
, and brought our fave assistant to life using MAI-Image 2.5 ↓ -

How a root agents.md ensures @agents .md is always created
By
–
in claude md just @agents
.md always i have a root agents md that tells agents when setting up new directories or repos to always do that. -
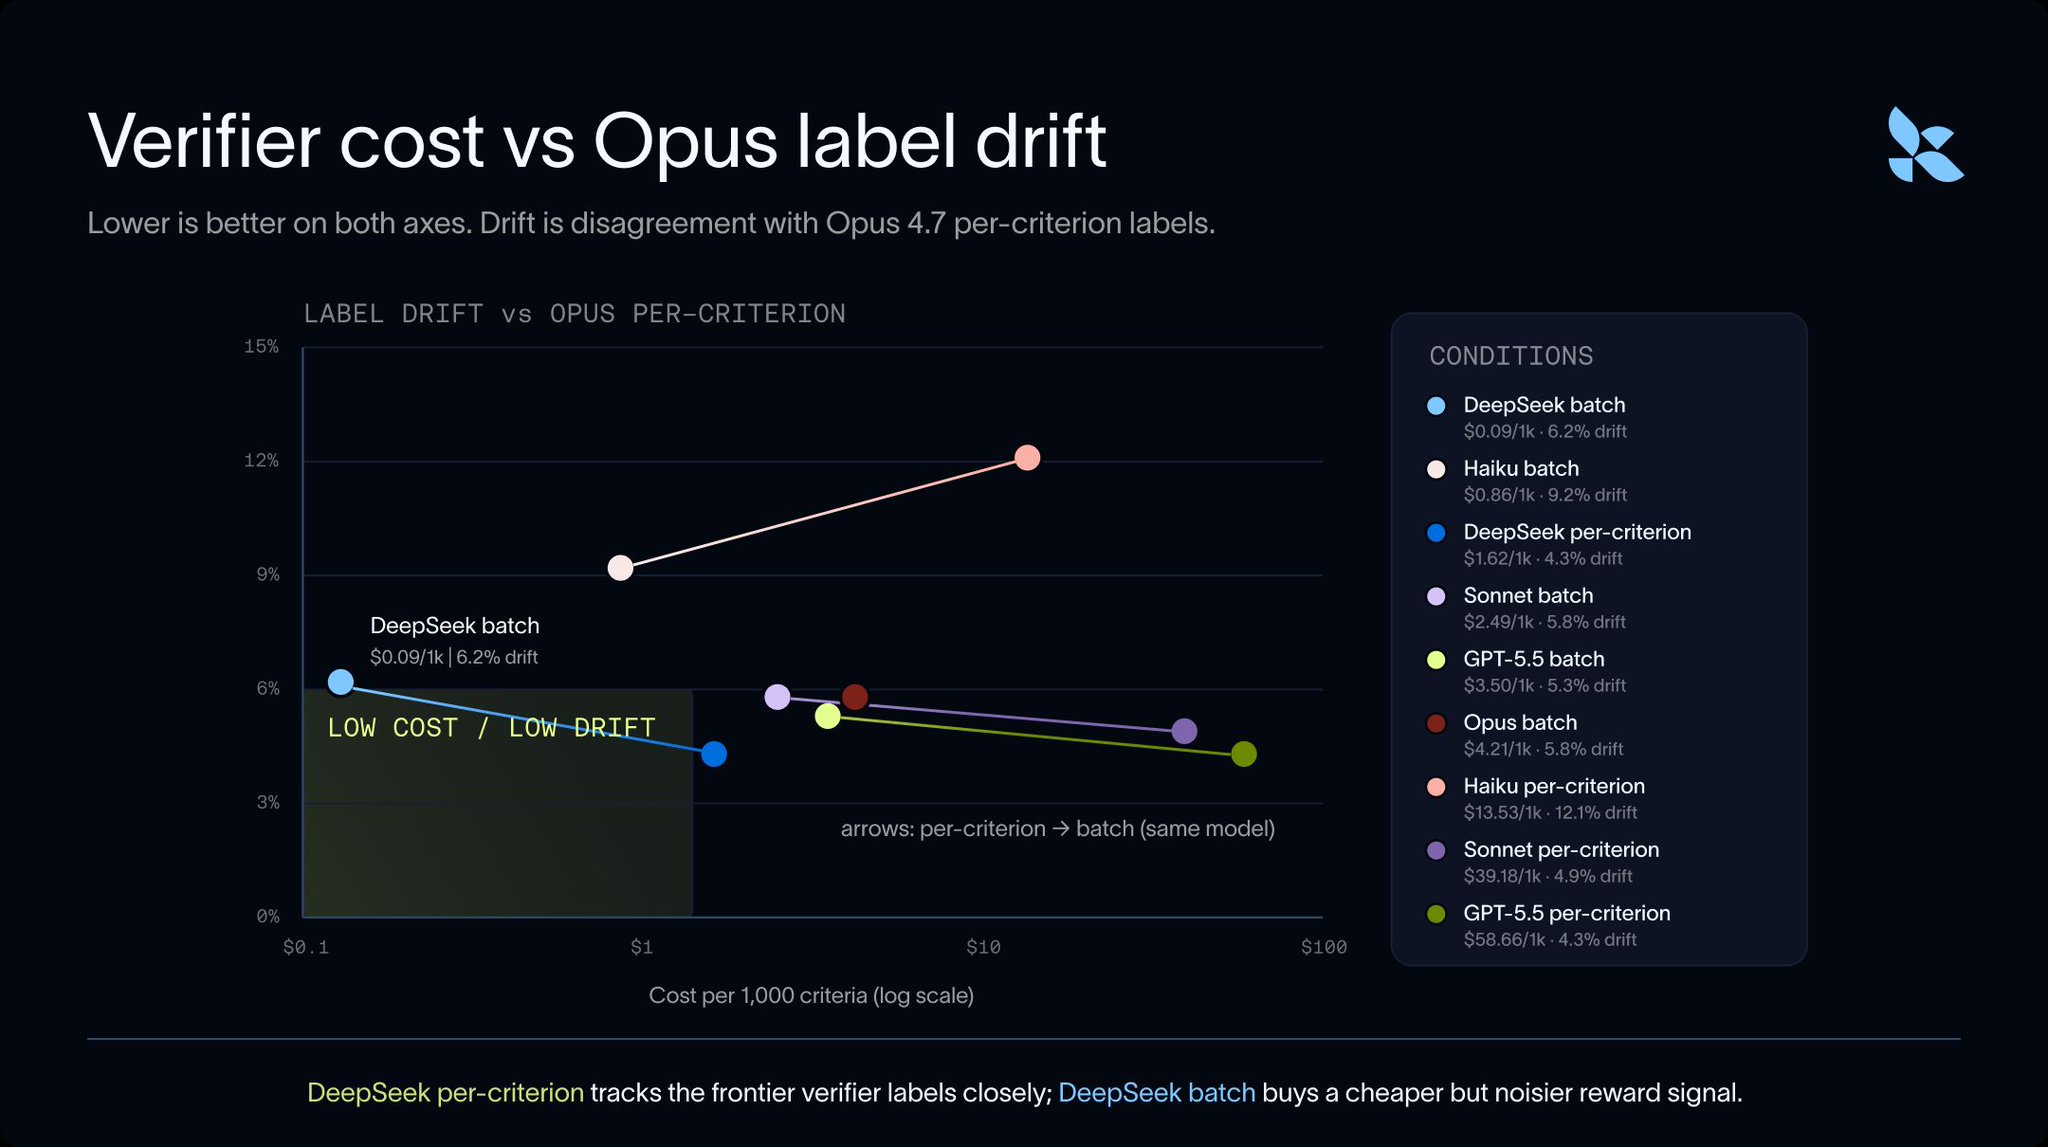
LangChain Labs study with Harvey on verifier efficiency benchmarking
By
–
In our LangChain Labs study with @Harvey
, we looked at how to measure efficiency across verifier designs. We benchmarked 5 setups against Sonnet per-criterion as the reference. -
Full study on efficient verifiers for legal agents
By
–
Read our full study: https://
langchain.com/blog/designing
-efficient-verifiers-for-legal-agents
…?