Frontier models are now world-class vulnerability researchers, but they’re currently better at finding vulnerabilities than exploiting them. This is unlikely to last. We urge developers to redouble their efforts to make software more secure. Read more:
CODE
-
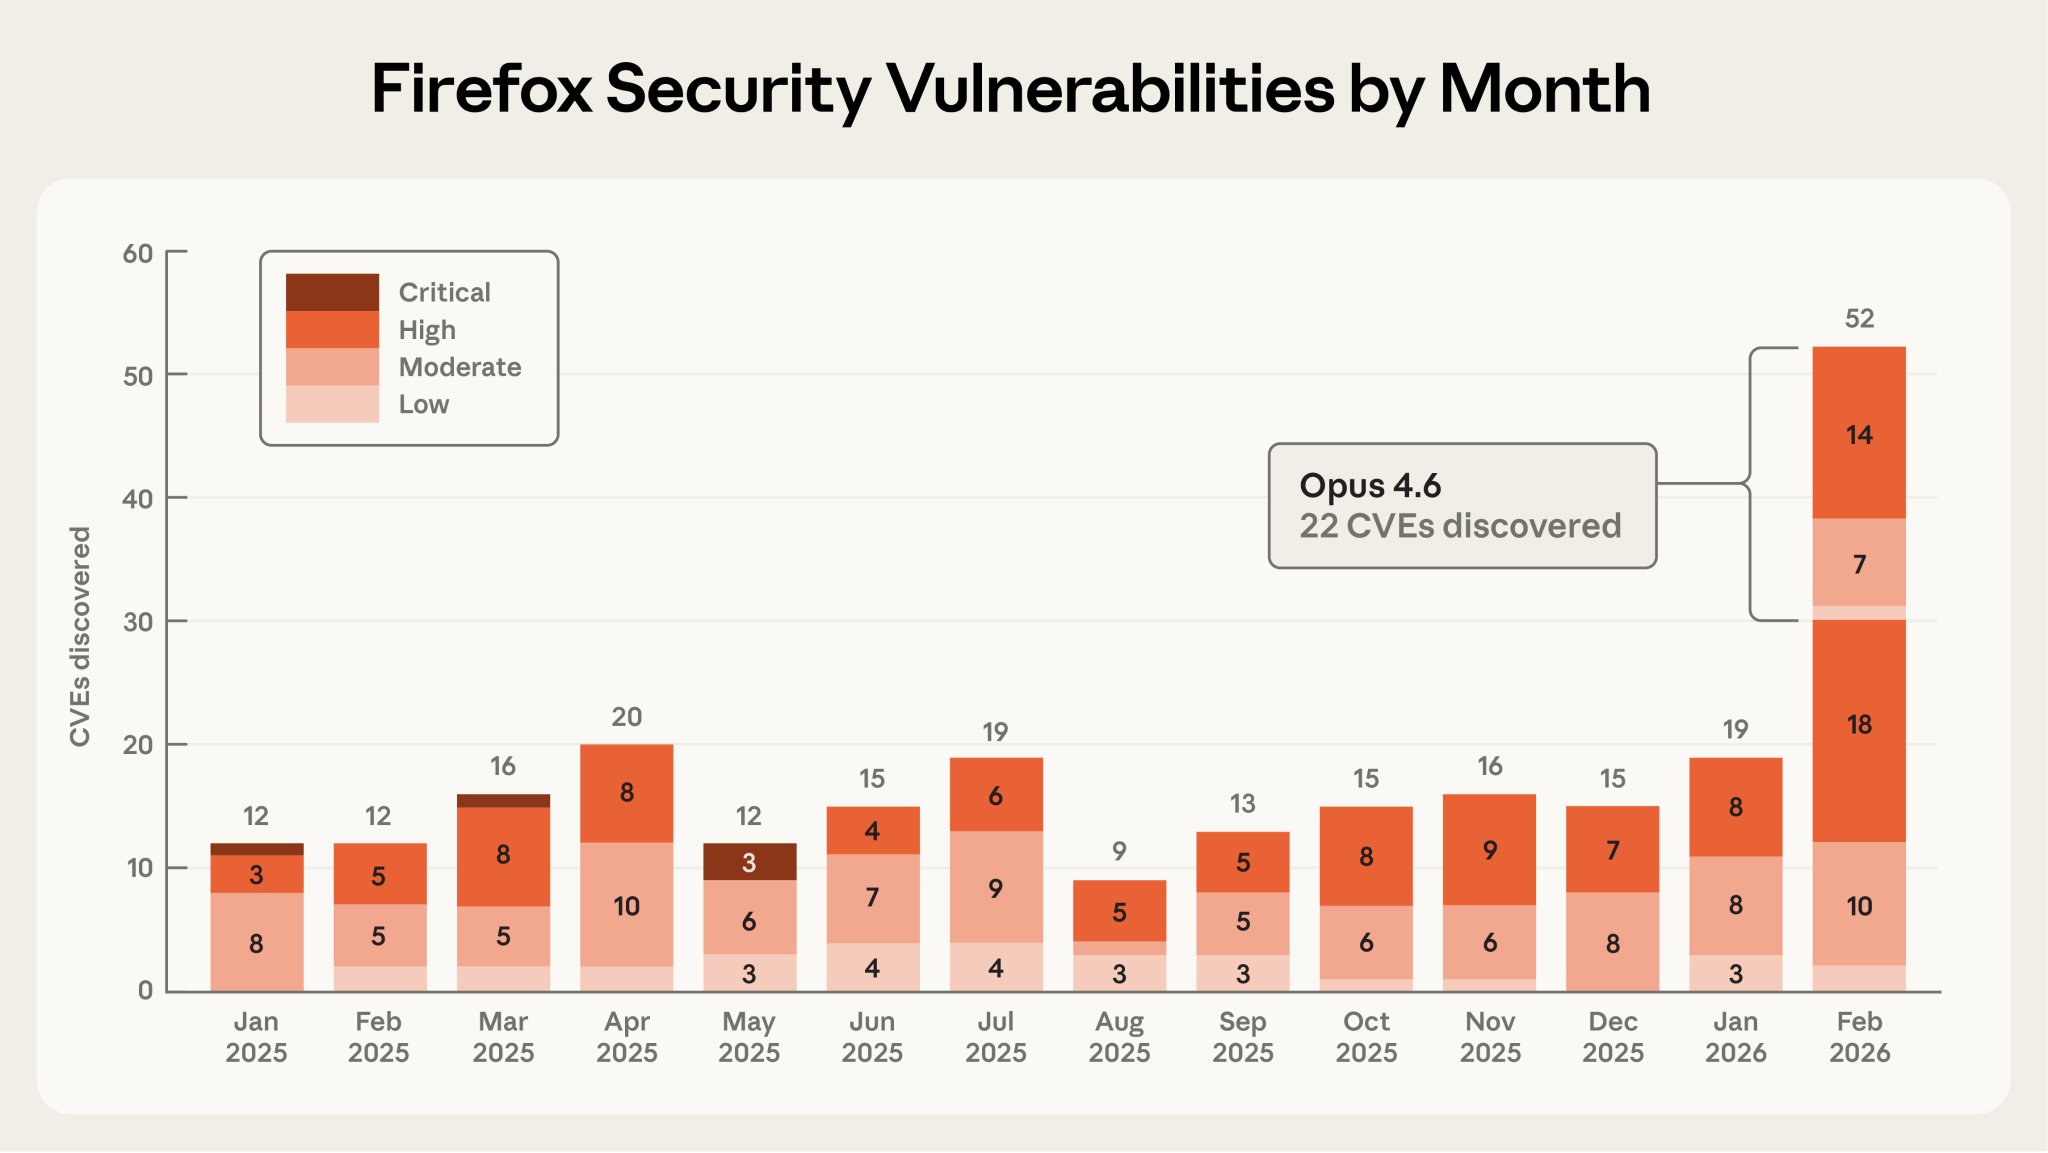
Claude Finds 22 Firefox Vulnerabilities in Security Partnership
By
–
We partnered with Mozilla to test Claude's ability to find security vulnerabilities in Firefox. Opus 4.6 found 22 vulnerabilities in just two weeks. Of these, 14 were high-severity, representing a fifth of all high-severity bugs Mozilla remediated in 2025.
-
Getting Started Guide to Claude Code AI Agents
By
–
folks who are just getting started: here's my step-by-step guide for setting up and using claude code – designed to show the power and reach of AI agents and beginner enough for anyone to jump in
-
Speculation on AI Model Capabilities: Coding and Logical Reasoning
By
–
maybe 5.4 is just 4.5 with extra coding and logical reasoning capabilities
-
Codex App: AI Transforms Software Development Into Task Delegation
By
–
holy sht.. AI just changed how software gets built. Codex App might be the closest thing to a GPT-3 moment for development. For years, AI coding tools lived inside terminals. Claude Code, Codex CLI, all incredibly powerful, but they still felt like tools built by developers, for developers. Flexible? absolutely. But also fragmented, full of setup, plugins, MCP servers, and custom workflows. Great for engineers. Not exactly a product for everyone else. What Codex changes isn’t just the model. It’s the interface of development. Instead of stitching together tools, environments and scripts, you simply talk to the system. Behind the scenes, agents read your codebase, modify files, install dependencies and execute tasks. Software creation starts to feel less like programming and more like delegating work. The moment it clicked for me was simple. During the OpenClaw wave I bought a Mac mini and set up a fresh environment. Normally the first installs would be npm or brew. This time it was Codex. I gave it full access and asked it to install everything needed to run the project. Dependencies, environment setup, configuration, runtime. All from a single prompt. Watching the system configure itself without touching the terminal once felt like looking at the next interface of computing. Not because AI wrote code. But because the computer started executing intentions instead of commands. Most people think AI will democratize coding by generating code faster. But that’s not the real shift. The real shift is that software development is slowly moving from writing code to assigning tasks to agents. Historically computing had three main interfaces. CLI for engineers, GUI for consumers, APIs for systems. AI introduces a new one. The agent interface. You don’t operate the software anymore. You tell systems what outcome you want and they orchestrate the process. If that interface becomes mainstream, the impact goes far beyond coding. It changes how startups are built, how products are shipped, and how technical the world needs to be to create software. Codex App might be one of the first glimpses of that future.
→ View original post on X — @arrakis_ai, 2026-03-06 12:32 UTC
-
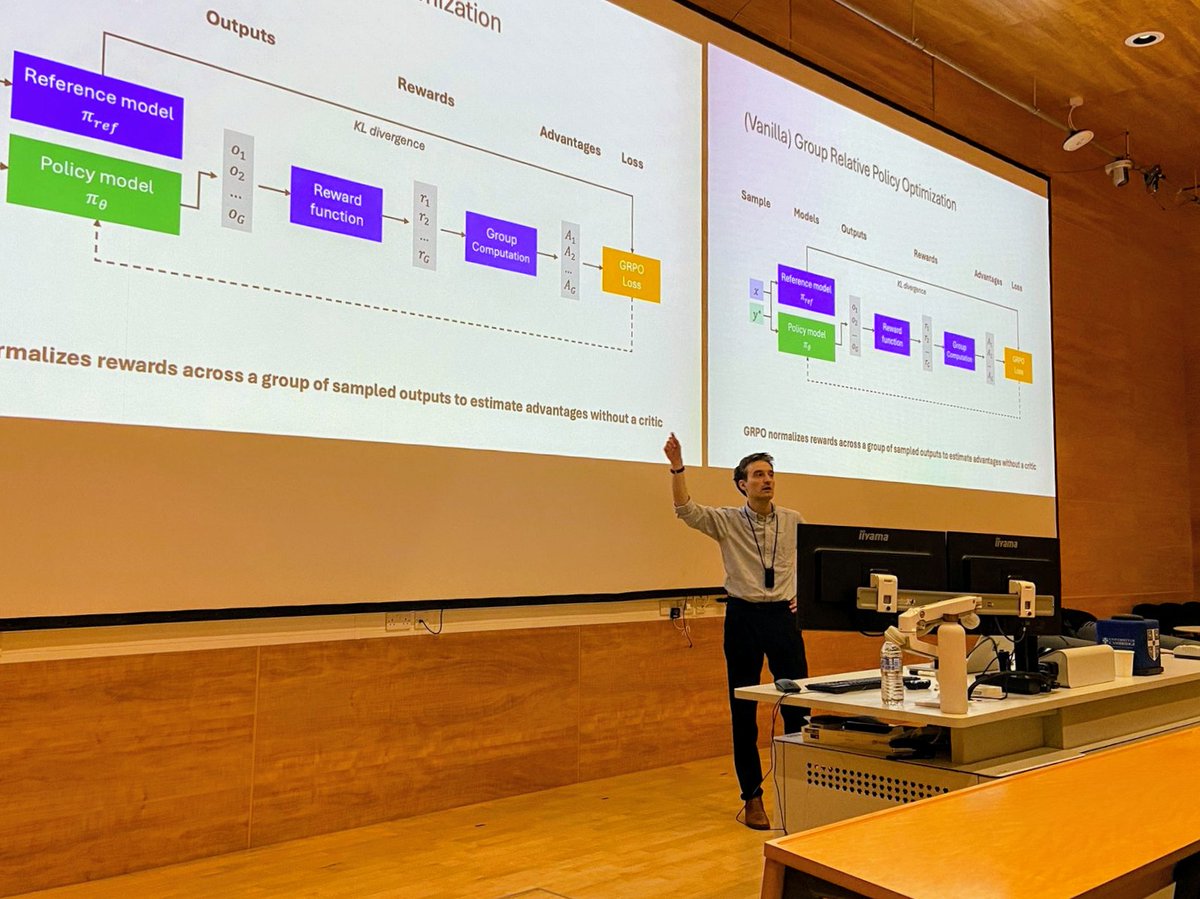
53 Slides on Post-Training Algorithms and Data Quality
By
–
I'm releasing 53 slides on post-training, covering core algorithms like DPO and GRPO, as well as data quality, synthetic data pipelines, and on-policy training. I had the pleasure of presenting it yesterday as a guest lecturer in Cambridge, UK
→ View original post on X — @maximelabonne, 2026-03-06 10:45 UTC
-
Researchers test AI self-awareness in reasoning
By
–
here's where it gets interesting. the researchers probed whether models internally "know" they're done. they introduced TSearch, which scores partial reasoning traces by cumulative log-probability across the entire chain, not just the next token. when you let the model explore
-
Research Collaboration in AI and Machine Learning Systems
By
–
I welcome discussions and research collaboration in: • Artificial Intelligence
• Scientific Computing
• Machine Learning Systems
• Advanced Predictive Modeling -
GPT-5.4 outperforms GPT-5.2 on code and knowledge benchmarks
By
–
that’s not true, evals comparing 5.2 vs 5.4 (thinking only) Coding (SWE-Bench Pro) > GPT-5.2: 55.6%
> GPT-5.4: 57.7%
→ ~+2.1 pts improvement in solving real-world repo bug-fix tasks. Knowledge-work benchmark (GDPval) > GPT-5.2: ~71% win/tie vs professionals
> GPT-5.4: 83% -
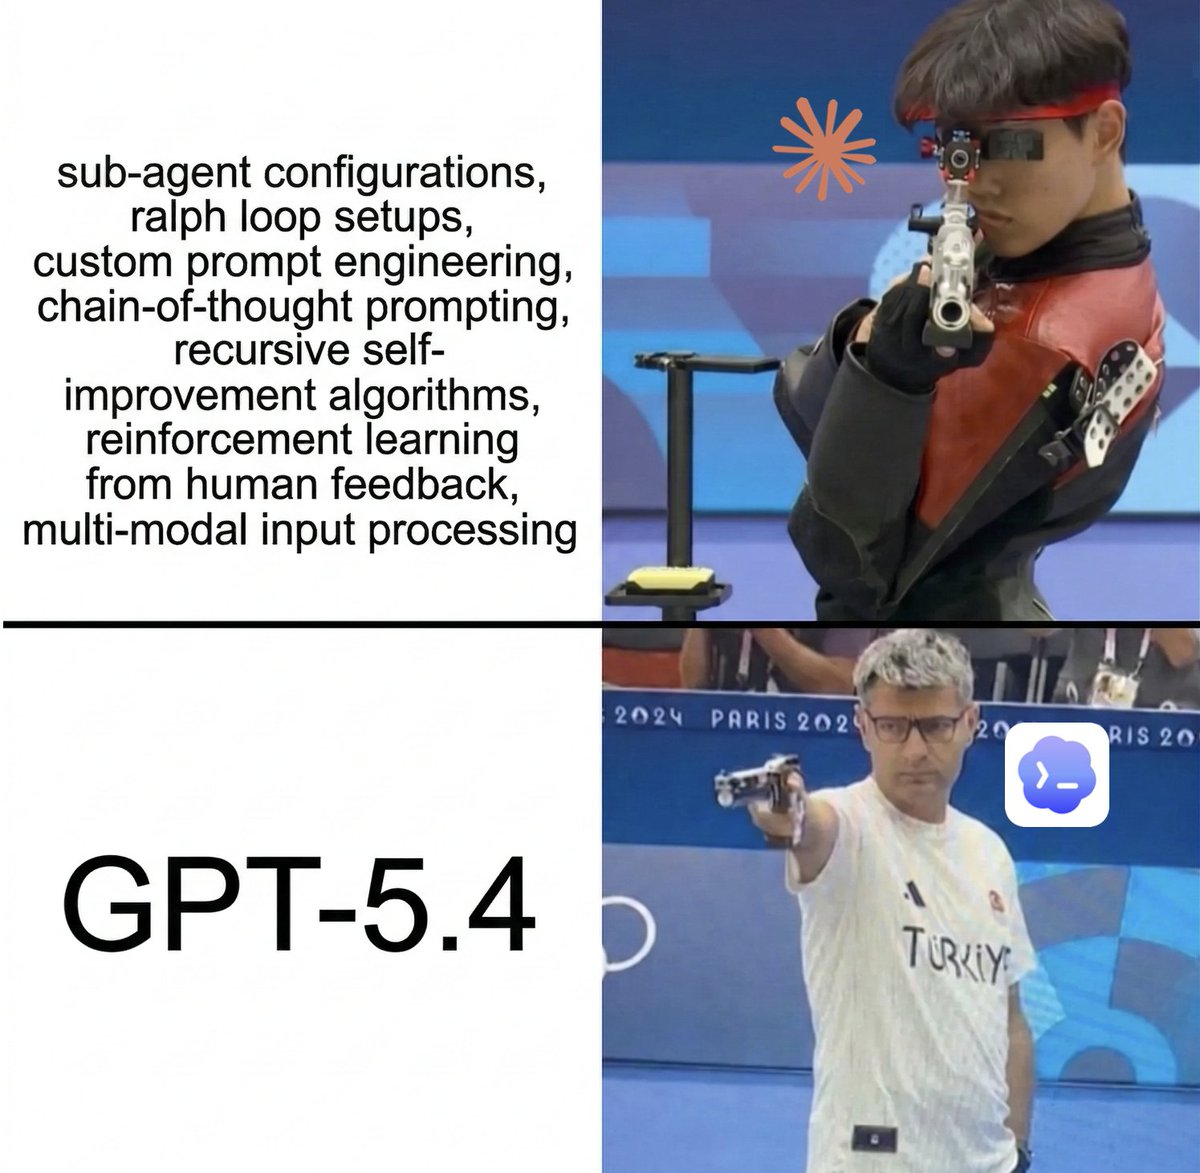
Comparison between Claude Code and Codex App
By
–
Claude Code vs Codex App [Translated from EN to English]
→ View original post on X — @arrakis_ai, 2026-03-06 07:44 UTC