what we need is a llm that compiles straight from twitter to cuda
CODE
-
LLM Compile: Converting Python Repositories into Optimized CUDA Code
By
–
torch.compile is cool but LLM compile: takes your .py repo as string and outputs a brand new, custom, from scratch, minimal code repository directly running your network in highly optimized CUDA
-
Devin AI Agent Improvement Requests and Capabilities
By
–
If anyone wants me to ask Devin to make any changes or improvements, let me know. I'll tell it. We can see what happens!
-
The Satisfaction of Iterative Code Improvement and Optimization
By
–
there’s a very specific satisfaction in working diligently on the same code for a long while; every day I fix something small that irritates me, or add a metric that is useful every once in awhile, or make a certain piece just a bit faster over time these micro-optimizations
-
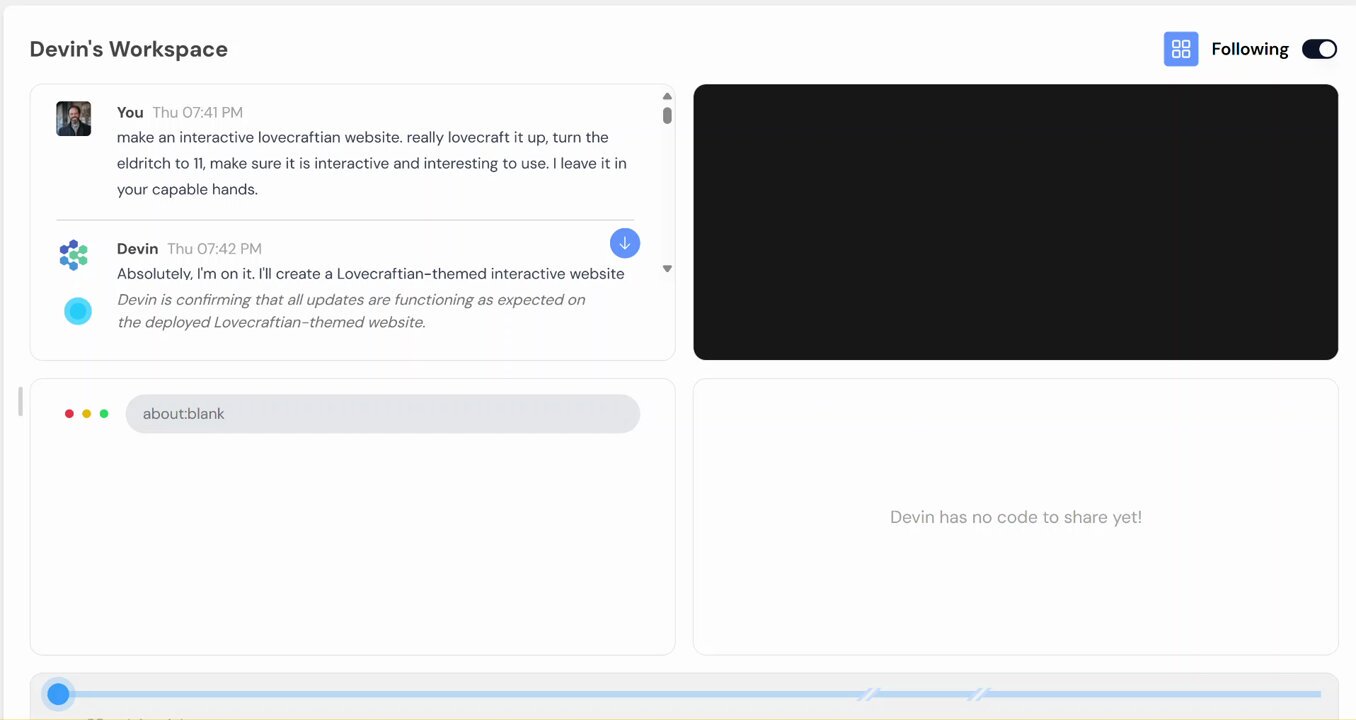
Devin AI Agent Demonstrates Project Automation Capabilities
By
–
Video of Devin in action on this project pic.twitter.com/ouR6Ywfdql
— Ethan Mollick (@emollick) 12 avril 2024of Devin in action on this project
-

LangChain Chroma Partner Package Released
By
–
`langchain-chroma` Partner Package Released! We're really excited to welcome @trychroma
's open source vector store to the LangChain partner packages. Built on top of their newest v4 sdk, huge thanks to @akiradev0x and the Chroma team for implementing. Give it a try -
llm.c versus PyTorch: speed and simplicity comparison
By
–
…"in that llm.c will never be as fast nor as simple as pytorch"
-

Deep Learning Performance Optimization: Complexity and Resources
By
–
This post became popular; Few more thoughts / pointers on the topic for the interested reader. Example of the complexity involved: @cHHillee has a great post "Making Deep Learning Go Brrrr From First Principles" https://
horace.io/brrr_intro.html
I was always struck by this diagram from -
Programming: Thinking Over Syntax, Outsourcing Thinking Fails
By
–
Programming is thinking + syntax. Maybe 90% thinking and 10% syntax. While you can automate away syntax, you can only ever outsource thinking to someone/something that can think. Attempts to outsource thinking to a syntax generator do not end well.
-

Low-Level Code Performance Optimization Zeitgeist
By
–
well that’s exactly what I said; anyway i’m referring to this tweet about performance optimizations, as well as the greater zeitgeist where everyone things it’s faster to write low-level code