Keras code compiles to JAX, TensorFlow, or PyTorch code, so anything you can do with one of these frameworks you can do with Keras. I recommend using JAX as your backend, as it is suitable for very-large scale computation and can be easily parallelized across many devices.
CODE
-
GPU acceleration and XLA compilation limitations in framework integration
By
–
But then you would not be able to run it on GPU, nor compile to XLA for a ~5x speedup, nor use it inside a TensorFlow codebase or a PyTorch codebase.
-

Keras ops API: NumPy syntax across JAX PyTorch TensorFlow
By
–
A neat feature of Keras is that its `keras.ops` API follows the NumPy API syntax exactly. And since it runs on JAX, PyTorch, TensorFlow, and NumPy itself, you can use Keras to write GPU-accelerated NumPy code that runs with any framework.
-
Dealing with random MPI hangs in large model training
By
–
I thought I didn't have to deal with these, but already the 350M model (14 hours of 8 GPUs working) sometimes randomly hangs with a cryptic MPI error once in a while. So I have to put the whole optimization into a `while 1` loop and a script that watches the log file and sends
-
Start Latency Issues with Dataset Tokenization in Python
By
–
TIL, will look into! The thing that makes this a bit complicated right now is the start latency. What bloats up the setup time right now is the dataset and its tokenization, which is all done in Python right now. Installing huggingface datasets, downloading FineWeb 10B and
-
Conservative hyperparameters with potential for 10X speedup
By
–
Agree!! I'm using very conservative settings for a lot of the hyperparameters (following GPT-3 paper when possible) and haven't tried to speed this up at all yet, but I expect a 10X multiplier here should be possible.
-
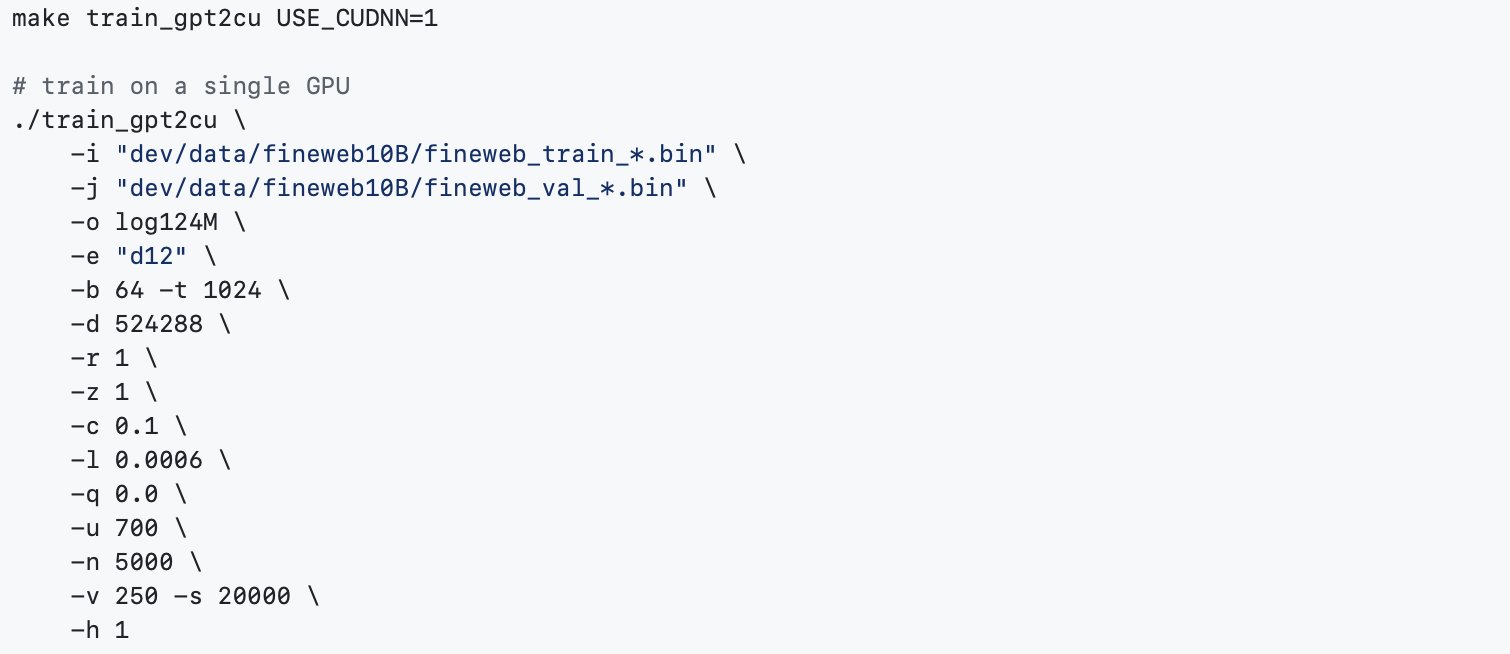
Reproduce GPT-2 124M in llm.c for $20 in 90 Minutes
By
–
# Reproduce GPT-2 (124M) in llm.c in 90 minutes for $20 The GPT-2 (124M) is the smallest model in the GPT-2 series released by OpenAI in 2019, and is actually quite accessible today, even for the GPU poor. For example, with llm.c you can now reproduce this model on one 8X
-
Running Multiple Open Source LLMs Locally with Ollama
By
–
Check out the code and complete hands on tutorial in the below blog https://
blog.futuresmart.ai/running-multip
le-open-source-llms-locally-with-ollama
…
#FuturesmartAI #AI #LLMs #Opensource -
Running Multiple Open Source LLMs Locally with Ollama
By
–
Running Multiple Open Source LLMs Locally with Ollama Check out this awesome blog on how to run LLMs on your local machine and build applications with ease
-
Fine-tuning Faster R-CNN for Sea Rescue Detection
By
–
Fine-tuning Faster R-CNN for Sea Rescue 🌊https://t.co/U1G0q7YrSk
— Satya Mallick (@LearnOpenCV) 28 mai 2024
Our research enhances Faster R-CNN to detect people in distress using the SeaDroneSee dataset. By preprocessing images into patches, we significantly improve detection accuracy.
Dive into our findings and see… pic.twitter.com/YQ5KOfvUClFine-tuning Faster R-CNN for Sea Rescue https://
learnopencv.com/fine-tuning-fa
ster-r-cnn/
… Our research enhances Faster R-CNN to detect people in distress using the SeaDroneSee dataset. By preprocessing images into patches, we significantly improve detection accuracy. Dive into our findings and see