New video (and black friday deal!): Boost RAG Performances with Fine-Tuned Embedding Models! Learn more: https://
youtu.be/YE6-dS-80KQ p.s. check the video description for a black Friday discount on our courses! #ai #rag #llm #llms
CODE
-
Fine-Tuned Embeddings Boost RAG Model Performance
By
–
-
Prompt Tuning Playbook for Post-trained Large Language Models
By
–
GitHub – varungodbole/prompt-tuning-playbook: A playbook for effectively prompting post-trained LLMs https://
bit.ly/4g1UJCz
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Stability AI Releases Three ControlNets for Stable Diffusion 3.5
By
–
ICYMI: We released three ControlNets for Stable Diffusion 3.5 Large this week: Blur, Canny, and Depth Model weights https://
huggingface.co/stabilityai/st
able-diffusion-3.5-controlnets
… Code https://
github.com/Stability-AI/s
d3.5/
… Stability AI Community License https://
stability.ai/community-lice
nse-agreement
… Comfy support -
Extract Metadata Retriever for Vector Database Search
By
–
Extract Metadata Retriever Automatically apply metadata filtering from user question when searching through vector databases https://
docs.flowiseai.com/use-cases/mult
iple-documents-qna#metadata-retriever
… -
Grok Integration Now Available in Flowise v2.2.1
By
–
Grok is now available to be used in Flowise v2.2.1!
— FlowiseAI (@FlowiseAI) 29 novembre 2024
Some other updates:
📄Document Store upsert & refresh API
🔖Extract Metadata Retriever pic.twitter.com/IpXSrPwg2pGrok is now available to be used in Flowise v2.2.1! Some other updates:
Document Store upsert & refresh API
Extract Metadata Retriever -
Running AI NPCs Locally: Feasibility and Implementation
By
–
Yes, you can run local LLMs. But can you run AI NPCs locally?
-

Comprehensive llama.cpp Guide: Building and Performance Benchmarking
By
–
Cool guide to llama.cpp from building to perf benchmarking llama.cpp's documentation is notoriously difficult to work with. There's some more advanced stuff I didn't know about, it's great stuff from @steel_ph0enix https://
steelph0enix.github.io/posts/llama-cp
p-guide/
… -
Structured JSON Generation with SmolLM2 in Browser
By
–
Fuck it! Structured Generation w/ SmolLM2 running in browser & WebGPU 🔥
— Vaibhav (VB) Srivastav (@reach_vb) 28 novembre 2024
Powered by MLC Web-LLM & XGrammar ⚡
Define a JSON schema, Input free text, get structured data right in your browser – profit!!
To showcase how much you can do with just a 1.7B LLM, you pass free text,… pic.twitter.com/x5GYWdmTe3Fuck it! Structured Generation w/ SmolLM2 running in browser & WebGPU Powered by MLC Web-LLM & XGrammar Define a JSON schema, Input free text, get structured data right in your browser – profit!! To showcase how much you can do with just a 1.7B LLM, you pass free text,
-
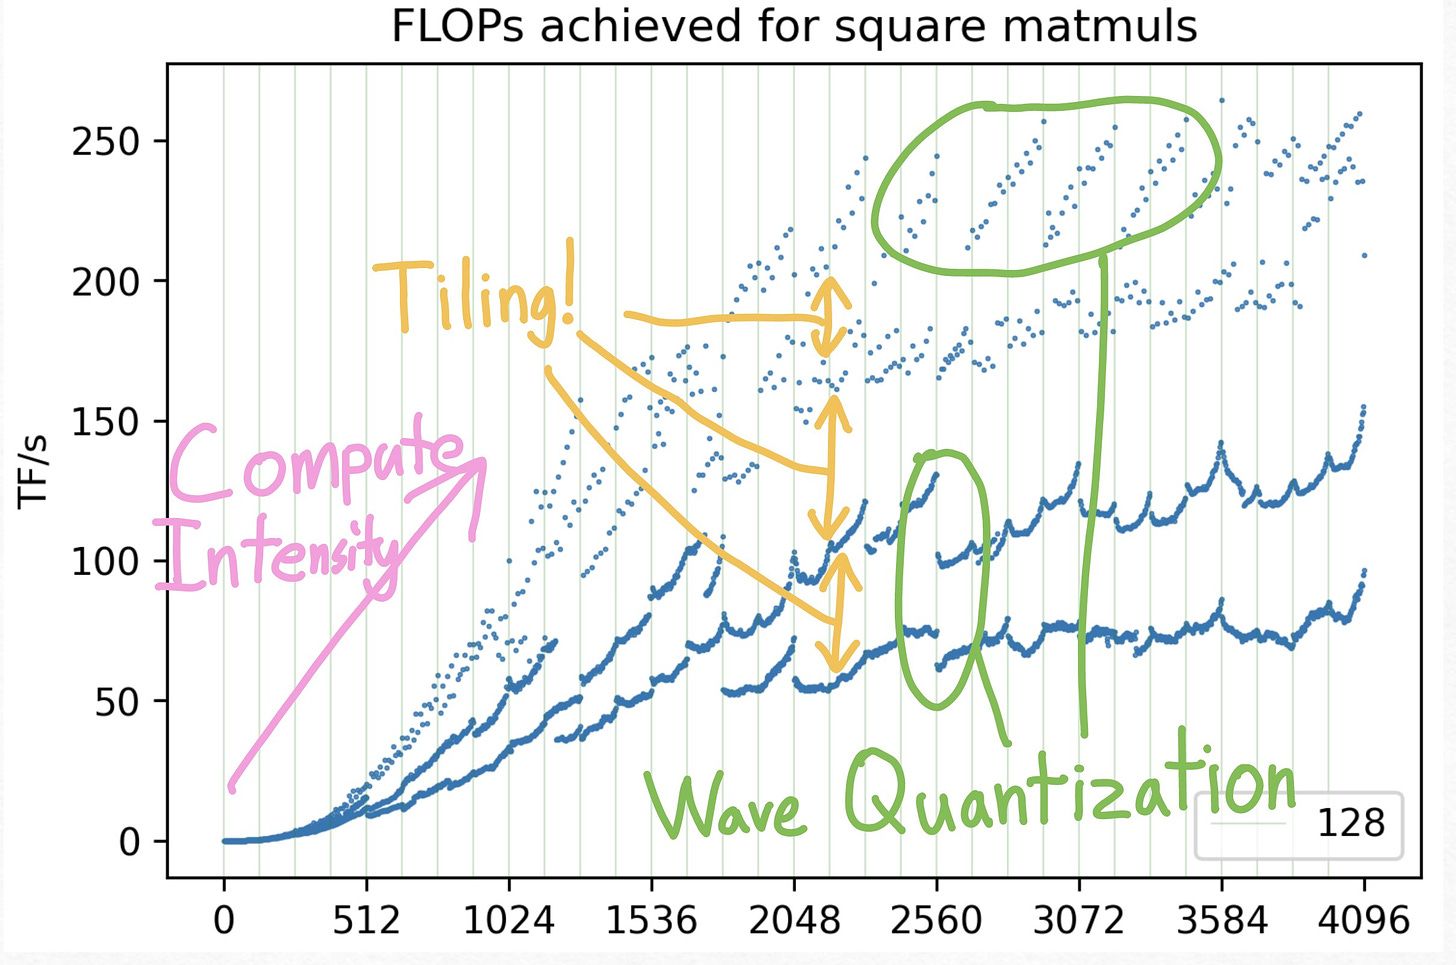
Matrix Multiplication Shapes in Deep Learning Models
By
–
What Shapes Do Matrix Multiplications Like? [medium] https://
bit.ly/4eO1HKc
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
GPU Resource Allocation: Balancing Optimization with Debugging Flexibility
By
–
A fully optimized system might wind up with persistent kernels running continuously on all GPUs, but I want the ability to debug a single process using all GPUs, as well as launch parallel experiments directly from one host without needing a cluster layer.