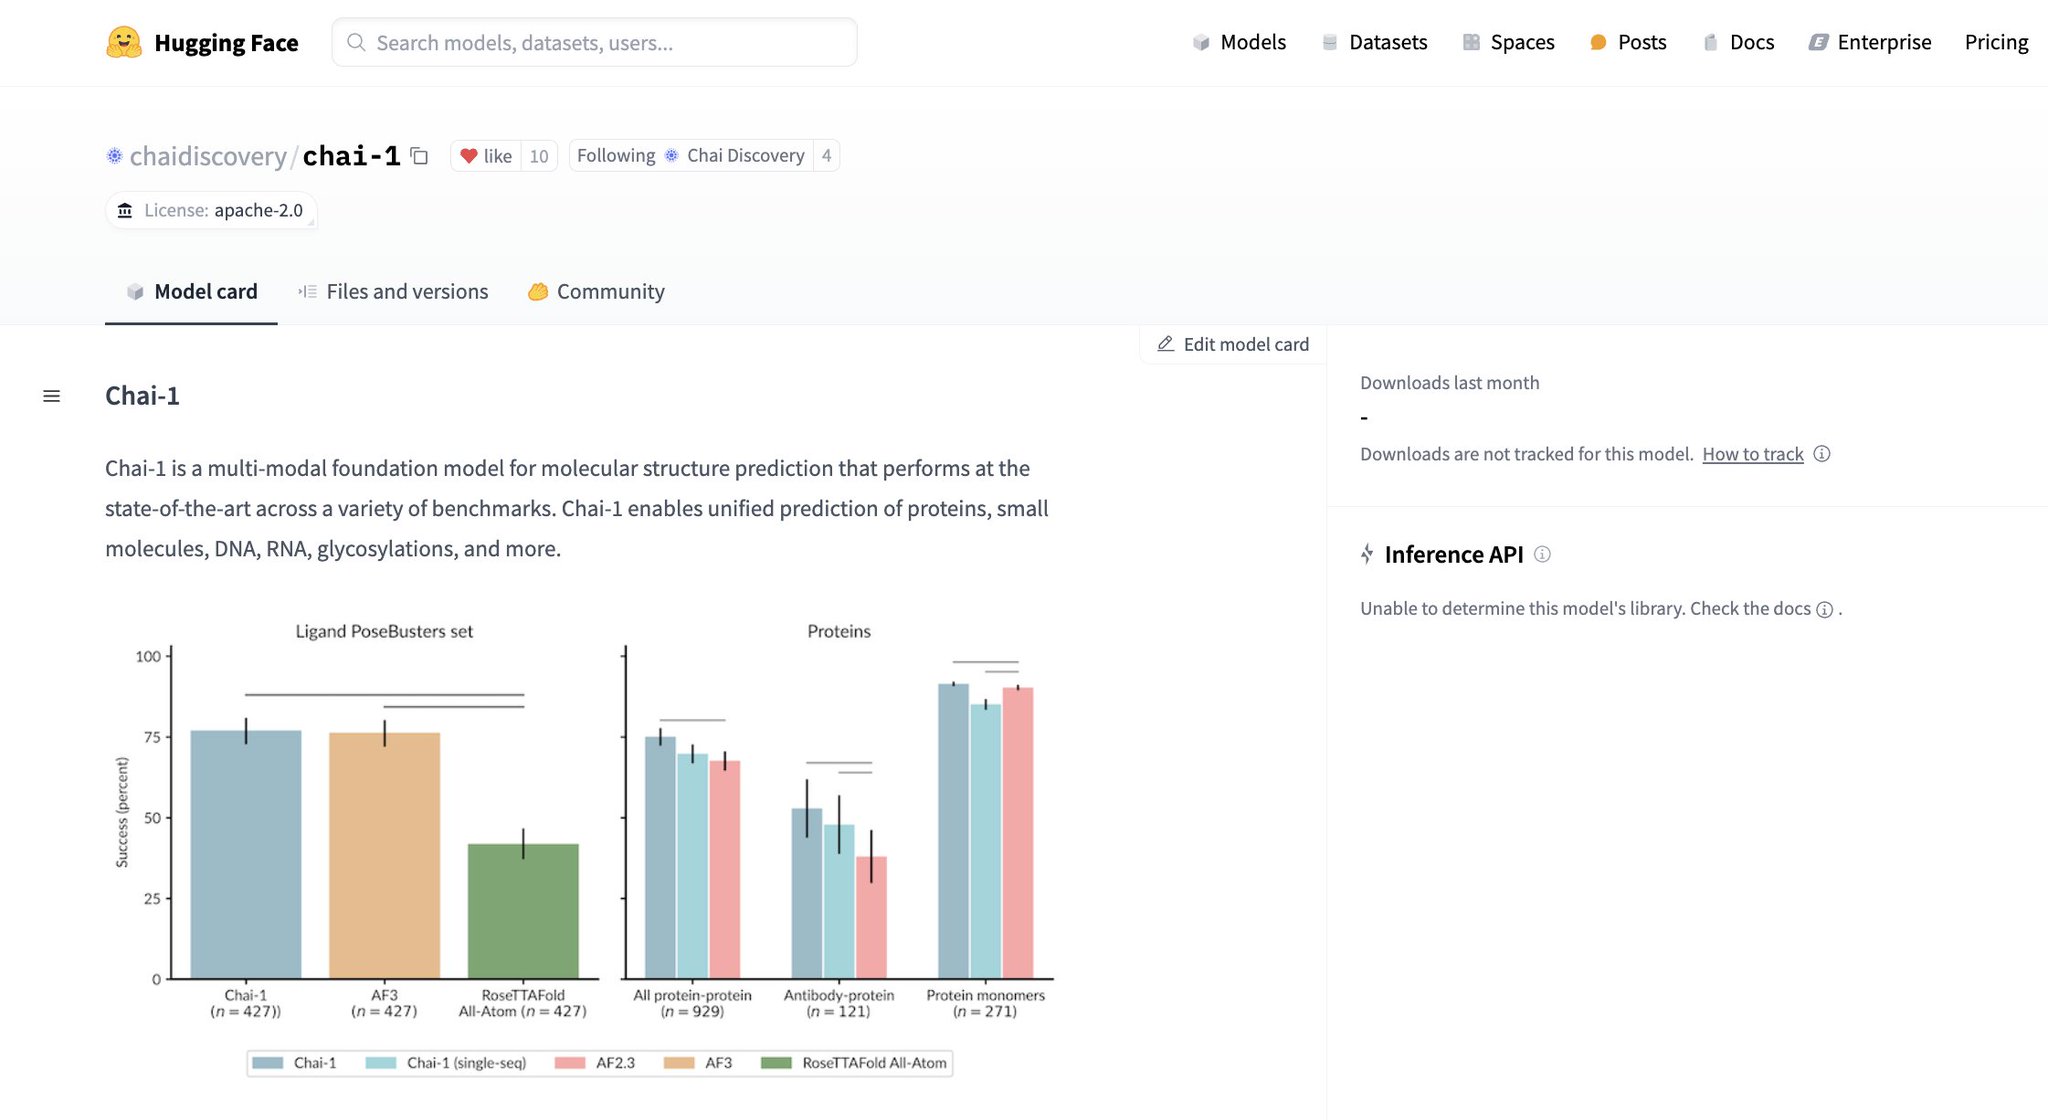
So excited to see more biology open-source models! Chai by @chaidiscovery does structure predictions at AlphaFold3 levels of accuracy and able to handle multi-peptide or peptide-ligand complexes rather than just single chains. All in Apache 2.0 on Hugging Face:
CODE
-
Using ChatGPT for Coding and Software Development Tasks
By
–
9. Coding
— God of Prompt (@godofprompt) 5 décembre 2024
ChatGPT is a tool that can help you with language and coding tasks.
It can assist you with writing and debugging code.
It can also be helpful in developing Games, Apps, and Websites. pic.twitter.com/k58f1S0Hsy9. Coding ChatGPT is a tool that can help you with language and coding tasks. It can assist you with writing and debugging code. It can also be helpful in developing Games, Apps, and Websites.
-
Building a Break Out game with AI in seconds
By
–
5. Build the Break Out game in seconds: pic.twitter.com/6AcLLHZxVI
— God of Prompt (@godofprompt) 5 décembre 20245. Build the Break Out game in seconds:
-
Using GPT-4o to generate a Facebook Messenger clone
By
–
4. Make a facebook messenger as a single html file. GPT-4o does this in 6 seconds(!): pic.twitter.com/qsOdMXtpnx
— God of Prompt (@godofprompt) 5 décembre 20244. Make a facebook messenger as a single html file. GPT-4o does this in 6 seconds(!):
-
Transforming Sketches into Working Apps with GPT-4o
By
–
1. Turn your simple drawing into a working App in seconds with the new GPT-4o: pic.twitter.com/8sL90DUVf9
— God of Prompt (@godofprompt) 5 décembre 20241. Turn your simple drawing into a working App in seconds with the new GPT-4o:
-
Stochastic Taylor Derivative Estimator: Efficient Amortization Method
By
–
Stochastic Taylor Derivative Estimator: Efficient amortization for arbitrary differential operators Zekun Shi, Zheyuan Hu, Min Lin, Kenji Kawaguchi https://
arxiv.org/abs/2412.00088 -
Cognify: Automated Gen-AI Workflow Optimization Tool
By
–
introducing Cognify: Automated, Multi-Faceted Gen-AI Workflow Optimization https://
github.com/GenseeAI/cogni
fy
… a tool that automatically enhances generation quality and reduces costs for gen-AI workflows, including those written with LangChain, DSPy, and annotated Python. -
Normalization and Token Counting in AI Model Evaluation
By
–
Isn't the point of normalization to control for the number of tokens (i.e. using mean rather than sum), so these 20% variations should be accounted for with acc_norm. I figured that's why most people use acc_norm these days!
-
Token Optimization and Model Performance Improvements Debate
By
–
Well, if you're willing to debate token equivalence I think that's a fair approach! The code itself hasn't changed and HellaSwag score is significantly higher given the same number of steps. It's not only fewer tokens on disk but they are "better" tokens too, IMHO +40% total.
-
Token Density Impact on Validation Metrics in Model Training
By
–
Nope, it wouldn't be the same; that's the catch! Because the token density is about 20% higher when the same text is processed, the validation metric ends up being around 4.18. Making the train/val boundary at exactly the same word is possible, but it won't change the mismatch.