Amazon’s retail stores are starting to run like cloud systems https://
cloudcomputing-news.net/news/amazon-re
tail-stores-are-starting-to-run-like-cloud-systems/?utm_source=dlvr.it&utm_medium=twitter
… #Cloud #Automation #Data #Innovation #DataPlatforms #CIO #BusinessStrategy #MLOps
AI
-
Amazon Retail Stores Operating as Cloud Systems
By
–
-

Google’s AI debates itself without training
By
–
HOLY SHIT… Google just proved that reasoning models aren't thinking, they're arguing. > DeepSeek-R1 spontaneously generates internal multi-agent debates inside its own chain of thought. Nobody trained it to do this. Reinforcement learning for accuracy produced it
-
Open-source models for agent tools over closed APIs
By
–
It’s time for open-source agent tools to rely primarily on open-source models, instead of closed-source APIs that send all your data to the cloud and ultimately will get hacked and/or shut down
-

China Launches Massive Humanoid Robot Manufacturing Line Production
By
–
China announces its first automated manufacturing line capable of producing 10.000 humanoid robots per year ~ 1 robot every 30 minutes.
— Chubby♨️ (@kimmonismus) 30 mars 2026
They go all in robots. https://t.co/a64BCMFkEK pic.twitter.com/reH4ArggYlChina announces its first automated manufacturing line capable of producing 10.000 humanoid robots per year ~ 1 robot every 30 minutes. They go all in robots.
-
daVinci-MagiHuman: Fast audio-video generation transformer model released
By
–
daVinci-MagiHuman is here: 15B single-stream Transformer for joint audio-video generation. 🎬 Demo video👇
— ModelScope (@ModelScope2022) 30 mars 2026
⚡ Blazing fast: 5s 256p video in 2s, 1080p in 38s — single H100
🎯 80.0% win rate vs Ovi 1.1, 60.9% vs LTX 2.3 (2,000 pairwise evals)
✅ WER 14.60% — best-in-class… pic.twitter.com/6GuiOTtedtdaVinci-MagiHuman is here: 15B single-stream Transformer for joint audio-video generation. 🎬 Demo video👇 ⚡ Blazing fast: 5s 256p video in 2s, 1080p in 38s — single H100 🎯 80.0% win rate vs Ovi 1.1, 60.9% vs LTX 2.3 (2,000 pairwise evals) ✅ WER 14.60% — best-in-class audio-visual sync, beats LTX 2.3 (19.23%) and Ovi 1.1 (40.45%) 📚 6 languages: Mandarin, Cantonese, EN, JP, KR, DE, FR 🧠 One unified stream: text + video + audio tokens, self-attention only. 🛠️ Full stack open: base + distilled (8-step, CFG-free) + super-res + inference code 📄 Apache 2.0. 🤖: modelscope.cn/models/GAIR/da… 💻: github.com/GAIR-NLP/daVinci-…
→ View original post on X — @shiqi_yang_147, 2026-03-30 09:18 UTC
-

AI: Consulting Firms Face Revenue Compression
By
–
For over a year now, clients have been pushing consulting firms to lower their prices in the name of productivity gains linked to AI. A HEC Alumni / Kea study confirms this. The real shock from AI is revenue compression, not just job displacement. [Translated from EN to English]
→ View original post on X — @alex_tsico, 2026-03-30 09:14 UTC
-
93-Year-Old Drives Independently With Tesla FSD and Grok
By
–
Une femme de 93 ans vient de s'acheter une Tesla Model Y avec FSD et la navigation Grok.
— VISION IA (@vision_ia) 30 mars 2026
Elle conduit. Toute seule. Sans aide. Sans peur. Sans fatigue.
Son fils : "Même si elle a toujours été une bonne conductrice, ma mère peut maintenant rouler sans la peur et la fatigue qui… https://t.co/j23dvfwIJYA 93-year-old woman just bought herself a Tesla Model Y with FSD and Grok navigation. She drives. All by herself. Without help. Without fear. Without fatigue. Her son: "Even though she's always been a good driver, my mother can now drive without the fear and fatigue that
-
MSA记忆路由技术对比Google Titans的核心问题回应
By
–
上条帖子聊了 MSA 和 Google Titans 的记忆路线对比,评论区讨论质量很高,整理一下大家最关心的 5 个问题,为了避免刷屏,统一回应一下诸位: ❶ 端到端 vs RAG 两套系统 大家对「4B 打赢 235B RAG」这个结果讨论很多。核心共识是:记忆路由和生成联合训练,比检索和生成各优化各的,架构上就赢了一层。有人说得更直接,RAG 是算力妥协下的临时方案,原生记忆才是终局。 ❷ 记忆怎么更新?怎么遗忘? 这是问得最多的。记得住只是第一步,记忆系统必须能纠错、能覆盖、能遗忘。什么都不忘,噪音就会淹没信号。这块确实是下一阶段的核心课题,我们在推进。 ❸ 能不能做更小的模型? 有人问 2B、0.5B 能跑到什么程度,比如 256k 记忆长度能不能用 256M 模型搞定。这个方向直接关系到端侧部署和成本,很有价值,也在我们的规划里。 ❹ 开源和 demo 什么时候出? 光论文就准备了 9 个月,开源和模型还在整理。快了,请再给我们一点时间。 ❺ 稀疏注意力这么多,MSA 凭什么不一样? 冷静的质疑也有:现在稀疏注意力方案多如牛毛,最终还是要数据驱动来验证。这个我同意,拍脑袋建模走不远,得靠结果说话。 记忆是 AI 的下一个基础设施,这个共识越来越清晰。接下来的硬仗在更新机制、遗忘策略和小模型适配。我们继续。 艾略特 (@elliotchen100) 10 天前我们发了 MSA, Memory Sparse Attention。 刚好,上周 Google 专门发了一篇博客,把 Titans + MIRAS 两篇论文打包,主题就叫「Helping AI have long-term memory」。 research.google/blog/titans-… 两条独立的研究路线,得出了同一个结论: AI 的记忆不能靠外挂,必须原生长在模型里。 但怎么「长」,路线完全不同。 Google 的思路是加模块。 在 Transformer 旁边接了一个 Memory MLP,用「惊讶度」指标决定什么值得记, 越意外的信息越值得存。再用自适应衰减机制学会遗忘,防止记忆爆炸。 本质上,是给模型装了一个外置海马体。短期记忆走注意力,长期记忆走 Memory MLP,两条通路并行。 MSA 的思路是改机制。 不加新模块,直接改造注意力本身。核心是一个可扩展的稀疏注意力架构,复杂度是线性的,记忆翻 10 倍,计算成本不会指数爆炸。用 document-wise RoPE 让模型天然理解「这段记忆来自哪里、什么时候产生的」。 用Memory Interleave 让散落在不同文档里的记忆碎片能被串起来做多跳推理。 最关键的一点:MSA 的记忆路由器和生成任务是端到端联合训练的。不像 RAG 的检索和生成是两个割裂的系统,优化目标互相打架。 一个是给大脑装外置硬盘,一个是让大脑自己进化出海马体。 结果呢? · 4B 参数的 MSA 模型,从 16K 扩到 1 亿 token,精度衰减不到 9% · 在长上下文 benchmark 上打赢 235B 级别的顶级 RAG 系统 · 2 张 A800 就能跑,这是创业公司买得起的成本 往后退一步看,这件事更大的意义是: 当 Google 把积累了一年多的记忆研究拿出来做重点战略宣传的时候,这个方向就不再是少数人的赌注,而是行业共识。 RAG 是第一代记忆(外挂笔记本)。 Titans 是第二代记忆(外置硬盘)。 MSA 是第三代记忆(原生海马体)。 「记忆」是 AI 的下一个基础设施。这条路,我们会一直走下去。 未来,可能真有一种服务叫做「Memory as a servicey」。 — https://nitter.net/elliotchen100/status/2038137282444796030#m
→ View original post on X — @elliotchen100, 2026-03-30 09:04 UTC
-
Product Pricing Frustration After User Adoption
By
–
This really annoys me. You get used to a product, and then they charge you a fortune for it.
-
Silicon Valley Warning: AI Industry May Be Scaling in Wrong Direction
By
–
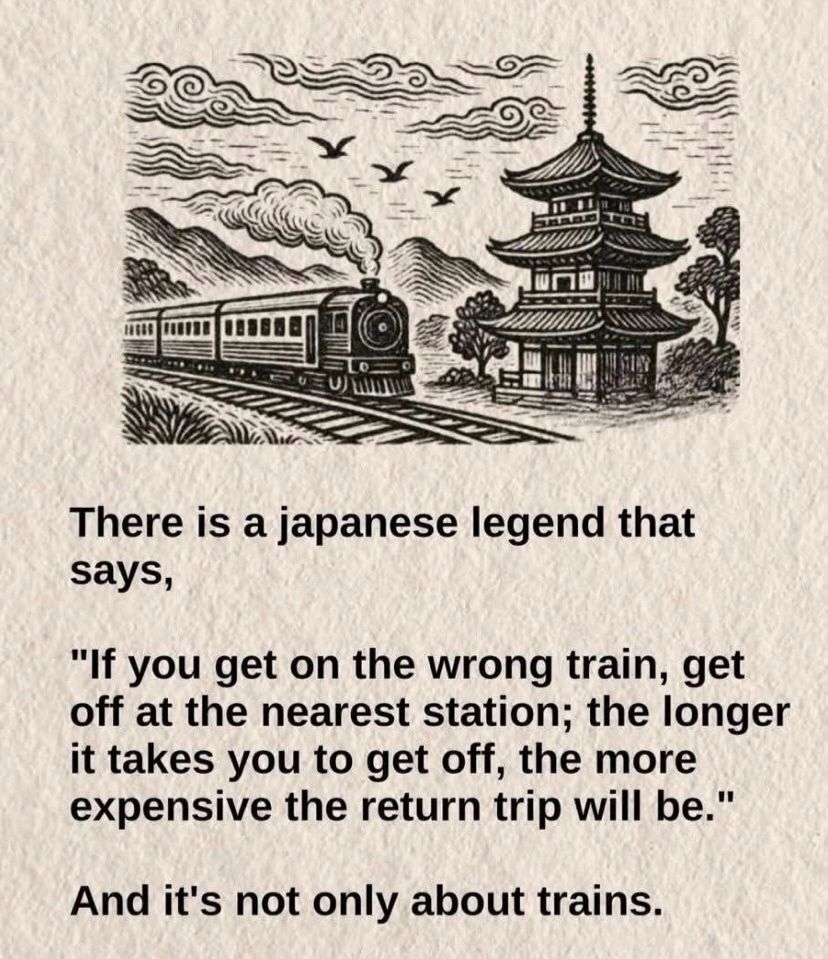
There is an old Silicon Valley warning that the AI industry should probably take more seriously: “𝗜𝗳 𝘆𝗼𝘂 𝗮𝗿𝗲 𝗼𝗻 𝘁𝗵𝗲 𝘄𝗿𝗼𝗻𝗴 𝗽𝗮𝘁𝗵 𝘁𝗼 𝗔𝗚𝗜, 𝗴𝗲𝘁 𝗼𝗳𝗳 𝗮𝘀 𝘀𝗼𝗼𝗻 𝗮𝘀 𝘆𝗼𝘂 𝗰𝗮𝗻. 𝗧𝗵𝗲 𝗹𝗼𝗻𝗴𝗲𝗿 𝘆𝗼𝘂 𝗯𝗲𝗹𝗶𝗲𝘃𝗲 𝘁𝗵𝗮𝘁 𝘀𝗰𝗮𝗹𝗶𝗻𝗴 𝗹𝗮𝗿𝗴𝗲 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲 𝗺𝗼𝗱𝗲𝗹𝘀 𝘄𝗶𝗹𝗹 𝗴𝗲𝘁 𝘆𝗼𝘂 𝘁𝗵𝗲𝗿𝗲, 𝘁𝗵𝗲 𝗳𝘂𝗿𝘁𝗵𝗲𝗿 𝘆𝗼𝘂 𝗱𝗿𝗶𝗳𝘁 𝗳𝗿𝗼𝗺 𝗔𝗚𝗜, 𝗮𝗻𝗱 𝘁𝗵𝗲 𝗺𝗼𝗿𝗲 𝗲𝘅𝗽𝗲𝗻𝘀𝗶𝘃𝗲 𝘁𝗵𝗲 𝗰𝗼𝘂𝗿𝘀𝗲 𝗰𝗼𝗿𝗿𝗲𝗰𝘁𝗶𝗼𝗻 𝘄𝗶𝗹𝗹 𝗯𝗲.” And that may be the bigger point. Not just whether LLM scaling reaches AGI. But whether the world’s smartest companies are becoming incredibly efficient at going faster in the wrong direction. #technology #ai #workplace Image credit: Ralph
→ View original post on X — @pascal_bornet, 2026-03-30 09:00 UTC