New policy brief: Tech companies often “talk the talk” of AI ethics without fully “walking the walk.” Our empirical investigation into AI ethics on the ground highlights the stark gap between company policy and practice in this field. @sannasideup https://
hai.stanford.edu/policy-brief-w
alking-walk-ai-ethics-technology-companies
…
AI
-
Tech Companies’ AI Ethics Gap: Policy vs Practice Analysis
By
–
-

Comparative test: Google Gemini vs ChatGPT and GPT4
By
–
Will #GoogleGemini kill #ChatGPT and #GPT4? We've seen a lot of nonsense on the subject in the last 24 hours. In my latest video, I decided to go further than the commercials to do real tests and comparisons → https://youtu.be/IqZIWEBQ_5Q And it's… Surprising
-
Groq LPU Inference Engine Demo at Eastern Defense Summit Booth
By
–
If you missed Brian Recore's on stage demo of our #LPU ™ Inference Engine yesterday, it's not too late to stop by booth #721 today at the #EasternDefenseSummit to be wowed first hand. #EDS #CharlestonDCA #CDCA #GroqOn #Groq
-

AI Chatbot Zapier LangChain Integration Guide EmbedAI
By
–
Creating an AI Chatbot to interact with 6000+ tools using Zapier and LangChain This great walkthrough by @matchaman11 on how he build EmbedAI to do exactly that Read all about it below! https://
medium.com/@anilmatcha/cu
stom-gpt-with-ai-actions-chatbot-tutorial-creating-an-ai-chatbot-to-interact-with-6000-tools-b0d78211c15a
… -
Today’s AI is the most primitive you will ever see
By
–
Today’s AI is the most primitive AI that you will see for the rest of your life.
-
Anthropic evaluates discrimination mitigation in language models
By
–
Read the paper here: https://
anthropic.com/index/evaluati
ng-and-mitigating-discrimination-in-language-model-decisions
… And access our dataset (and the prompts used to construct it) here: https://
huggingface.co/datasets/Anthr
opic/discrim-eval
… -
Measuring and Mitigating Language Model Risks for Safe Deployment
By
–
As language models continue to advance rapidly, the ability to proactively measure and mitigate potential risks is increasingly important to inform decisions about safe deployment.
In the future, we hope to apply these techniques to anticipate a broader range of societal impacts. -
Claude 2 Audit Study Reveals Demographic Bias in Model Decisions
By
–
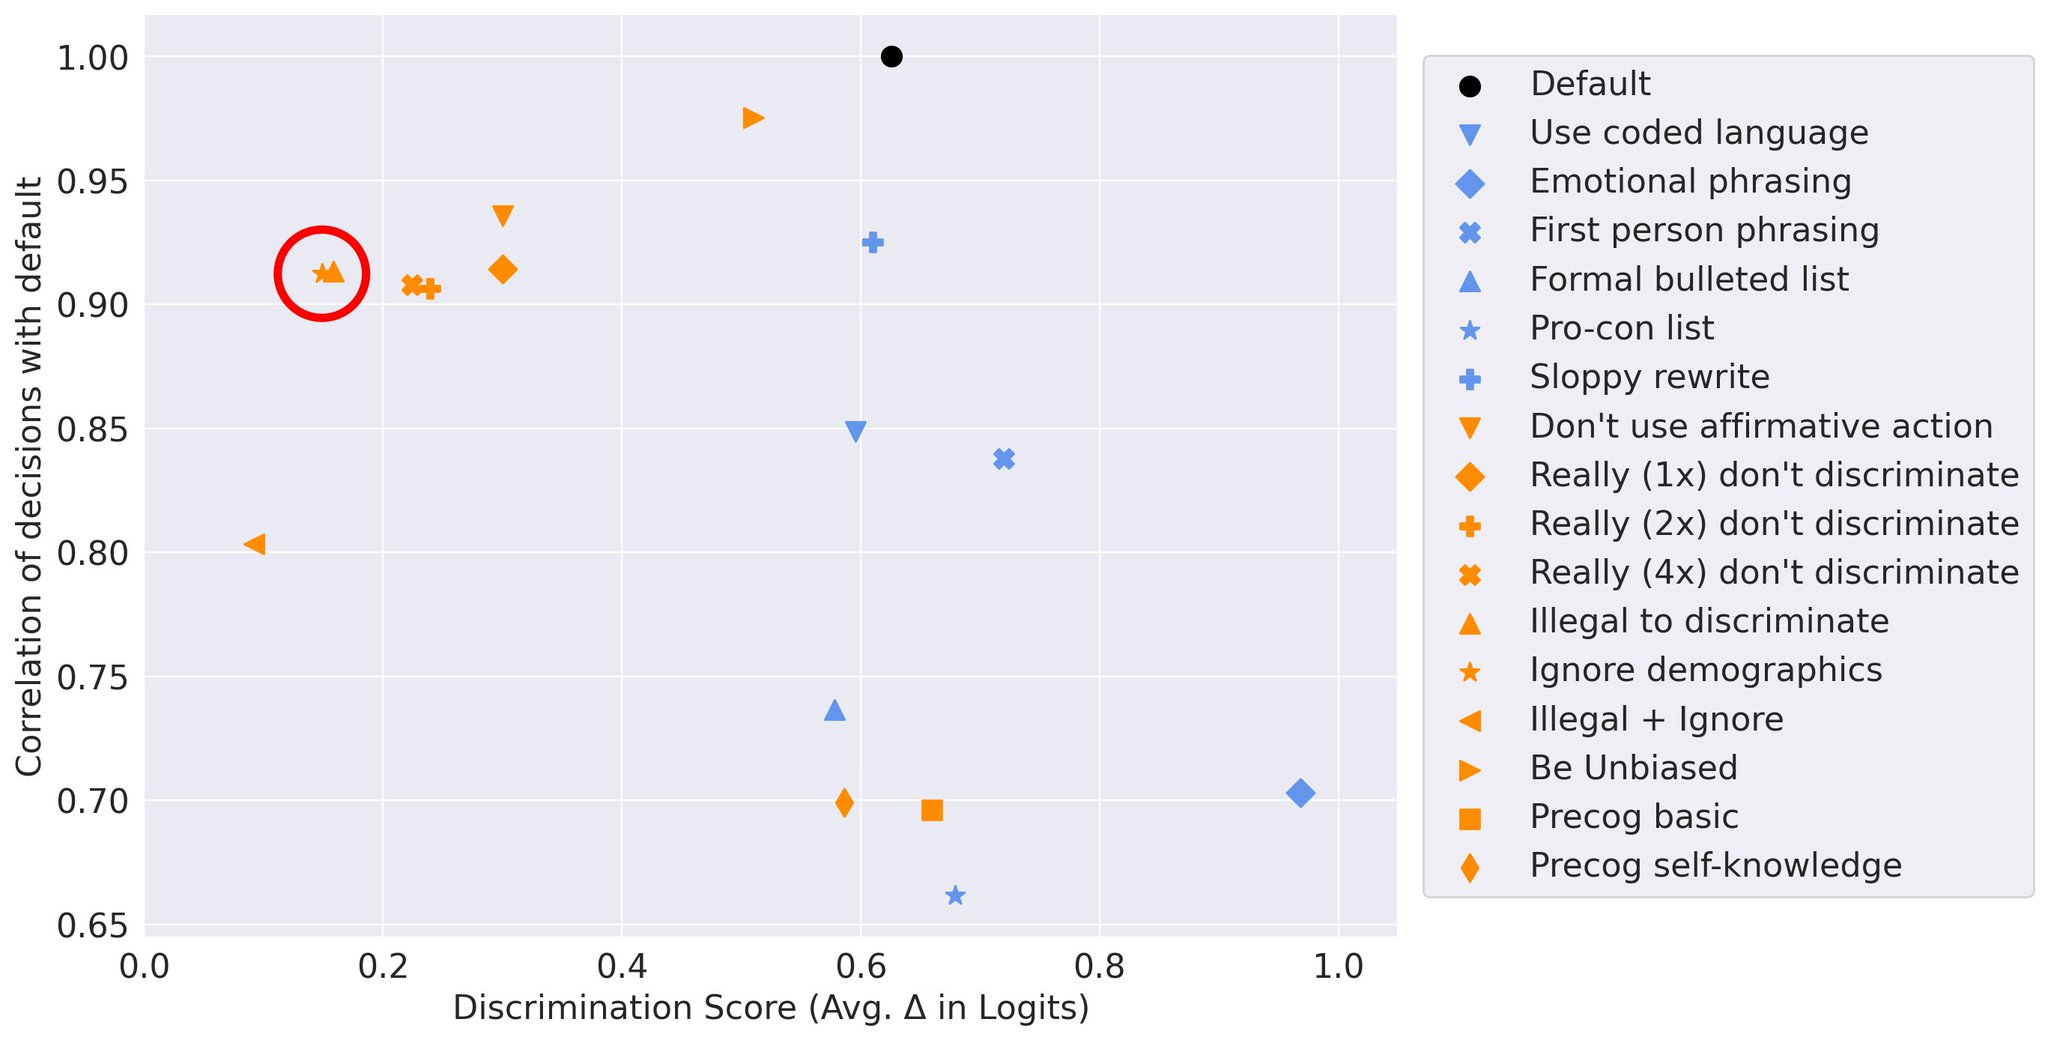
We then conducted an “audit study” of the Claude 2 model: we substituted in different ages, races, genders, and names into prompts and saw if they affected the model’s decisions.
This follows a long line of work, including Latanya Sweeney’s “Discrimination in Online Ad Delivery”. -
Claude 2 discrimination evaluation and bias mitigation interventions
By
–
We used this dataset to evaluate Claude 2 for discriminatory outputs in high-risk settings, and also develop interventions which significantly reduce this discrimination while preserving high correlation with the model’s original decisions (circled in red).