SpaceX (xAI) becoming the next Oracle.
Reflection apparently has immediate access to Nvidia GB300 chips via SpaceX and will pay $150 million per month starting July 1, 2026.
If the deal continues until 2029, the total value would reach approximately $6.3 billion
AI HARDWARE
-

SpaceX/xAI gets Nvidia GB300 chips for $150M/month
By
–
-
Unitree demonstrates G1 humanoid robot voice-to-action capabilities
By
–
#Unitree has demonstrated the voice-to-action capabilities of its humanoid robot G1. #humanoidtech #humanoid #robot #Robotics #AI #TechRevolution #TechInnovation #ArtificialInteligence #PhysicalAI @lexfridman @KirkDBorne @Ronald_vanLoon @erikbryn @antgrasso @sallyeaves
-
Physical AI: Leading Companies Bringing AI into Robots and Machines
By
–
#PhysicalAI is moving artificial intelligence from screens and software into #robots, #drones, self-driving #vehicles and #intelligent #machines. Here are the companies #leading the race to bring #AI into the real world and why their work could reshape #business, work and
-

NVIDIA PiD decodes AI latents to 4K in under a second
By
–
Can you decode AI latents to 4K images in under a second? NVIDIA researchers introduce PiD, a pixel diffusion decoder that unifies decoding and upscaling into one fast step. It converts 512×512 latents to 2048×2048 pixels in under 1 sec on a consumer RTX 5090 — 6x faster than
-
AI Glasses: A Natural Layer Between Humans and Intelligence
By
–
AI glasses are not about replacing the smartphone overnight. They are about creating a more natural layer between humans and intelligence. I explored this in my new video with @Meta
. Watch the full video. Would you trust AI glasses more for productivity, creativity, fitness, -
Glasses as AI interface: see, understand, respond in real time
By
–
AI’s next interface won’t be another app.
— Ronald van Loon (@Ronald_vanLoon) 22 juin 2026
It will be your eyes.
That sounds futuristic, but it is already becoming real with glasses that can see what you see, understand context, and respond in real time.
Here’s why that matters… pic.twitter.com/GFm7VRhHDVAI’s next interface won’t be another app. It will be your eyes. That sounds futuristic, but it is already becoming real with glasses that can see what you see, understand context, and respond in real time. Here’s why that matters…
-

Codex Cli makes local AI easy with hardware-aware optimization
By
–

Let me make Local AI easy for you Give Codex Cli the article below & tell it: – Infer the right Inference Engine from your hardware + article below
– Use uv+venv
– Pick the right kernels
– Tune flags, batching, KVCache, etc
– Optimize for your hardware & chosen model See? Easy -

Amazon and Nvidia Confirm AI Demand, TSMC Unveils 1.4nm Chip
By
–
Amazon and Nvidia Say AI Data Center Demand is Not Slowing Down! TSMC Unveils 1.4nm Chip to Fuel Next-Gen AI and Tech! #BigData #Analytics #DataScience #AI #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming
-

Liquid AI’s Hyena Edge Model Enables LLMs on Smartphones and Edge
By
–


Liquid AI is Revolutionizing LLMs to Work on Edge Devices Like Smartphones with New Hyena Edge Model! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless
-
Why focus on inference engines: performance gains with vLLM and Sglang
By
–
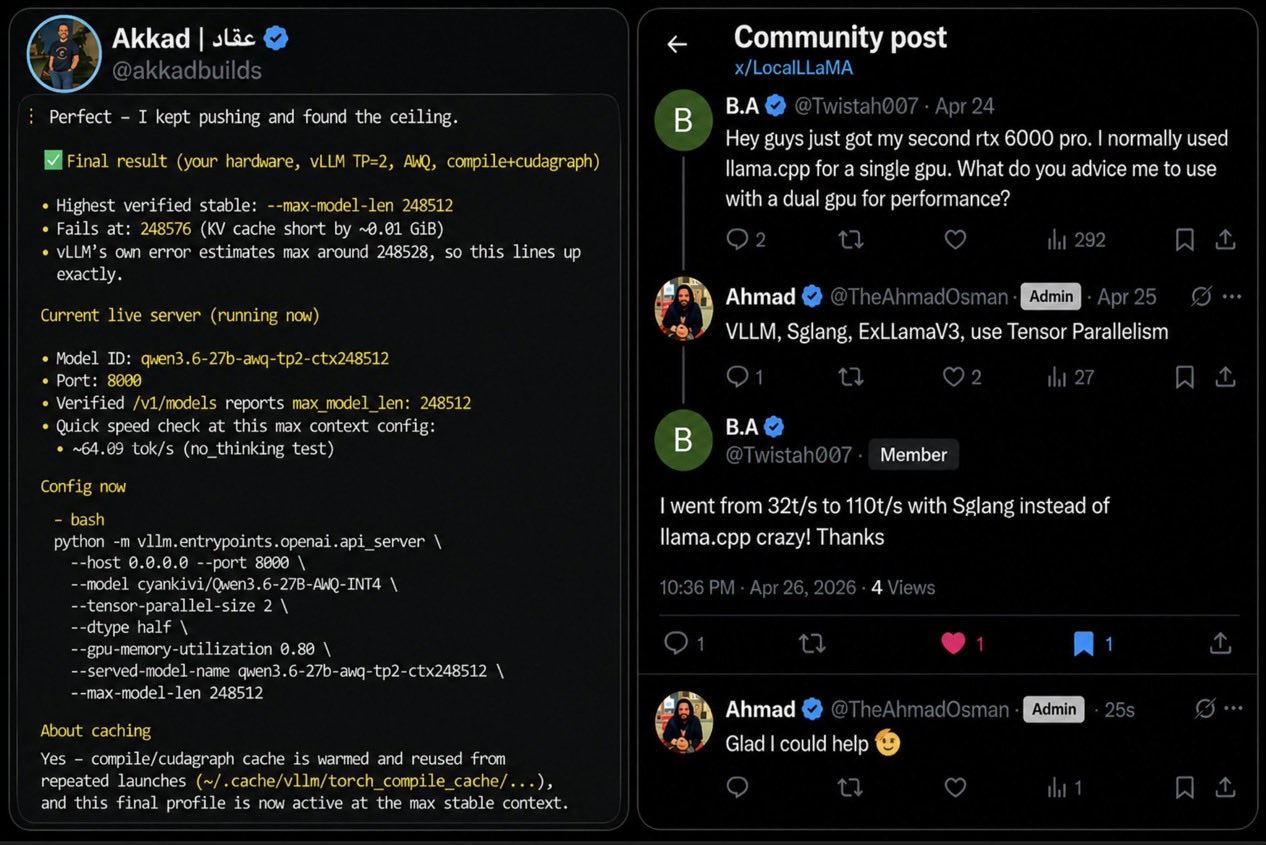
Why do I focus on Inference Engines/Software Stacks for your hardware? – 2x RTX 3090s: ~14.5 tok/s → ~64 tok/s moving to vLLM w/ TP=2 – RTX PRO 6000: ~32 tok/s → ~110 tok/s moving to Sglang So: – CUDA/2+ GPUs: ExLlamaV3/vLLM/Sglang > llama.cpp – Edge: llama.cpp > Ollama