Can you run 8K real-time object detection at the edge? We did—with 57% of compute, leaving plenty to spare. 380 overlapping tiles/sec YOLOv8l model 8K camera, no downscaling All powered by Metis + Voyager SDK Watch it in action https://
eu1.hubs.ly/H0jMJ080
AI HARDWARE
-

8K Real-Time Object Detection at Edge with 57% Compute Efficiency
By
–
-

Jensen Huang and Anirudh Devgan Discuss AI and Accelerated Computing Future
By
–
Join Jensen Huang, Founder and CEO, NVIDIA, and Anirudh Devgan, President and CEO, @Cadence for an exclusive fireside chat at CadenceLIVE. Learn about the future of AI, accelerated computing, and electronic design. https://
nvda.ws/4cYVL1Q -
Always-On Microphone AI: Battery Life Trade-offs Challenge
By
–
This and having your mic on all day on your phone would destroy the battery life. You’d need to charge it every 2-hours.
-

Ukraine’s Rare Earth Elements and AI Industrial Infrastructure Development
By
–
Inevitable. Now: what does Ukraine actually have in terms of REE? Existing surveys are out of date (Soviet Era.) But as I argue, this is directly correlated to the Industrial buildout of Intelligence.
-
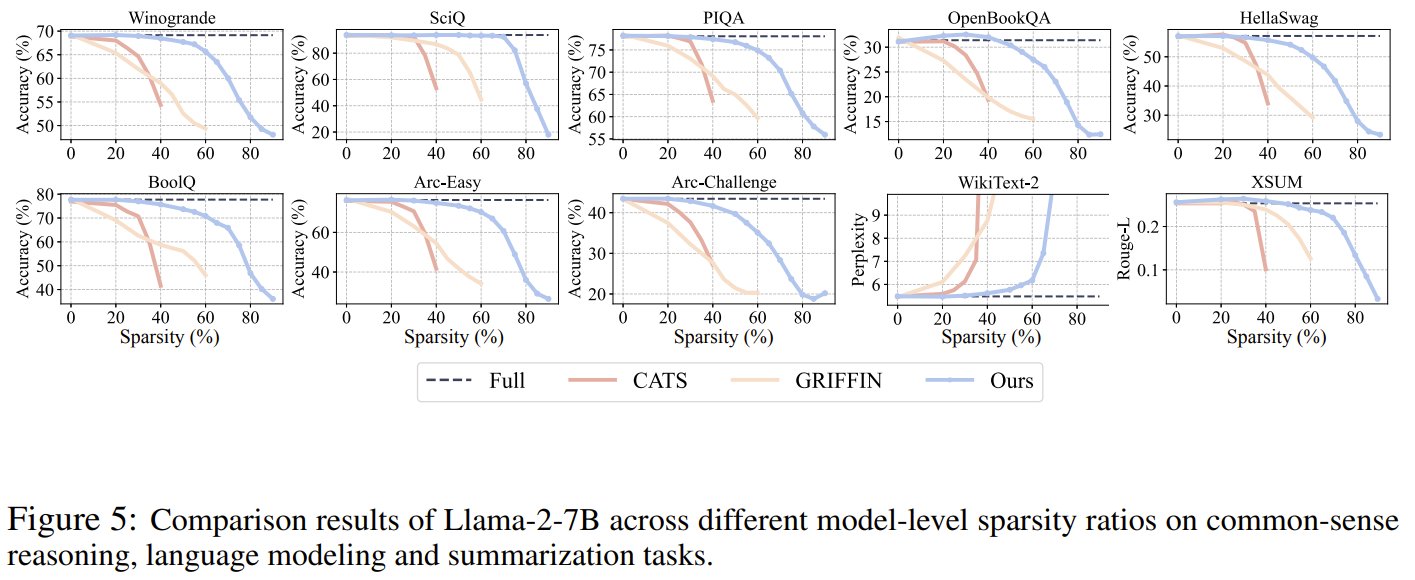
R-Sparse: 50% faster LLM inference without retraining
By
–
What if your LLM ran twice as fast—with zero retraining?
R-Sparse slashes compute by 50% using a clever trick: skip the unimportant math without guessing what to skip. No tuning, no ReLU, no problem. It’s efficient inference, reimagined for the edge. -
Large Sensor Model Improves Wearable Exercise Activity Recognition
By
–
We trained our Large Sensor Model (LSM) on over 40 million hours of de-identified multimodal sensor data from 165K users to demonstrate how it could improve performance in wearable tasks like exercise and activity recognition. Here’s what we found → https://t.co/zD3Tx7ShpO pic.twitter.com/5A2auMYgpd
— Google AI (@GoogleAI) 29 avril 2025We trained our Large Sensor Model (LSM) on over 40 million hours of de-identified multimodal sensor data from 165K users to demonstrate how it could improve performance in wearable tasks like exercise and activity recognition. Here’s what we found → https://
goo.gle/4fYDQJ4 -
LlamaCon Event: Groq Accelerates Meta’s Llama API
By
–
LlamaCon in full swing! Swag, friends, customer demos from @MaitaiAI
, the @AIatMeta Llama API accelerated by Groq. It's a good day -

Cerebras Inference Now Available on Llama API Platform
By
–
Cerebras launched inference just 8 months ago. Today it is officially part of Llama API. Any developer can now click a button and get a wafer-scale chip to generate tokens at ~2,600 t/s. Insane progress.
-
Cerebras Inference Platform Delivers High-Speed AI Processing
By
–
Feel the speed: https://
inference.cerebras.ai -

Official Llama API Accelerated by Groq Partnership
By
–
The Official Llama API ⚡️Accelerated by Groq
— Groq Inc (@GroqInc) 29 avril 2025
In partnership with @AIatMeta.
The fastest way to run Llama with no tradeoffs.
Preview now live. pic.twitter.com/8C8DXFpfSCThe Official Llama API Accelerated by Groq In partnership with @AIatMeta
.
The fastest way to run Llama with no tradeoffs.
Preview now live.