The team just added a little extra holiday spirit to @Copilot! Meet Eggnog Mode Mico – live now in the US, UK, and Canada, only available for the holidays. Toggle on by just clicking the ⛄ icon while talking to Mico. pic.twitter.com/zDQM3548BA
The team just added a little extra holiday spirit to @Copilot
! Meet Eggnog Mode Mico – live now in the US, UK, and Canada, only available for the holidays. Toggle on by just clicking the icon while talking to Mico.
The magic lies in 3 core actions: Retain: Store memories naturally (e.g., "User prefers functional programming"). Recall: Query with context and time awareness. Reflect: Get a synthesised perspective, not just a raw data dump.
Hindsight is an open-source Long Term Memory system built specifically for AI agents. It goes beyond simple vector search. We're talking: Temporal reasoning ("What did I do last spring?") Connecting disconnected facts Formulating opinions & personalities
Building AI agents is all cool until the lack of context, LLM hallucinations and inconsistent retrieval hit the pipeline: Enter Hindsight by @vectorize_io: an open-source framework designed to make the memory work like a human:
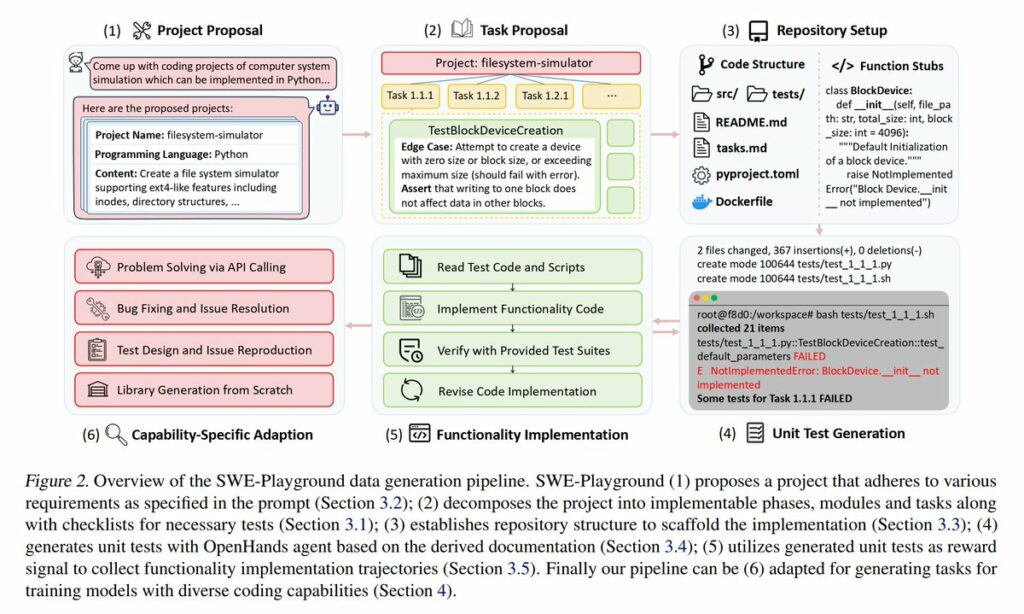
There are many good training methods for improving agents on SWE-bench: SWE-Gym, SWE-Smith, R2E-Gym. But what about broader software engineering tasks? In SWE-Playground, we introduce a new, more diverse synthetic data generation strategy to train divers software agents. Yiqi Zhu (@StephenZhu0218) Introducing SWE-Playground: A fully automated pipeline that generates synthetic environments to train versatile coding agents. 🤖✨ Training software engineering agents often relies on existing resources like GitHub issues and focuses on solving SWE-bench style issue resolution tasks. While this has driven incredible progress, real-world engineering involves a wider spectrum of tasks —from designing new libraries to writing reproduction scripts. 🌐 Rather than mining existing repositories, SWE-Playground synthetically generates projects, tasks, and verifiable unit tests from scratch. This approach offers two exciting opportunities: 1️⃣ Flexibility: We can generate tasks without being constrained by the availability or structure of existing open-source data. 2️⃣ Versatility: We extend training beyond Issue Resolution to include Issue Reproduction and Library Generation from Scratch. The results? 🚀 Our agents achieve strong performance across SWE-bench Verified, SWT-Bench, and Commit-0, demonstrating high data efficiency compared to baselines trained on larger datasets. Huge thanks to my amazing collaborators @apurvasgandhi and @gneubig for their incredible efforts on bringing this work to life! 👇 🧵 A deep dive into how we build versatile agents synthetically. Paper: arxiv.org/pdf/2512.12216 Project Page: neulab.github.io/SWE-Playgro… Code: github.com/neulab/SWE-Playgr… Data & Models: huggingface.co/collections/S… — https://nitter.net/StephenZhu0218/status/2000754124019683469#m
The problem with classic AIs? They're stuck in a chat window. The 2026 revolution is AI that acts WITHIN your system. To truly delegate, not just do things with AI's help. And for that, this tool is perfect → https://
youtu.be/pt_GoaONb2Y
20 must-try AI tools for 2025. This stack covers everything: chat & reasoning image gen video gen voice/music AI search automation AI agents My top 3 right now: ChatGPT, Perplexity, Midjourney. What are yours? #AI #AITools #GenerativeAI #Automation
Vibe Agent in AI21 Maestro helps you create AI agents from a single plain-English description. It suggests purpose, validation checks, tools, and model/compute settings while explaining each step in real time.
Vibe Agent in AI21 Maestro helps you create AI agents from a single plain-English description. It suggests purpose, validation checks, tools, and model/compute settings while explaining each step in real time. Watch the video and start building with AI21 Maestro:
NVIDIA Nemotron 3 Explained — a quick breakdown of NVIDIA’s new agent-ready AI model family built for reasoning, chat, RAG, and instruction-following. Learn how Mixture-of-Experts (MoE) architecture enables lower latency, lower cost, and scalable deployment, with Nano, Super,