Important nuance: “long-horizon” ≠ “complex task.” It’s about planning under uncertainty across many steps. Some evals test long histories, not long futures. Our bandit toy shows frontier models still go greedy. Great clarifier, @chris_m_glaze
@snorkelai
-
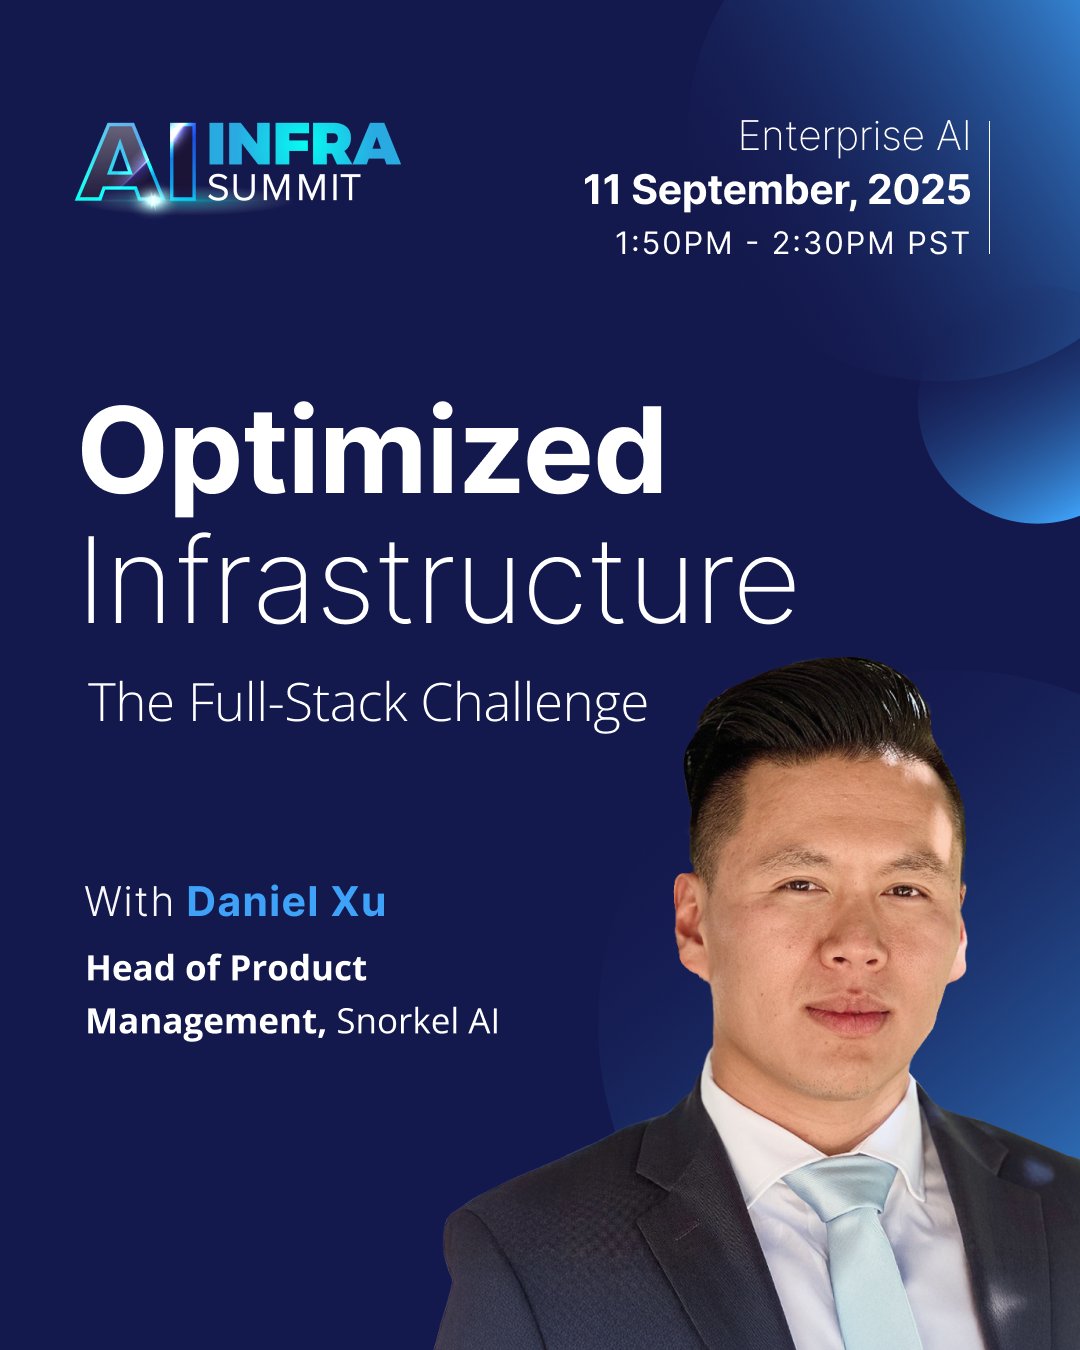
Snorkel’s Optimized Infrastructure Panel at AI Infra Summit
By
–
Snorkel’s Daniel Xu → “Optimized Infrastructure” panel, Sept 11, 1:50–2:30 PM. TY @awscloud + Amazon SageMaker for hosting; joined by Walgreens Boots Alliance, @datadoghq
, Lablup Inc. #AIInfraSummit -
Expert-Verified Datasets for AI Application Evaluation
By
–
We partner with our network of vetted experts, using detailed evaluation rubrics to generate high-quality datasets that improve AI applications. Follow us @SnorkelAI for updates, & if you need expert-verified datasets for your evaluation needs, talk to us!
-
SnorkelGraph: Expert-Verified Benchmark Suite for LLM Reasoning
By
–
SnorkelGraph is part of our expert-verified benchmark suite, designed to systematically test LLM reasoning across math, spatial, and graph domains. Follow us for updates, and if you need expert-verified datasets for your evaluation needs, talk to us!
-
Controlling Graph Reasoning Difficulty: Size and Operator Complexity
By
–
We control difficulty with: Graph size: more nodes/edges = more elements to reason over Operator complexity: different ops stress different reasoning skills (counting, paths, optimization)
-
Snorkel Graph Benchmark Shows Significant Room for Advancement
By
–
As the leaderboard shows, this benchmark is far from saturation ATM: https://
leaderboard.snorkel.ai/category/snork
elgraph
… We’re looking forward to seeing continued advances in this skill, particularly in open models. -
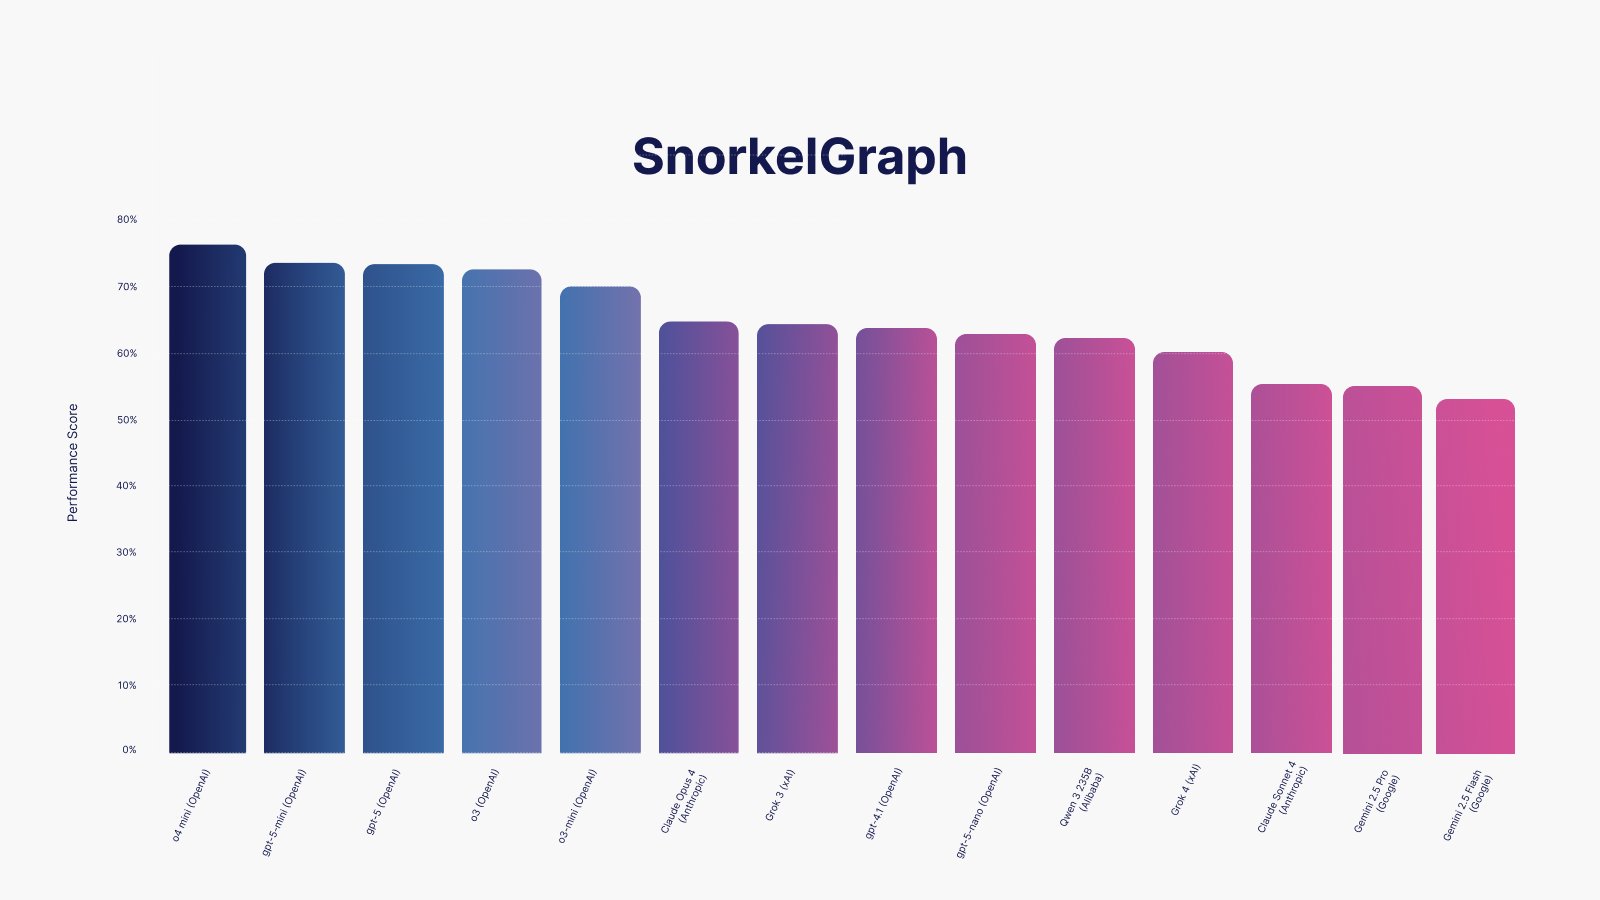
SnorkelGraph: Graph Reasoning Benchmark for LLMs
By
–
Operations in graph theory are fundamental to analyzing complex systems, and provide a multi-hop, long-context reasoning challenge for LLMs. That’s why we built SnorkelGraph: a benchmark for evaluating graph reasoning with verifiable ground truth. https://
leaderboard.snorkel.ai/category/snork
elgraph
… -
Evaluating LLM reasoning on graph-based natural language tasks
By
–
Each question asks the LLM to compute the outcome of a natural language question (operator) over graphs encoded via node + edge lists. Example: “Find the minimum-density subgraph…” Because these questions all come with verifiable answers, LLM responses are easy to evaluate.
-
Expert-Curated Datasets Improve Small Model Reasoning Skills
By
–
Want to improve a smaller model’s reasoning skills? Our DaaS team is building expert-curated datasets for reasoning, function calling, and more. Let’s talk!
-
Reasoning Models Outperform: Inference-Time Compute Advantage
By
–
Key insights:
Reasoning > non-reasoning models. Better living through inference-time compute!
Smaller open-weights models struggle without fine-tuning or other post-training optimization
SnorkelWordle is a strong signal for evaluating reasoning, especially in smaller models