What makes Snorkel's contribution unique? We're bringing our expertise to help:
• Contribute tasks
• Calibrate task difficulty
• Provide sophisticated performance analysis
• Expand the benchmark's evaluation techniques
@snorkelai
-
Snorkel Enhances AI Benchmark with Task Calibration and Analysis
By
–
-
Terminal-Bench 2.0 Advances SOTA for Next-Gen AI Agents
By
–
We’re excited to contribute to Terminal-Bench 2.0, and help advance SOTA for evaluating next-gen AI agents. S/O: @Mike_A_Merrill @alexgshaw @terminal_bench @StanfordAILab @LaudeInstitute Read more:
-
Terminal-Bench: Evaluating AI Coding Assistants Performance
By
–
Why does Terminal-Bench matter?
AI coding assistants (Claude Code, Codex, Cursor, & Devin) rely on command-line interfaces. The terminal represents a convergence of power, flexibility, & the text-based modality where language models excel—hence the need for robust evaluation. -
Terminal-Bench Gains Recognition Across Major AI Models
By
–
The industry is taking notice Terminal-Bench scores now appear on: DeepSeek-V3.1-Terminus model card Qwen3-Coder release Claude Sonnet 4.5 announcement
800+ GitHub stars | ~100 developer contributors -
Advanced AI Agents Benchmark Performance Comparison
By
–
Terminal-Bench is challenging even for the most advanced agents: • OpenAI's Codex (gpt-5-codex): 42.8% verified score • Anthropic’s Claude Code (claude-sonnet-4-5): 50.0% per their release announcement • Leaderboard:
-
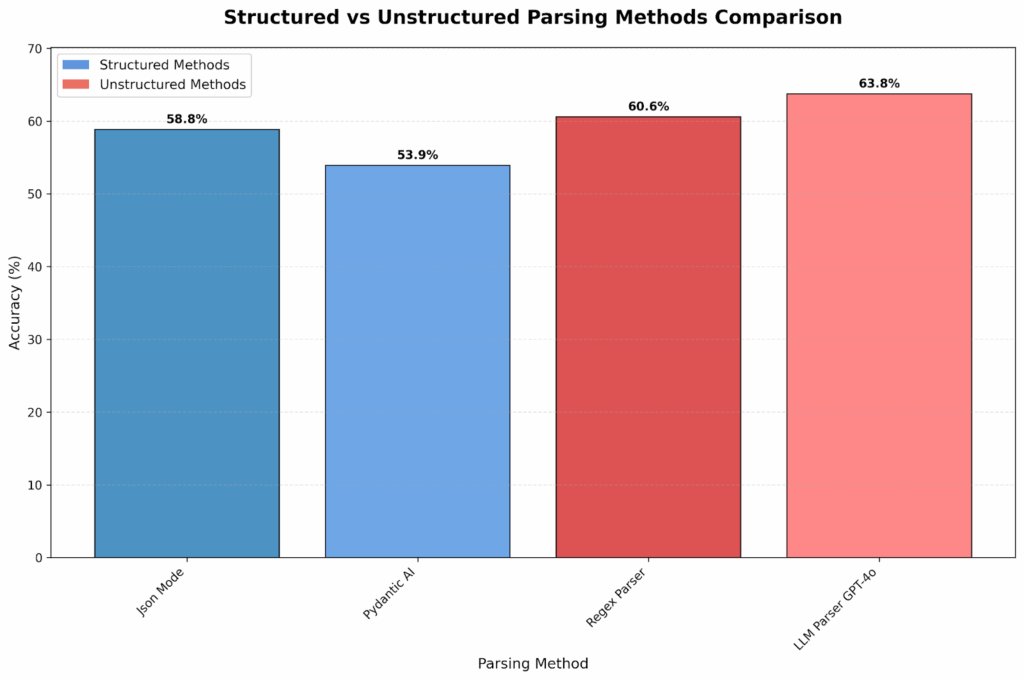
Flexible parsing unlocks hidden capabilities in weaker language models
By
–
Flexible parsing revealed hidden capabilities in weaker models LLM-based parsers captured valid answers from free-form reasoning, improving reported accuracy for models that struggled with rigid constraints. It’s a trade-off: exactness versus resilience.
-
Parsing and Evaluation: Technical Foundations for AI Systems
By
–
The bottom line: Parsing isn't just a technical detail. It's part of the evaluation story. Don’t forget to follow us @snorkelai and @realjustinbauer – and if you have questions about evals, RL environments, and expert-developed datasets, talk to us!
-
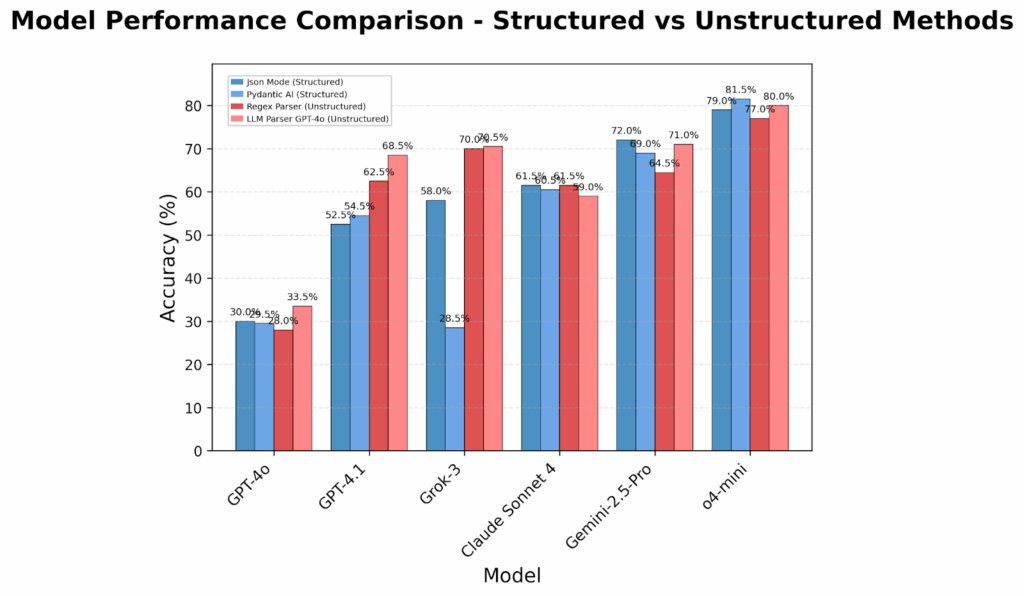
Structured Formats Limit AI Reasoning Capabilities
By
–
Structured formats can actually constrain reasoning Models like GPT-4.1 and Grok-3 performed worse when forced into rigid JSON structures. The formatting requirements limited their ability to think through complex problems.
-
Reasoning Models Show Resilience Across Parsing Methods
By
–
Reasoning-first models stayed resilient Claude Sonnet 4, Gemini 2.5 Pro, and o4-mini showed minimal sensitivity to parsing methods—their strong reasoning held steady across formats.
-
Parsing Evaluation Choices Impact AI Neutrality Analysis
By
–
New blog post! Parsing isn’t Neutral: https://
snorkel.ai/blog/parsing-i
snt-neutral-why-evaluation-choices-matter/
… @realjustinbauer breaks down what we found: