From isolated snippets → full workflows. Proud to partner with @Stanford and @LaudeInstitute on #TerminalBench 2.0 — helping redefine agent evaluation. Thanks @Mike_A_Merrill and @alexgshaw for leading the charge and allowing our researchers the opportunity to contribute.
@snorkelai
-
RL Environments Research Blog by ArminPCM Team
By
–
Brilliant work by @ArminPCM and our research team on the latest RL Environments themed blog. Dive in
-
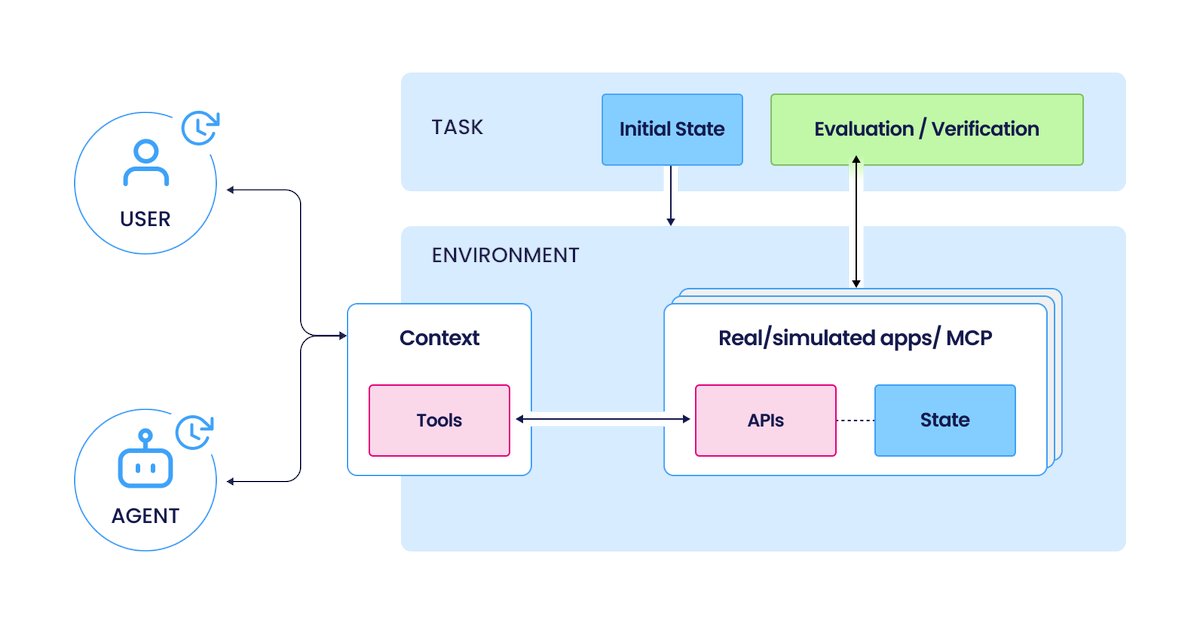
Building Advanced RL Environments for Reliable AI Reasoning
By
–
A good RL environment is more than a sandbox — it’s a system with:
– Real tools & APIs
– Stateful feedback
– Deterministic rewards & rubrics At Snorkel, we combine expert-built tasks + automated QC to create environments that truly measure reasoning and reliability. -
Snorkel Builds Enterprise-Grade Reinforcement Learning Environments
By
–
New from @ArminPCM : how Snorkel builds reinforcement learning (RL) environments that train and evaluate agents in realistic, enterprise-grade settings.
-
Agents Handle Snorkel-Contributed Tasks at Upcoming Event
By
–
Excited for this release — can't wait to see how agents handle the Snorkel-contributed tasks! We'll be at the event too — see you there!
-
AI Models Spatial Reasoning Leaderboard Challenge
By
–
Each model sees only text — no images — and must track every rotation and translation step-by-step to predict where things end up. Explore the leaderboard → http://
leaderboard.snorkel.ai/category/spati
al
… -
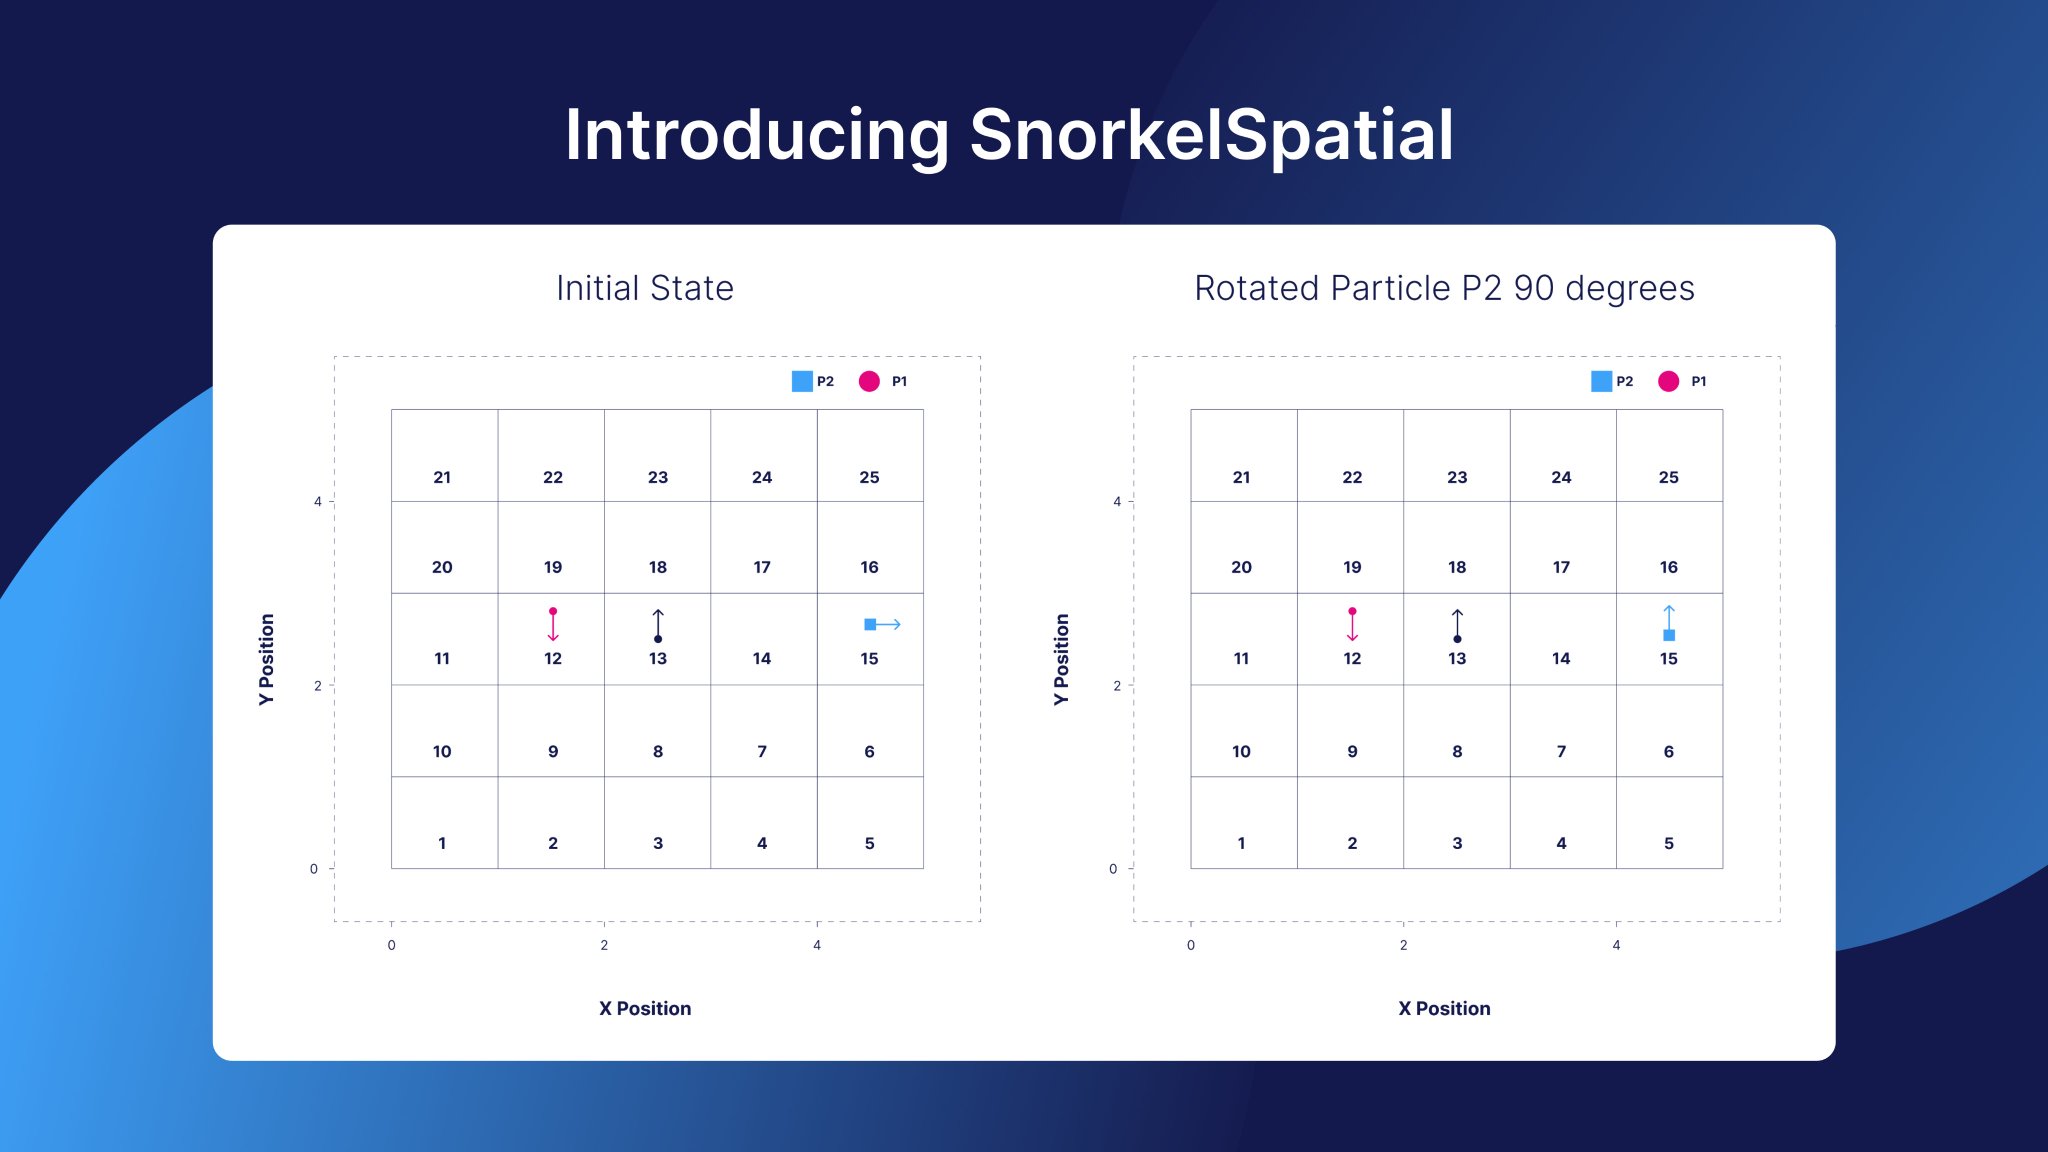
SnorkelSpatial Benchmark Tests LLM Spatial Reasoning Abilities
By
–
New benchmark drop SnorkelSpatial tests how well LLMs can think in space, following text-based moves and rotations in a 2D world.
-
Rubric-Driven Evaluation Improves LLM Alignment and Data Quality
By
–
Rubric-driven evaluation doesn’t just improve human and LLMaJ alignment. It accelerates delivery, reduces rework, and improves the thing we care about most: data quality.
-
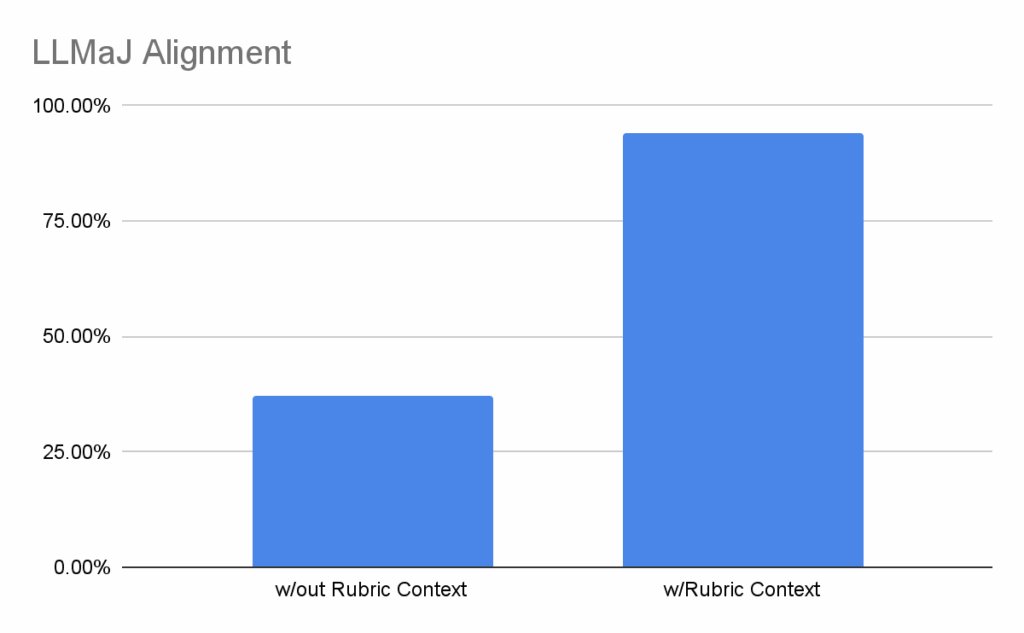
LLM-as-Judge Alignment Improves to 94% With Structured Evaluation
By
–
After refining our rubric design process, alignment between human reviewers and LLM-as-a-Judge improved from 37 % → 94 % — proof that structured evaluation enhances consistency.
-
Trusted Scale: Snorkel’s Framework for Scaling Trust in AI
By
–
This is Trusted Scale — Snorkel’s framework for designing, validating, and scaling trust in AI data pipelines. Read the full post by @pham_derek →
https://
snorkel.ai/blog/scaling-t
rust-rubrics-in-snorkels-quality-process/
… #AI #LLM #DataQuality #SnorkelAI #MachineLearning