We’re hiring! The Snorkel DaaS Ops team is growing — with multiple roles open across data engineering, operations, and analytics. Interested in AI, data pipelines, or working at the intersection of ML + delivery?
Check out open positions (remote & on-site) →
@snorkelai
-
Snorkel DaaS Ops Team Hiring: Data Engineering and ML Roles
By
–
-
Thanking Partners Advancing AI Through Better Data
By
–
Grateful today—and every day—for the people pushing AI forward with better data.
— Snorkel AI (@SnorkelAI) 27 novembre 2025
From researchers to partners to customers, thank you for helping us advance how AI learns and performs. 🦃 📊 ✨ pic.twitter.com/MT3tEVLQYaGrateful today—and every day—for the people pushing AI forward with better data. From researchers to partners to customers, thank you for helping us advance how AI learns and performs.
-
Self-Verification as Adversarial Training Signal for AI Models
By
–
The key takeaway:
Critique is for debugging — not polishing.
When the same model plays both “actor” and “judge,” self-verification can become an adversarial training signal.
Read the full breakdown → -
Self-Critique in Agentic AI: Benefits and Risks Explained
By
–
Self-critique is a core pattern in agentic AI — but it turns out to be dangerous in the wrong place.
New blog from @ArminPCM show: Self-critique helps when models are failing It destroys accuracy when models are already right
This has big implications for RLAIF, RLFT, and -

SEA Workshop on Scaling Environments for AI Agents
By
–
Next week at #NeurIPS2025 → the SEA Workshop on scaling environments for agents. If you care about eval, RL, or containerized rollouts — this is the room. Proud to sponsor this workshop. Shoutout to @guohao_li , @lawhy_X , @douglas_ym and @celineee_xie , along with the rest
-
DaaS Operations Hiring: Join Our Growing Team
By
–
Join the fun….come build with us. We’re hiring for DaaS Operations:
-

NeurIPS 2025 Highlights: Scalable Agents Workshop and Research
By
–
Continuing our #NeurIPS2025 highlights — looking forward to a great conference this year. Papers exploring expert data, benchmark quality, RL environments, and evaluation design The SEA Workshop (Dec 7), bringing together researchers pushing the boundaries of scalable agent
-
Terminal Bench 2.0: Reliable Powerful Agents and Harbor Platform
By
–
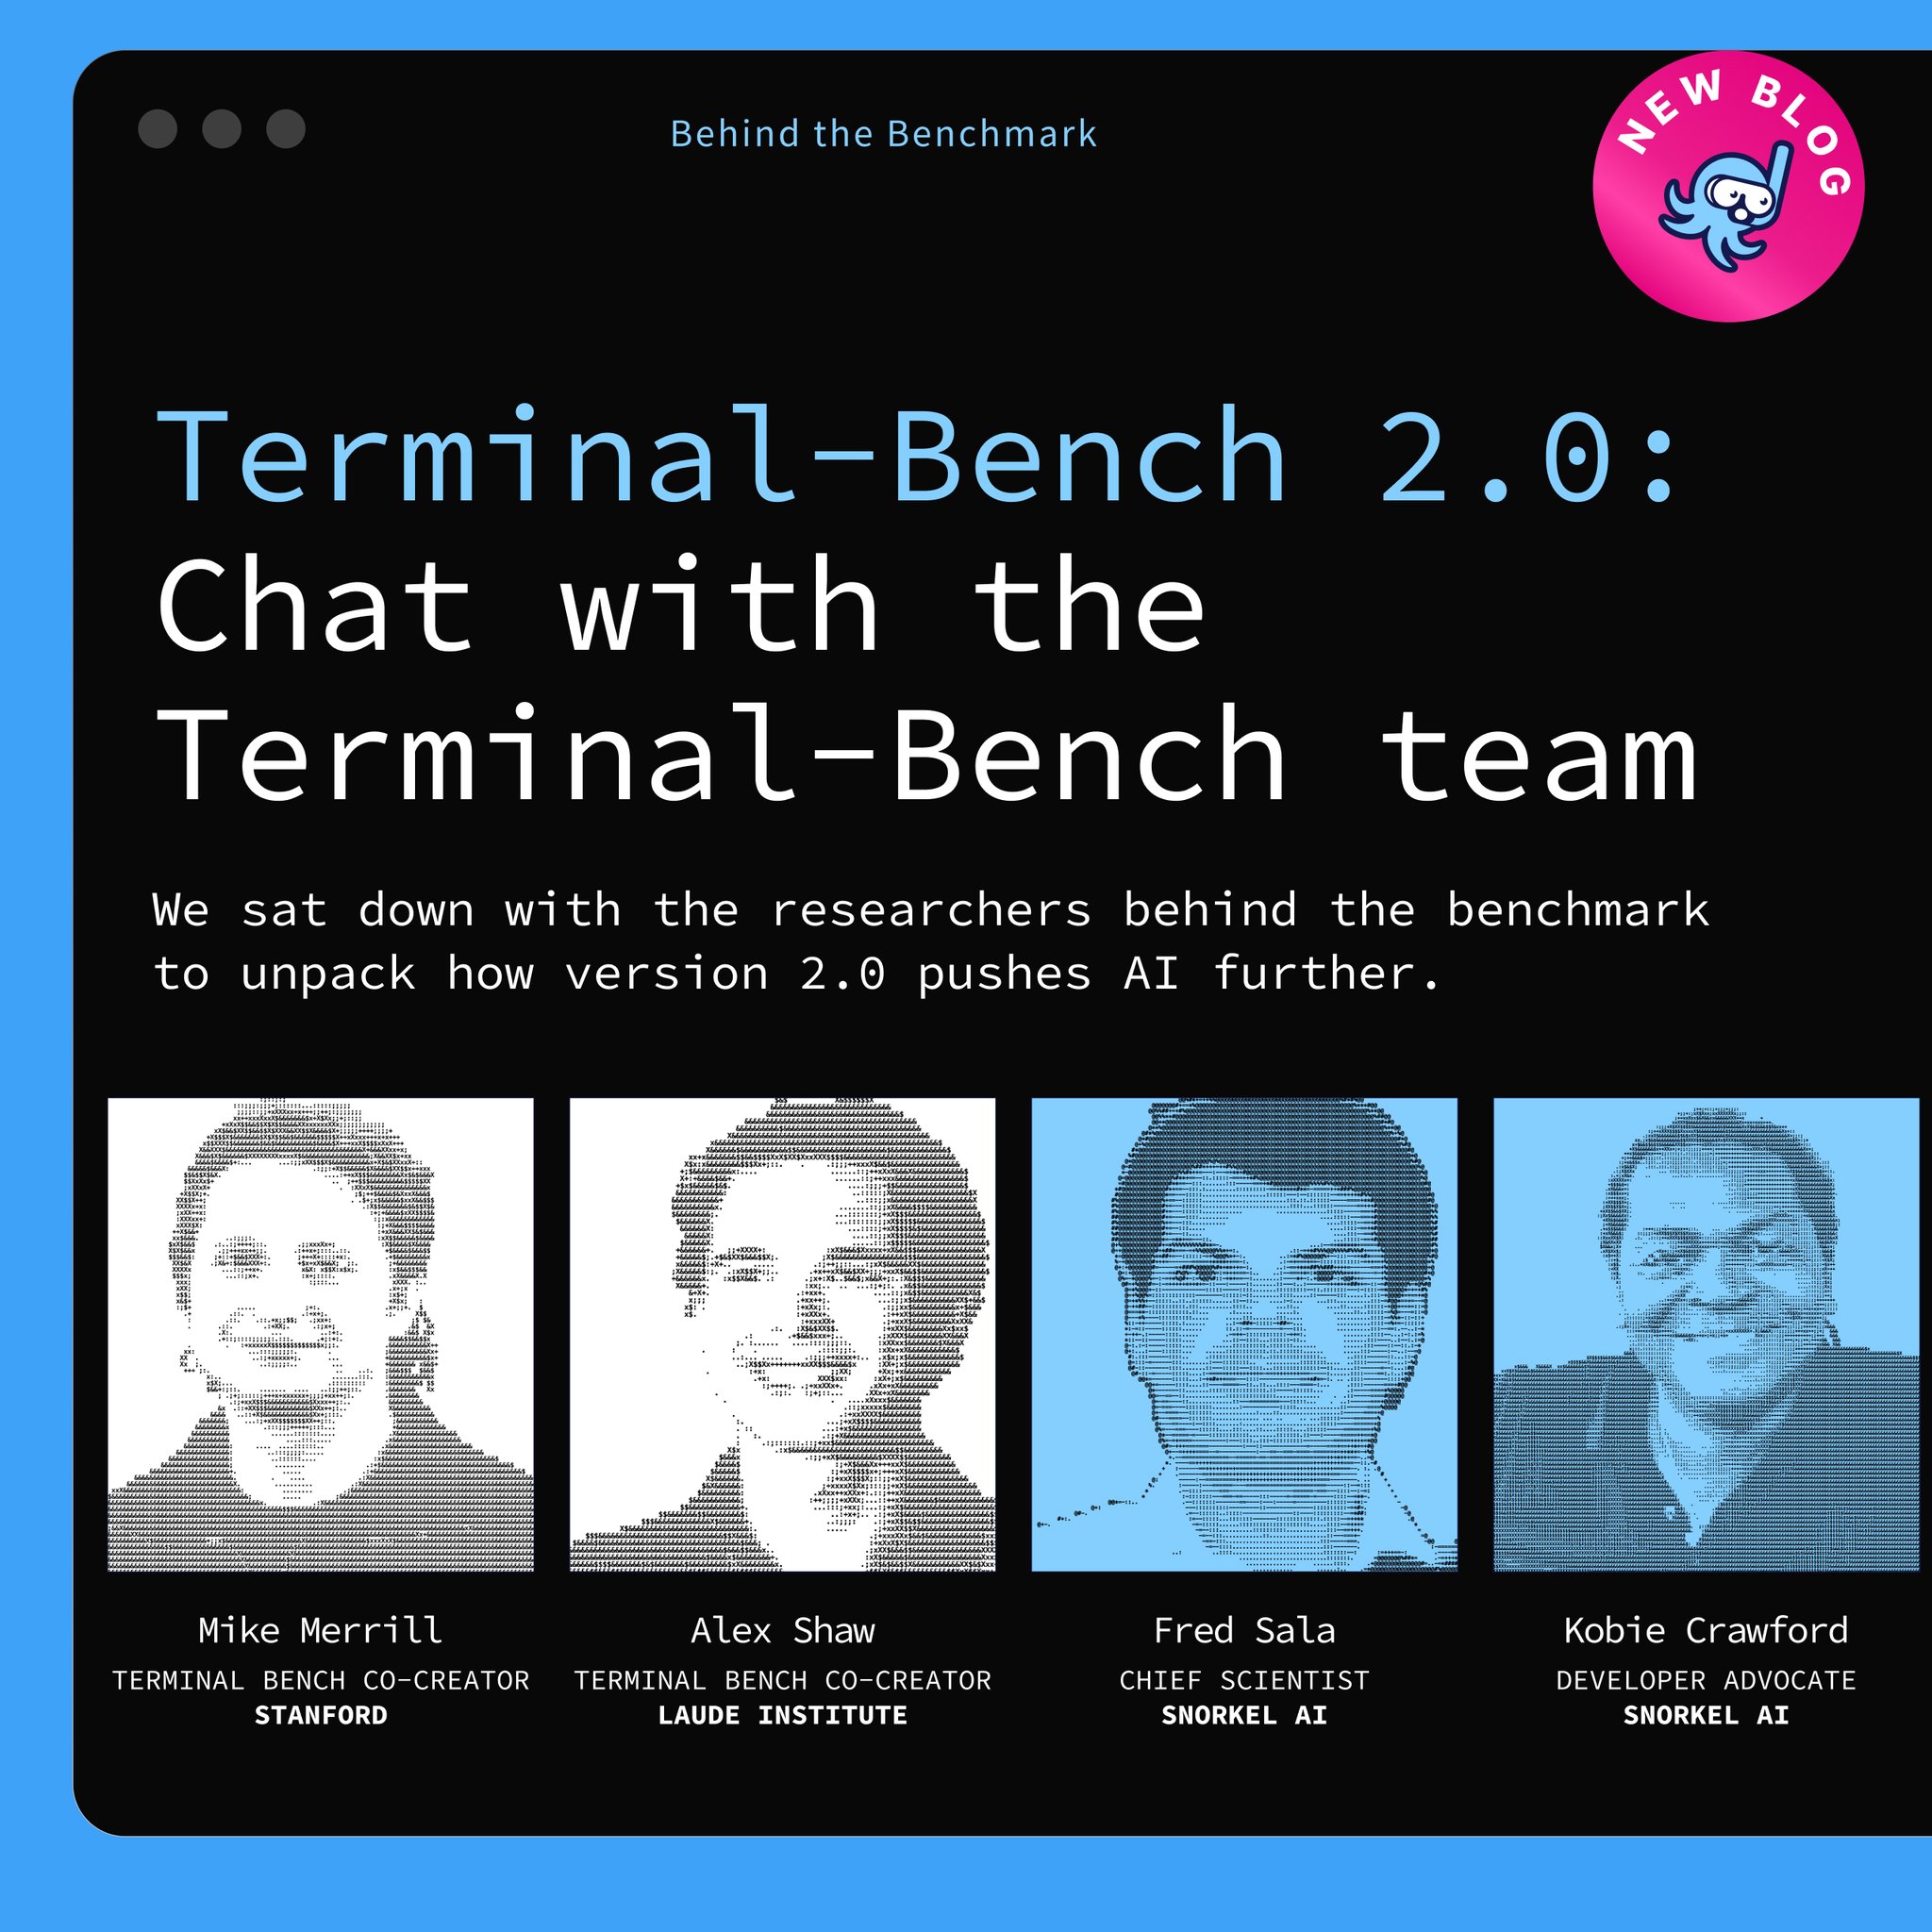
We had a terrific interview with the creators of Terminal Bench 2.0. They unpack:
• why terminals → more reliable and powerful agents
• key design tradeoffs in TB 2.0
• Creating Harbor to enable eval, RL, and agent workflows at scale
• lessons from building a 100+ -
Snorkel AI Launches Terminal-Bench 2.0 and Harbor Tool
By
–
Congrats to the Terminal-Bench team from Snorkel AI! Thrilled to see Terminal-Bench 2.0, and excited to see Harbor — a game-changer. @laudeinstitute @stanfordailab @mike_a_merrill @alexgshaw @lschmidt3 @andykonwinsky @bradenjhancock
-
Snorkel Advances Agentic AI Safety with Terminal-Bench
By
–
By codifying harder, more realistic terminal tasks, we’re pushing agentic AI to be safer, smarter, and more capable. Explore Snorkel’s contribution to Terminal-Bench 2.0: https://
bit.ly/482E28L