Your GenAI model might be underperforming, and you wouldn’t know. Outdated eval methods miss hidden failure modes in agentic systems. Rubric-based evaluation fixes that. What it is & why it matters https://
snorkel.ai/blog/data-qual
ity-and-rubrics-how-to-build-trust-in-your-models/
…
@snorkelai
-
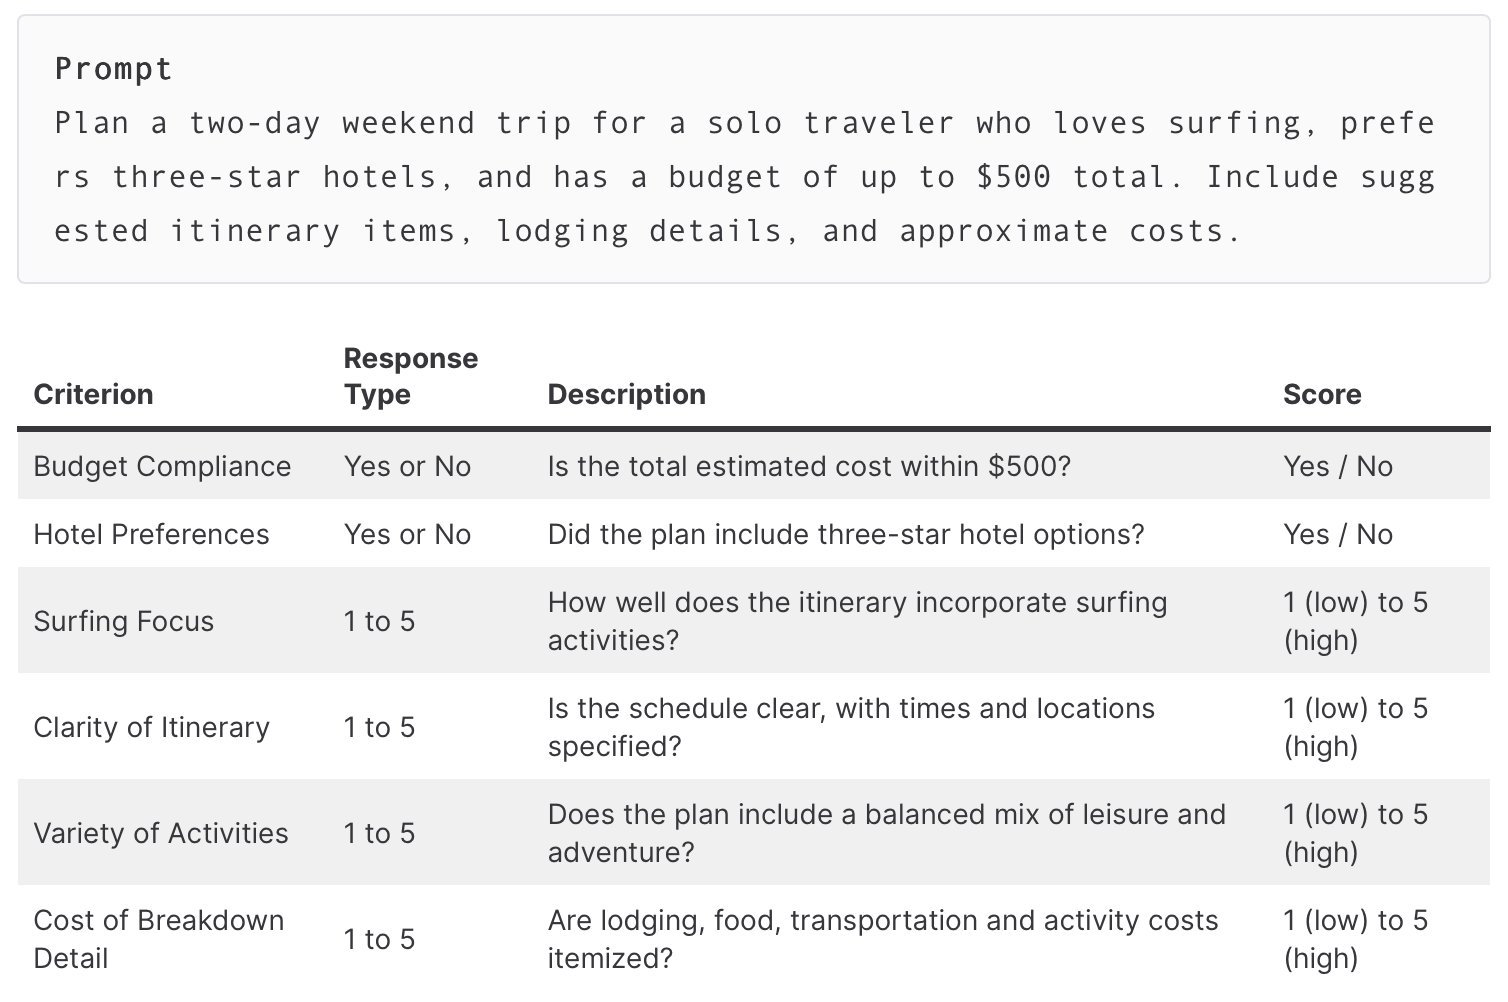
Improving GenAI Model Evaluation: Rubric-Based Methods for Agentic Systems
By
–
-
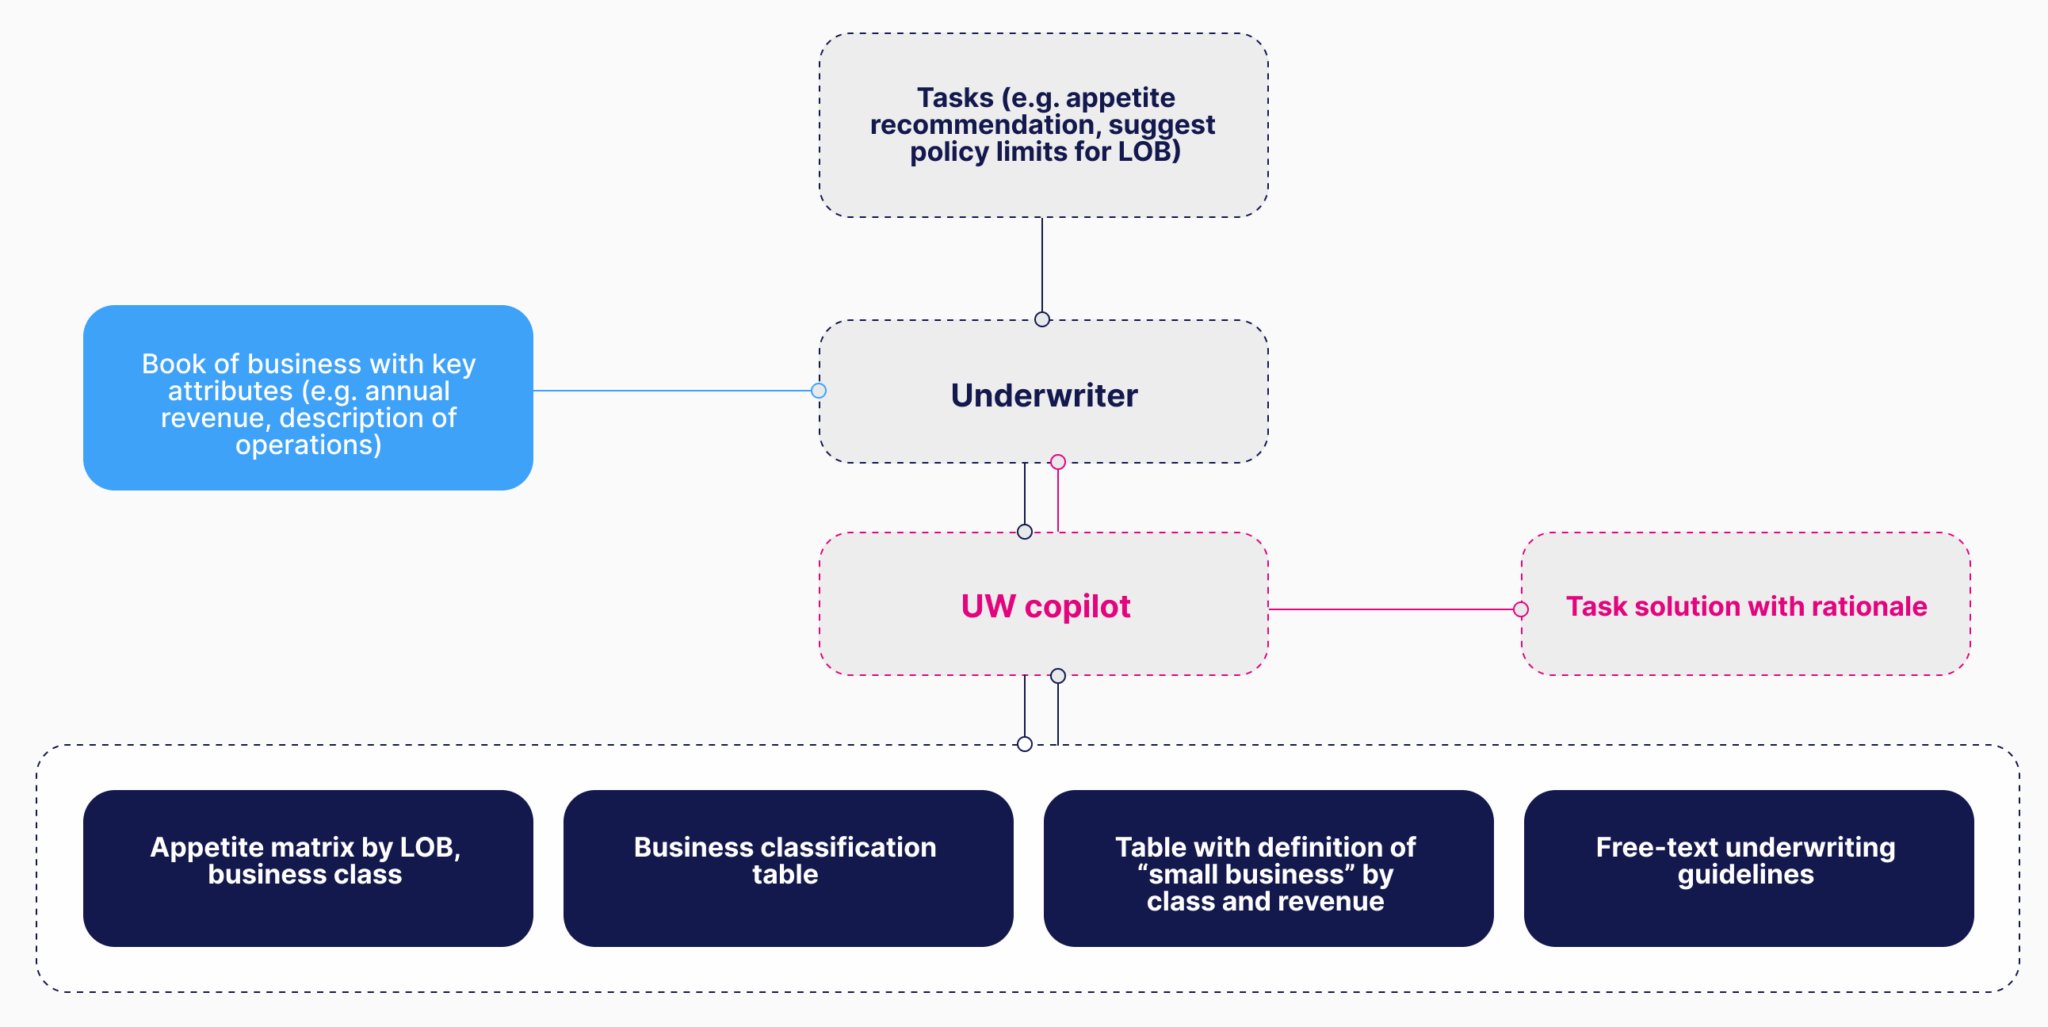
AI Copilots for Insurance Underwriting: Enterprise Readiness Benchmark
By
–
Can an AI copilot underwrite insurance? We built a benchmark with real underwriters to find out. Top models struggled with tool use, hallucinations, and basic reasoning. See what it takes to build enterprise-ready AI https://
snorkel.ai/blog/evaluatin
g-ai-agents-for-insurance-underwriting/
… #AI #InsuranceTech #SnorkelAI -
Scaling Expert Data: Trust Over Technology in AI
By
–
Community builder, ops lead, pickleballer. Jake Shaver breaks down what it takes to scale expert data and why the future of AI starts with trust, not just tech.
— Snorkel AI (@SnorkelAI) 28 juillet 2025
Full chat here 👉 https://t.co/kYaiwApyht#AI #LLM #ExpertData pic.twitter.com/pts3x4ZUIaCommunity builder, ops lead, pickleballer. Jake Shaver breaks down what it takes to scale expert data and why the future of AI starts with trust, not just tech. Full chat here https://
youtu.be/MGLKPygGR30 #AI #LLM #ExpertData -
Multi-Turn Insurance Underwriting: Open-Source LLM Evaluation Benchmark
By
–
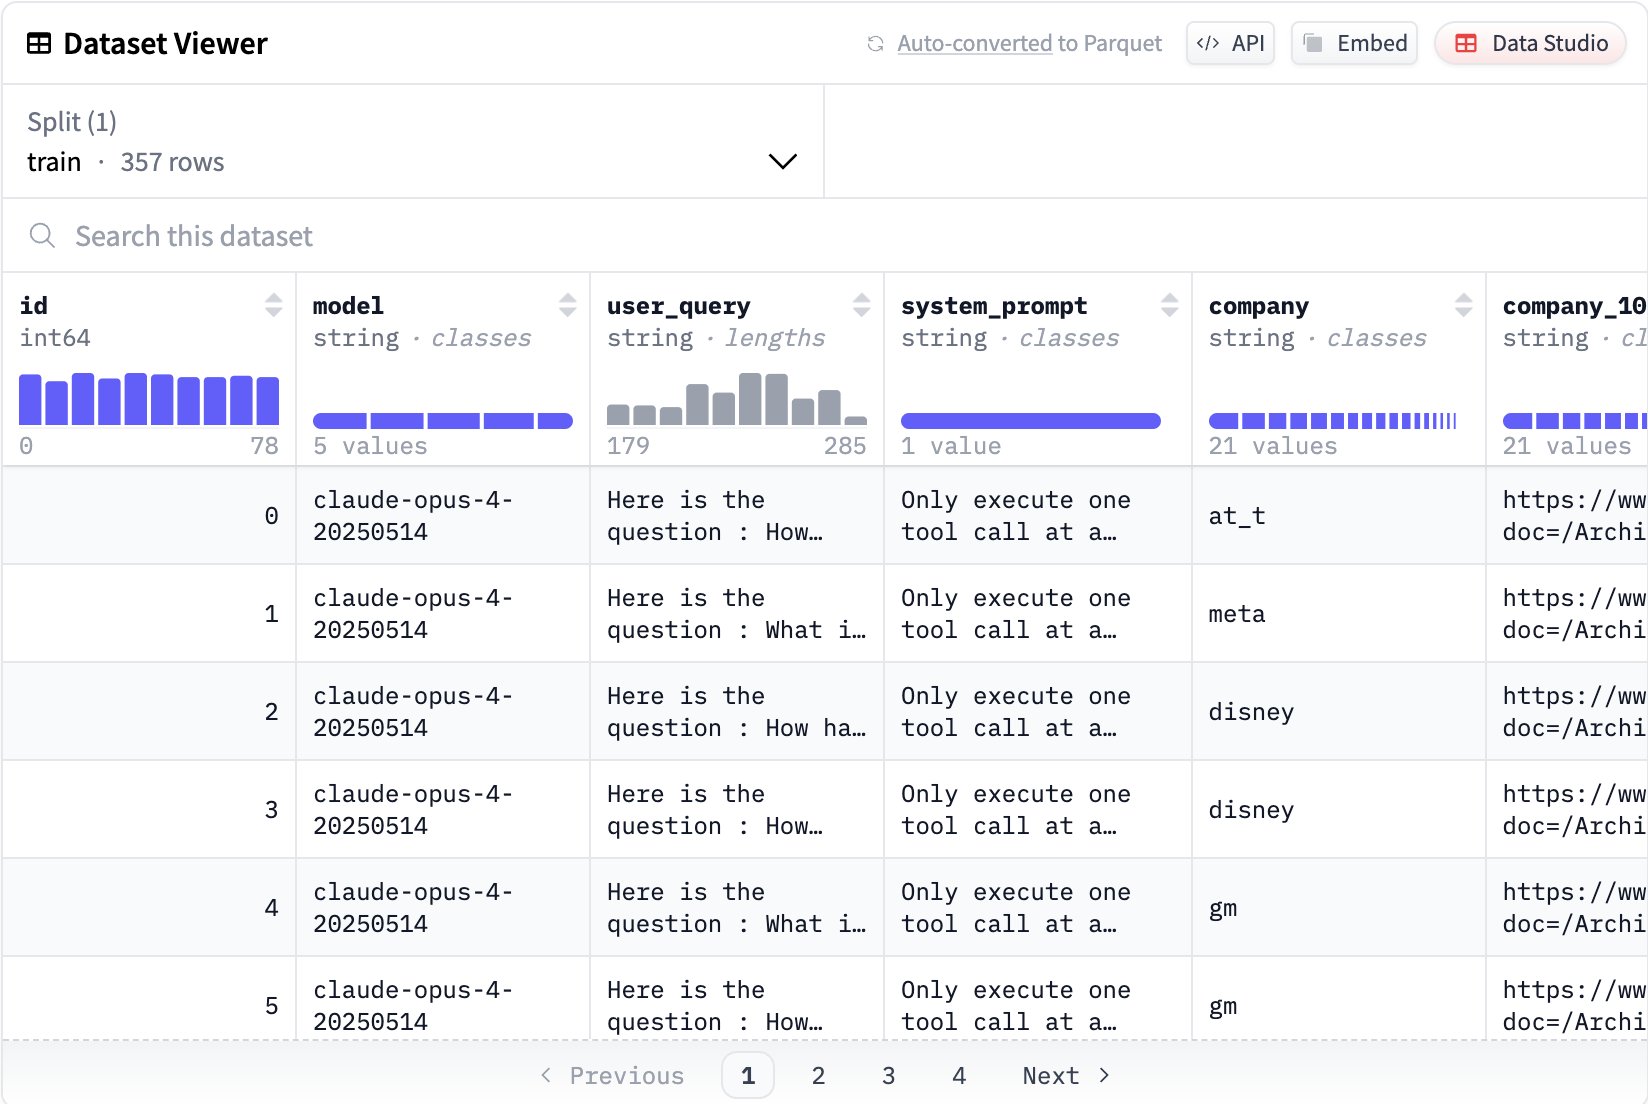
New: Multi-Turn Insurance Underwriting: our open-source, expert-reviewed benchmark for multi-step LLM evaluation. Multi-turn chats Tool use & reasoning LLM-judged accuracy On Hugging Face https://
huggingface.co/datasets/snork
elai/Multi-Turn-Insurance-Underwriting
… #LLMEvaluation #RAG #OpenSource -
Expert Data Drives Next-Gen AI Innovation and LLM Development
By
–
Curated, expert data is key for next-gen #AI. Co-founder Vincent Chen shares more in @vmblog
: https://
vmblog.com/archive/2025/0
7/16/celebrating-ai-appreciation-day-2025-technology-leaders-reflect-on-ai-s-revolutionary-year.aspx
… #SnorkelAI #LLM -
PhD-Level Benchmark Tests Advanced Reasoning in LLMs
By
–
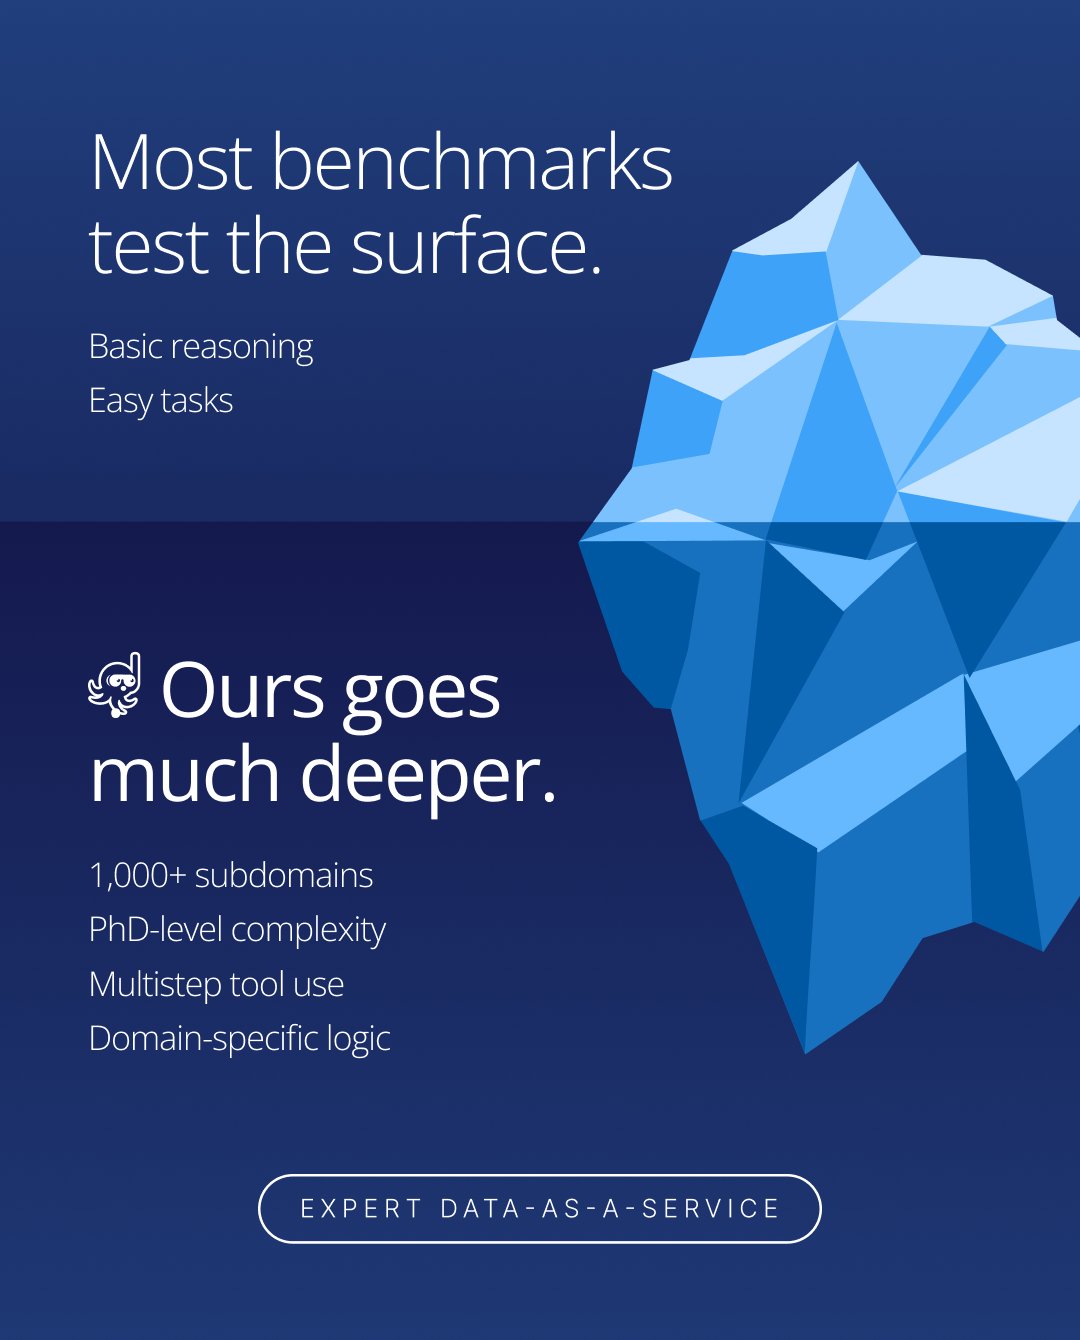
Not all benchmarks are created equal. We built a PhD-level multiple-choice test across 1,000+ subdomains, STEM, humanities, pro fields. Top LLMs? Scored <20%. This is what it takes to test advanced reasoning. Built with Snorkel’s Expert Data-as-a-Service. #LLM #GenAI
-
New Finance Reasoning Benchmark Reveals LLM Performance Gaps
By
–
Our new benchmark dropped this week and it’s already exposing where even top LLMs struggle. Top score: 51.9%. Test your agent (or just try a task) https://
huggingface.co/datasets/snork
elai/agent-finance-reasoning
… -
Grok 4 Tops SnorkelFinance Benchmark with 51.9% Score
By
–
You asked for finance + reasoning—so we built it. 📉
— Snorkel AI (@SnorkelAI) 16 juillet 2025
Grok 4 ranks top 5 on SnorkelFinance—Top score? Just 51.9%.
Full results coming soon. Built with Snorkel’s Expert DaaS.
🧪 Try it: https://t.co/UatfcKbWZ2
🔗 Benchmarks in comments. pic.twitter.com/gjyiUnydM1You asked for finance + reasoning—so we built it. Grok 4 ranks top 5 on SnorkelFinance—Top score? Just 51.9%. Full results coming soon. Built with Snorkel’s Expert DaaS. Try it: https://
lnkd.in/gn4yHeVG Benchmarks in comments. -

Rising to #13 on National Security 100 list for trusted AI
By
–
We’re #13 on this year’s #NatSec100, up from #43 in 2024.
— Snorkel AI (@SnorkelAI) 14 juillet 2025
Appreciate the nod. Grateful to build alongside so many working toward secure, trusted AI.
📘 https://t.co/O3hIS8o9io#GenAI #AI #NatSec pic.twitter.com/Ymq8OrVpweWe’re #13 on this year’s #NatSec100, up from #43 in 2024. Appreciate the nod. Grateful to build alongside so many working toward secure, trusted AI. https://
natsec100.org #GenAI #AI #NatSec -
Snorkel AI Hiring: Join Award-Winning AI Team
By
–
We’re hiring! Snorkel AI is honored to be recognized by @TheDataIQ
, @BIGAwards
, @theCUBE
, @Forbes
, @VentureBeat & The Cloud Awards for our 2025 wins. Join our award-winning team & help shape the future of AI! http://
snorkel.ai/join-us #AI #Jobs #Hiring