It's been a another wild month in AI & Deep Learning research. I curated and summarized noteworthy papers here: https://
magazine.sebastianraschka.com/p/ai-research-
highlights-in-3-sentences-2a1/
… Ranging from new optimizers for LLMs to new scaling laws for vision transformers.
@rasbt
-
AI Research Highlights: LLM Optimizers and Vision Transformer Scaling Laws
By
–
-
LLaMA’s Simplicity and Growing Ecosystem Appeal
By
–
I wouldn't mind it staying on the top for longer, haha. I do like the relative simplicity of LLaMA, and it's grown on me thanks to all the awesome projects built on top of it.
-
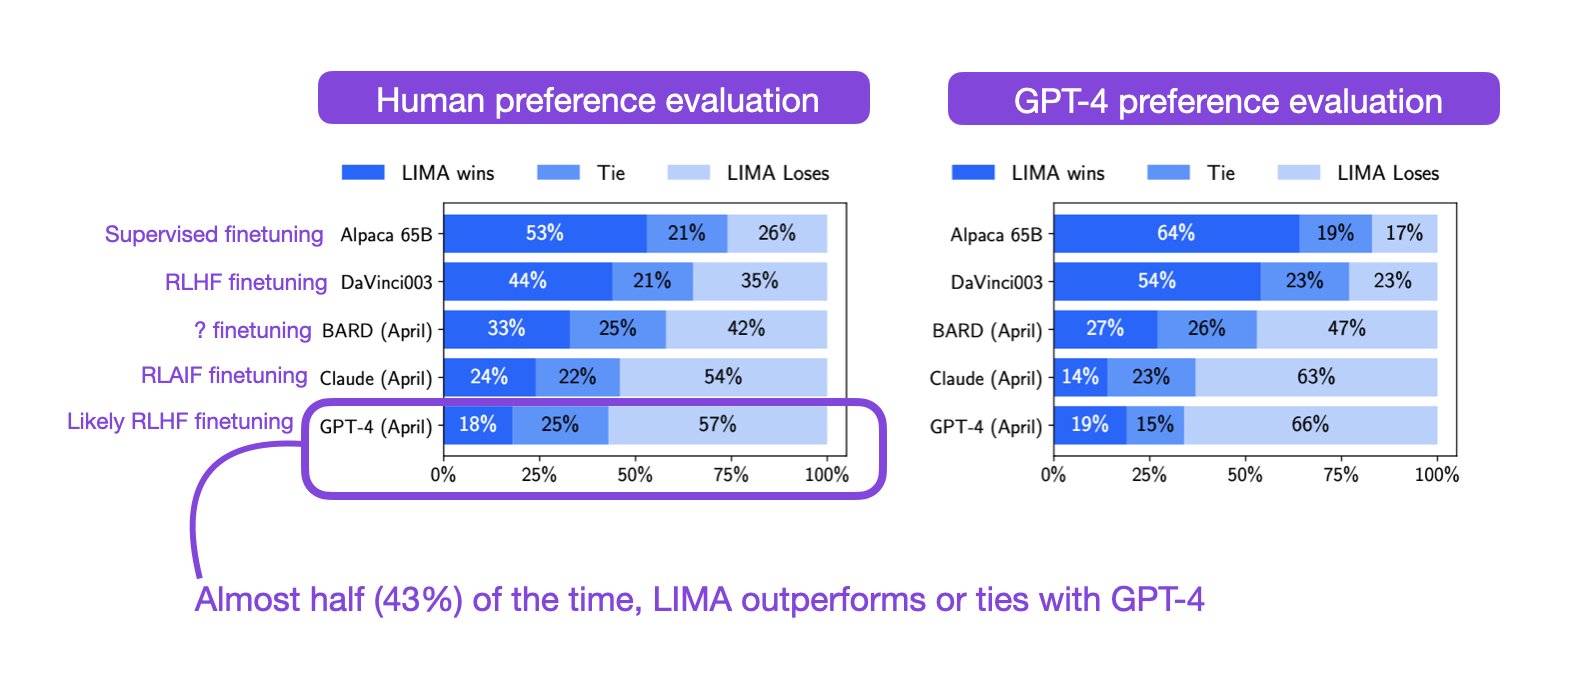
LIMA Dataset Now Available on Hugging Face
By
–
Just saw that the LIMA dataset is now available! https://
huggingface.co/datasets/GAIR/
lima
… -
LoRA Implementation in Lit-Parrot with Analysis Coming Soon
By
–
Just implemented LoRA (
https://
github.com/Lightning-AI/l
it-parrot/pull/128
…) and may be able to tell more soon. (Stay tuned for more info next week. Have to get all my analyses organized and write that up properly before mixing up some numbers there. Probably no qlora, but some info on LoRA at least) -
Full Fine-tuning Requires 8x A100s for 7B Models
By
–
Yup. Other interesting tidbit: to run full finetuning without Adapter on 7B requires at least 8x A100s for comparison.
-
Largest Model Currently Available and Future 120B Model Rumors
By
–
That would be 40B. As far as I know, that’s currently the largest one. A 120B one is in the works though according to rumors.
-
Single Epoch Training on 52k Alpaca Dataset
By
–
This was for one iteration/epoch over the 52k Alpaca dataset.
-
LLaMA-Adapter Works with Any LLM, Including Falcon 40B
By
–
Fun fact: LLaMA-Adapter is not LLaMA-specific. You can use it to finetune any LLM.
— Sebastian Raschka (@rasbt) 8 juin 2023
Below, I finetuned a 40B Falcon model using LLaMA-Adapter (it also works on a single GPU with 20 GB RAM).
Have been heads down tinkering & will follow up with more benchmarks! https://t.co/2Fr6faChv2Fun fact: LLaMA-Adapter is not LLaMA-specific. You can use it to finetune any LLM. Below, I finetuned a 40B Falcon model using LLaMA-Adapter (it also works on a single GPU with 20 GB RAM). Have been heads down tinkering & will follow up with more benchmarks!
-
Video-LLaMA Paper Lacks Quantitative Evaluation Metrics
By
–
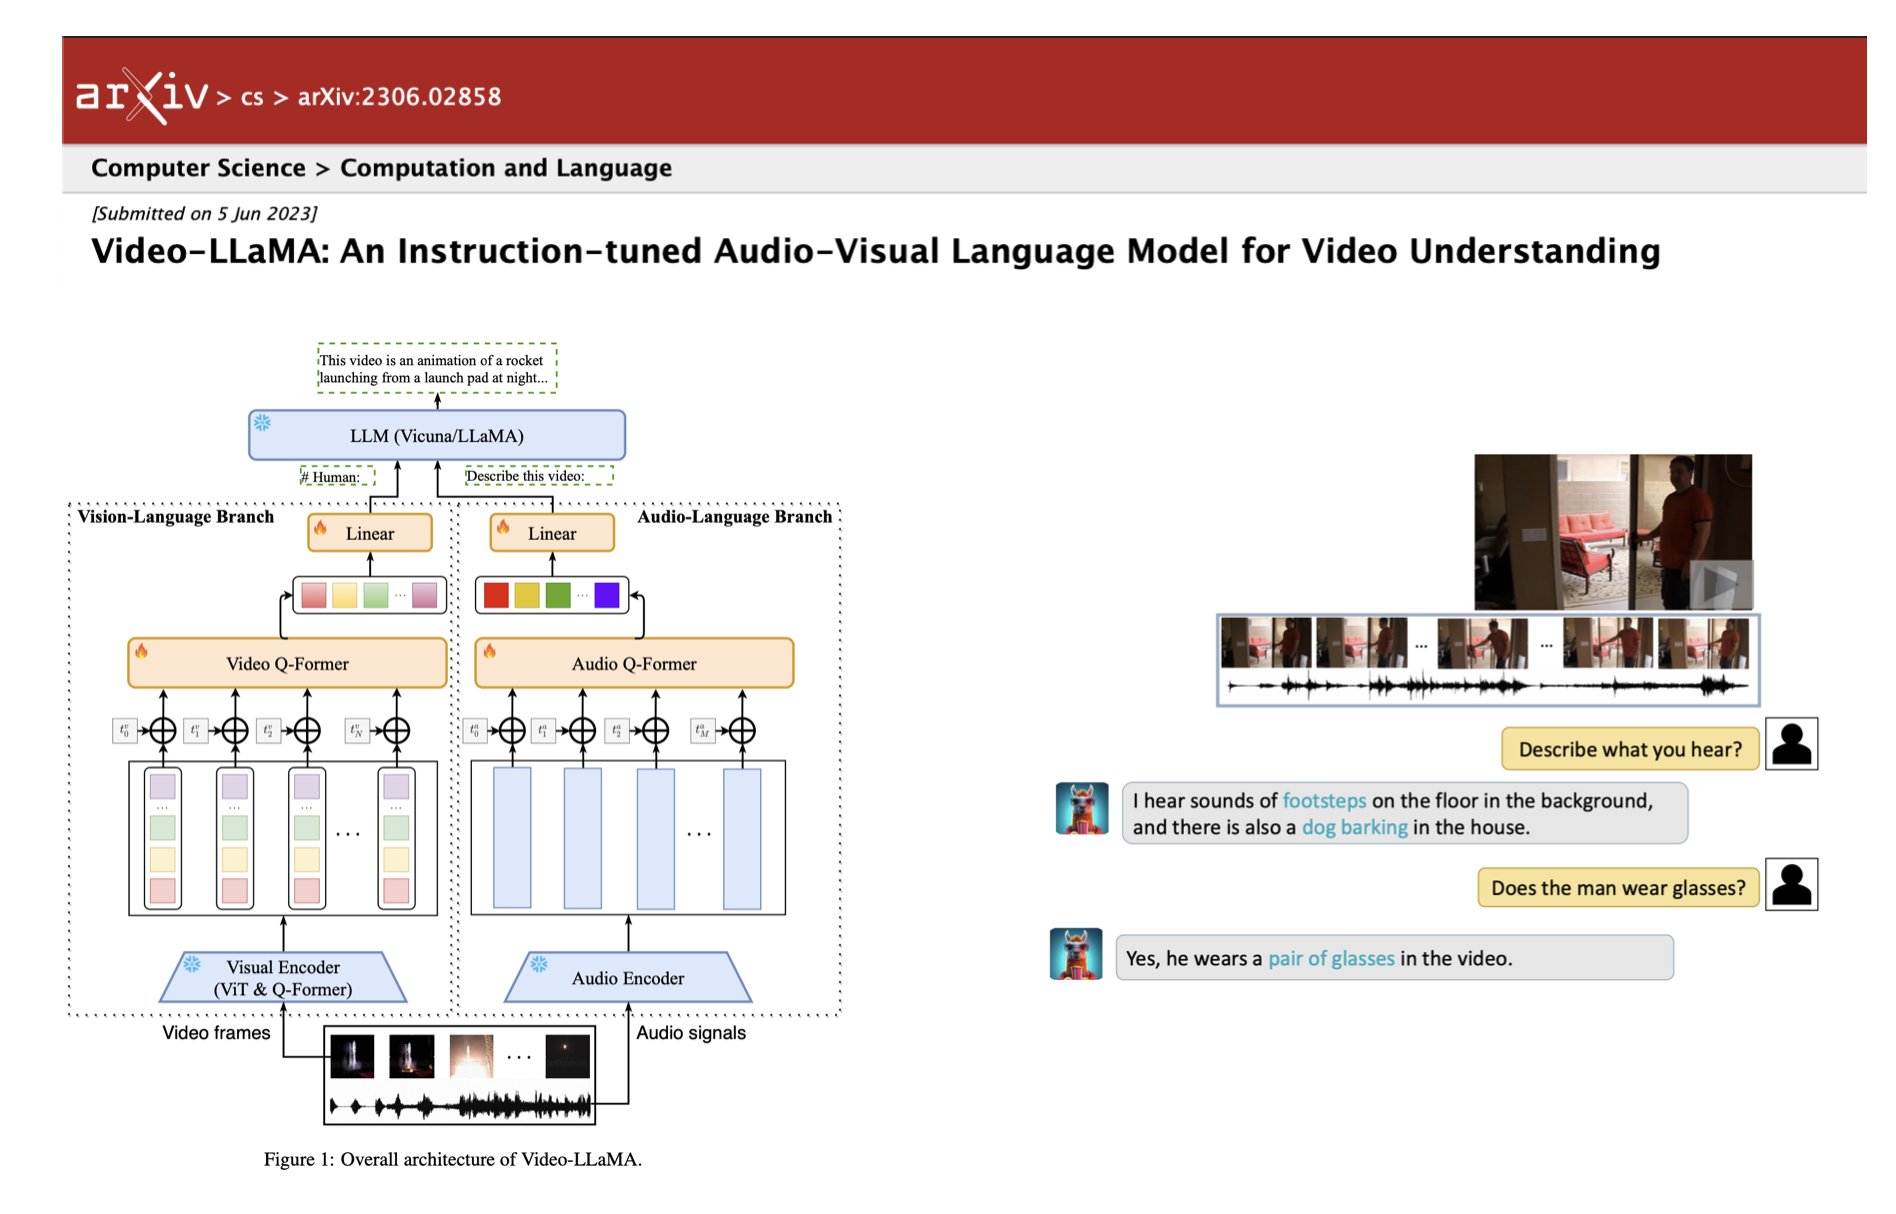
"Video-LLaMA: An Instruction-tuned Audio-Visual Language Model for Understanding". This method is pretty cool, but what is this new trend where papers don't contain any type of quantitative model evaluation? Looks like researchers are in a rush. https://
arxiv.org/abs/2306.02858 -
Withholding Code While Publishing Implementation Details in Papers
By
–
Similar to "We don't share the code but the details are described in the paper for those who want to implement and use it"