Just added LoRA the other day (PR still in progress: https://
github.com/Lightning-AI/l
it-parrot/pull/128#pullrequestreview-1477273133
…) and will do some comparisons soon!
@rasbt
-
LoRA Implementation Added to Lit-Parrot Project
By
–
-
LLaMA-Adapter: Efficient LLM Fine-tuning with Tunable Prefixes
By
–
I really like the LLaMA-Adapter method! In a nutshell, it's about finetuning LLMs more efficiently. In a nutshell, it's adding a tunable prefix to the key and value tensors in the self-attention layers. Fun fact: it's not specific to LLaMA. Use it with any LLM!
-
FNet performance limitations compared to attention-based architectures
By
–
Yeah, for some applications it may be sufficient. But FNet doesn't outperform a contemporary attention-based architecture though
-
Humorous commitment to converting someone to PyTorch
By
–
maybe not this year, but I'll convert you to PyTorch eventually haha
-
Pretrained Models Make Fine-tuning the Only Practical Approach
By
–
Hah, and even further, with pretrained models available, anything more than finetuning feels like a pain
-
Schmidhuber’s 1991 Alternative to RNNs: The Origins of Linear Transformers
By
–
Hah, yeah, little known fun fact: Schmidhuber proposed an alternative to RNNs back in 1991, which is now called "linear Transformers" or "Transformers with linearized self-attention" via more recent papers. Summarized it here: https://
magazine.sebastianraschka.com/p/why-the-orig
inal-transformer-figure
… -
Transformer’s Birthday: Attention Mechanisms and RNN Evolution
By
–
Happy birthday, transformer! An awesome summary @DrJimFan
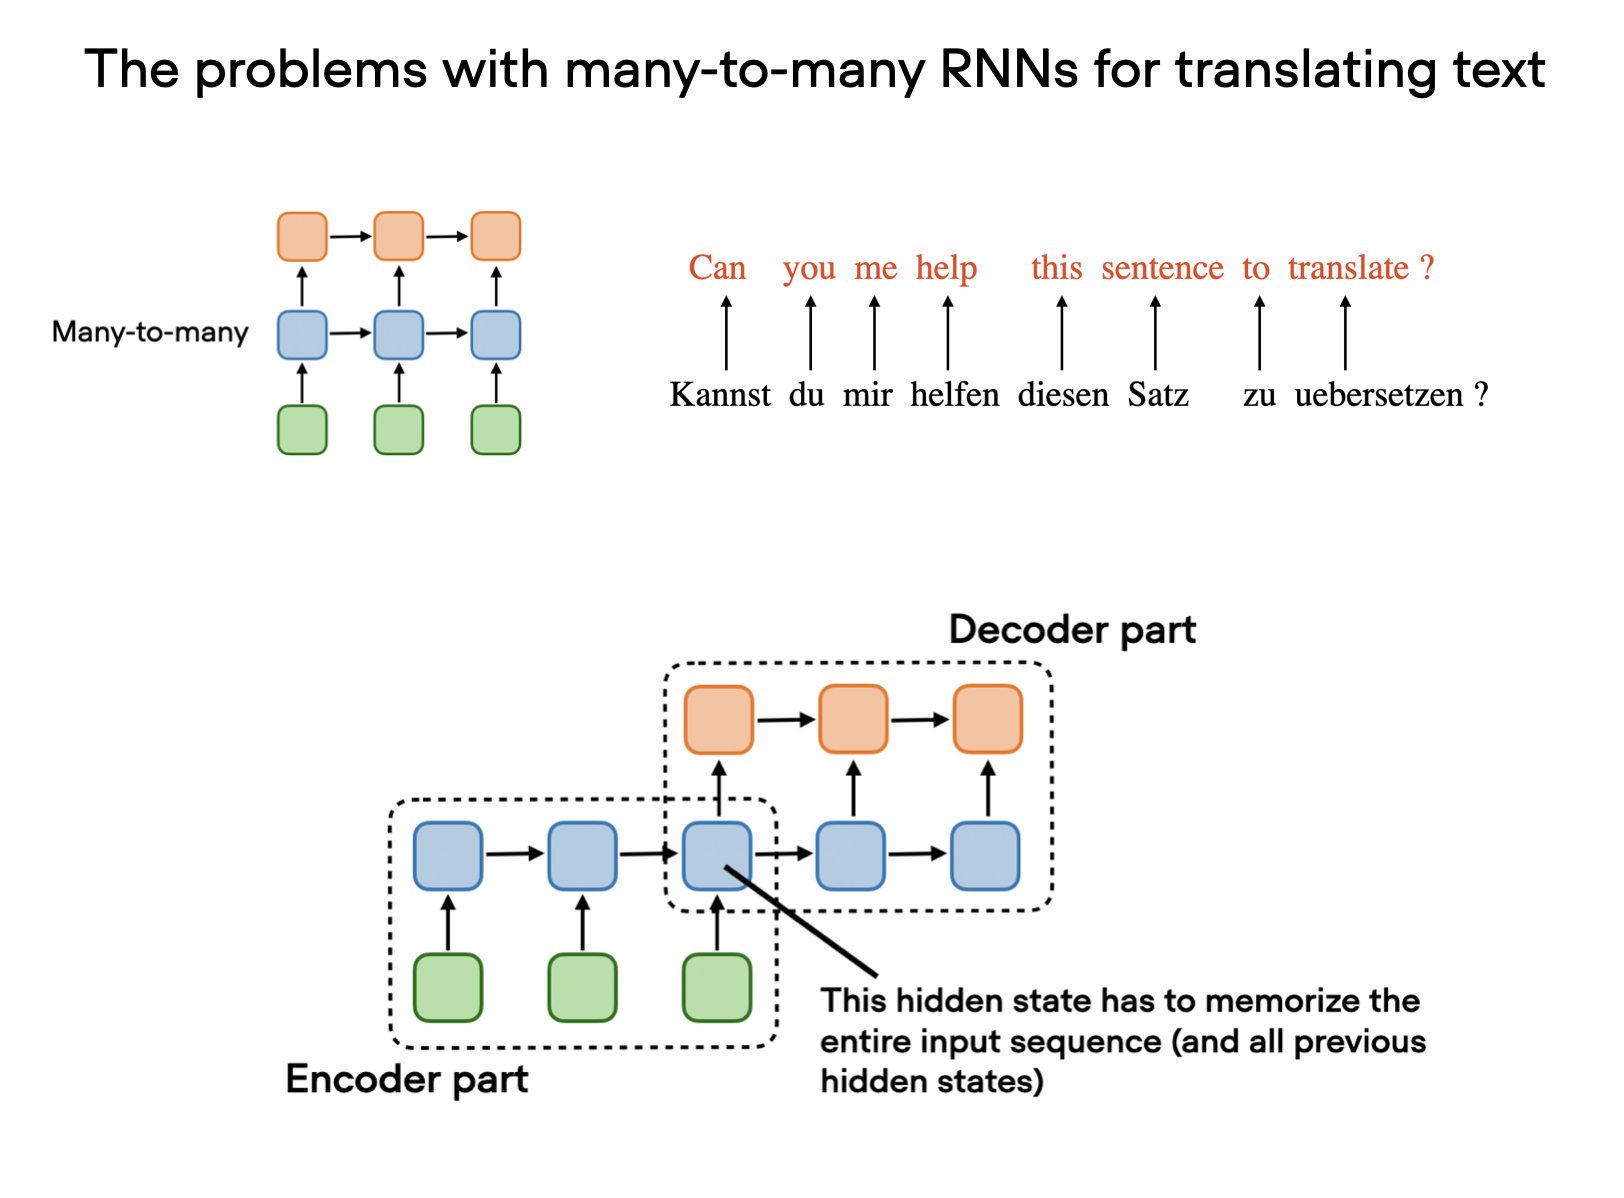
! Also interesting to think about why we needed attention for RNNs (before transformers) in the first place. Since we can't translate word-by-word, we needed a RNN encoder-decoder setup. But then, it's hard to remember. -
Attention Mechanism Origins Traced Back to 1991 Schmidhuber
By
–
Oh, and sorry, @DrJimFan
, even the 2014 paper is not the original attention paper. It goes actually back to 1991 (via @SchmidhuberAI
) in https://
semanticscholar.org/paper/Learning
-to-Control-Fast-Weight-Memories-An-to-Schmidhuber/bc22e87a26d020215afe91c751e5bdaddd8e4922
… I've summarized it here: https://
magazine.sebastianraschka.com/p/why-the-orig
inal-transformer-figure
… -
Deep Learning Lecture: From RNNs to Transformer Architecture
By
–
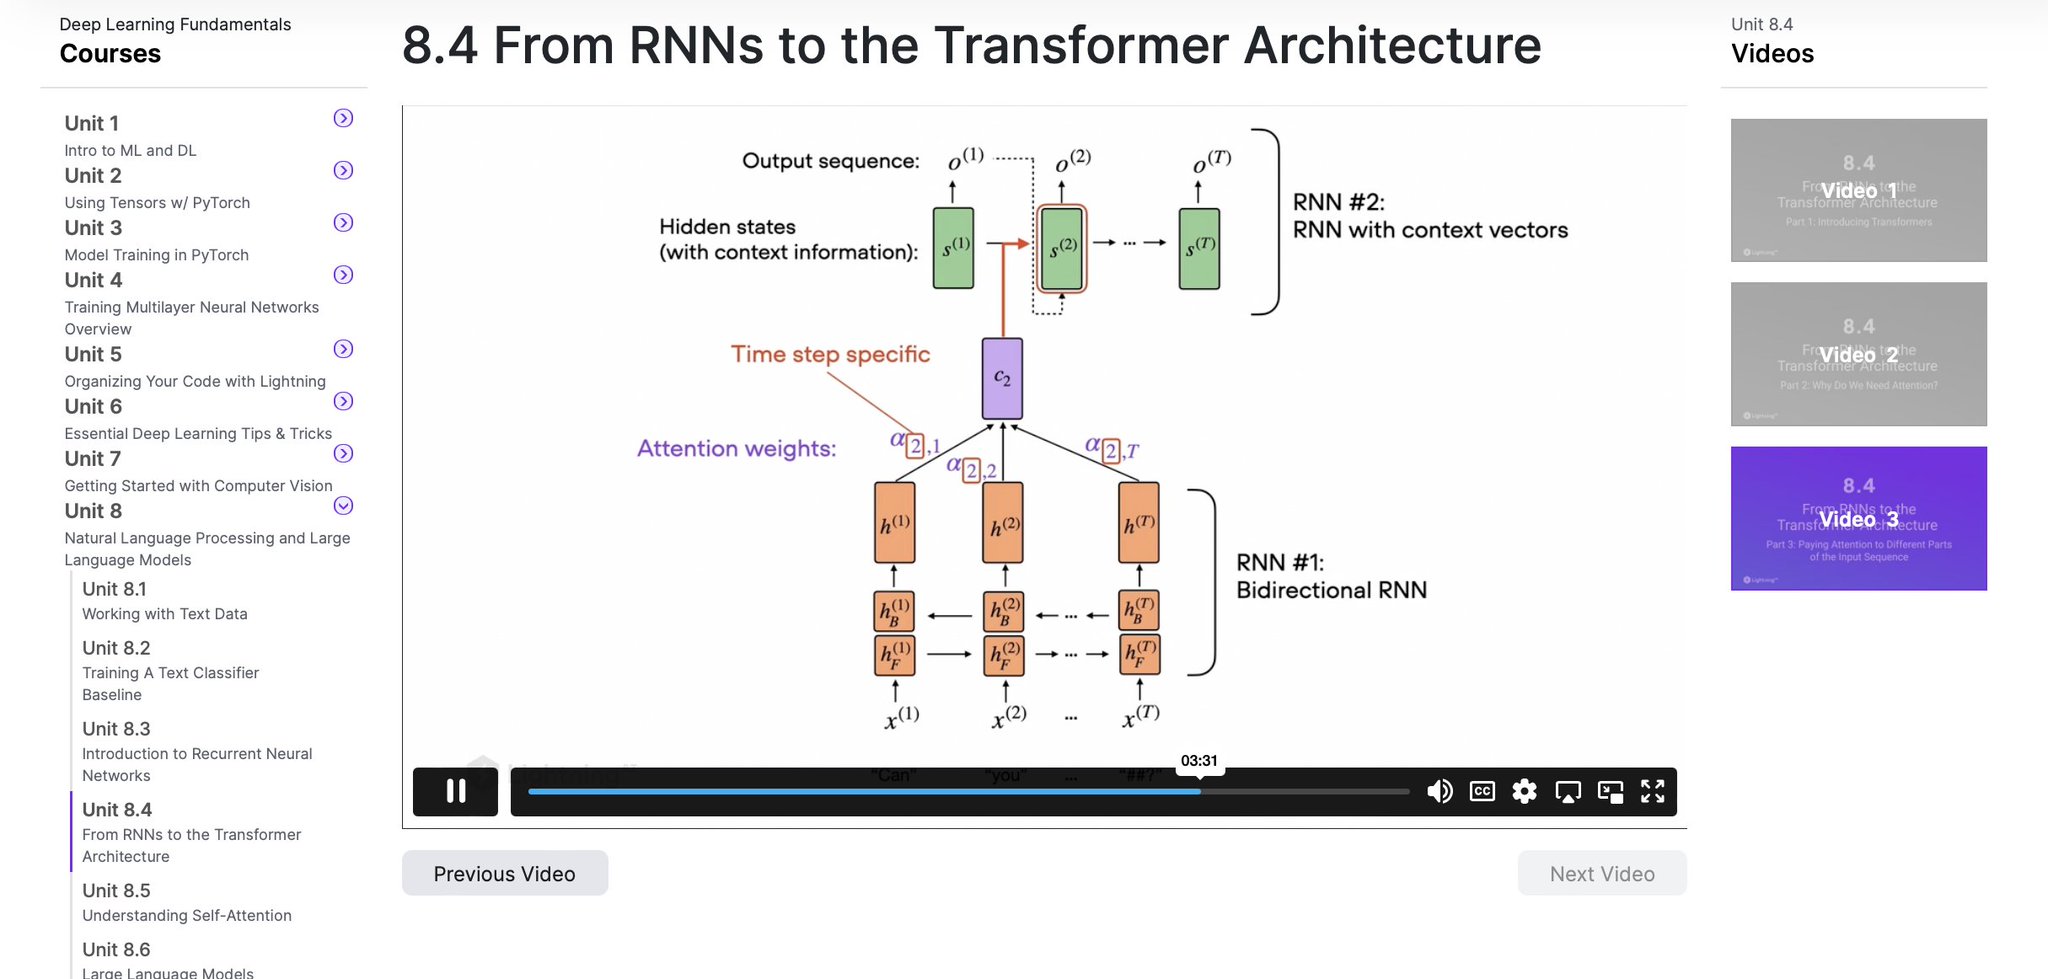
Link to the lecture in case someone's curious: https://
lightning.ai/pages/courses/
deep-learning-fundamentals/unit-8.0-natural-language-processing-and-large-language-models/8.4-from-rnns-to-the-transformer-architecture/
… -
Bahdanau Attention as Essential Foundation for Transformer Learning
By
–
Yup! I always start my book chapters, lectures, etc with Bahdanau attention paper. I think it's a great intro & motivation for developing transformers. Without it, it would feel like sth is missing.