I don’t think there’s a restriction wrt to multimodal LLMs though (eg using techniques like LLaMA-Adapter v2). But yeah, the evaluation datasets won’t include images.
@rasbt
-
Positional Encoding and Attention Mechanisms in Neural Networks
By
–
Hm good point and not sure. The positional encoding might not be required (there was a paper on that recently referred to as NoPE). Attention mechanisms I’d say are a generalization of MLPs (they could learn uniform weights if that’s useful). So I’d tend to say no.
-
Transformer publication timeline close to Bahdanau attention
By
–
Ah no! Interesting, I didn’t know it was published only 1 month after Bahdanau attention for RNNs
-
Self-Attention Mechanisms in Transformers: From RNNs to LLMs
By
–
What motivated self-attention mechanisms in transformer-based LLMs in the first place?
— Sebastian Raschka (@rasbt) 21 août 2023
A made a short video covering
– the limitations of RNNs
– the original (Bahdanau) attention mechanism for RNNs,
– how it all led to the original Transformer architecture used in LLMs https://t.co/oMLNlJMef6What motivated self-attention mechanisms in transformer-based LLMs in the first place? A made a short video covering
– the limitations of RNNs
– the original (Bahdanau) attention mechanism for RNNs, – how it all led to the original Transformer architecture used in LLMs -
Mixed-Precision Training: Easy to Enable, High Impact Results
By
–
Awesome, glad to hear that helped. What’s nice is that mixed-precision training it’s so easy to enable but can have a huge impact in practice 🙂
-
Token input limit discussion for model evaluation
By
–
There is a limit on 2048 token inputs for evaluation, is that what you mean?
-
Clarification about 1D convolutional networks misunderstanding
By
–
Yeah. 1D made me think of 1D convolutional networks on pixels arrays hence my weird question. But yeah pls ignore what I said 😛
-
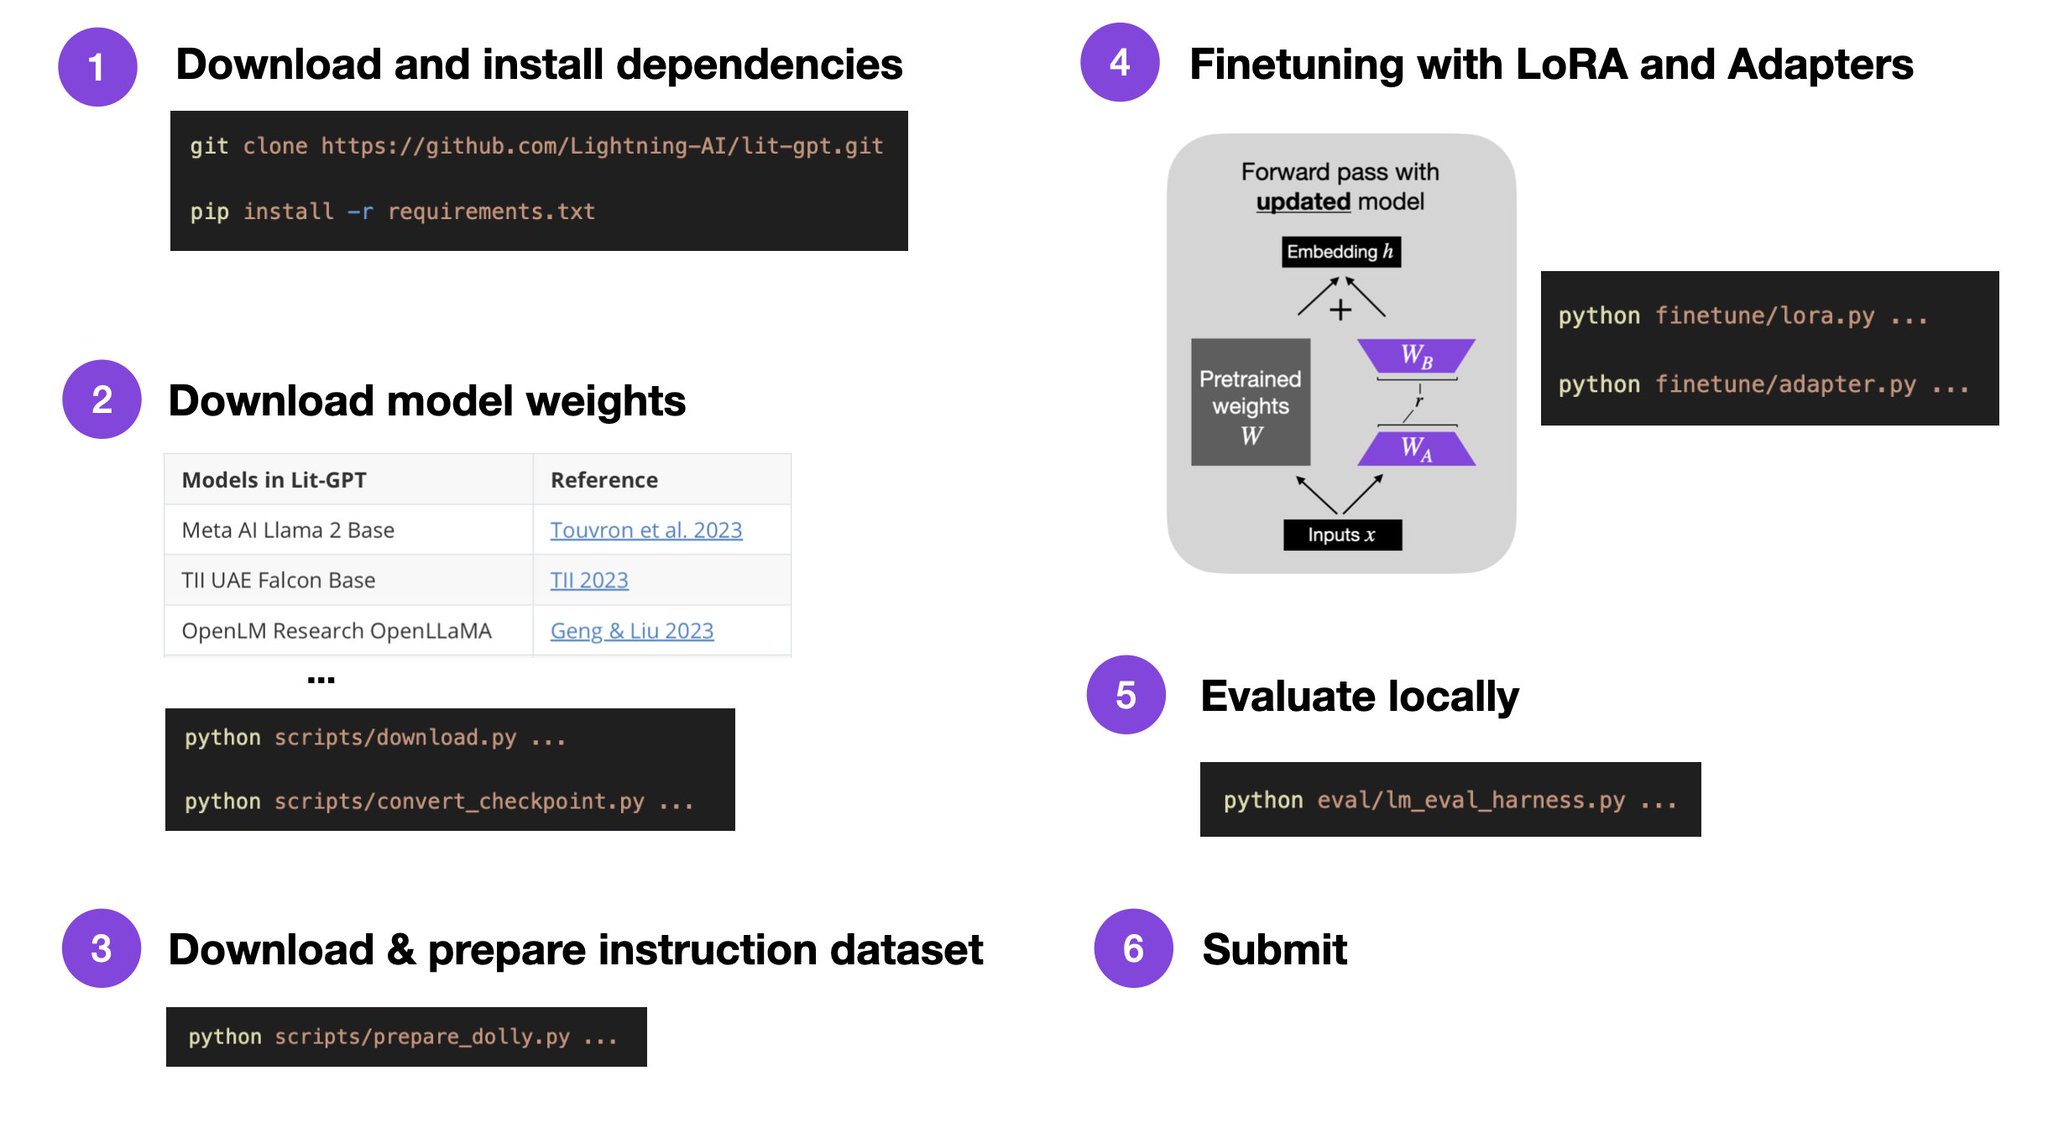
NeurIPS 2023 LLM Efficiency Challenge Quickstart Guide
By
–
Interested in the NeurIPS 2023 LLM Efficiency Challenge or just training your custom LLM on 1 GPU? Wrote a new quickstart guide to get started in ~5 min: https://
github.com/Lightning-AI/l
it-gpt/blob/main/tutorials/neurips_challenge_quickstart.md
… If there's interest, also happy to write an article w. research directions to explore. Let me know! -
UMAP faster than t-SNE despite being slower than PCA
By
–
Saying UMAP is slower than PCA is "the glass is half-empty" view haha.
The more positive take is: UMAP is much faster than T-SNE!