Lit-GPT 🙂 https://
github.com/Lightning-AI/l
it-gpt
…
@rasbt
-
Lit-GPT: Lightning AI’s New GitHub Repository Launch
By
–
-
Scaling Llama 2 to GPT-3 Size for Performance Comparison
By
–
Someone needs to scale up Llama 2 to GPT 3 size. Would be curious how that compares then.
-
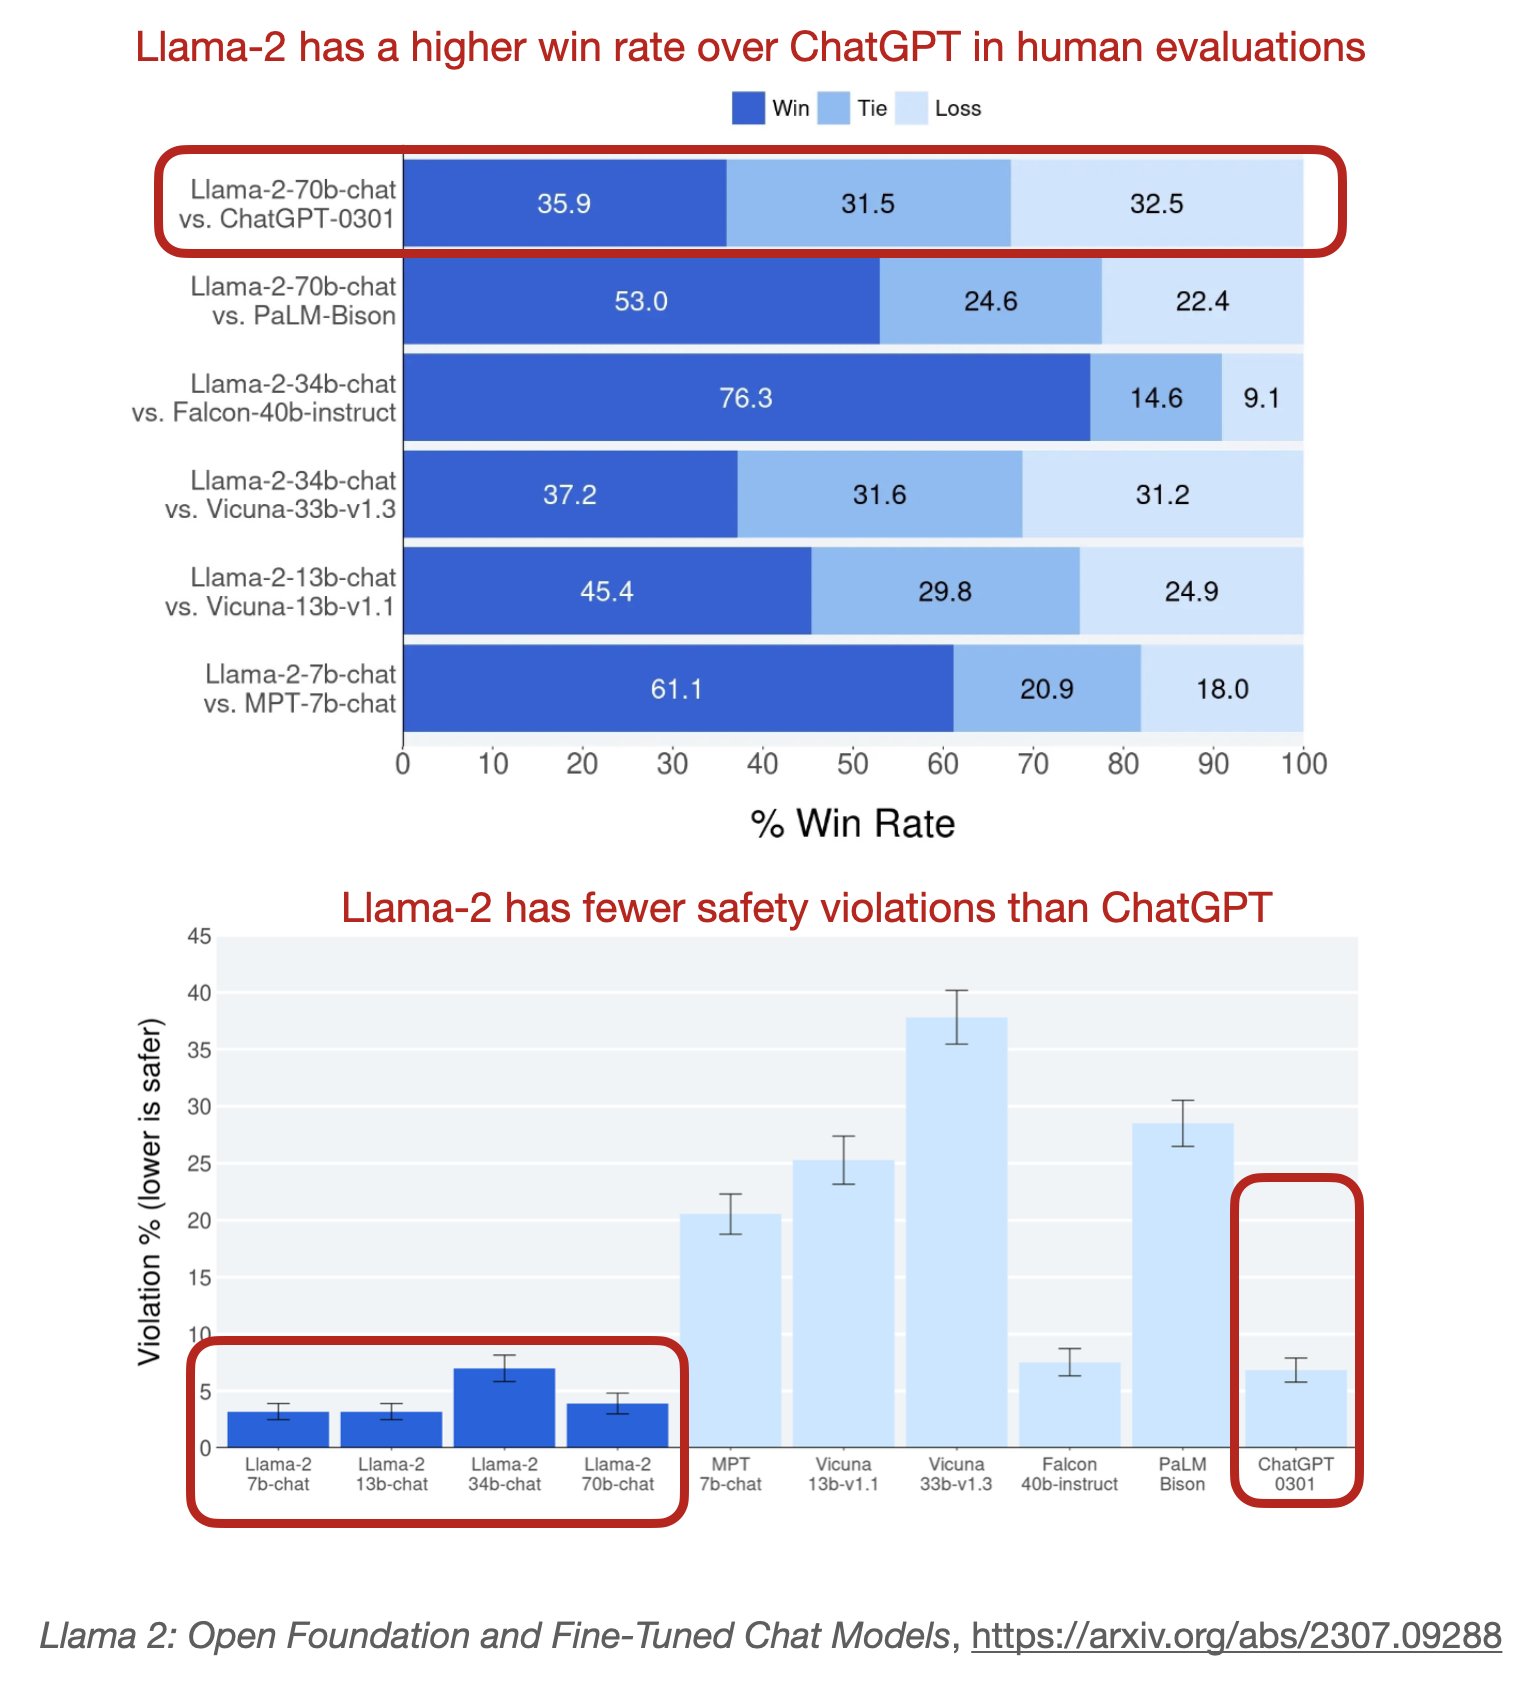
LoRA Services vs Open-Source: Llama 2 Competitive Comparison
By
–
Will be interesting how this LoRA-on-demand service will compare to open-source LoRA on prem. Here's a little reminder that open-source Llama 2 compares very favorably to ChatGPT / GPT 3.5
-
ML Evaluation Metrics and Lit-GPT Evaluation Framework
By
–
I have a write-up explaining BLEU, ROUGE, and BERTScore in Chapter 19 of my ML Q and AI book: https://
leanpub.com/machine-learni
ng-q-and-ai/
… Other than that, Lit-GPT has currently the Eleuther AI Evaluation Harness implemented: https://
github.com/Lightning-AI/l
it-gpt/blob/main/tutorials/evaluation.md
… -
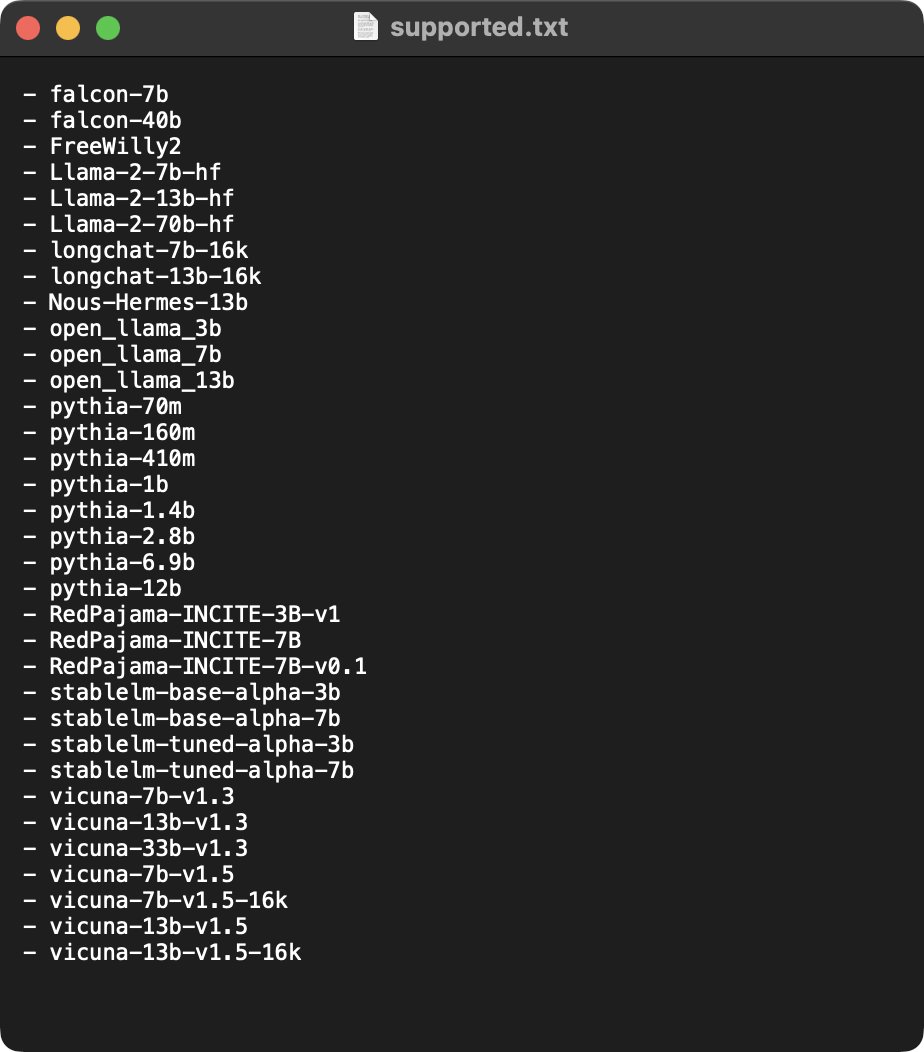
Supported Models Toggle via Checkpoint Directory Flag
By
–
Sure, the same code works for all supported models. You can toggle these via the –checkpoint_dir flag pointing to the directory where you downloaded the model. Here's a list of the currently supported models:
-
Finetuning Llama 2 7B with Only 13 GB RAM on Single GPU
By
–
I forgot to mention the probably most important thing: Finetuning Llama 2 7B this way – only requires 13 GB RAM – and can thus comfortably run on a single GPU
-
LoRA Quantization and Evaluation Scripts for Llama-2 Models
By
–
Qualitatively, you can use python generate/lora.py –lora_path '… .pth' –quantize "bnb.nf4" –precision "bf16-true" –checkpoint_dir "…/Llama-2-7b-hf" Quantitatively, you can use the python eval/eval_harness scripts: https://
github.com/Lightning-AI/l
it-gpt/tree/main/eval
… -
QLoRA Single-GPU Limitations and Multi-GPU Future Plans
By
–
QLoRA right now it's single-GPU. I left multi-GPU support as a future todo since I am currently mostly focused on the NeurIPS LLM challenge. But it might well be working with multi-GPU settings already; it's just that I haven't tested. Could be that it requires switching from
-
Optional FlashAttention 2 Installation Feature
By
–
Yes, it's an optional feature. It uses FlashAttention by default, but you can optionally use FlashAttention 2 via pip install 'flash-attn>=2.0.0.post1' –no-build-isolation
-

QLoRA Support Added to Lit-GPT for All LLM Models
By
–
Just added QLoRA support for all LLMs in Lit-GPT: Llama 2, Falcon, Pythia, StableLM, and all others! You can use it via `python finetune/lora.py –quantize "bnb.nf4"` to save significant GPU memory. I've ran a few more benchmarks on the Gh PR here: https://
github.com/Lightning-AI/l
it-gpt/pull/275
…