Wouldn’t that be only a problem the other way around, going from float16 -> bfloat16?
Since float16 supports more digits after the decimal points, going bfloat16 -> float16 there shouldn’t be no rounding?
@rasbt
-
Float16 vs Bfloat16 Conversion Rounding Issues
By
–
-
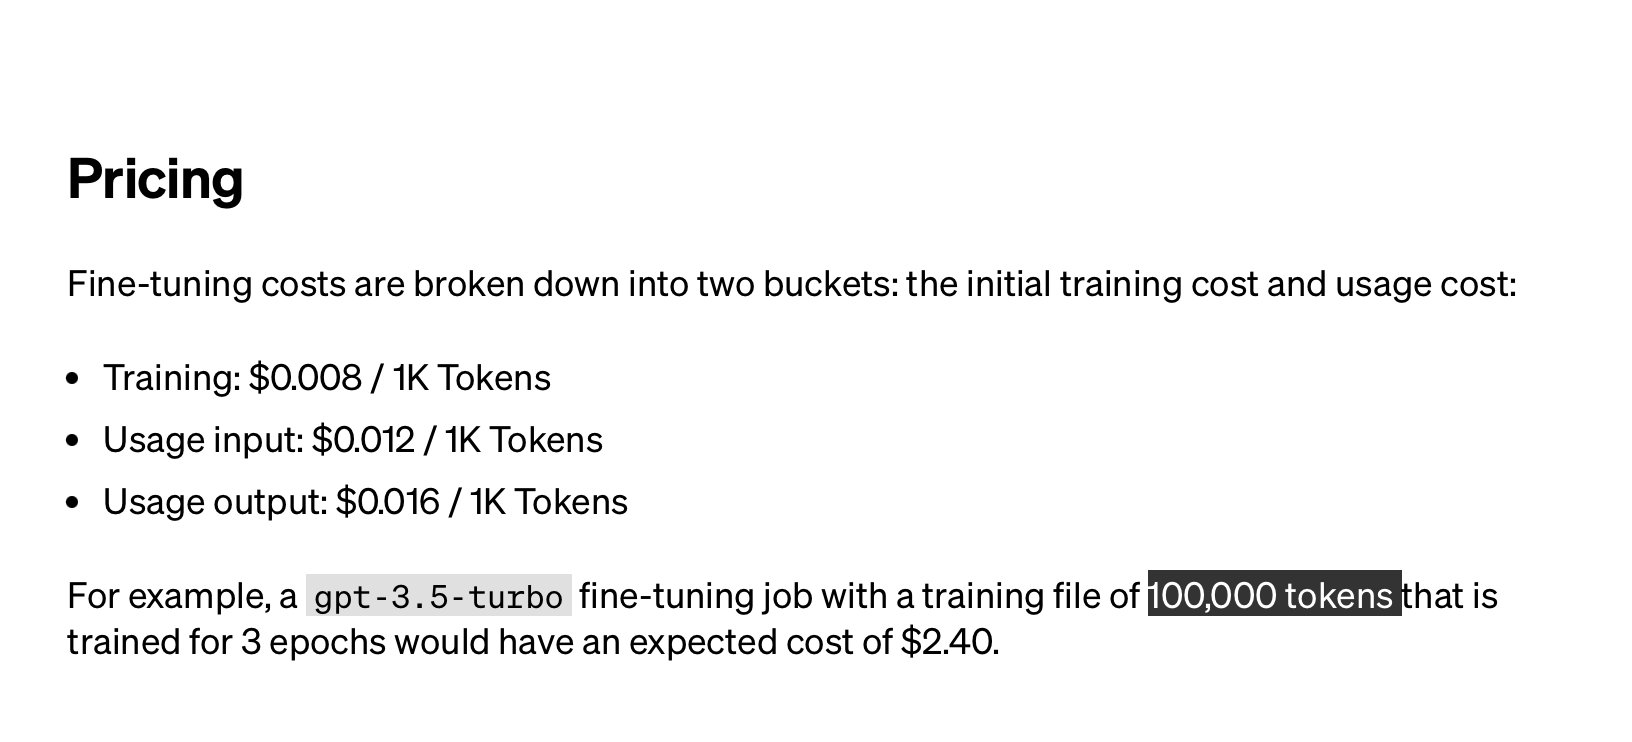
Skepticism about few-shot learning effectiveness and token costs
By
–
5-50 examples, I am skeptical that this can even produce good results. Hm, on their website they include a cost example with 100,000 tokens, so this must surely be more than 5-50 examples?
-
Hardware Dependencies and Limitations for Metal Support
By
–
Interesting, thanks for sharing. This sounds pretty cool actually. But afaik certain features are also hardware dependent, like bfloat16, so I am not sure if Metal or macOS can address that. Would probably require new chips as well.
-
llama.cpp inference and gptq quantization techniques exploration
By
–
Oh, reading a bit more about llama.cpp (
https://
github.com/ggerganov/llam
a.cpp
…), that's only inference, not training? I haven't tried since I don't have the model checkpoints on my laptop, but you may be able to use gptq.int4 quantization then: https://
github.com/Lightning-AI/l
it-gpt/blob/main/tutorials/quantize.md
… -
QLoRA 4-bit NormalFloat format supported only on Nvidia GPUs
By
–
Ah sorry, I meant M1/M2 chips (not specifically M1/2 CPUs). As far as I know, the 4-bit NormalFloat format that is used in QLoRA is currently only supported on Nvidia GPUs (
https://
github.com/TimDettmers/bi
tsandbytes/issues/485
…). Maybe the repo you mentioned uses a different type of quantized training. -
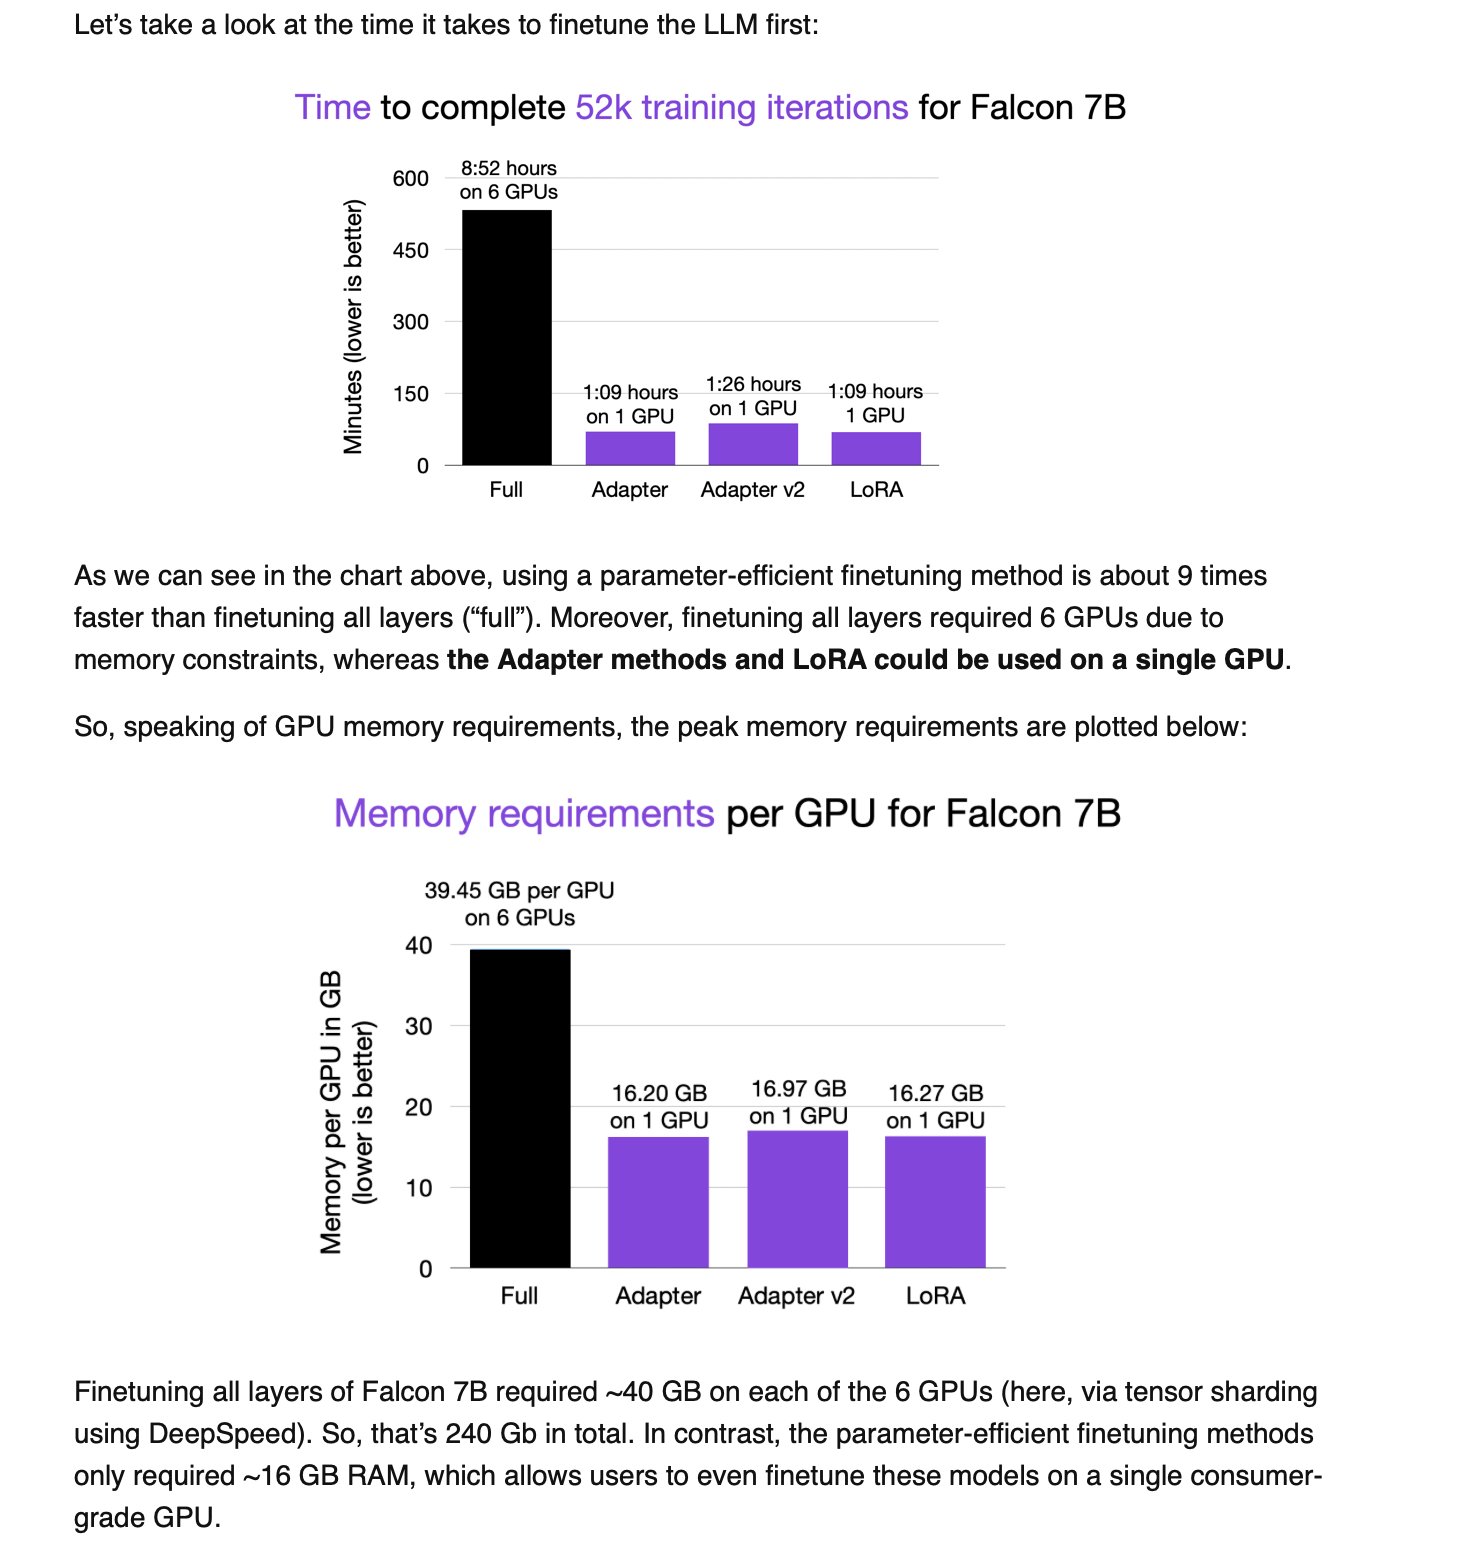
LoRA Compared to Llama-Adapter and Llama-Adapter v2
By
–
LoRA is a parameter-efficient finetuning technique, yes. I recently compared to Llama-Adapter and Llama-Adapter v2:
-
Alternative Precision Flag for Non-GPU Machines
By
–
I haven't tried on non-GPU machines, but maybe the following works:
"–precision 16-true" instead of "–precision bf16-true" -
BFloat16 Support in Ampere GPUs and M1 Chips
By
–
BFloat16 is a format introduced in Ampere architectures (Nvidia A100 cards) or newer. M1 chips for some reason have also bfloat16 in PyTorch, but I think this MPS bfloat16 is something very different.
-
BFloat16 Weight Clipping Limits and Extreme Value Representation
By
–
Hm, so that means all weights above values 65504 and below -65504 will be clipped. Does anyone know of there are numbers that large/small in the original bfloat16 representation?
-
LoRA as Cost-Effective Solution for Multi-Customer LLM Deployment
By
–
I believe this would be easiest and most cost-effective because they won't have to store a new 175B parameter LLM for each customer then. With LoRA, you can use the same base LLM but only need to store the LoRA weights.