I mean why not? It worked pretty well in DeepSeek V3.2
@rasbt
-
Question about sliding window attention implementation
By
–
Hmm I don’t think they use sliding window attn ? Where did you see that?
-
Expert Size and Number Match DeepSeek V3 Specifications
By
–
Probably also should have added that
– the expert size (2048) and number (256) is now exactly the same as in DeepSeek V3 / V3.2. -

GLM-5 Architecture: Weights Released, Key Features Unveiled
By
–
The weights are out! Here's the GLM-5 architecture comparison. GLM-5 is: – bigger than its predecessor (mainly more experts) but has rel. similar active parameter counts – uses multi-head latent attention – uses DeepSeek Sparse Attention
-
Anticipating Performance Improvements Over GLM-4.7 Predecessor
By
–
The upcoming days will tell once the reports are released. But I am assuming it's going to be better than their GLM-4.7 predecessor, which was Claude Sonnet 4.5-level
-
Clarification: GLM-5 is the new version, not 4.5
By
–
I think you misread: It's GLM-5 that is new, not 4.5.
-

Qwen3-Next-Coder: Local Model for Agentic Coding Tasks
By
–
Agreed! But in the meantime, there was also Qwen3-Next-Coder, which is even more attractive as a local model for agentic coding tasks:
-
Post-Training as Key Differentiator in Modern AI Development
By
–
Good question. I would say the post-training is usually one of the biggest distinguishing contributors these days
-
DeepSeek V3.2 and Arcee Trinity Release Timeline Updates
By
–
It's been two whole months since DeepSeek V3.2 and two whole weeks since Arcee Trinity!
-
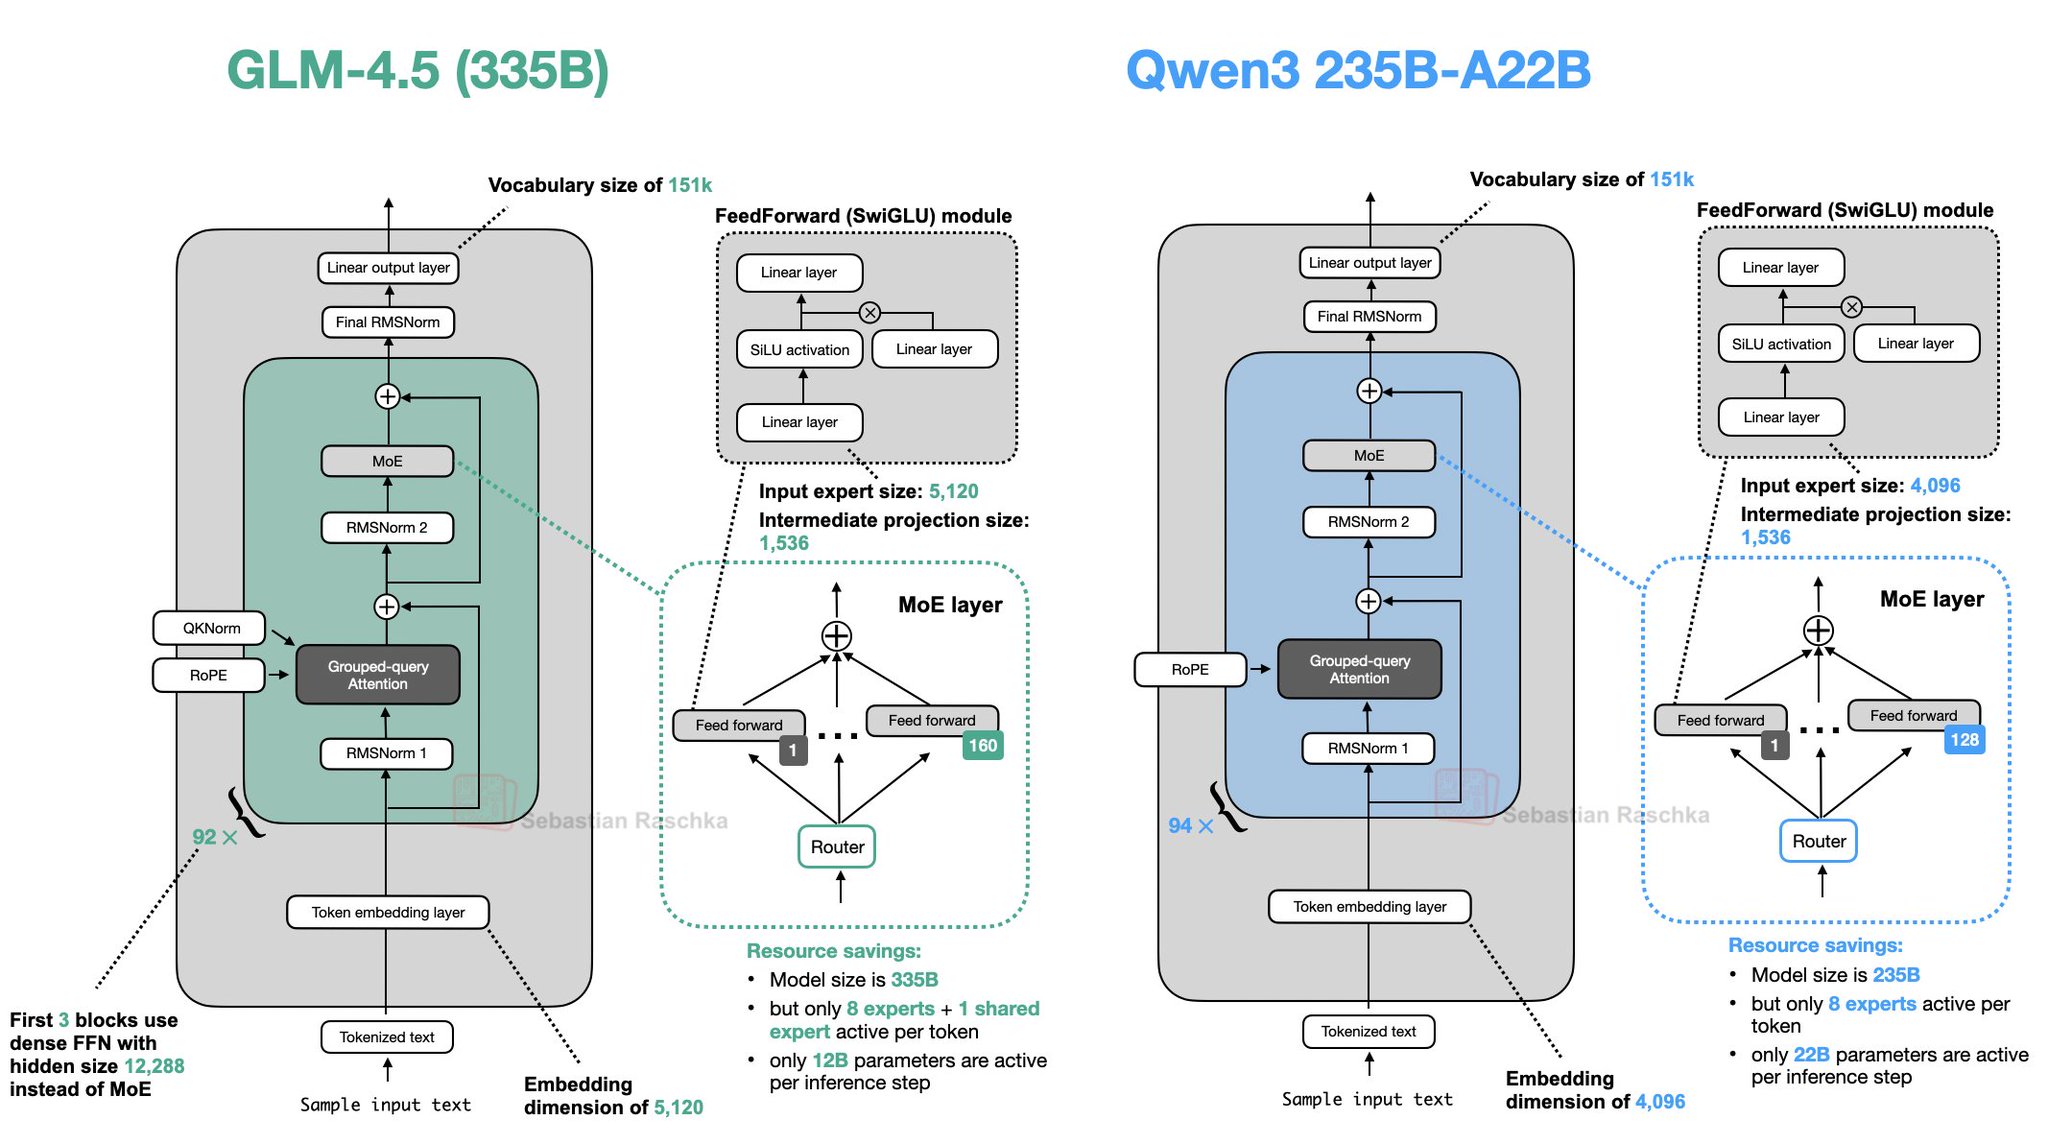
GLM-4.5: Notable benchmark performance between o3 and Claude
By
–
I think 4.5 was the first really notable one. Benchmark-wise it sat between between OpenAI o3 and Claude 4 Opus.
I have a brief section about it in my Big LLM Architecture Comparison article: https://
magazine.sebastianraschka.com/i/168650848/11
-glm-45
…