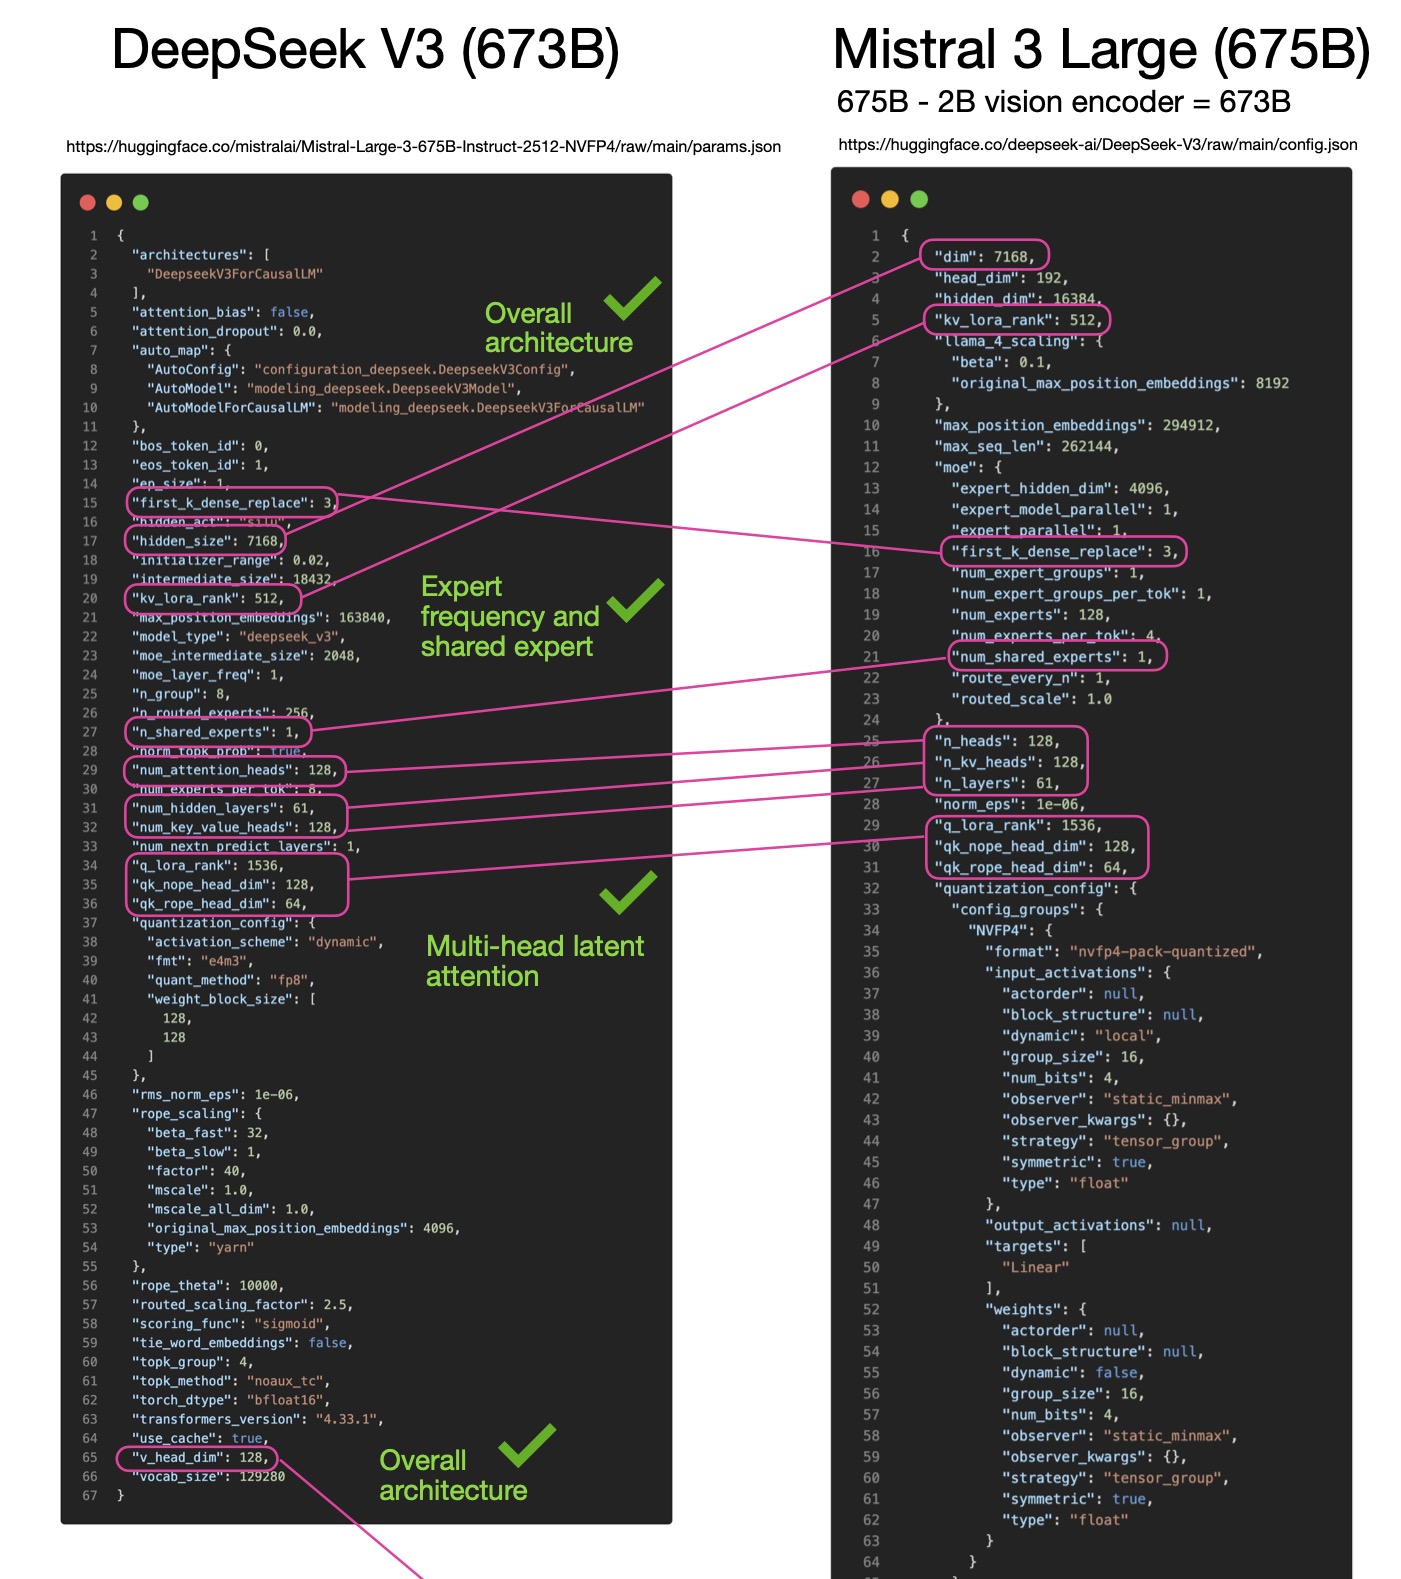
Qwen3.5 is ranked at an impressive 7th place on pinchbench atm. It's really impressive for such a relatively small open-weight model.
I think that's a perfect use case for local LLMs.
Curious to see where Nemotron 3 Super will rank.
@rasbt
-
Qwen3.5 Ranks 7th on Pinchbench as Impressive Small Open-Weight Model
By
–
-
Nvidia Nemotron 3 Super 120B: High Performance Open-Weight LLM
By
–
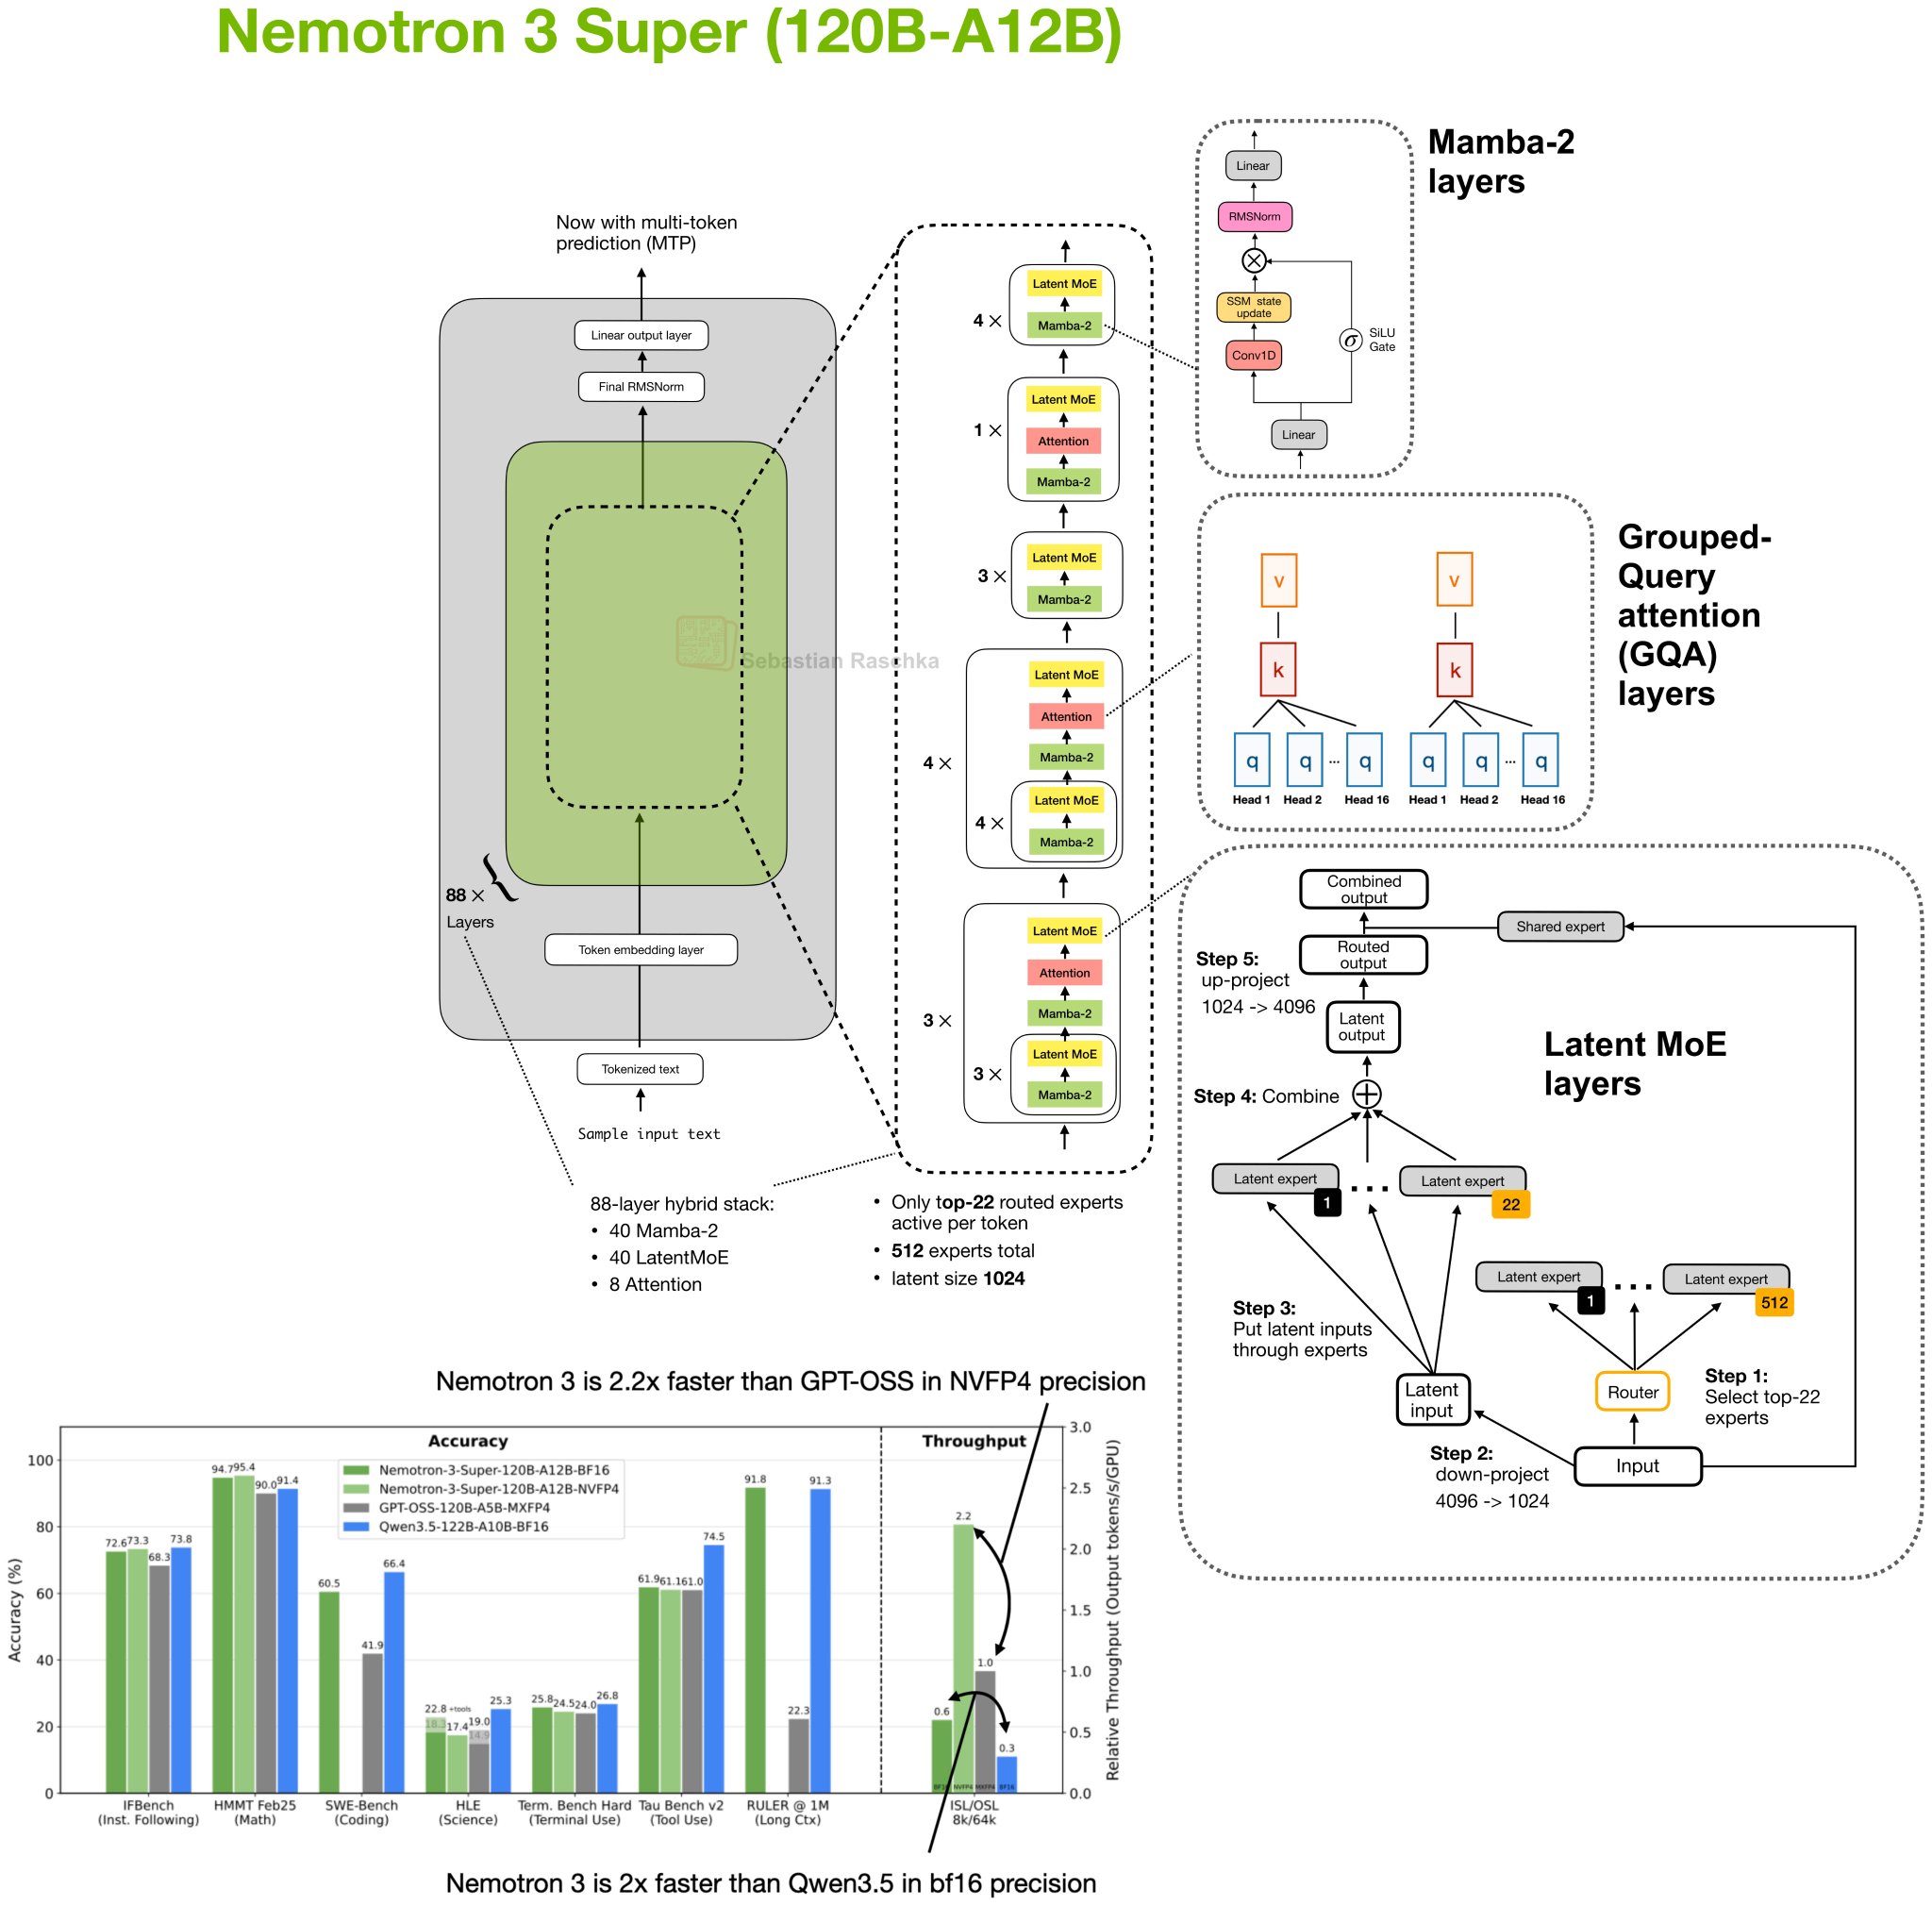
Another week, another noteworthy open-weight LLM release. Nvidia’s Nemotron 3 Super 120B-A12B looks pretty good. Benchmarks are on par with Qwen3.5 122B and GPT-OSS 120B, but the throughput is great! Below is a short, visual architecture rundown.
-
Qwen3.5 Implementation Integration Guide for LLMs
By
–
Thanks! I think it shouldn't be too hard. I have a Qwen3.5 from-scratch implementation here: https://
github.com/rasbt/LLMs-fro
m-scratch/blob/main/ch05/16_qwen3.5/qwen3.5-plus-kv-cache.ipynb
… that you can use as a drop-in replacement. Perhaps the easiest thing to do here is to take that and put it into the qwen. py (
https://
github.com/rasbt/LLMs-fro
m-scratch/blob/main/pkg/llms_from_scratch/qwen3.py
…). If you -
Chapter 8 LLM Distillation Notebook Released on GitHub
By
–
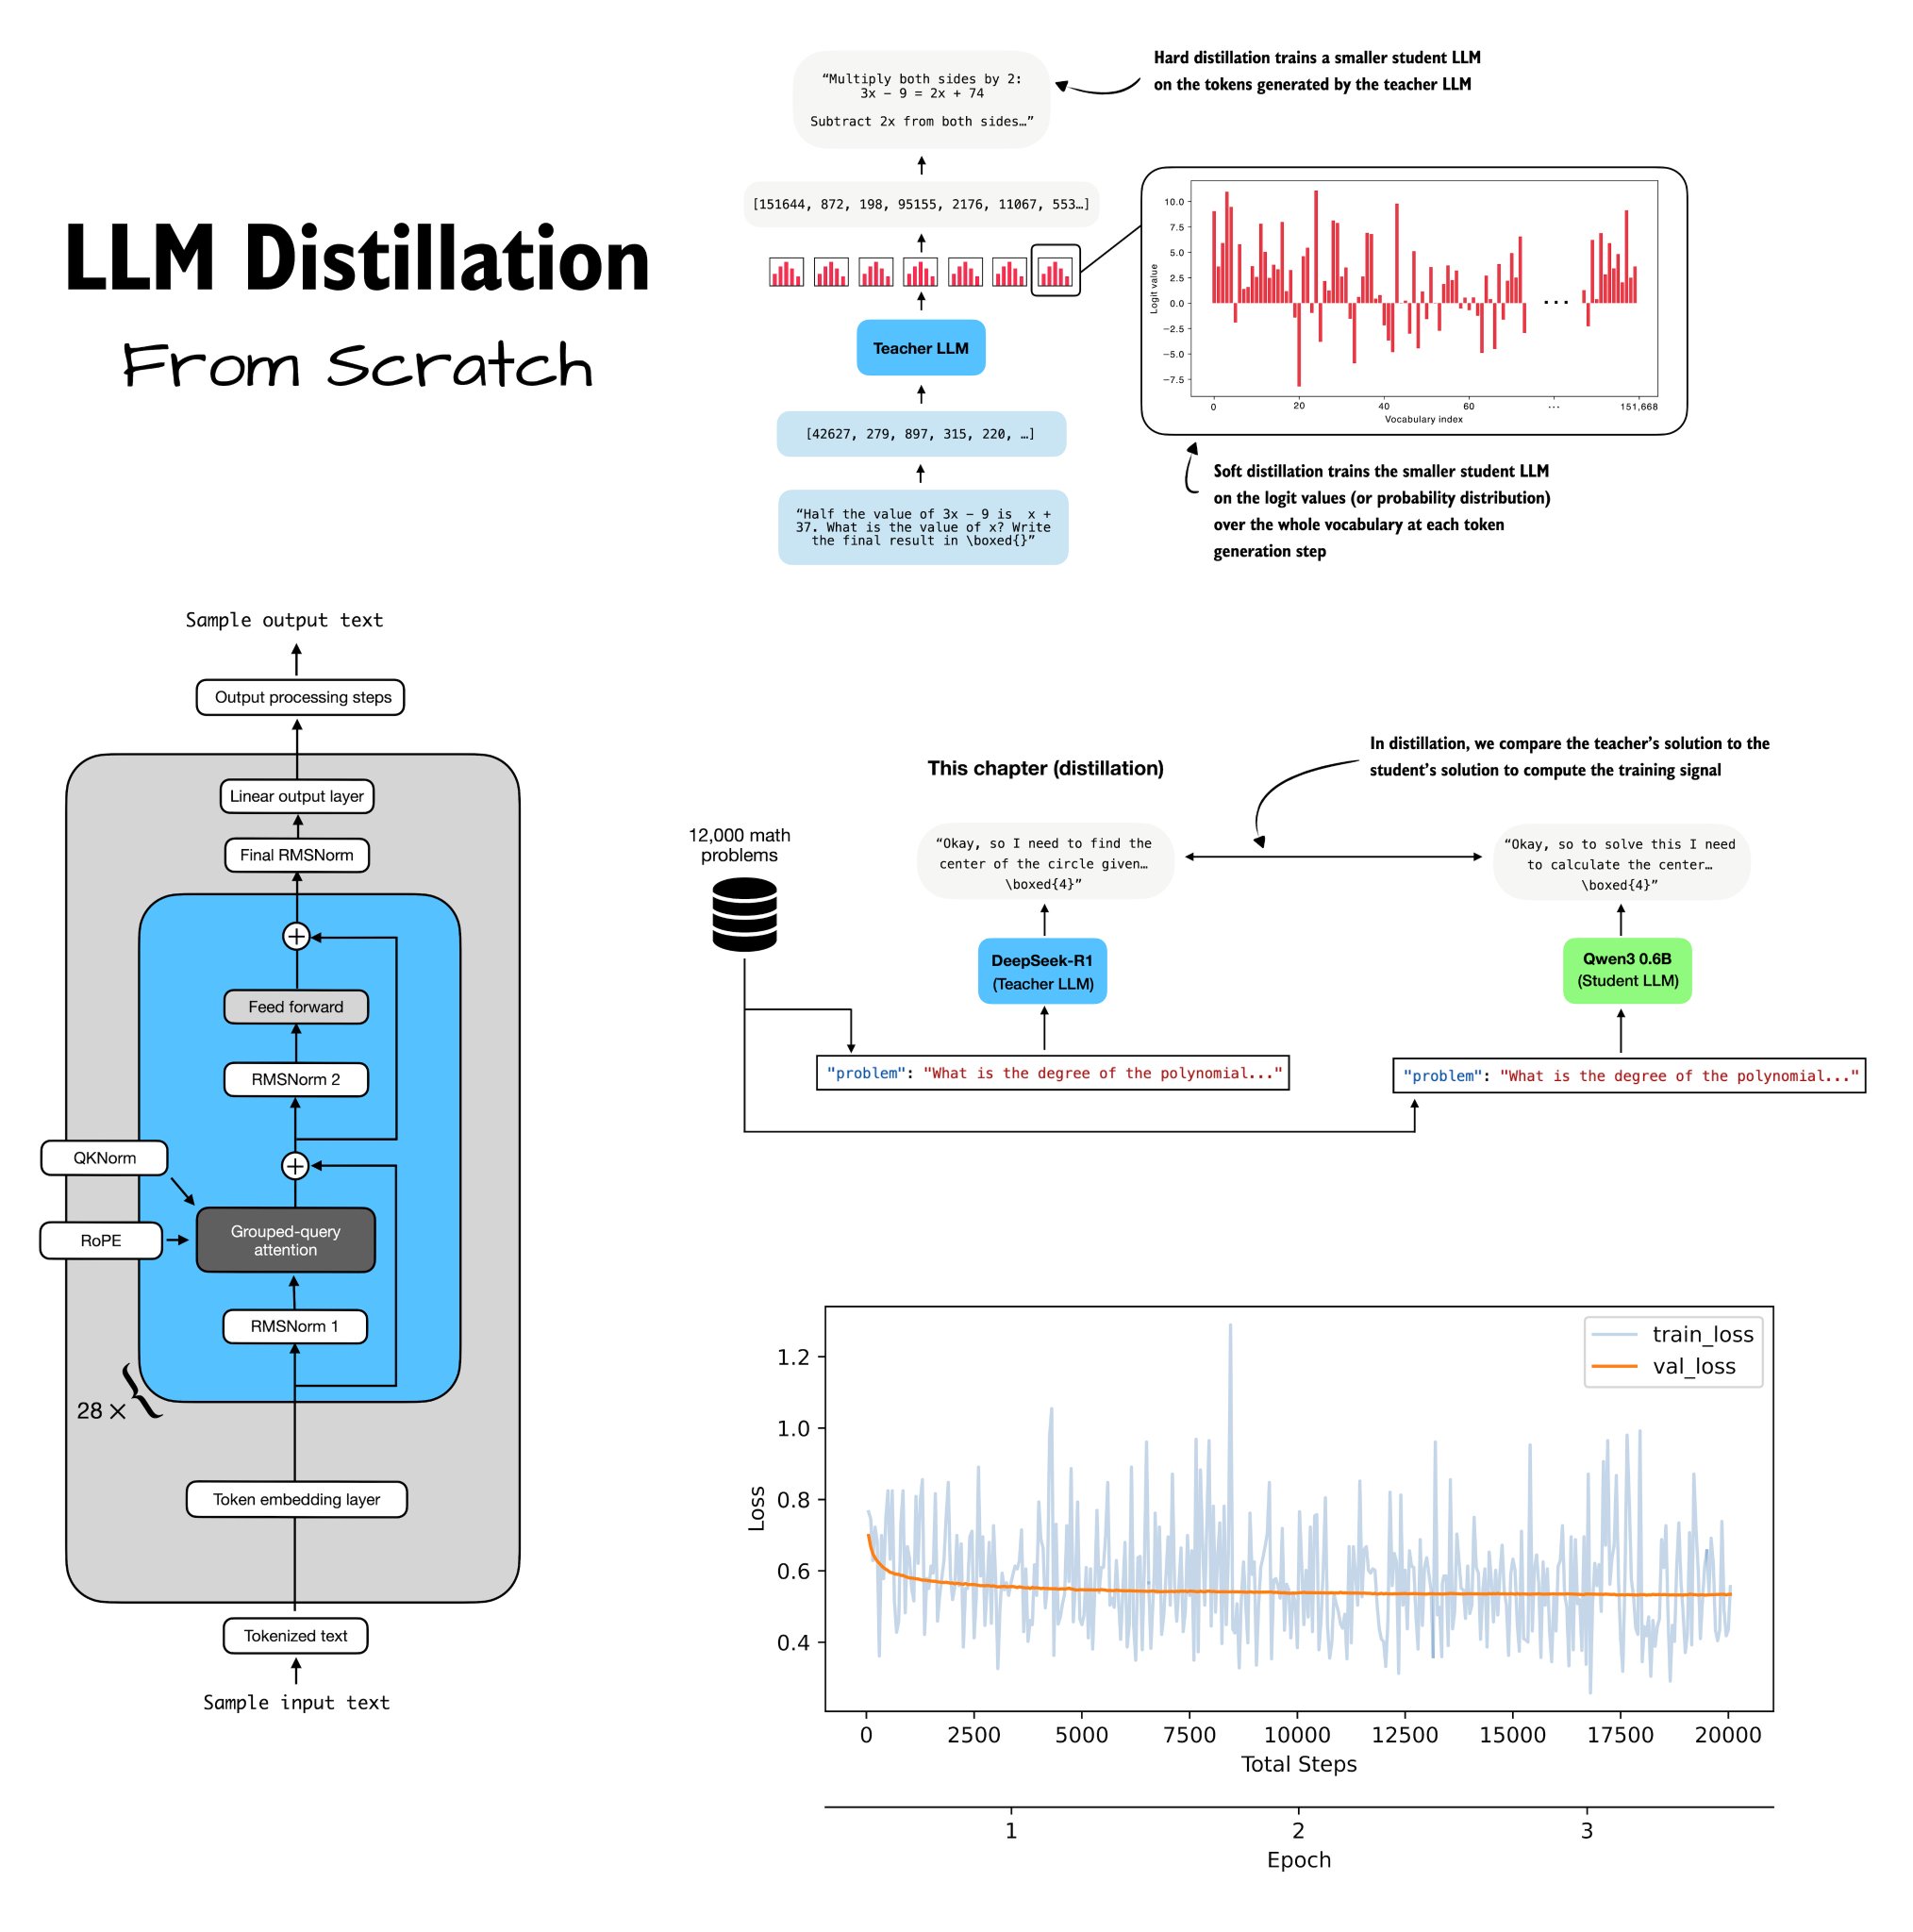
The Ch08 Nb on distilling LLMs is now on GitHub: https://
github.com/rasbt/reasonin
g-from-scratch/blob/main/ch08/01_main-chapter-code/ch08_main.ipynb
… Hard distillation that works with any LLM (minding the terms of service, of course). -
Running MiniMax M5 Model on Mini M5 Max Hardware Locally
By
–
To run MiniMax M5 on a Mini M5 Max locally
-
RLVR Sequel with GRPO and Distillation Techniques
By
–
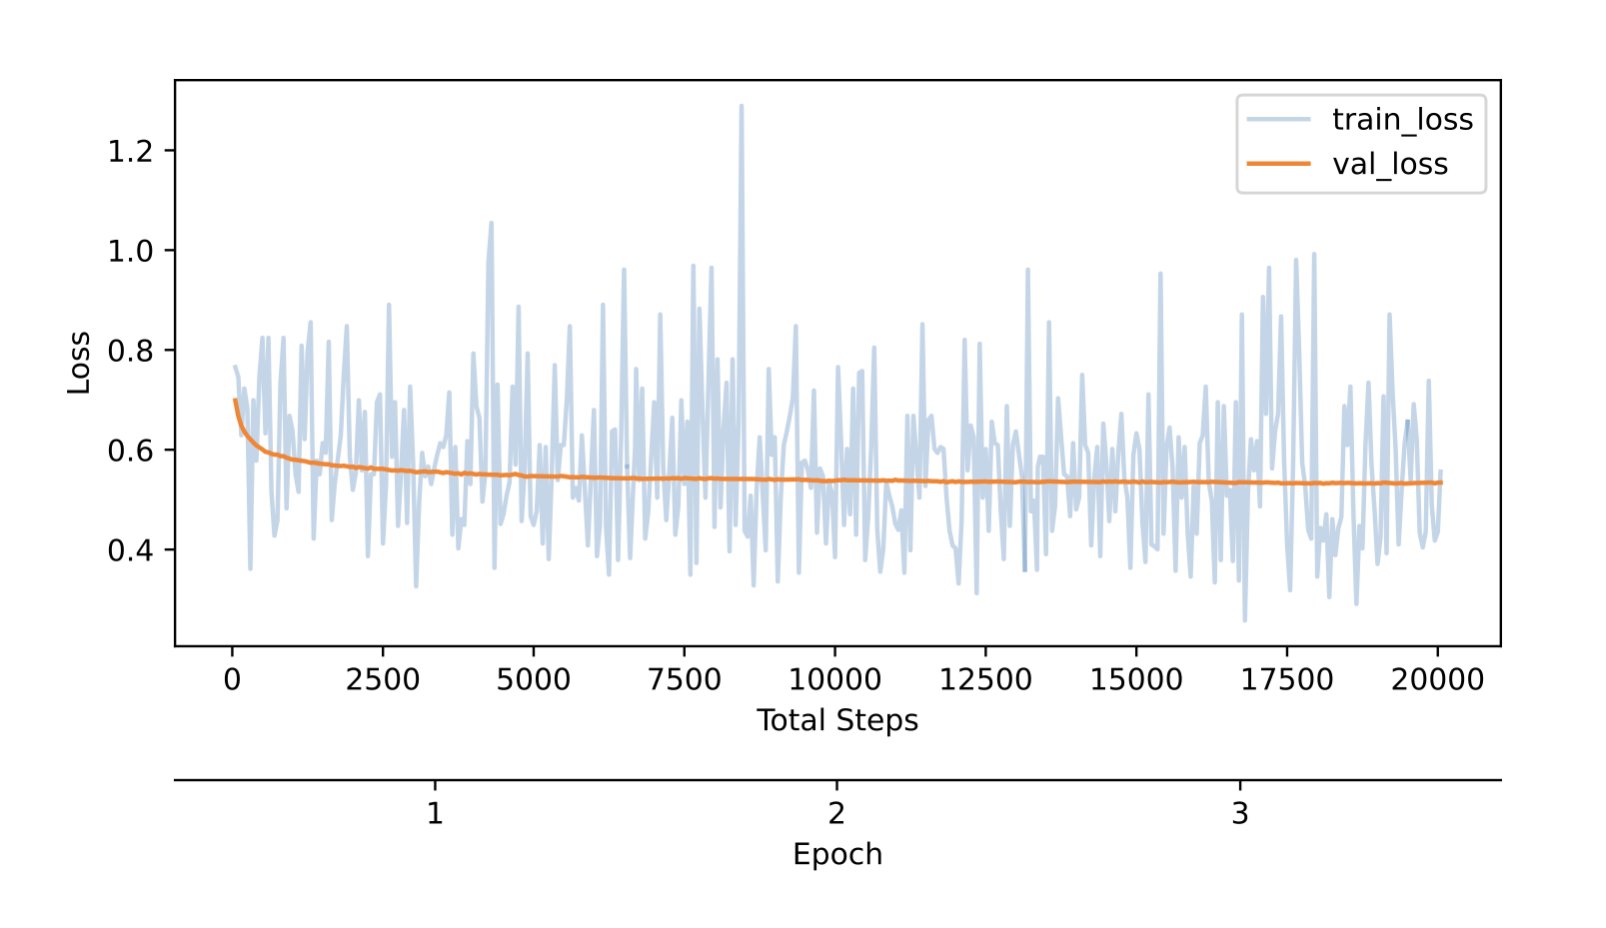
Thanks! You might also like the sequel on RLVR with GRPO and distillation: https://
github.com/rasbt/reasonin
g-from-scratch/tree/main/ch06
… -
DeepSeek V3.2 Uses Mixture of Experts Together
By
–
yeah they are used together like in DeepSeek V3.2
-
MLA Uses DSA Underneath According to DeepSeek V3.2
By
–
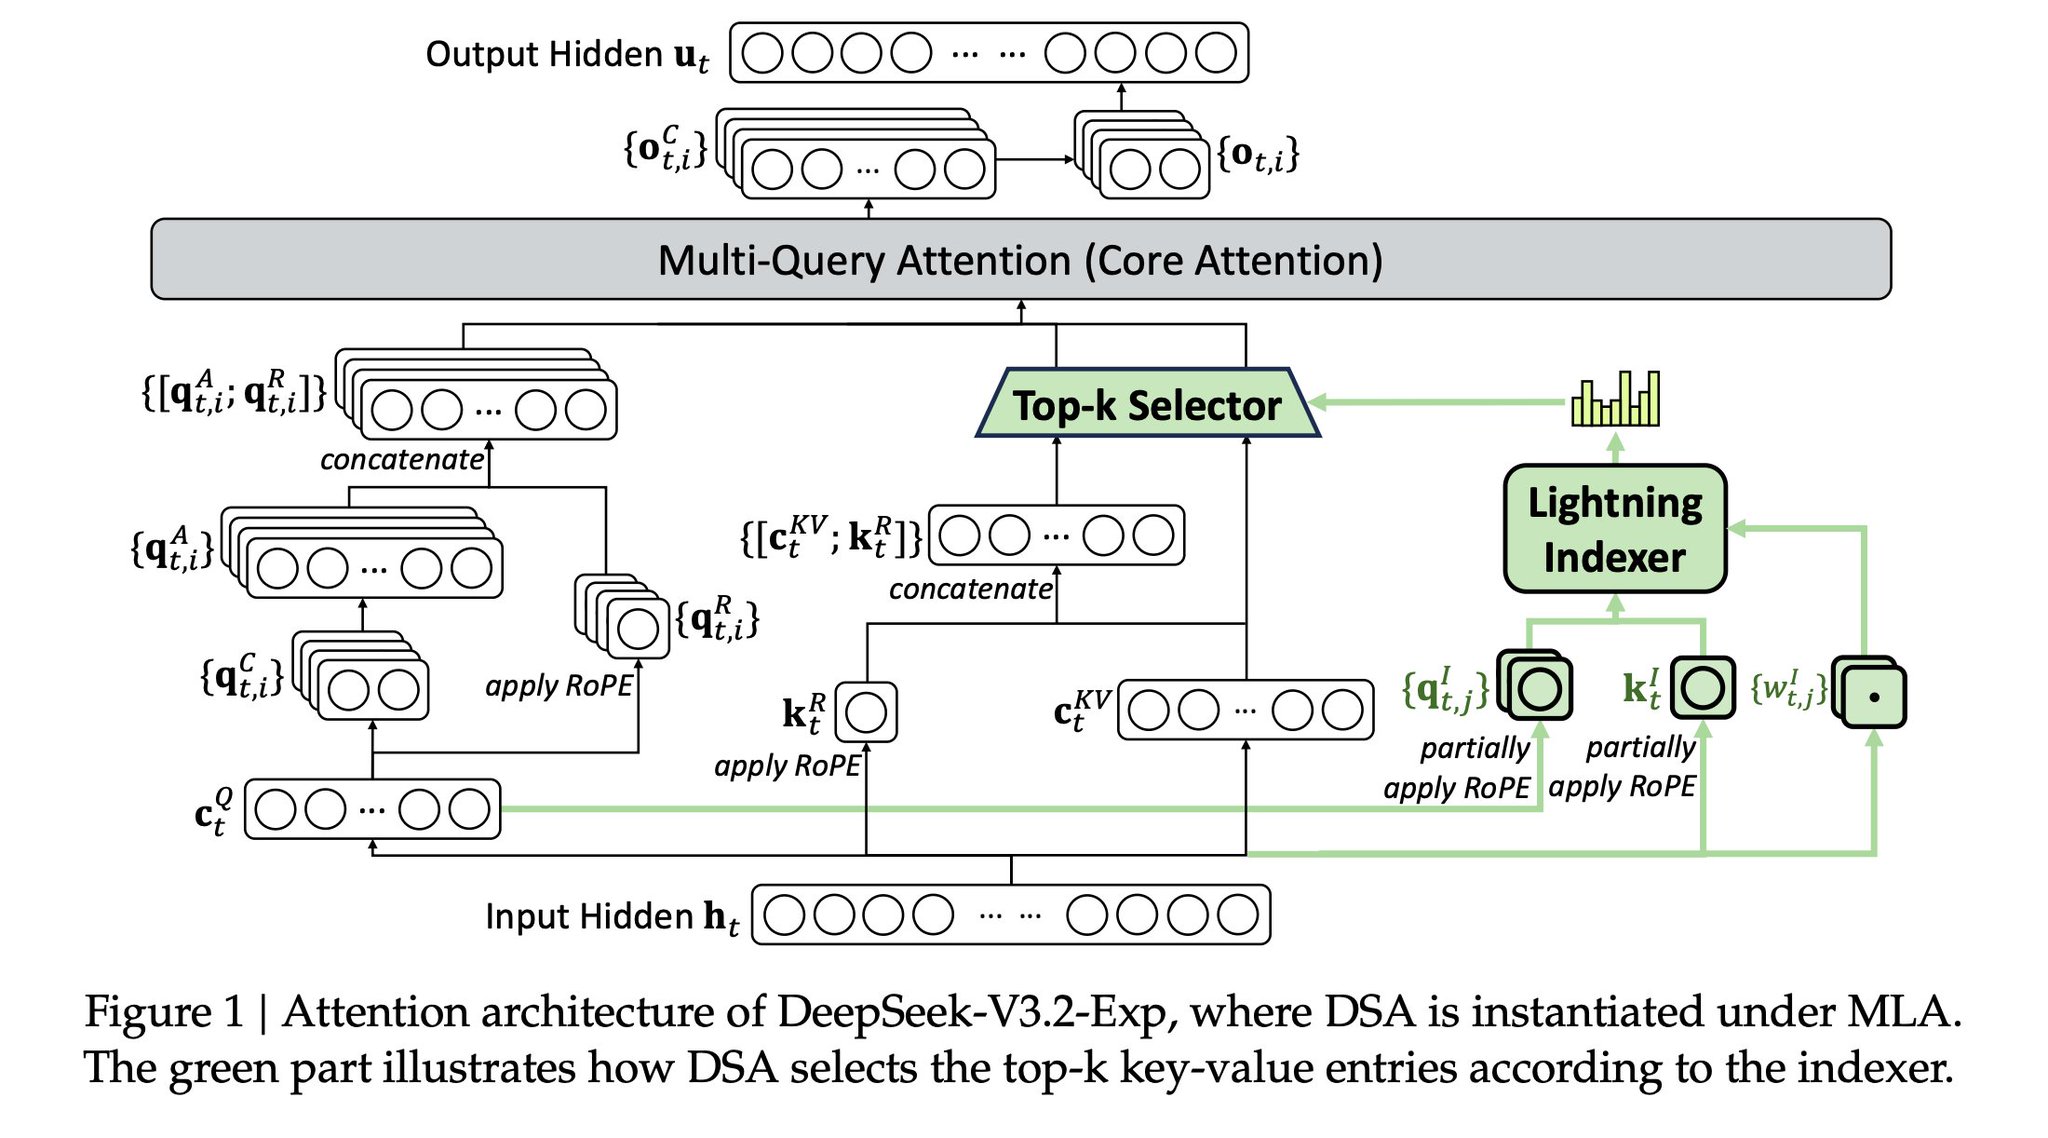
I'd say it the other way around: MLA uses DSA underneath, but that's right! E.g., from the DeepSeek V3.2 paper:
-
DSA: Learning-Based Token Selection Beyond Fixed Window Attention
By
–
Also, DSA is basically a smarter version of sliding window attention where you "learn" which past tokens to select versus forcing it to be in a specific window