But is there evidence that they actually do that? I mean lots of companies could theoretically do that, but is it worthwhile compared to pre-training larger models (more experts) or using that compute for additional post-training?
PS: also there are two companies that have TPUs
@rasbt
-
Evidence for MoE Scaling vs Larger Pre-training Models
By
–
-
Build A Reasoning Model Chapter Release Coming This Week
By
–
The next chapter of Build A Reasoning Model (From Scratch) should drop soon! There's been a bit of delay getting that into the early access from the publisher's front due to the holidays, but I hope this week!
-
PyTorch version preferred over TensorFlow edition
By
–
The one to the right is the PyTorch edition of the one to the left (which uses TensorFlow). Definitely would prefer that one.
-
Writing Chapter 6 on RLVR with GRPO
By
–
Currently more than half way through writing chapter 6 on RLVR with GRPO. I think if you liked Build an LLM from scratch you will like it even better
-
Base Models Trained on CoT Data: Finding the Silver Lining
By
–
Yeah, there is a silver lining. But I think it gets a bit muddled since most base models are trained on CoT data.
-
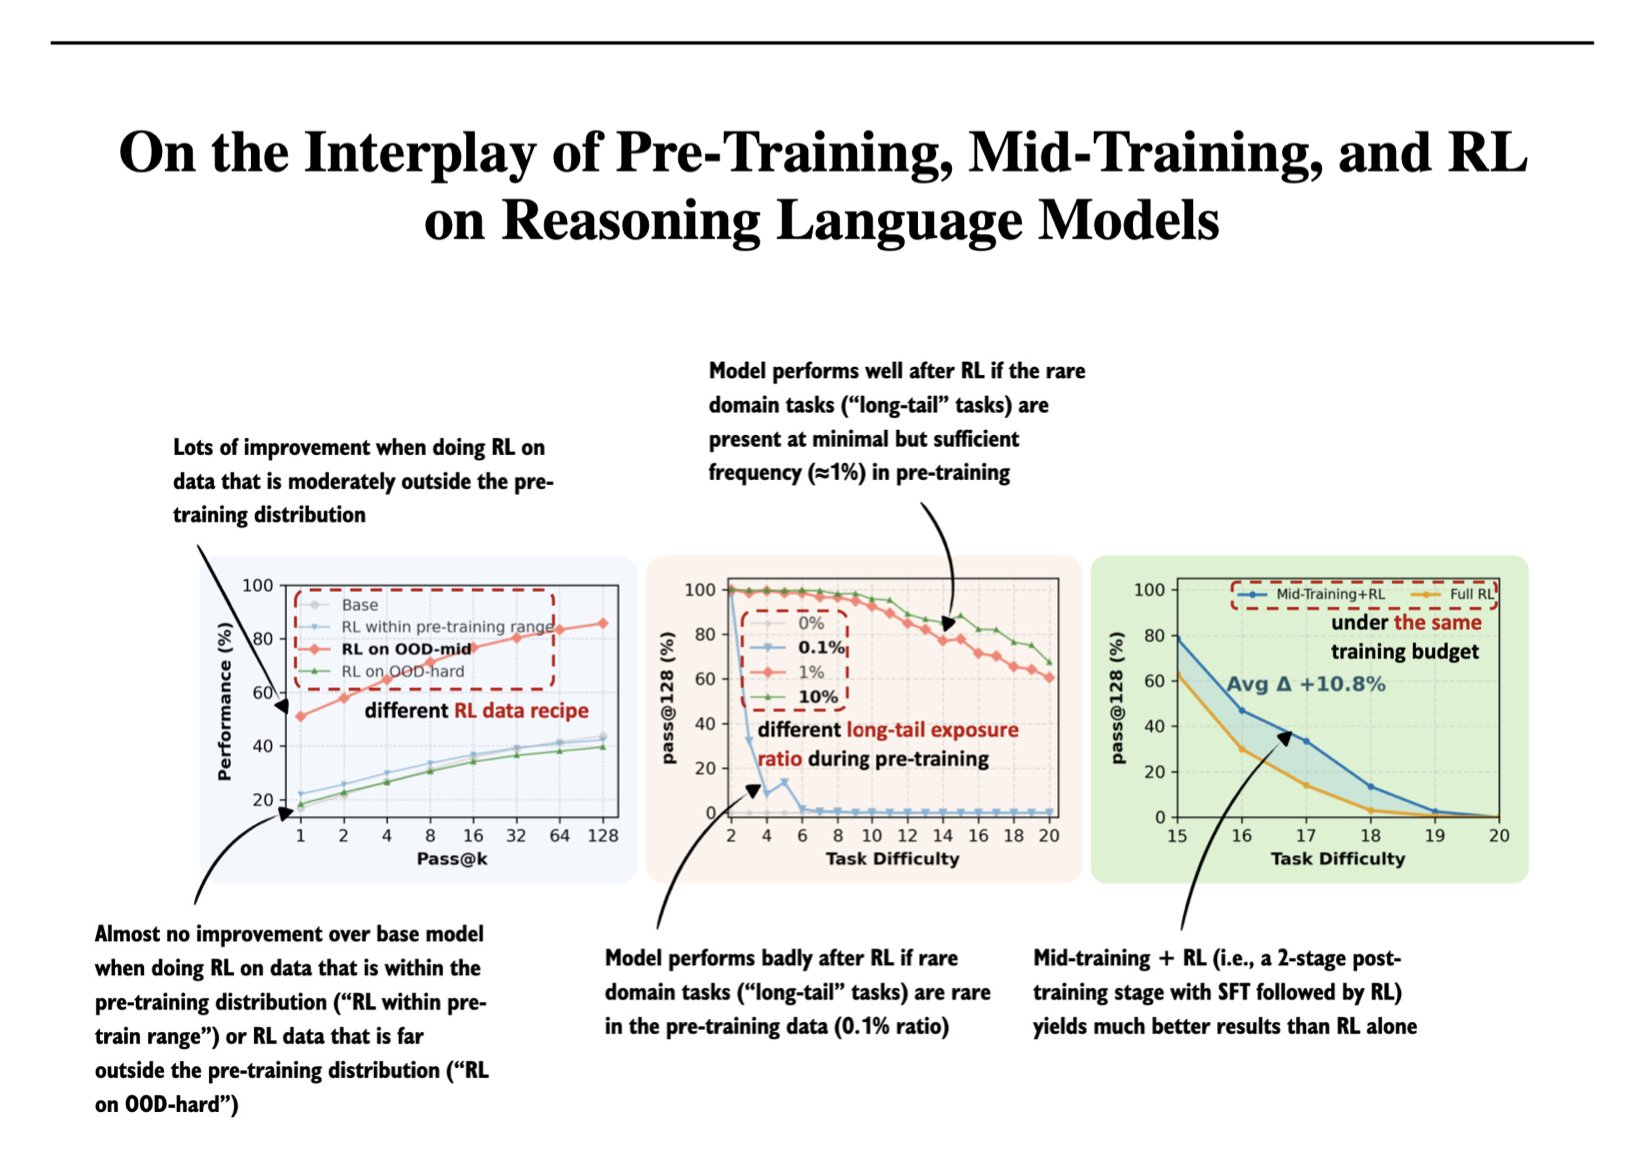
Optimal RL Balance in Training Reasoning Models
By
–
Another really interesting paper from my 2025 bookmarked papers: On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models (https://arxiv.org/abs/2512.07783). In short, RL is most effective when applied to data that is neither too close to nor too far from the
-
Text Diffusion as Alternative to Standard LLMs
By
–
I wrote a bit about it here https://
magazine.sebastianraschka.com/p/beyond-stand
ard-llms
… but in short, I don't think there's a real viable alternative at the moment.
– Text diffusion is interesting as a lower-cost option (Google is planning to launch Gemini Diffusion some time as alt. to their lowest cost Flash -
Increasing Context Length and Model Capacity: Expensive Trade-offs
By
–
Either
a) you increase the context length and/or let the model crawl through stored data
b) you start of with a model that has large enough capacity and periodically update the weights
Both options are expensive, so I am not sure they actually want this right now. -
Experimenting with Olmo 3 and DeepSeek V3.2 GRPO tweaks
By
–
Oh yeah you probably will. I am currently running tons of experiments to decide which of the Olmo 3 and DeepSeek V3.2 GRPO tweak I should add in the final version.
No side objective really except I'd do an honest evaluation to make sure that the model actually learns well. -
Pre-trained Base Models Lacked Instruction-Following Capabilities
By
–
Yeah, I guess that’s right. They were probably only pre-trained base models at that time and didn’t have good instruction-following abilities.