Special thanks to: – @failspy for his notebook and abliterated models
– Arditi et al. (cc @NeelNanda5
) for the excellent "Refusal in LLMs" blog post (
https://
lesswrong.com/posts/jGuXSZgv
6qfdhMCuJ/refusal-in-llms-is-mediated-by-a-single-direction
…)
– All the LLM mergers and fine-tuners for the source models
– Charles Goddard and @arcee_ai for MergeKit
@maximelabonne
-
LLM Interpretability and Refusal Mechanisms Research Acknowledgments
By
–
-
NeuralDaredevil-8B Model Improvement Through DPO Training
By
–
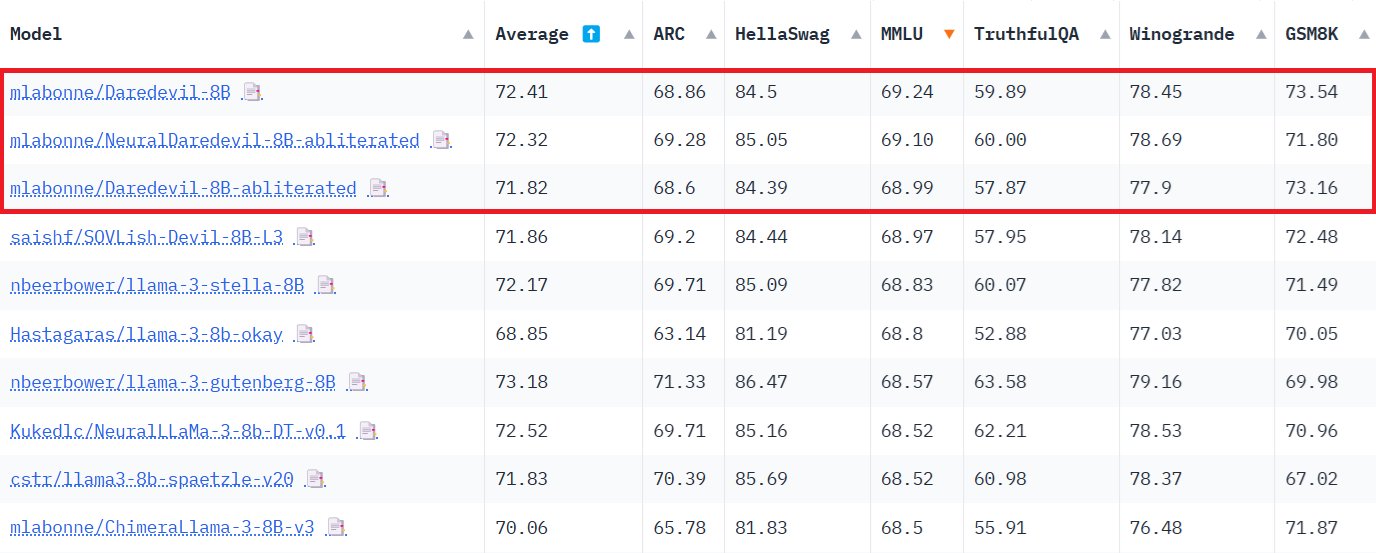
There's still room for improvement: GSM8K suffered because it's underrepresented in my DPO dataset. More epochs would definitely help too. I find it super exciting and I'm curious to see how people will use it. NeuralDaredevil-8B:
-
DPO Fine-Tuning Fixes Instruct Model Performance Effectively
By
–
I healed it using DPO fine-tuning. Unlike SFT, it doesn't lobotomize the Instruct model. I trained it for one epoch of orpo-dpo-mix-40k with an lr of 5e-6 and a sequence length of 2048 using Axolotl. This successfully fixed the model as you can see on the benchmarks.
-

Removing Meta Alignment from Daredevil-8B Model
By
–
But Daredevil-8B is still censored. Many people asked me for uncensored models, so I wanted to try something. I used @failspy
's abliteration notebook to remove Meta's alignment. Unfortunately, abliteration also slightly degrades performance: 1-2% on every benchmark. -

Daredevil-8B: Mega-Merge Model Using DARE TIES
By
–
Daredevil-8B is a mega-merge composed of 9 models using DARE TIES. Like the original Daredevil-7B, the model recipe was designed to maximize the MMLU score. The model family tree is already quite wild. Daredevil-8B: https://
huggingface.co/mlabonne/Dared
evil-8B
… -

NeuralDaredevil-8B Achieves Top MMLU Scores Among 8B Models
By
–
NeuralDaredevil-8B Daredevil-8B has the highest MMLU score among 8B models on the Open LLM Leaderboard. Thanks to abliteration and DPO fine-tuning, I managed to create an uncensored version that outperforms Llama 3 Instruct 8B on every benchmark (9 tested).
-
AI Model Performance Regression Discussed in Technical Community
By
–
Yeah it's broken, the model even recovered the MMLU loss
-
Building Large Language Models From Scratch Repository
By
–
Thanks Sebastian, I really enjoy Build a Large Language Model From Scratch. Amazing repo too!
-
Models Show Refusal Behavior on Harmless Instructions
By
–
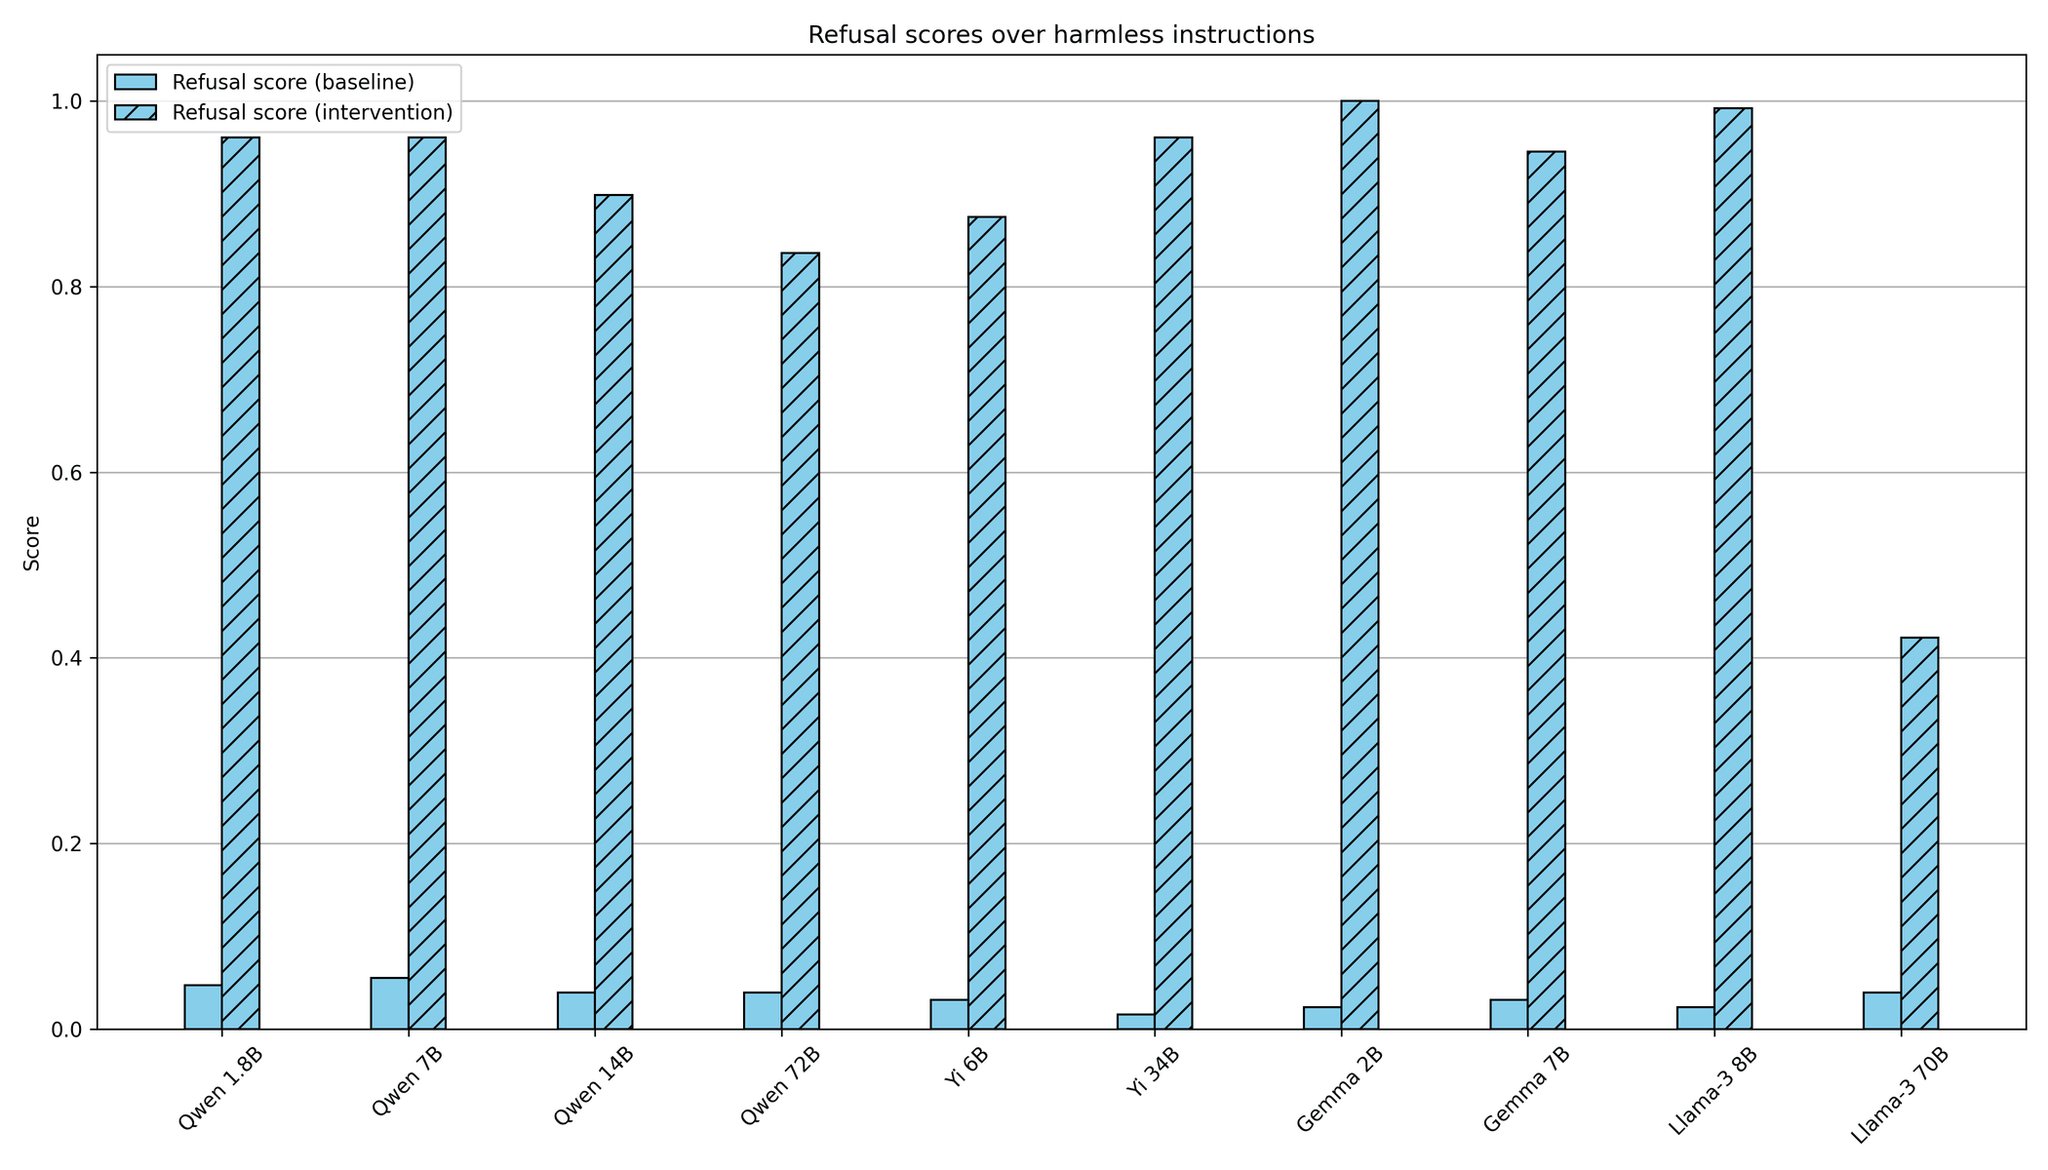
Yes they also show it in the blog post. In this figure, they've added the refusal direction and you see models refusing harmless instructions
-
New Abliterated Models Released for Larger AI Systems
By
–
They also released a collection of abliterated models. I recommend giving it a try (especially for larger models).