I haven't checked but that sounds good indeed, you might be able to directly do a phi-3 MoE with this
@maximelabonne
-

Create Your Phi MoE: Phixtral Reproduction Guide
By
–
Create your Phi MoE In January, I released Phixtral, the first MoE based on Phi-2. I said I would release the code, but Microsoft decided to modify Phi-2, which broke my version. Thanks to Vishal Rajendra Kumar, we now have a way to reproduce Phixtral with his Phi2xtral
-
Indie Developer Releases Graph Neural Networks Book
By
–
I've spent 15 years making indie video games but my first release on Humble Bundle is my book about Graph Neural Networks. Please support your local indie GNN developer https://
humblebundle.com/books/generati
ve-ai-packt-books
… -
Mergekit Weight Merging Limitations Across Different Architectures
By
–
You can't merge the weights of different architectures with mergekit. I quite like this solution but I don't expect it to be competitive
-
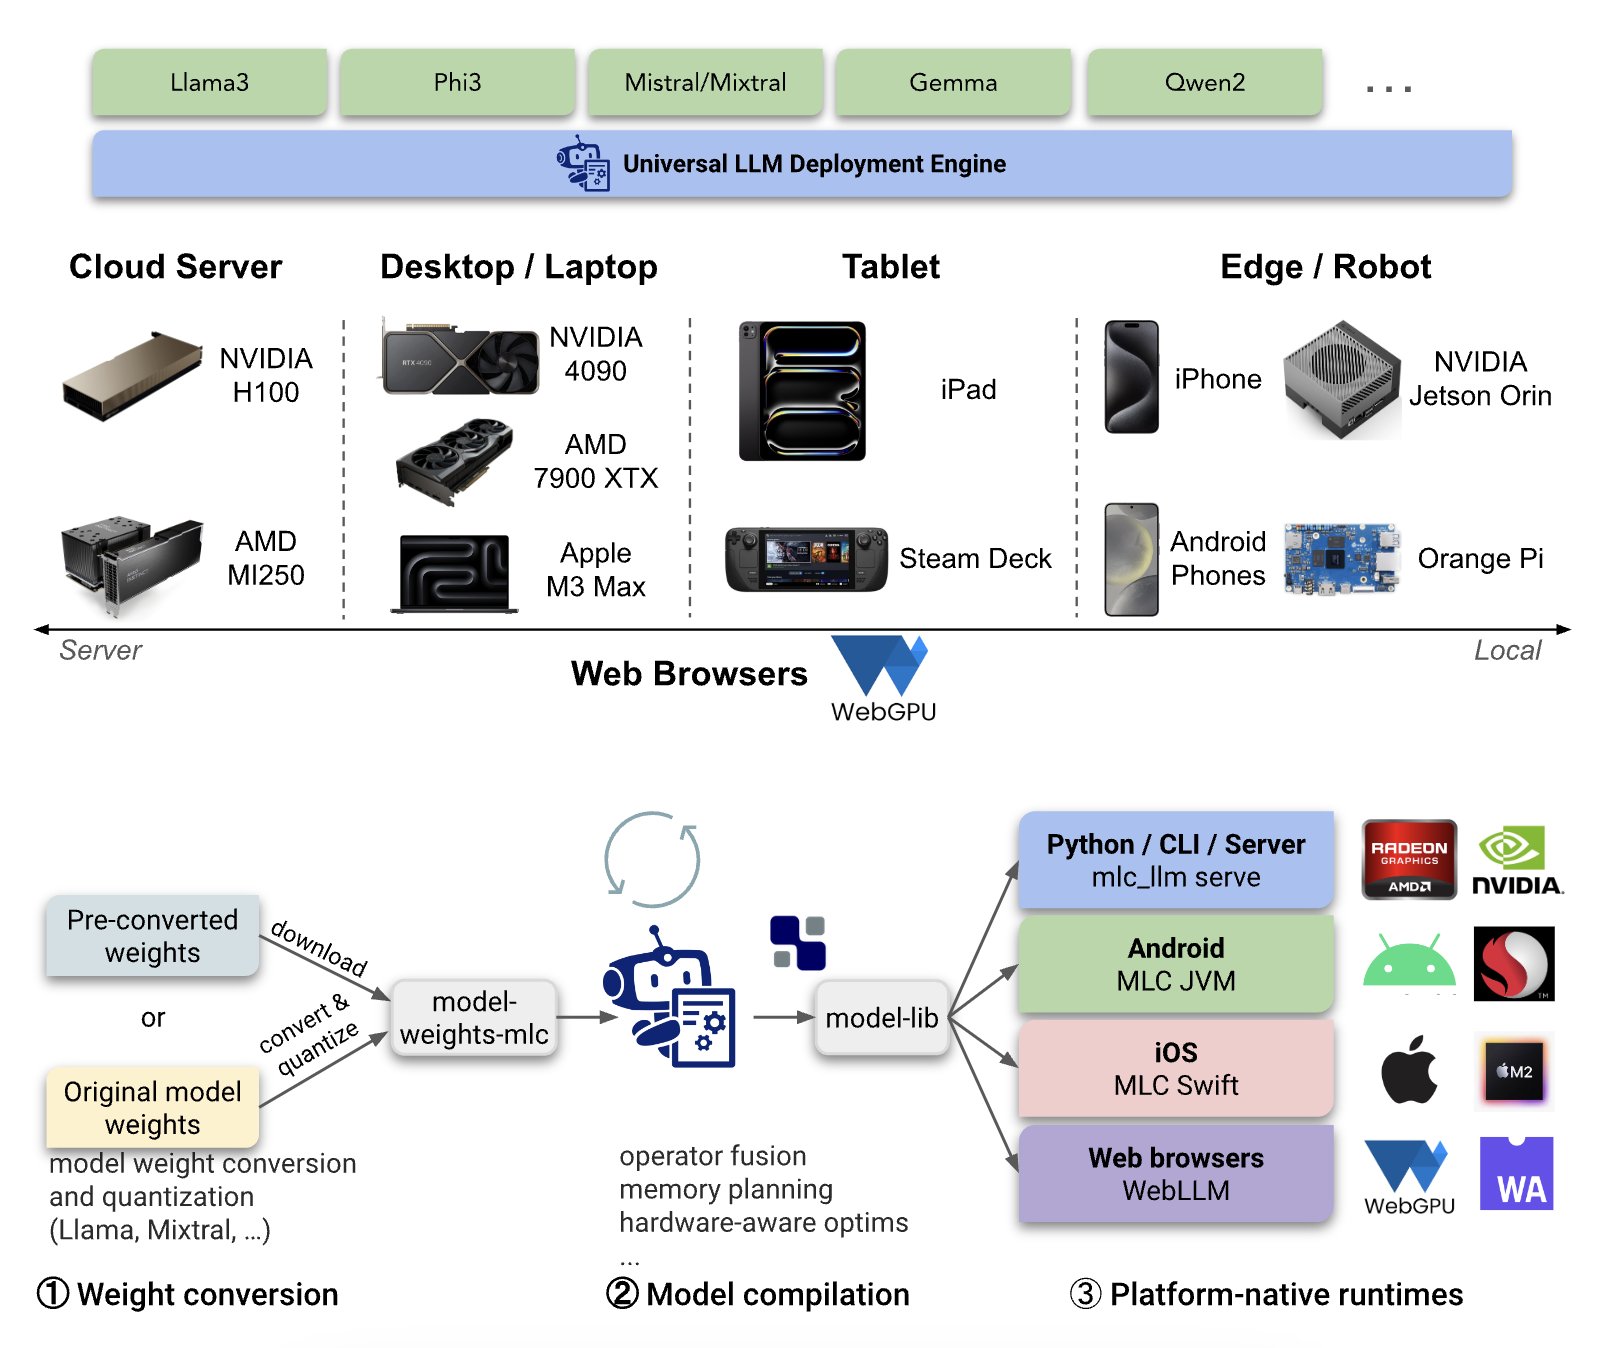
MLCEngine unifies cloud and local LLM deployment across devices
By
–
MLCEngine The cool MLC project now supports both cloud and local deployment in a unified engine. It can deploy LLMs on servers with multi-GPU support or local devices like laptops, browsers (WebGPU), and phones Quick start: https://
llm.mlc.ai/docs/get_start
ed/quick_start.html
… -
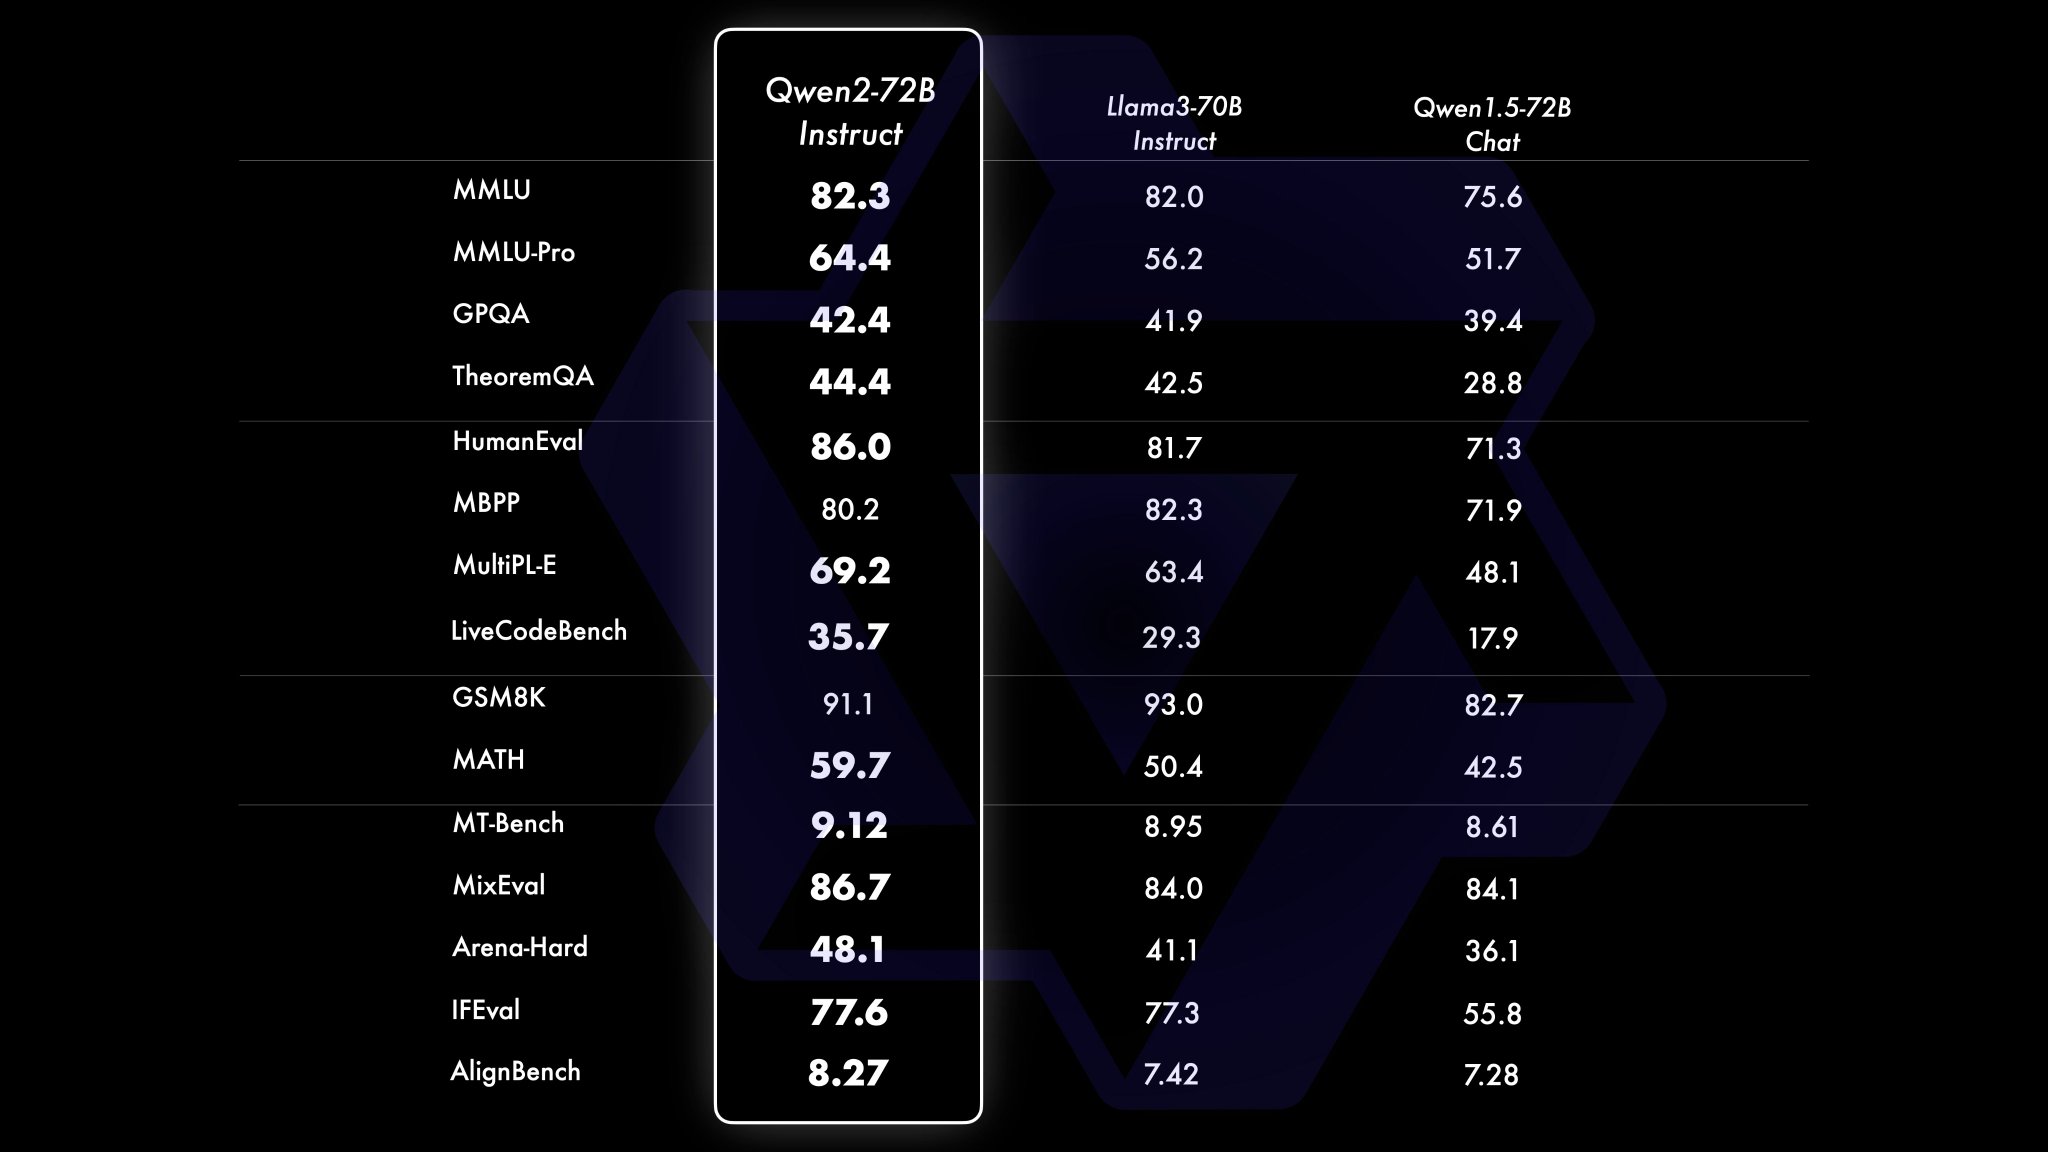
72B Model Benchmarking: MixEval and MMLU-Pro Performance Analysis
By
–
The 72B model looks amazing but wow what an excellent benchmarking! Super happy to see MixEval and MMLU-Pro there. I have high hopes for MixEval as a proxy for Arena Elo. Also curious to see if these models behave better than Llama 3 for SFT.
-
Adversarial Techniques Work Across Languages and Model Architectures
By
–
Yes, I can confirm that it also works in other languages (tested in French with NeuralDaredevil). I haven't tried to apply it to MoE models but it should work too. It may be trickier to choose a refusal direction because there are more blocks.
-
AirLLM throughput performance assessment and testing
By
–
AirLLM? No I haven't tested it, I don't think the throughput will be interesting
-
Large AI Model Requires Over 140 GB RAM VRAM
By
–
Sure but it'll take over 140 GB of RAM/VRAM, so not ideal
-
Replicating 70B Model: Fine-tuning Challenges and Solutions
By
–
Yeah all the steps can be replicated for a 70B version. The only issue is we don't have as many high-quality fine-tunes of this model.