Abliterating LLMs is the most interesting trend I've seen in months A simple weight modification can jailbreak models without any retraining. Here's how it works: Identification – Run model on harmful & harmless prompts
– Capture activations at the last token position
–
@maximelabonne
-

Weight Modification Jailbreak Technique for Large Language Models
By
–
-
Phi Models Overrated: Scaling Remains Safest Path Beyond GPT-4o
By
–
I'm slightly skeptical about Phi models, which are very good but overrated in benchmarks imo I'd say it's not necessary, but scaling is definitely the safest way of surpassing GPT-4o
-
Code Generation Advancement in AI Development
By
–
Hey that's cool. I worked a lot in code gen, it's great to see this
-
Gemini Performance Improvement on MMLU Benchmark
By
–
Agreed, MMLU is not a great benchmark and Gemini has improved quite a lot
-
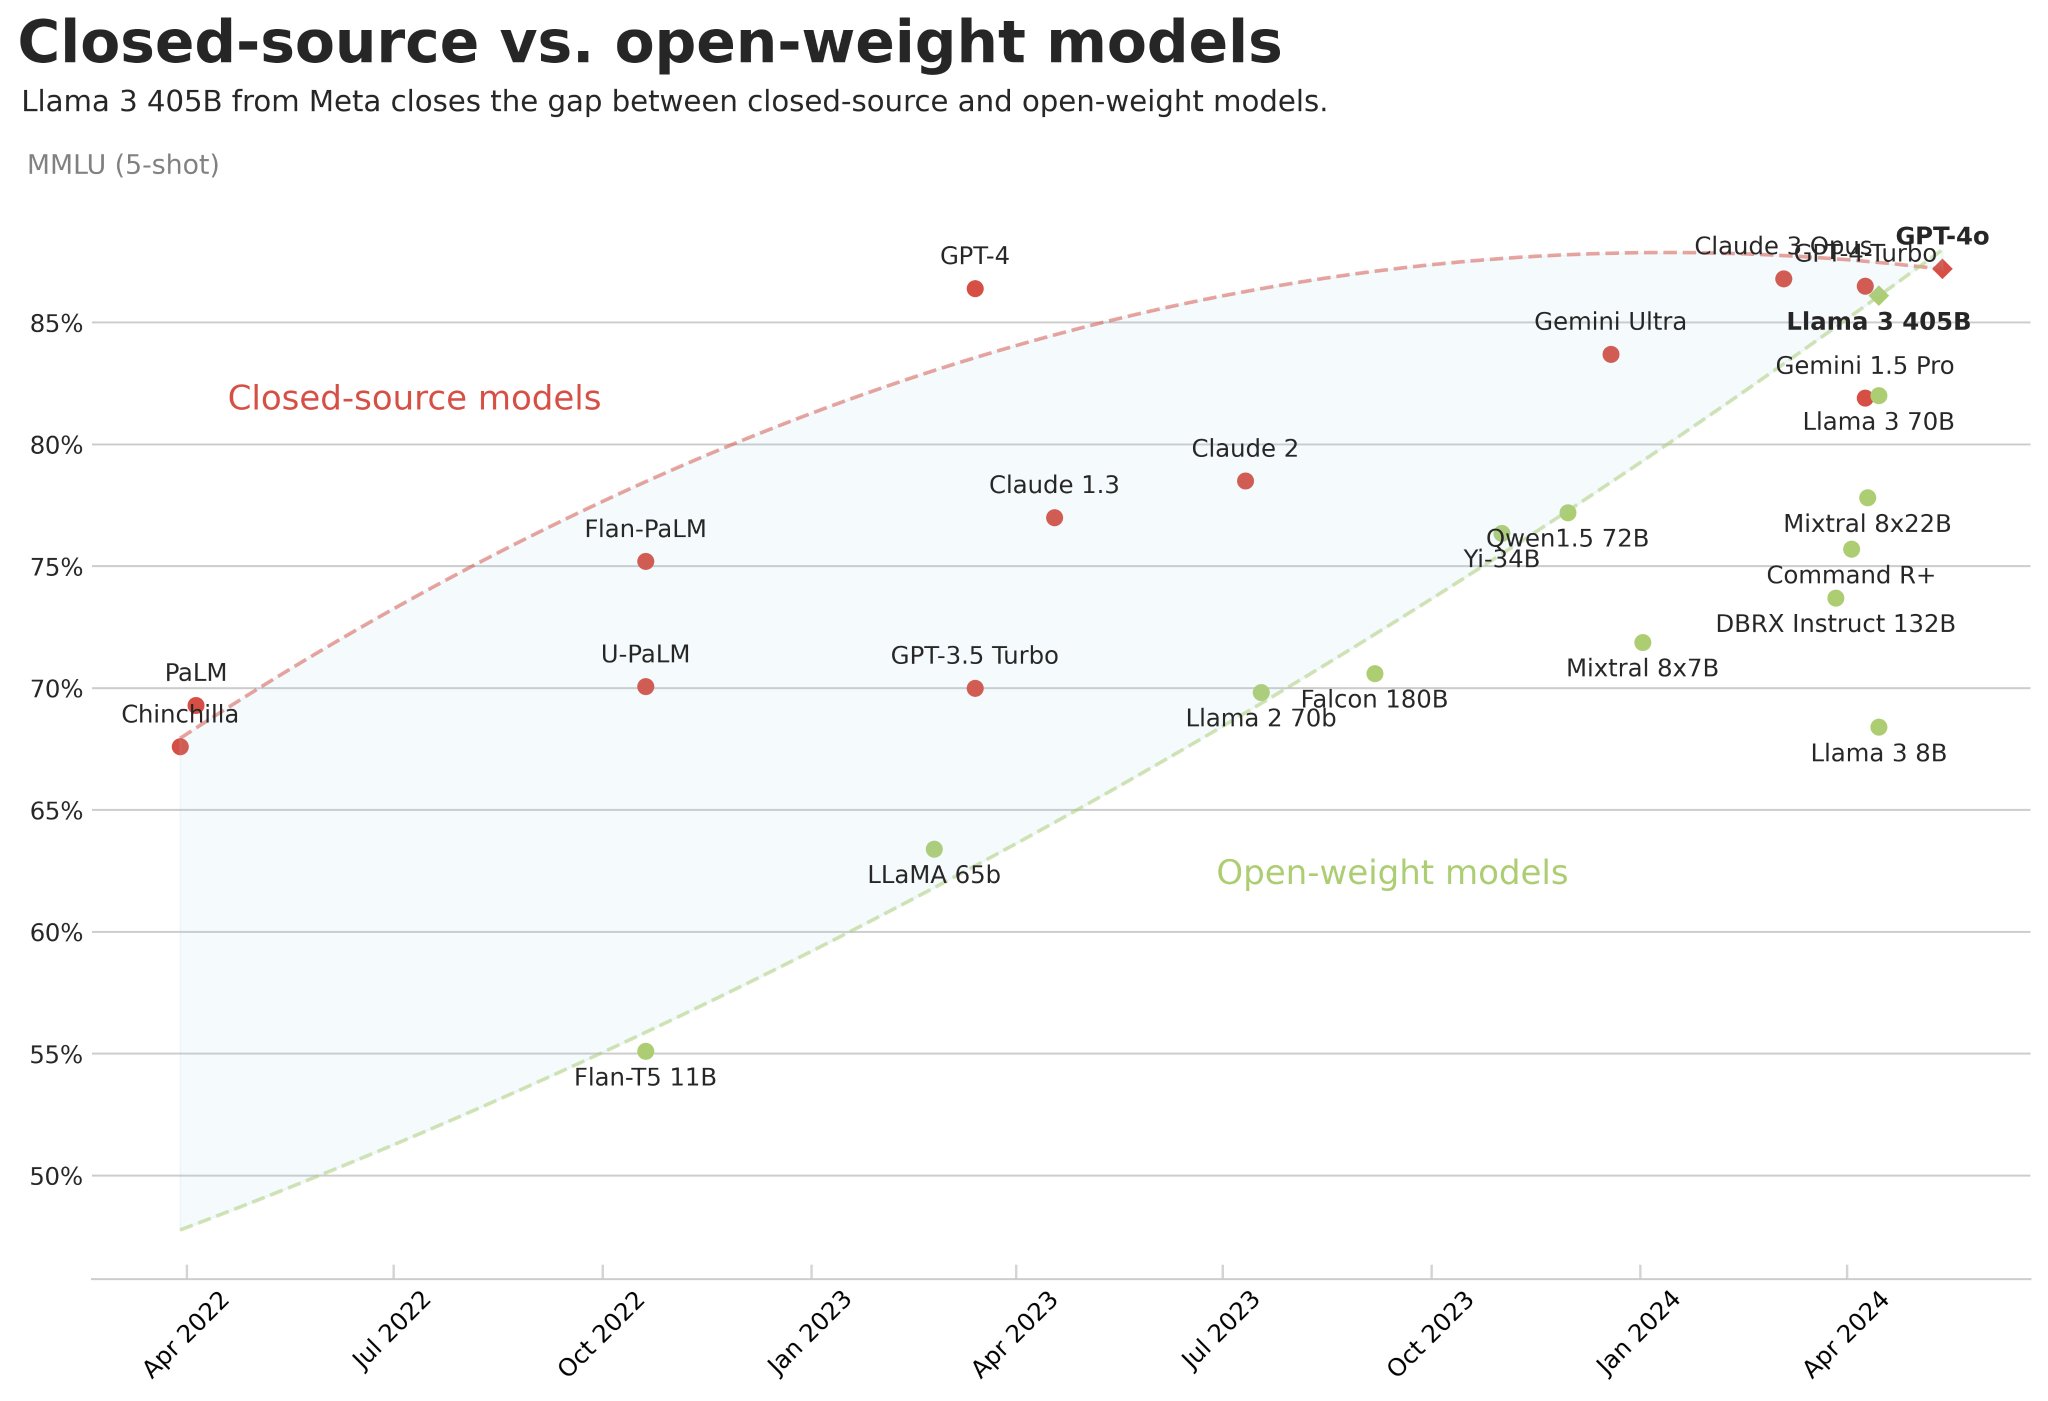
Llama 3 405B Closes Gap with GPT-4o on MMLU
By
–
The gap between closed-source and open-weight models is closing in terms of MMLU The release of GPT-4o is not a significant breakthrough with a score of 87.2% on the 5-shot MMLU (source: https://
openai.com/index/hello-gp
t-4o/
…). On the other side, Meta reported that Llama 3 405B's -
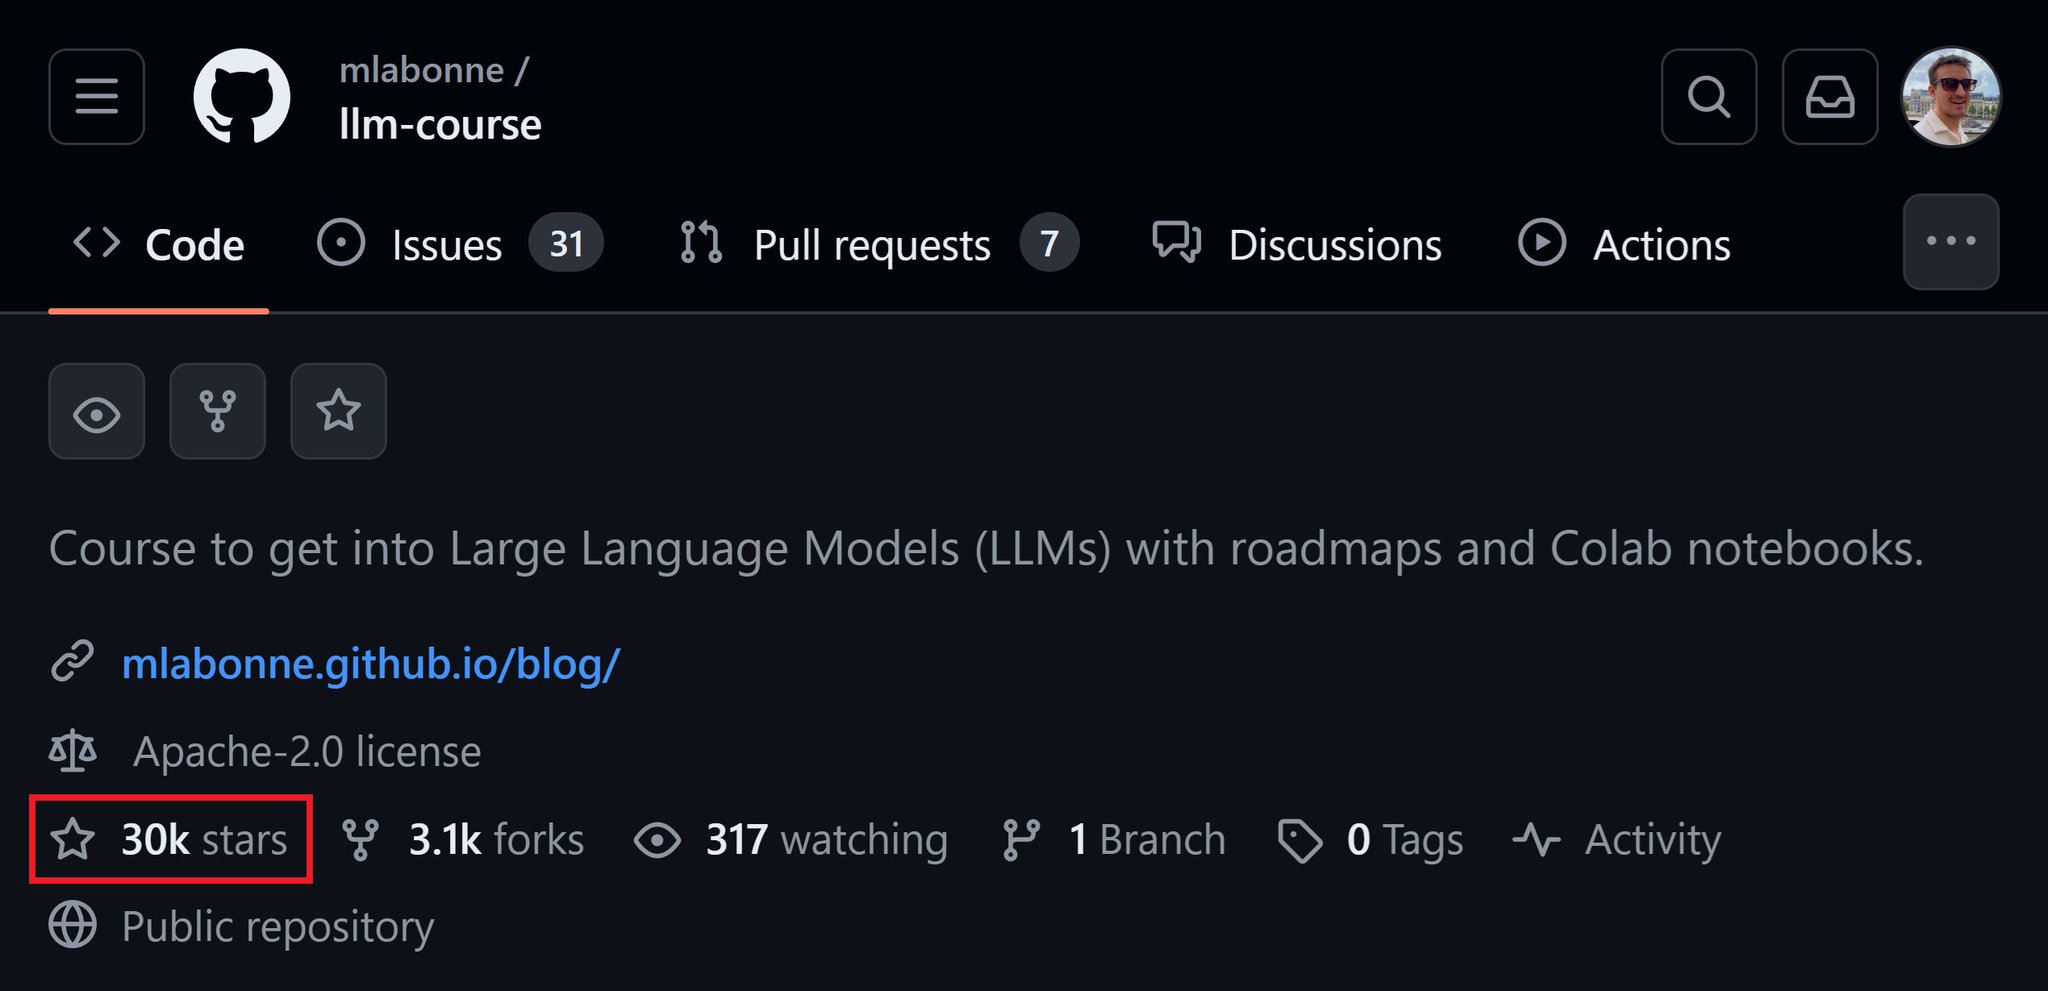
LLM Course Reaches 30k Stars on GitHub
By
–
The LLM Course hit 30k stars on GitHub! This is beyond anything I imagined. To compare, vLLM has 20k stars and Jax has 28k. We're not at llama.cpp (58k) or PyTorch (78k) yet, but this already feels indecent. Thanks for all the support! I'll be adding new sections and
-

Quarto Publishing Platform for Technical Blogging
By
–
Just updated my blog with new info, links, and various fixes: https://
mlabonne.github.io/blog/ Once again, this is the time to recommend @quarto_pub if you want to start a blog. It natively handles markdown and Jupyter notebooks. It's customizable, easy to use, and looks pretty good! -
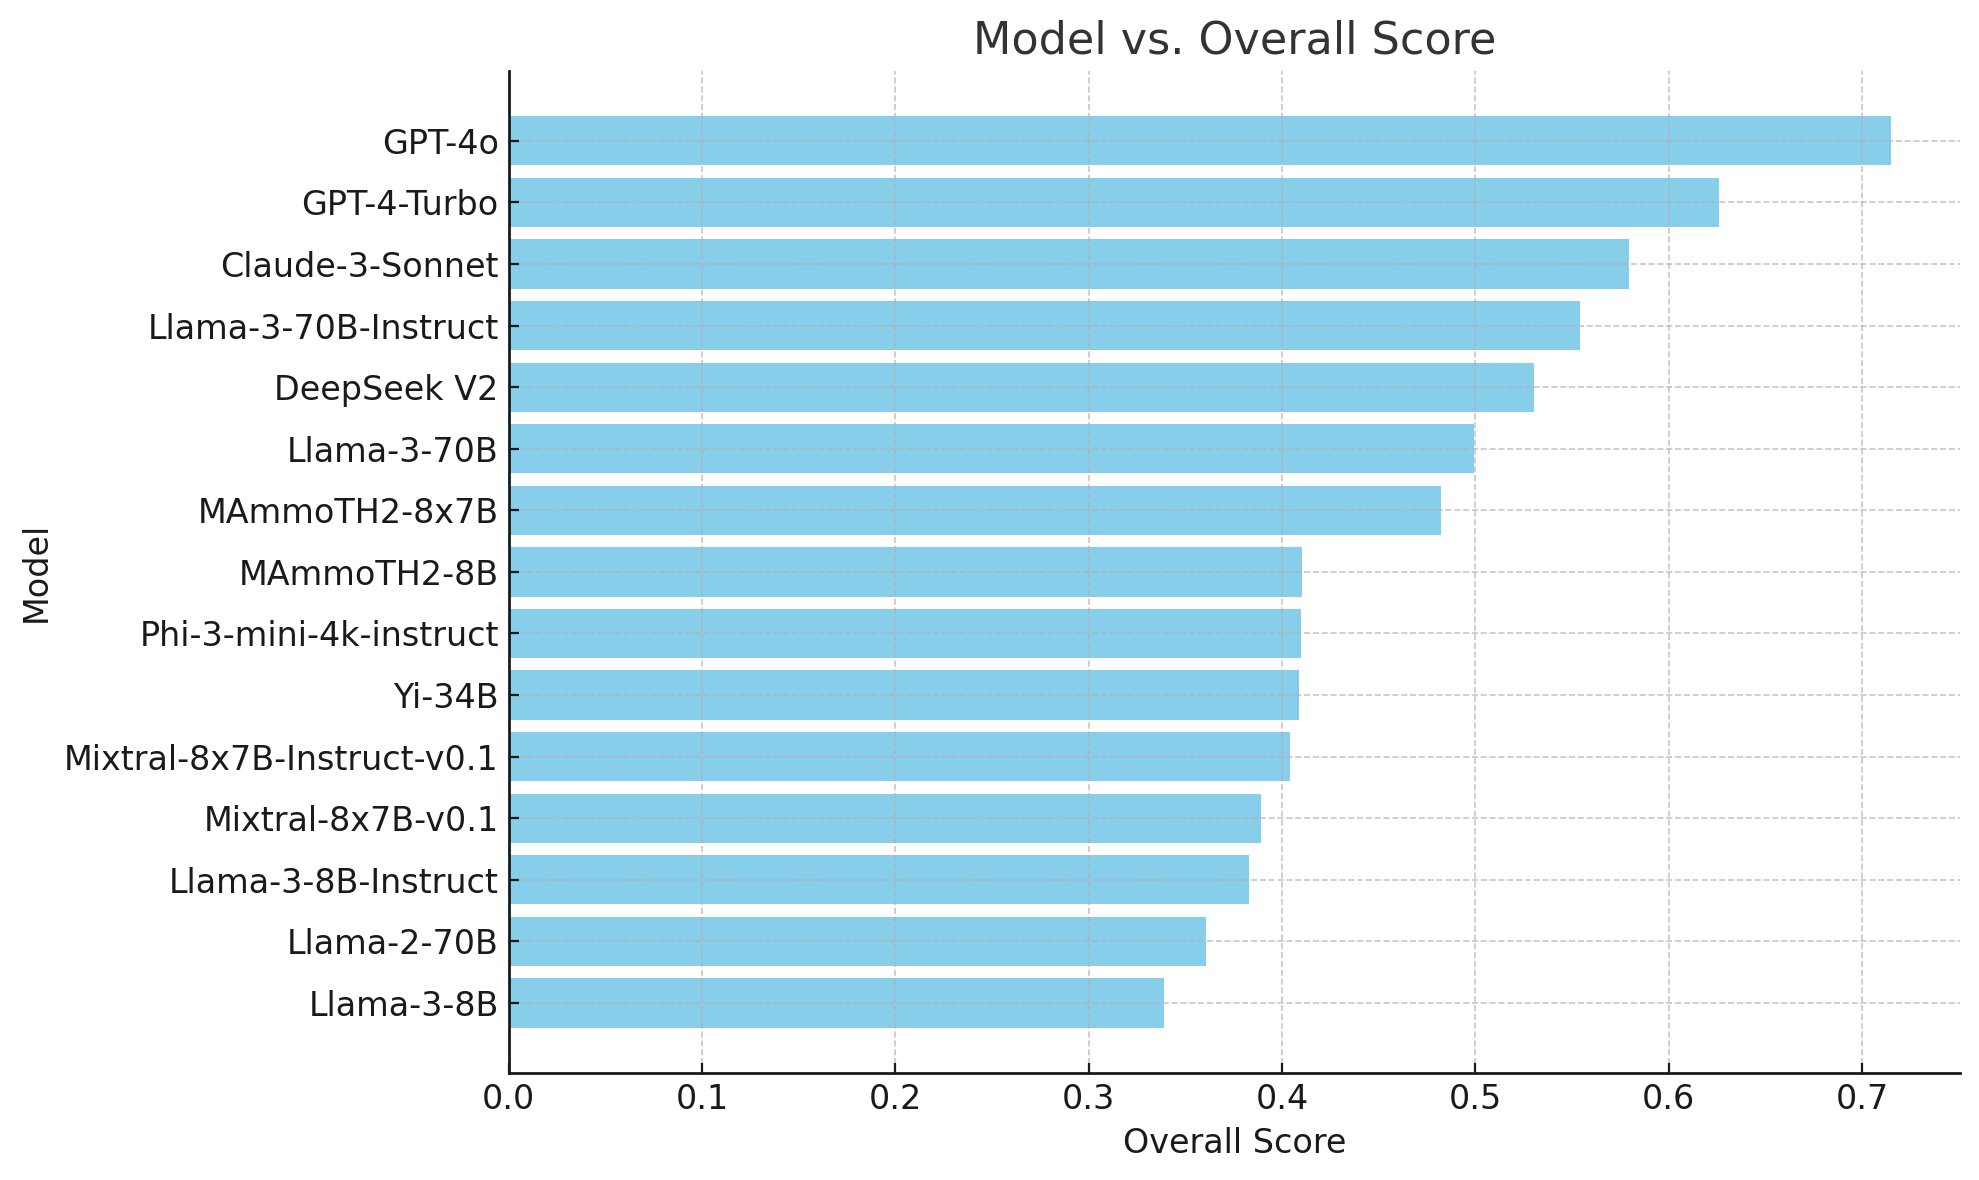
Improving AI Benchmarks: TIGER-Lab’s Enhanced MMLU Evaluation
By
–
We need to improve our benchmarks the same way we improve our models. Super interesting work from TIGER-Lab with an upgraded version of MMLU with 12k complex questions (vs. 16k for MMLU) and additional reasoning problems. – It is more discriminative among frontier models (see