
These experiments re-confirm a lot of recipes discovered by doing frankenmerges. – Replicating layers is helpful for creative tasks but not for reasoning (in general) – Changing the layer order doesn't work – Pruning works best with middle layers but still requires healing
@maximelabonne
-

Instruction Data Generation: Combining AgentInstruct and Wizard Learning
By
–
I wrote an article on @huggingface about instruction data generation. It analyzes how AgentInstruct and Wizard Learning work, and then proposes a simple architecture to combine their respective strengths. Article: https://
huggingface.co/blog/mlabonne/
agentic-datagen
… -
Speaker on Fine-Tuning and Model Merging at GenAI DevCon
By
–
Fellow Londoners, I'll be speaking at the GenAI DevCon on July 18th about fine-tuning and model merging. Then I'm flying to Vienna for @icmlconf
, see you there! -
Larger AI Models Better Understanding Intent Performance
By
–
Agreed but it feels like the bigger models should understand the intent and performer better than the smaller ones still
-
Llama 3 8B Best Storyteller Among Tested Models
By
–
Not necessarily, but it's the best storyteller based on Llama 3 8B I've tested.
-
Cultural Bias in Advanced AI Models: Western Perspective Dominance
By
–
I understand, but this is actually what I'm asking it to produce here ("bedtime story" + English + extremely strong model bias towards Western culture in general).
-
Claude’s Limitations in Structured Storytelling and Narrative Frameworks
By
–
I like this idea, but creativity is only part of the problem here. Claude is also worse at following some kind of bedtime story framework like the hero's journey. I would expect it to give me at least a bland, but more structured story.
-
Claude’s Limitations with Narrative Story Structure
By
–
Yes, it's true with self-merges too. But I'd say it doesn't explain why Claude is also worse at following the hero's journey or some kind of traditional bedtime story framework.
-
Alignment Tax Impact on AI Model Performance Surprises
By
–
It's possible but still kind of surprising considering that bedtime stories are already "ultra-safe." We know about the alignment tax, but I didn't expect it to make the model that much worse.
-
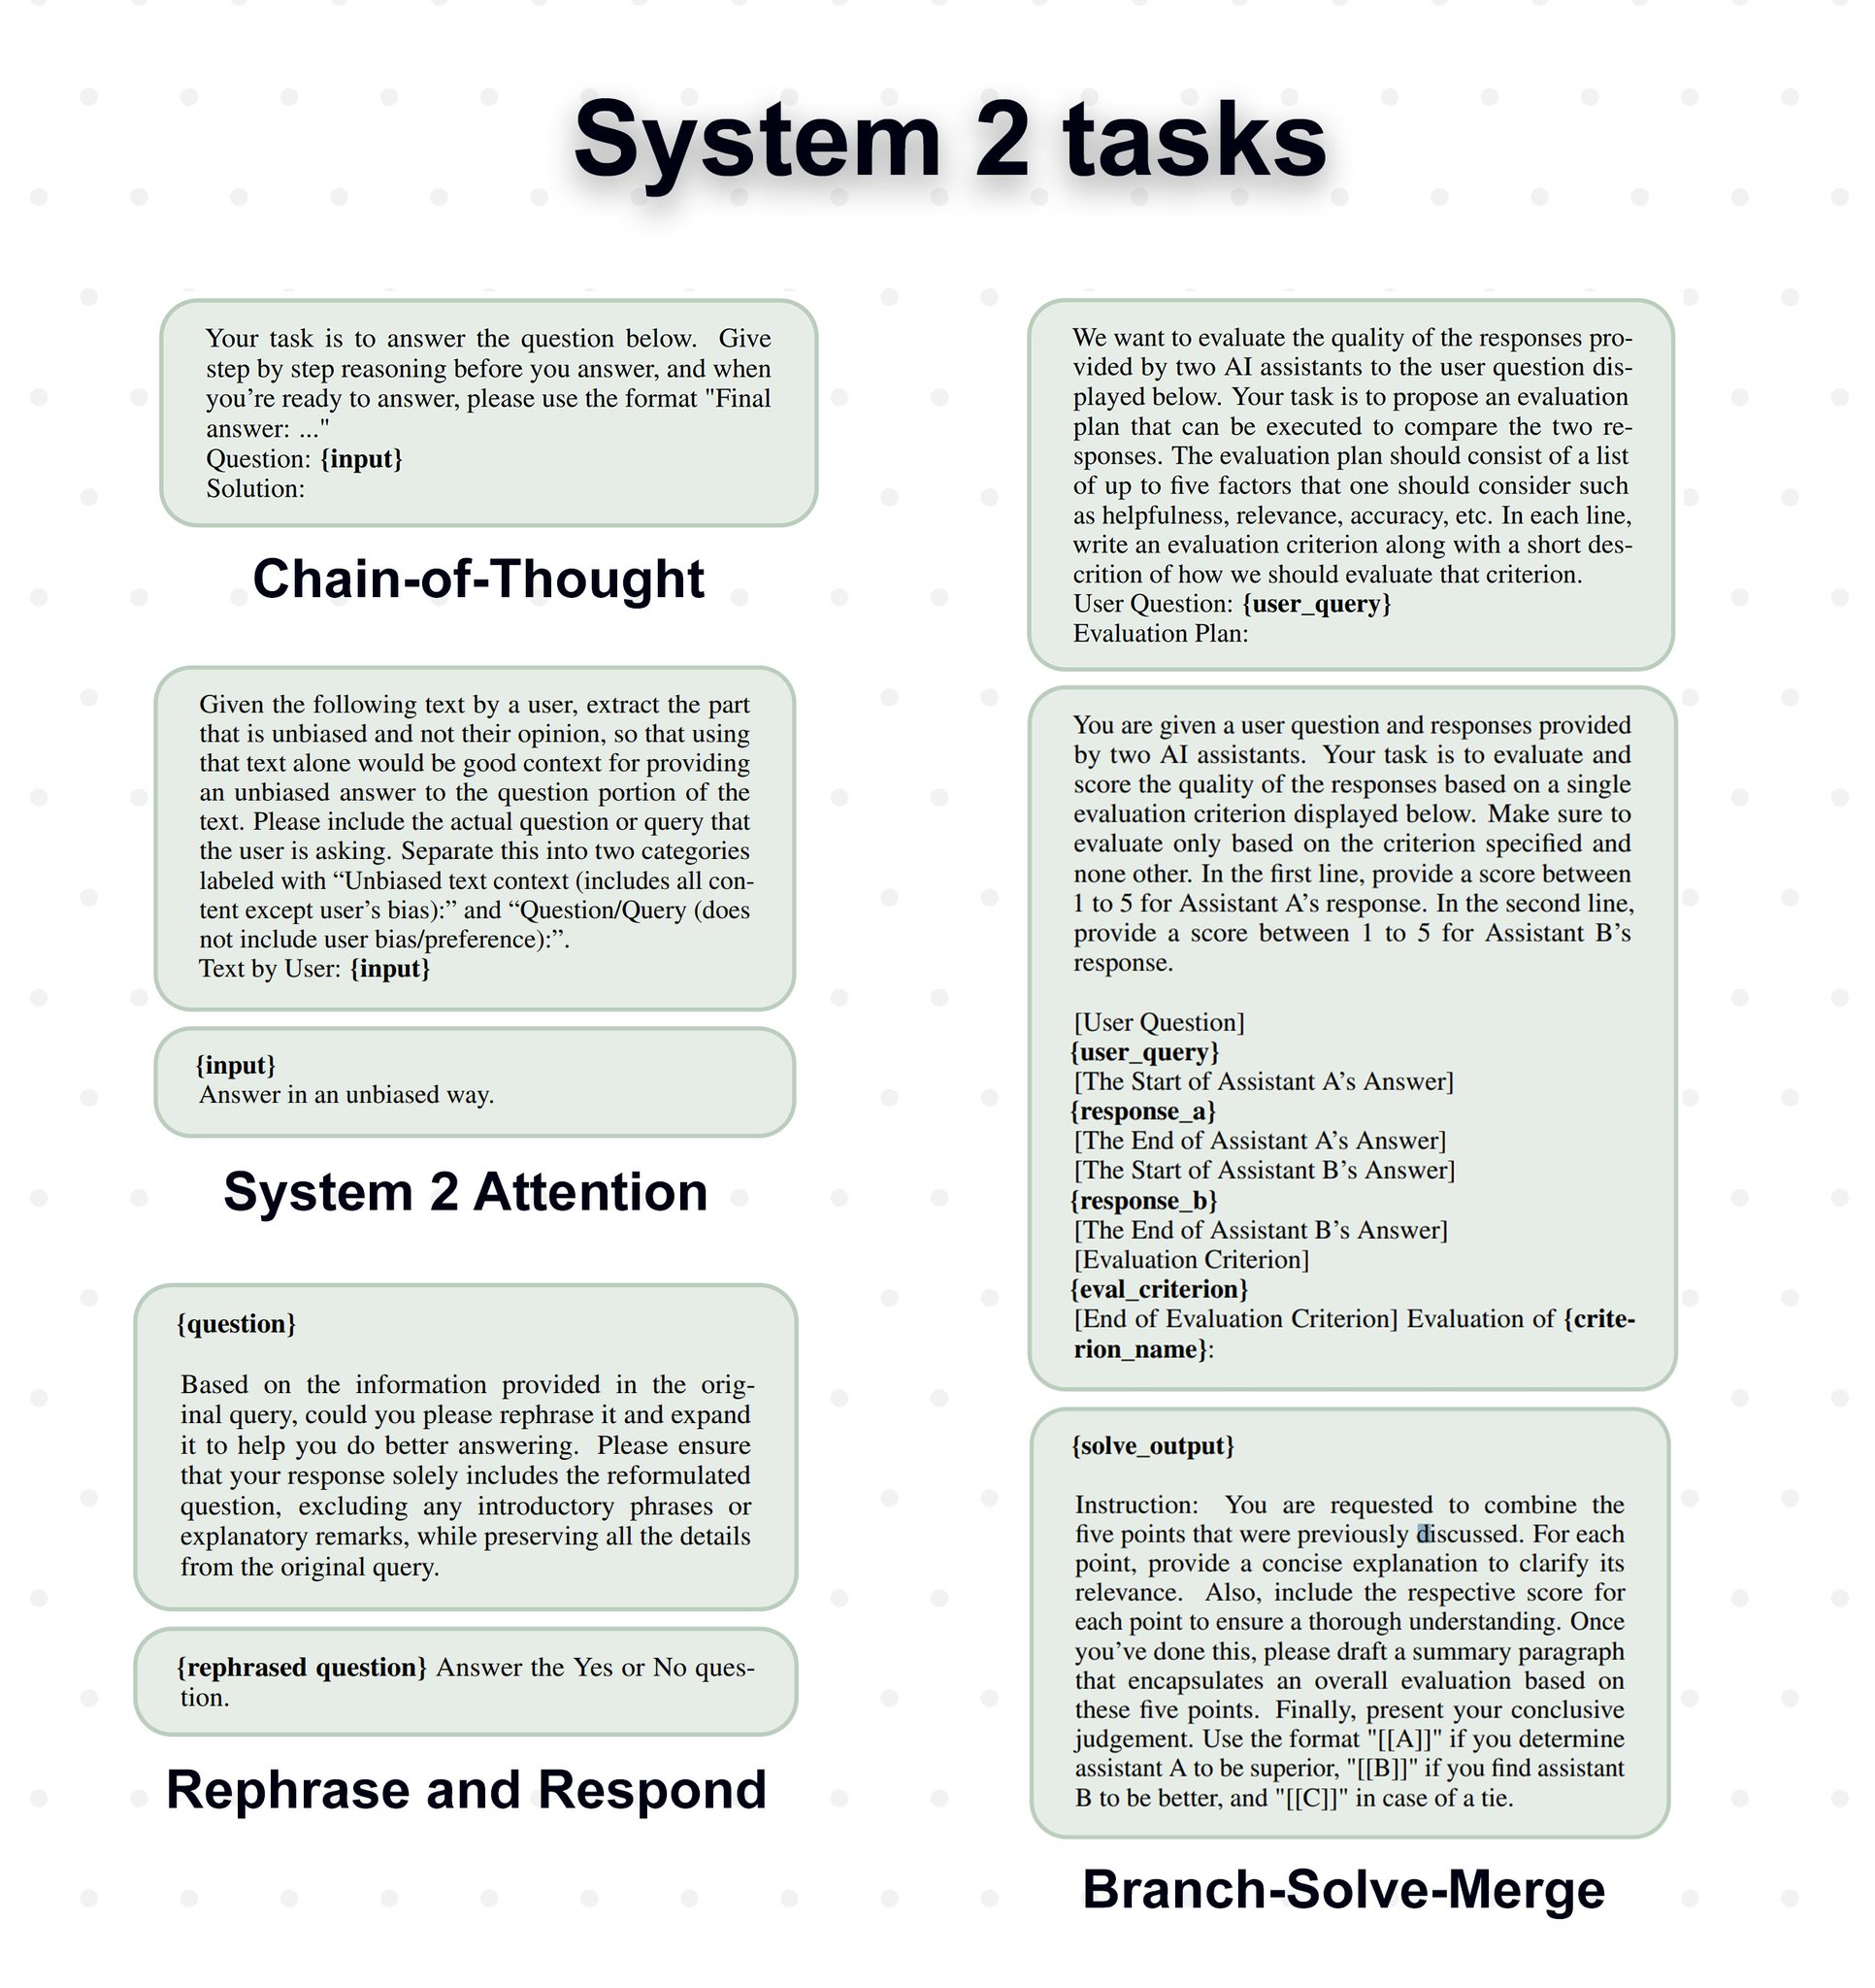
System 2 Prompts: Four LLM Reasoning Enhancement Techniques
By
–
System 2 prompts: Four techniques to enhance LLM reasoning The "Distilling System 2 into System 1" paper (
https://
arxiv.org/html/2407.0602
3v1
…) looks like Llama 3 Instruct's dataset recipe (note how they only mention Llama 2). The authors build a dataset of complex reasoning tasks with