Here's the BigCodeBench leaderboard with the raw data (elo_mle) and more details about how it's calculated https://
huggingface.co/spaces/bigcode
/bigcodebench-leaderboard
…
@maximelabonne
-
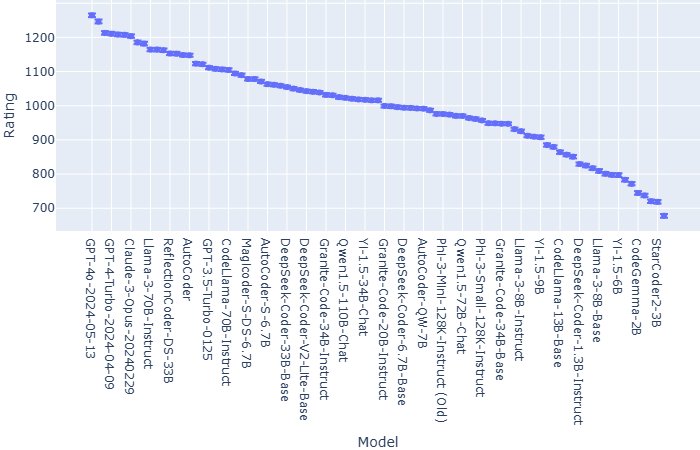
BigCodeBench Leaderboard: Code Model Performance Rankings
By
–
-
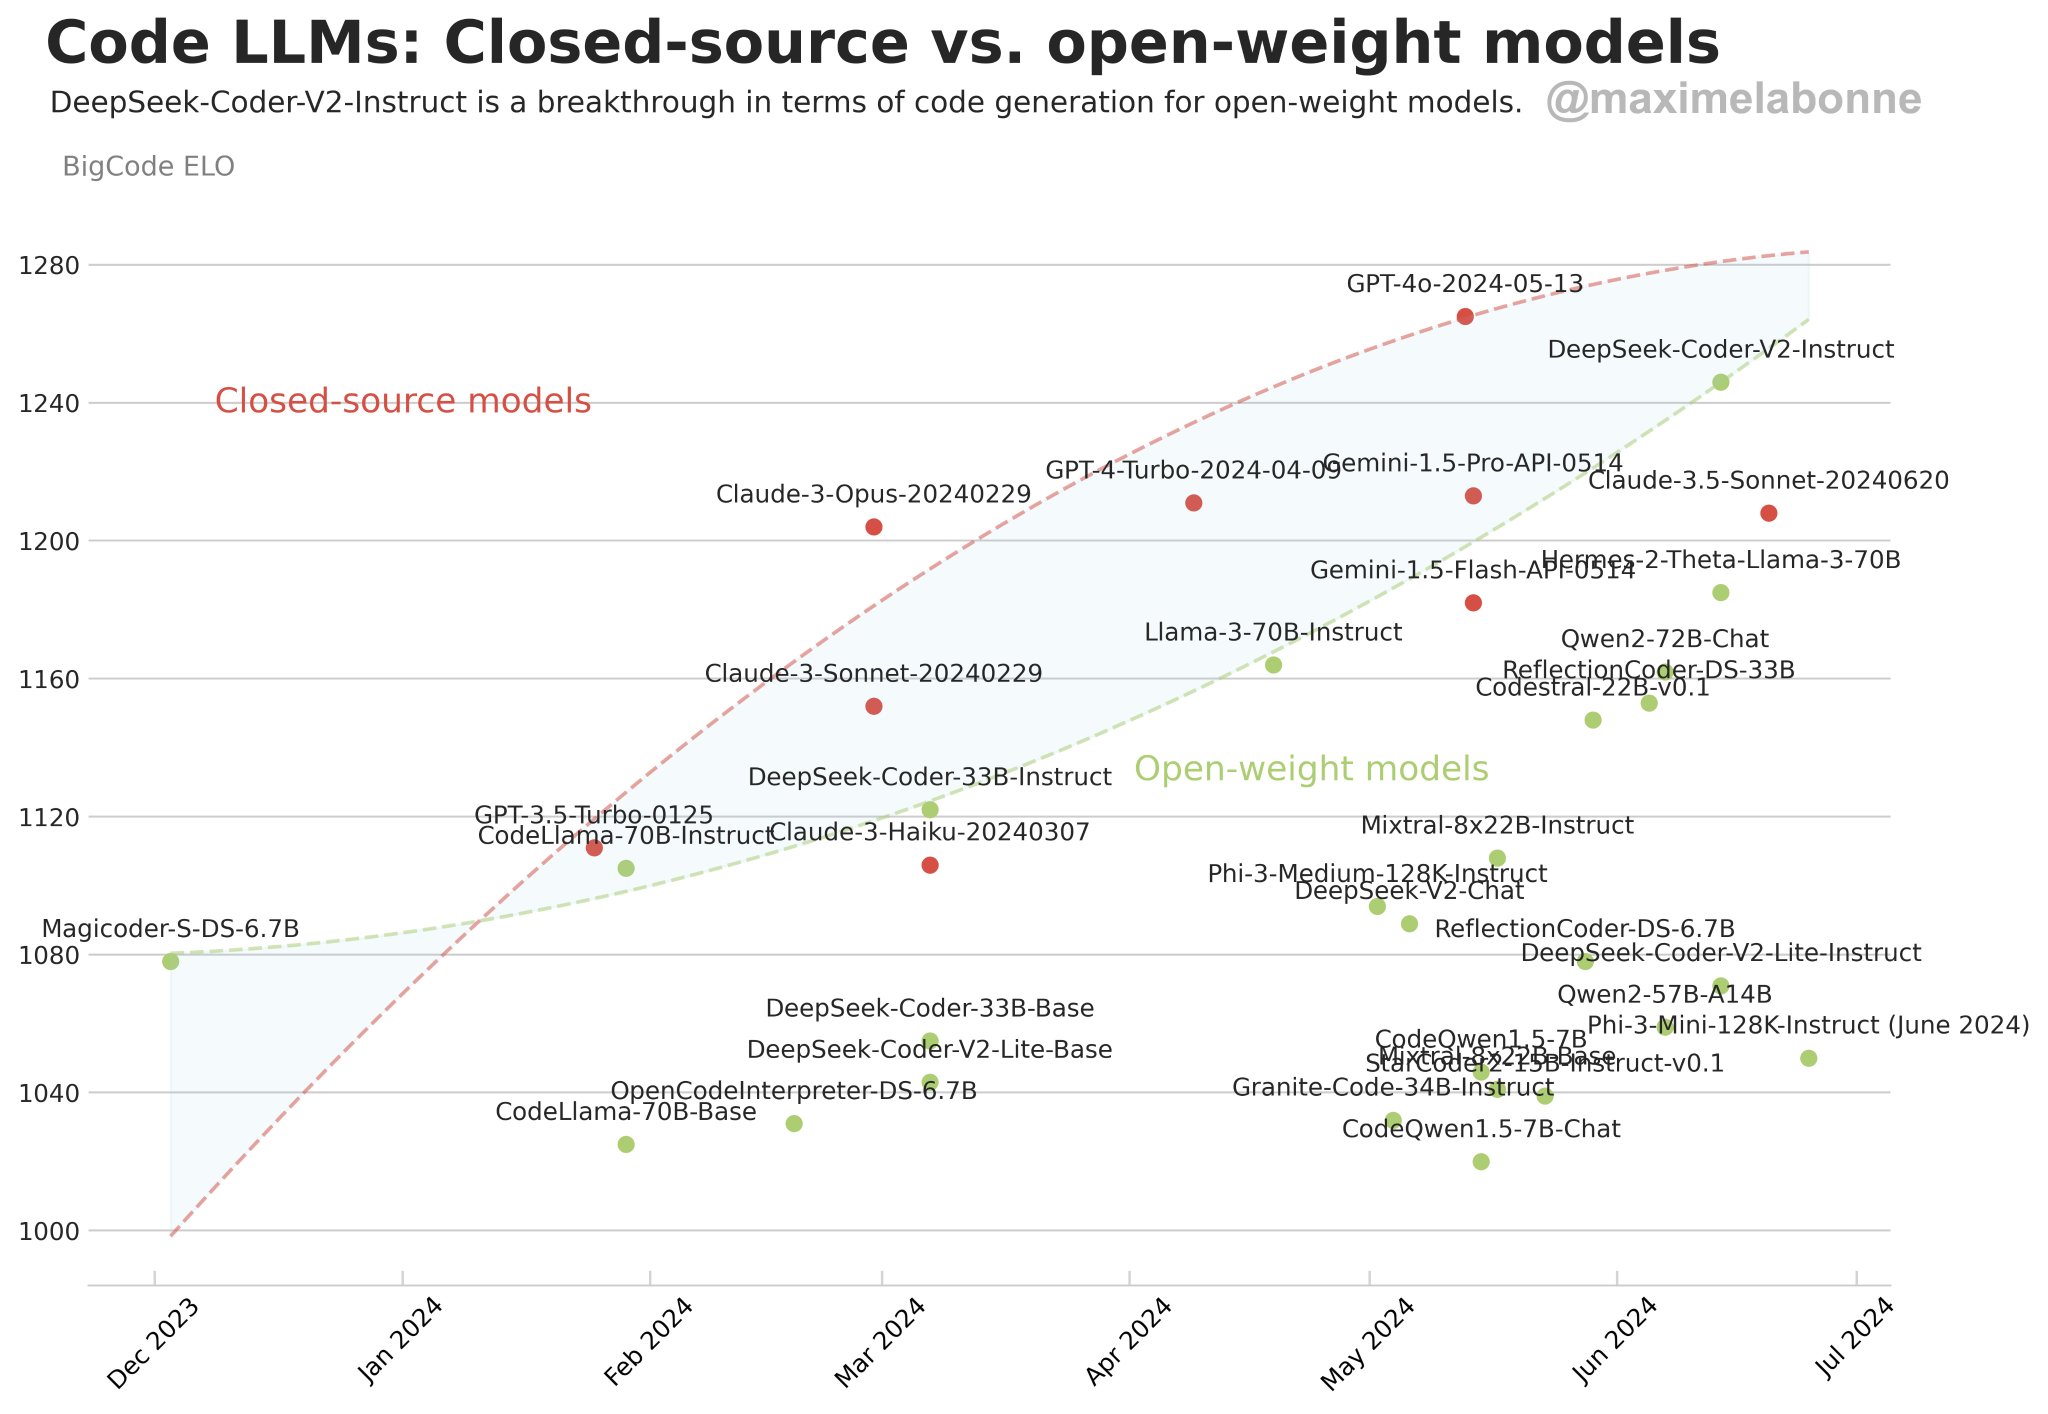
DeepSeek Coder V2 Matches Best Closed-Source Code Models
By
–
New chart with Code LLMs Based on the BigCodeBench Leaderboard, it shows the impressive performance of DeepSeek Coder V2 (236B, 21B active), which is on par with the best closed-source models. Personally, I've switched to Sonnet and I'm very happy with its code performance.
-
Code leaderboard: tracking development innovation
By
–
Not yet, but it'd be interesting to have something similar for code for example. Do you have a leaderboard in mind?
-
ICL versus Fine-tuning: Cost-Latency Trade-offs in LLM Optimization
By
–
I agree actually, if a problem can be solved with ICL (in terms of cost, latency, etc. and not just accuracy), then it's perfect. But I want to point out that it also makes fine-tuning even more relevant in a lot of use cases.
-
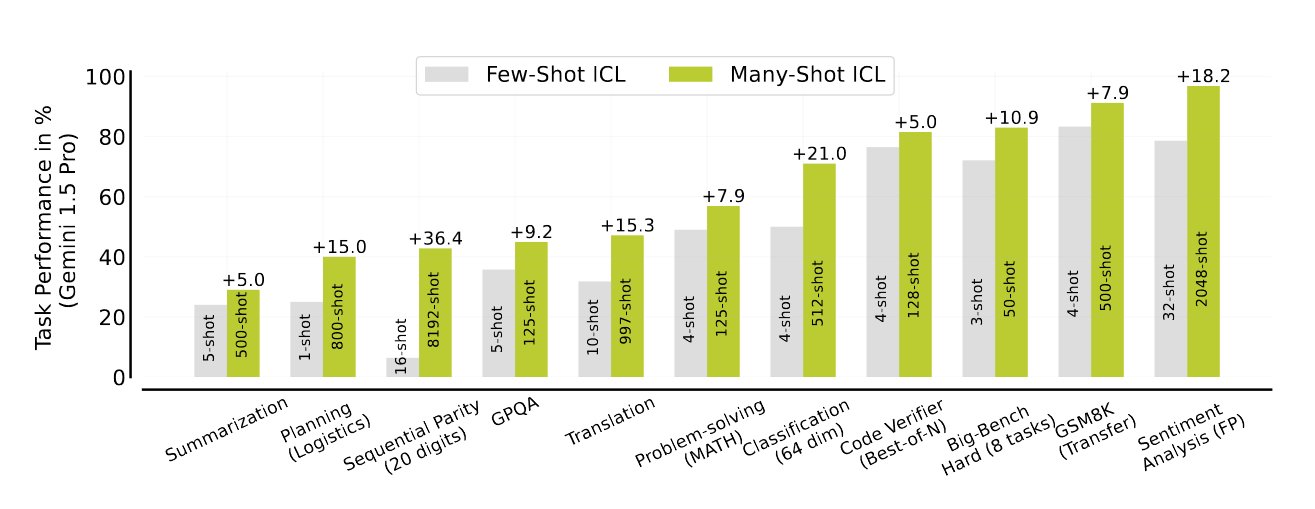
Prompt Engineering Gains Equivalent to Fine-Tuning Model Performance
By
–
I see many people rediscovering this paper and jumping to the wrong conclusions. Any gain in prompt engineering is a gain in terms of fine-tuning. A fine-tuned model will simply perform better with many-shot ICL.
-
HuggingFace Cache Storage Management Challenge
By
–
Haha yeah I regularly need to flush my HF cache before it eats up all my storage space
-
Structured Generation Techniques for AI Model Control
By
–
It looks like structured generation could do a lot of heavy lifting for you, have you tried it?
-
Mistral-based version reaches 747k monthly downloads
By
–
Meanwhile, the previous version based on Mistral gets 747k downloads/month and I have no idea why this is the case ¯_(ツ)_/¯
-
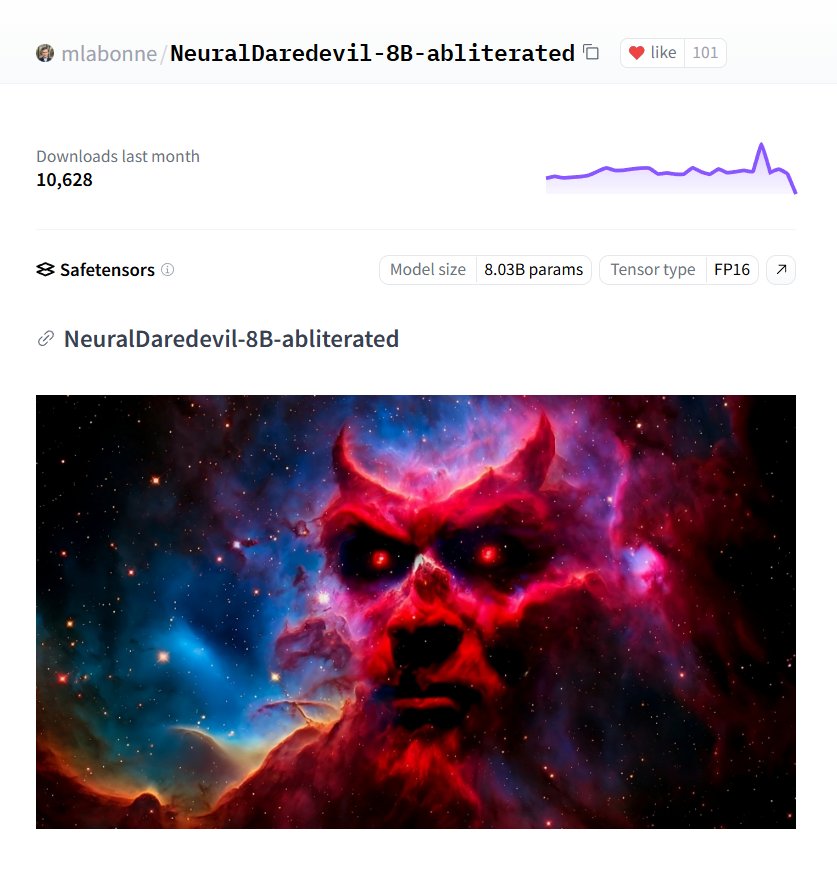
NeuralDaredevil Reaches 10k Monthly Downloads on Hugging Face
By
–
NeuralDaredevil reached 10k downloads/month and 100 likes on @huggingface Thanks everyone! It performs surprisingly well in many (unexpected) domains and languages, like math and Portuguese. It's also being re-evaluated on the Open LLM Leaderboard v2 due to an issue with IFEval
-

Alignment Lab Releases 600M Reddit Samples Dataset
By
–
Another insane drop from @alignment_lab
: 600M samples from top Reddit posts.