Lack of standardization in the benchmarks. To be fair, MMLU is not that bad compared to many other evals
@maximelabonne
-
Celebrating open-source contributions to AI development
By
–
Thanks for all your work @Thom_Wolf
, open-source was a good bet! 🙂 -

Closed-Source vs Open-Weight Models Comparison
By
–
I made the closed-source vs. open-weight models figure for this moment.
-
Offline vs Online Distillation: Implementation Discrepancy Analysis
By
–
It feels like they're talking about "offline" distillation here, but actually implemented online distillation as described in the paper
-
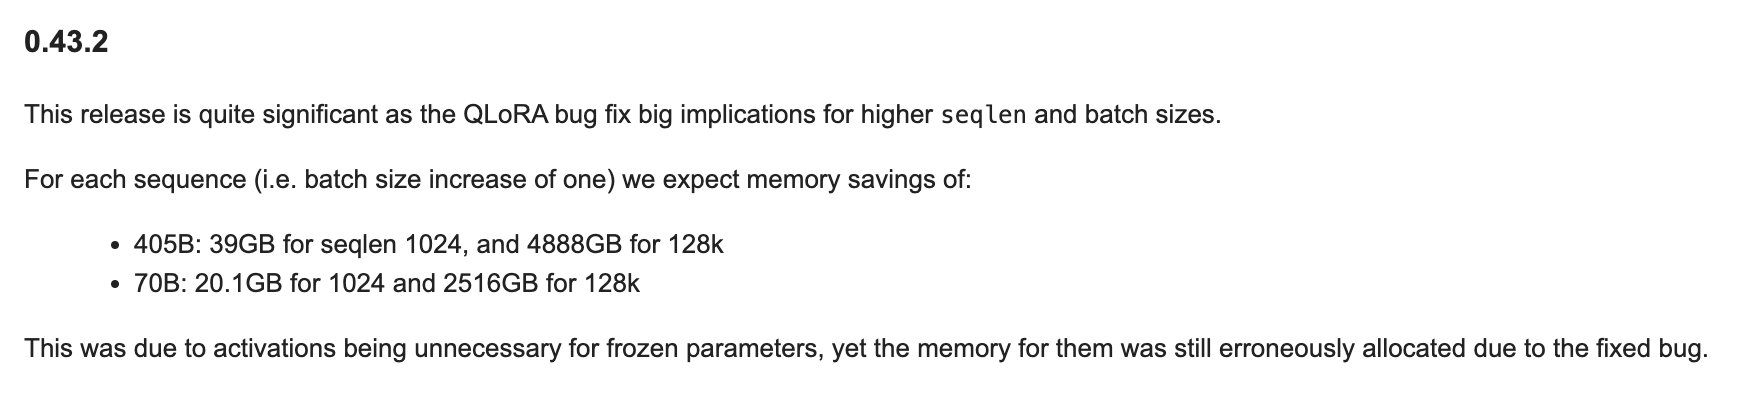
QLoRA Bug Consumes 4888GB VRAM in Llama 3 405B
By
–
One bug in bitsandbytes caused QLoRA to consume an extra *read notes* 4888 GB of VRAM. Even with QLoRA, fine-tuning Llama 3 405B on long sequence lengths ain't cheap.
-
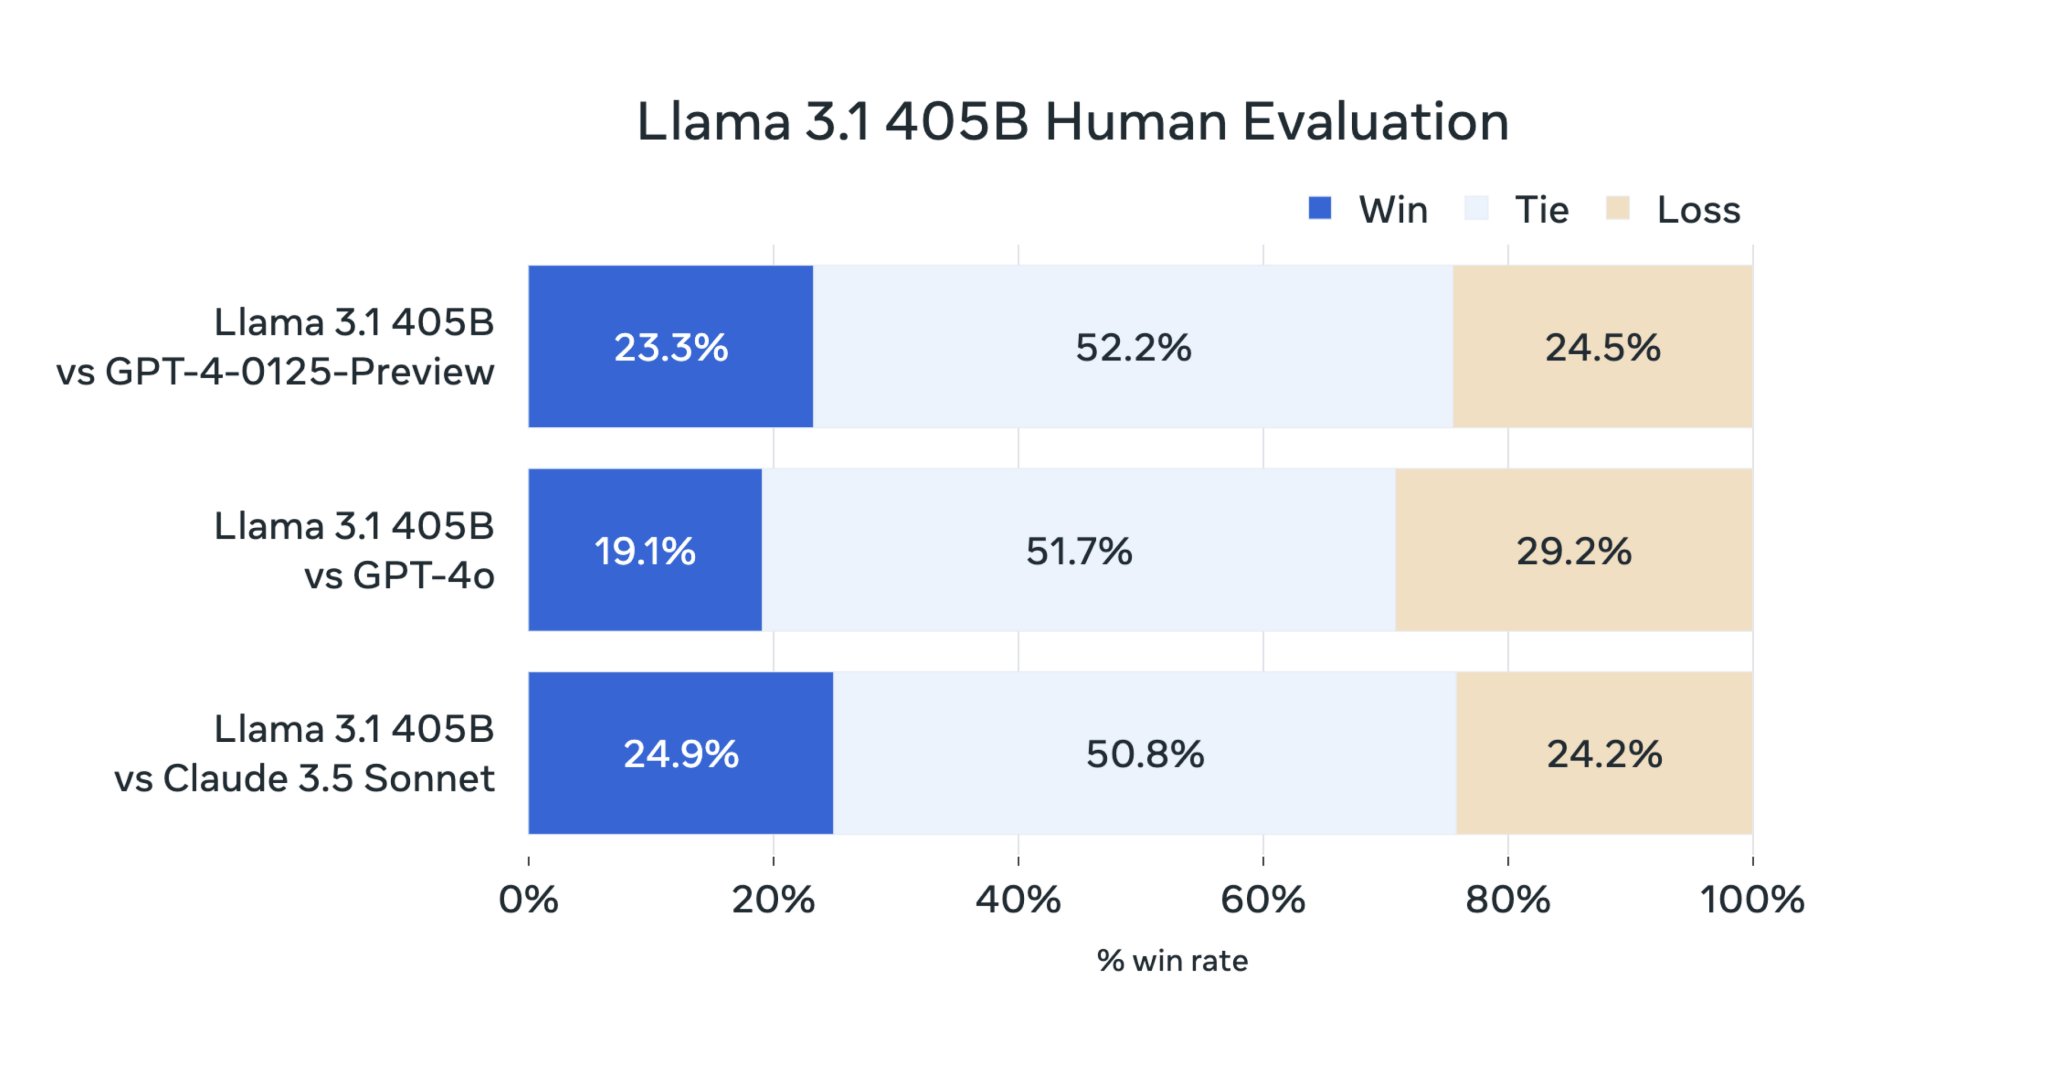
GPT-4o preferences and user adoption considerations
By
–
I guess it depends on how much you like GPT-4o
-
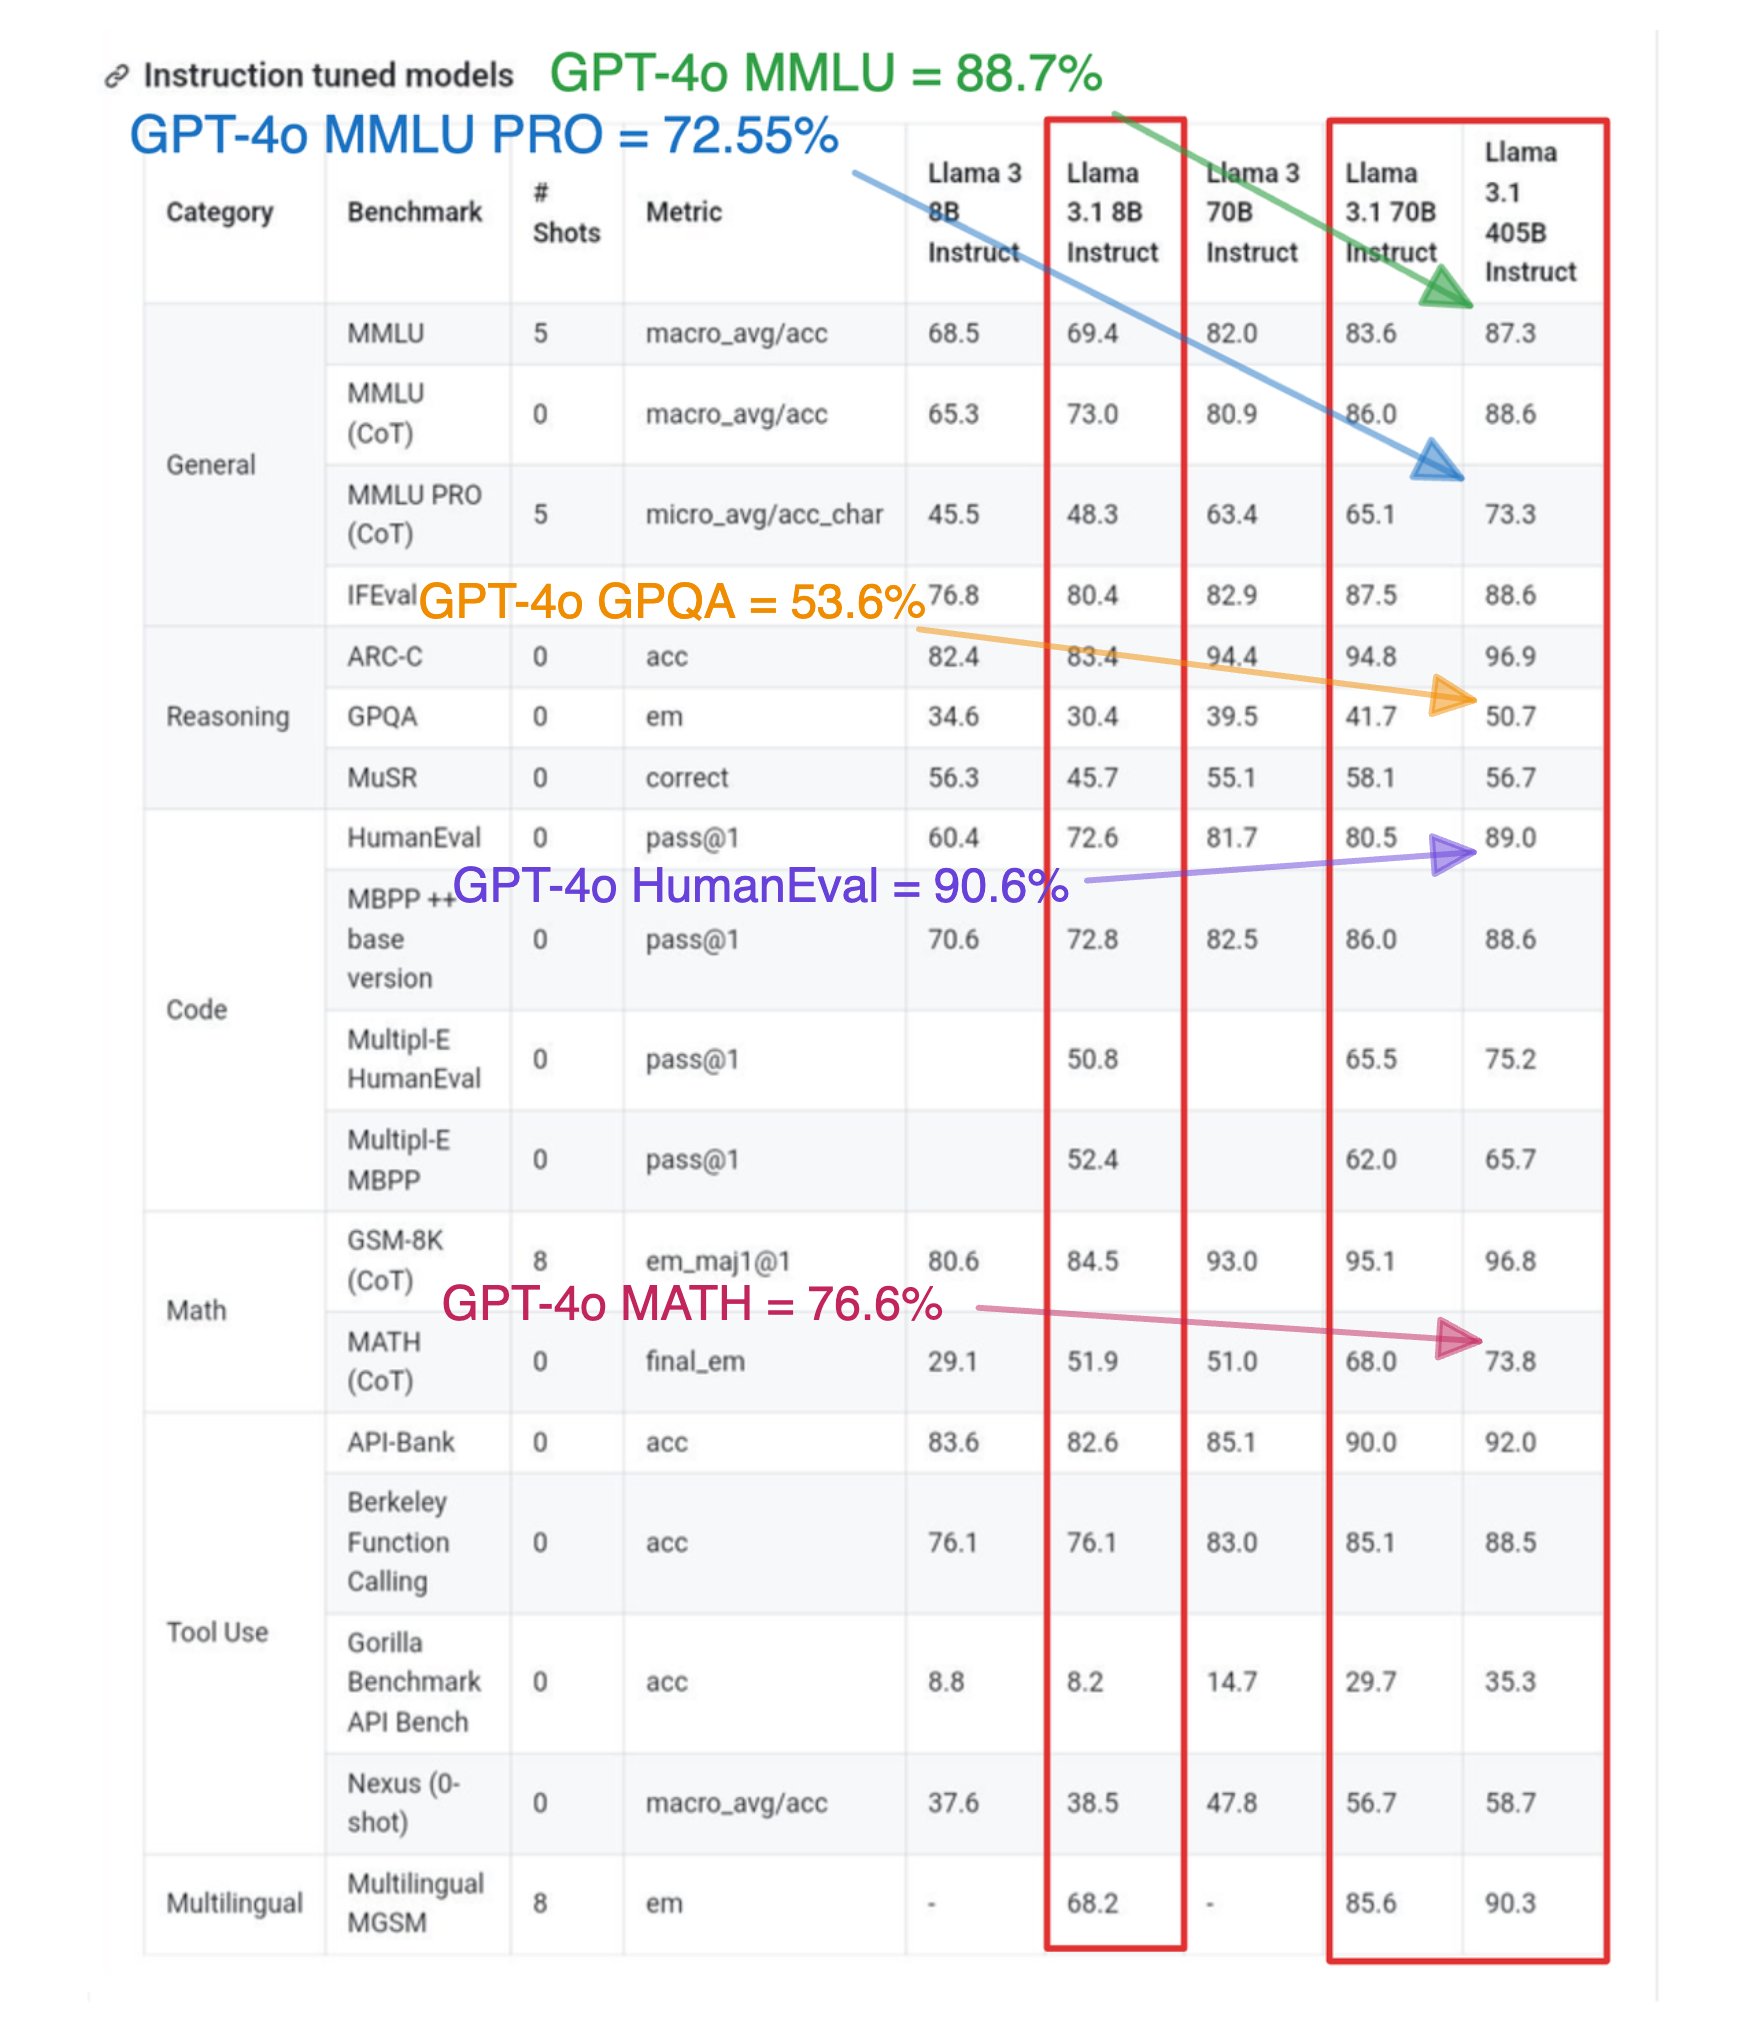
Open-Weight Models Achieve SOTA for First Time Ever
By
–
Small update: open-weight models are SOTA for the first time in history
-
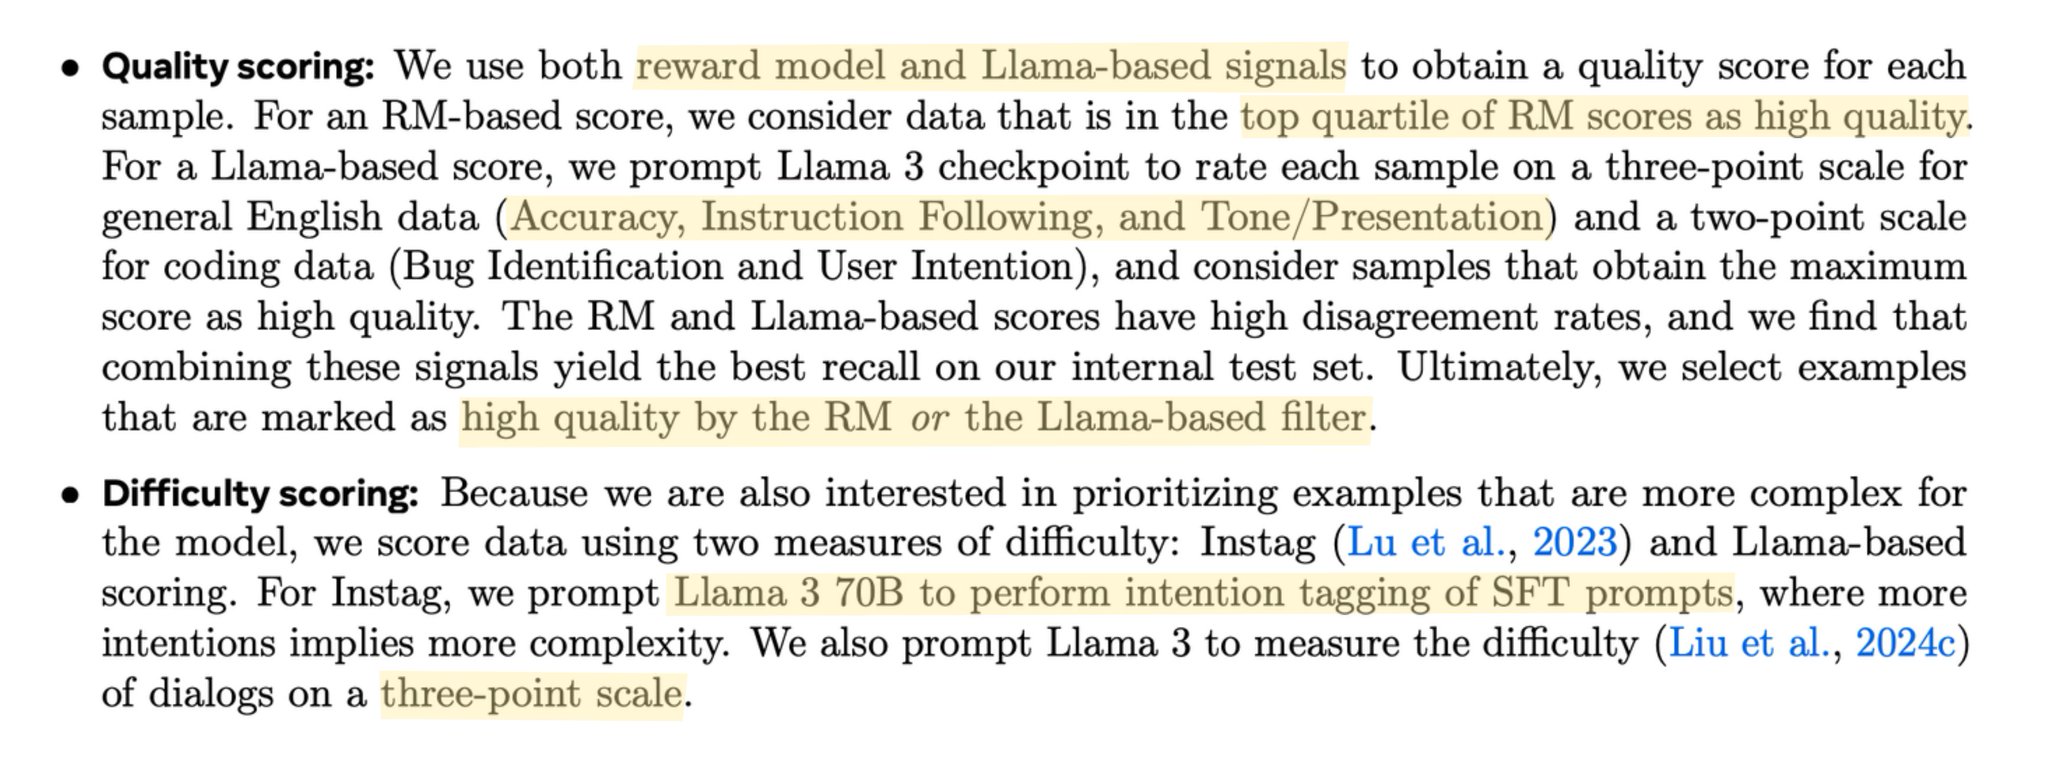
Llama 3 Instruction Filtering: Quality and Complexity Evaluation
By
–
Llama 3's paper is full of cool insights. Here's how they filtered out bad instruction samples. – Quality is evaluated by a reward model and an LLM-as-a-judge
– Complexity is a combination of Instag (
https://
arxiv.org/abs/2308.07074) and LLM-as-a-judge + It looks like models are merged