Thanks! I used ChatGPT with a lot of patience and prompting. I also gave up because of the new rate limits.
@maximelabonne
-
FineLlama-3.1-8B Model Deployment Issues on Hugging Face
By
–
I've also made a Hugging Face Space to chat with the FineLlama-3.1-8B model we build in the article.
— Maxime Labonne @ ICLR (@maximelabonne) 29 juillet 2024
The model looks good but the space tends to crash after one answer. I'm interested if you know how to fix it!
🤗 Space: https://t.co/6bDNLHShqh pic.twitter.com/PLjzajao0xI've also made a Hugging Face Space to chat with the FineLlama-3.1-8B model we build in the article. The model looks good but the space tends to crash after one answer. I'm interested if you know how to fix it! Space: https://
huggingface.co/spaces/mlabonn
e/FineLlama-3.1-8B
… -
FineTome-100k: High-Quality Filtered Dataset Release
By
–
I'm also releasing FineTome-100k, a refiltered subset of arcee-ai/The-Tome using fineweb-edu-classifier. It's super high-quality data, perfect when you need extra samples to concatenate with a dataset. FineTome: https://
huggingface.co/datasets/mlabo
nne/FineTome-100k
… -
Fine-tune Llama 3.1 Ultra-Efficiently with Unsloth
By
–
Fine-tune Llama 3.1 Ultra-Efficiently with @UnslothAI New comprehensive guide about supervised fine-tuning on @huggingface
. Over the last year, I've done a lot of fine-tuning and blogging. This guide brings it all together. Article: https://
huggingface.co/blog/mlabonne/
sft-llama3
… -
Model Quantization Commands and Optimization Techniques
By
–
Thanks @bartowski1182
! Is it possible for you to provide the commands you used to quantize the models? I can't keep up with this pace -
Correctness as a Gradient: Backpropagation Approach
By
–
Correctness is a gradient and I want to backprop it
-

Llama 3.1 Uses Synthetic Data Not Distillation Says Expert
By
–
Many people say that Llama 3.1 is distilled, but this is incorrect: it's just synthetic data. Here's a plot from kindacognizant (
https://
reddit.com/r/LocalLLaMA/c
omments/1ed58iu/llama31_models_are_fake_distillations_this_should/
…) showing the difference in probability distributions. Yeah, it's NOT EVEN distilled. Still more performance to tap into. -
FLAN Model Limitations in Modern LLM Evaluation
By
–
I don't think we can draw any conclusion about modern LLMs since it was made with FLAN
-
1T AI Model Upscaled: Technical Report Released
By
–
Yes, I'm planning to play with it a little 🙂 I've shared the 1T model that was upscaled yesterday, the technical report is an interesting read, I recommend it
-
Interactive LLM Decoding Strategies and Sampling Effects
By
–
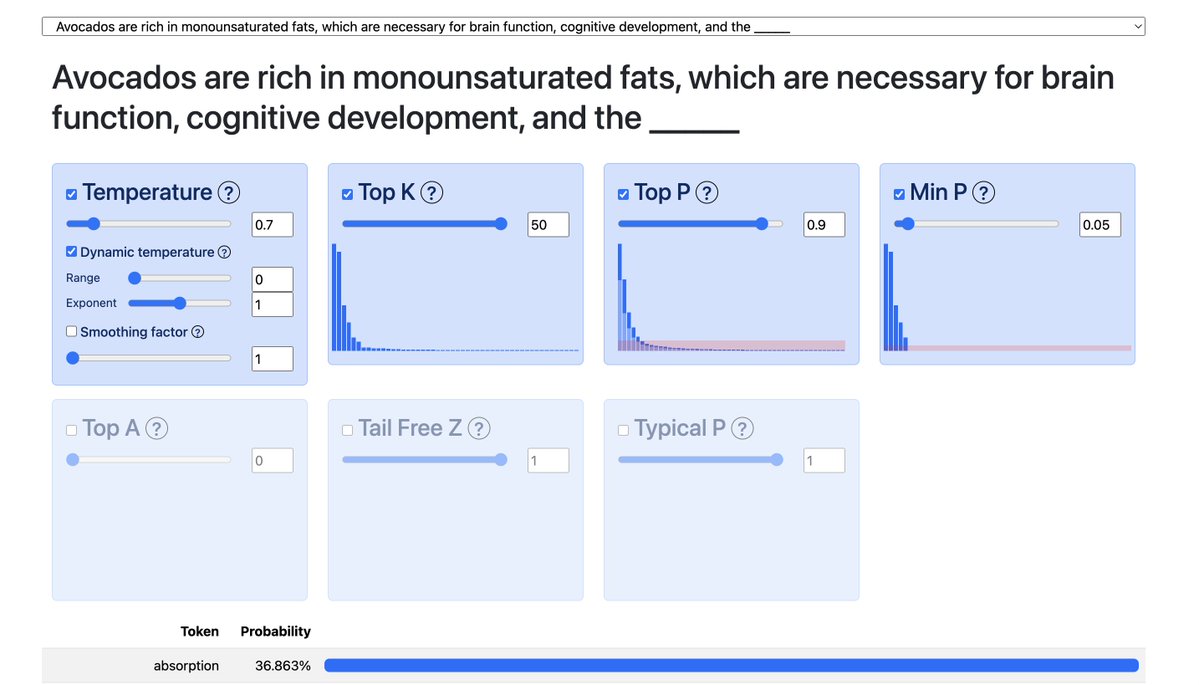
Interactive LLM decoding strategies LLM sampling is a cool app that shows the effect of temperature, top K sampling, top P sampling, etc. on the probability distribution outputted by an LLM. LLM sampling: https://
artefact2.github.io/llm-sampling/i
ndex.xhtml
…