Anyway, have fun quantizing and running this monster! This is a silly experiment but who knows, we might: 1/ Realize it's good at something, like creative writing
2/ Get some insights into how to create these self-merges Good luck everyone and make your own frankenmerges
@maximelabonne
-
Experimenting with Model Merging and Quantization Techniques
By
–
-
BigLlama-3.1-681B-Instruct: New Intermediate Checkpoint Released
By
–
Because 1T parameters might be a bit too much, I'm also releasing an "intermediate checkpoint": BigLlama-3.1-681B-Instruct. It's closer to what Llama 3 120B was to the 70B, so it might be more coherent as well. Model: https://
huggingface.co/mlabonne/BigLl
ama-3.1-681B-Instruct
… -
Code Configuration Generation Experiment With Storage Cost
By
–
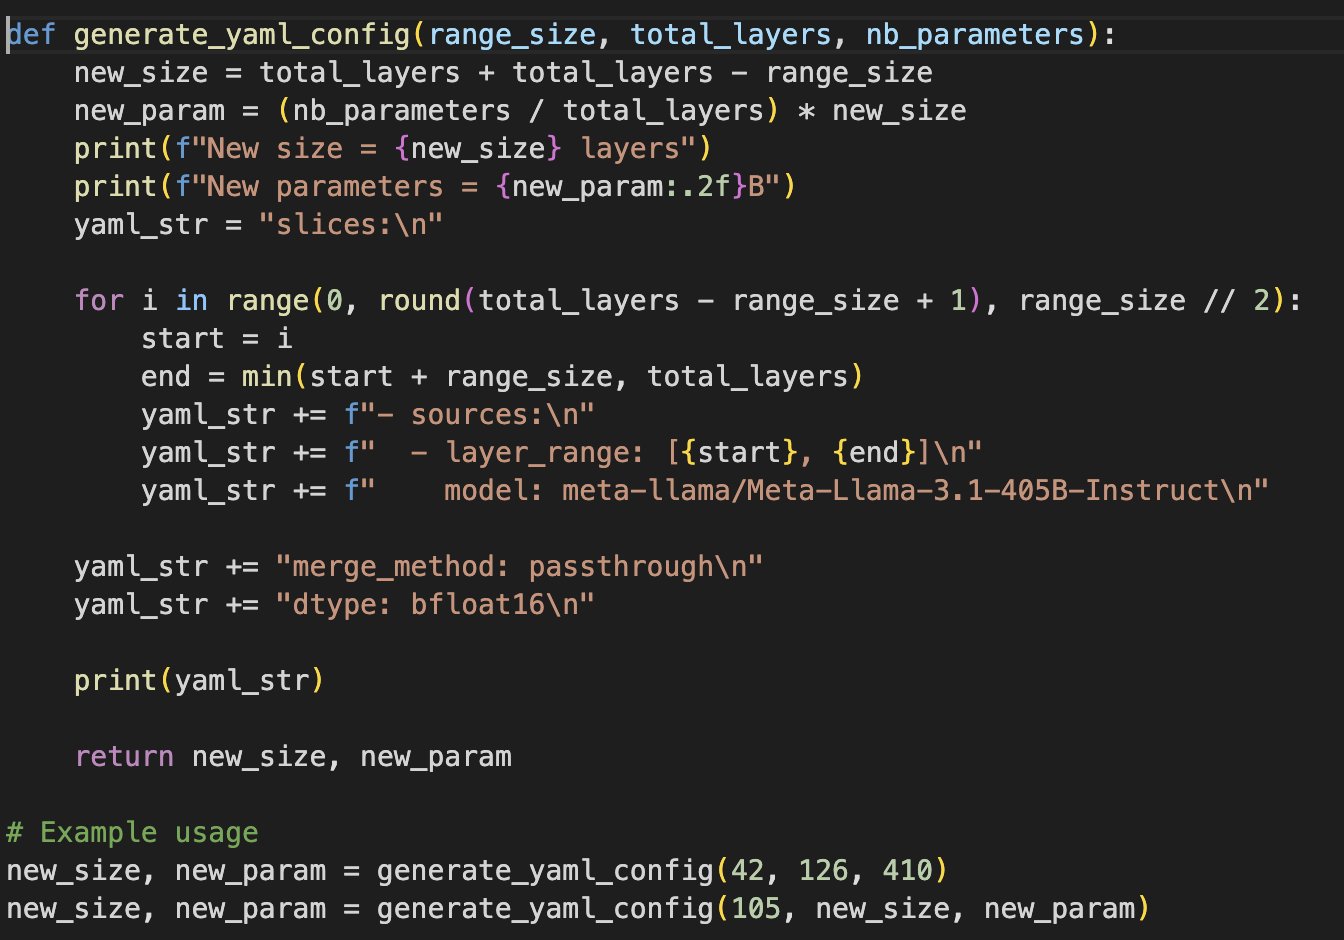
Here's the code I've used to generate the configuration. It's pretty nice, it allows you to experiment with different overlaps. Also get mentally ready for the storage bill.
-
BigLlama-3.1 reaches 1 trillion parameters milestone
By
–
BigLlama-3.1-1T-Instruct So I've heard that 405B parameters weren't enough… It's my pleasure to present an upscaled Llama 3.1 with 1,000,000,000 parameters. Now available on @huggingface
. Model: https://
huggingface.co/mlabonne/BigLl
ama-3.1-1T-Instruct
… -
LoRA Adapter Refusal Vector Calculation Technique
By
–
I didn't calculate the refusal vector, this is a LoRA adapter
-
Llama 3.1 Compatibility and Overlap with Previous Version
By
–
Yes, there seems to be a large overlap. Llama 3.1 is based on 3.0, so it's not too crazy but it's nice it works without requiring any tweaking
-
Llama 3.1 70B Recipe Adapted with LoRA Optimization
By
–
I adapted this recipe to Llama 3.1 70B using @failspy
's Meta-Llama-3-70B-Instruct-abliterated-v3.5 and optimized the LoRA rank. GGUF quants are ready and there shouldn't be any issue with the tokenizer. Special thanks to him and to grimjim for the model and this technique. -
Lorablation: Two-Step LoRA Extraction for Model Abliteration
By
–
Lorablation is a simple two-step process: 1/ Extract a LoRA by comparing two models: a censored and an abliterated Llama 3.0 2/ Merge the LoRA with a censored Llama 3.1 to abliterate it It means that we directly applied a Llama 3 LoRA to a 3.1 model and it just works!
-
Uncensored Llama 3.1 70B Instruct Model Released
By
–
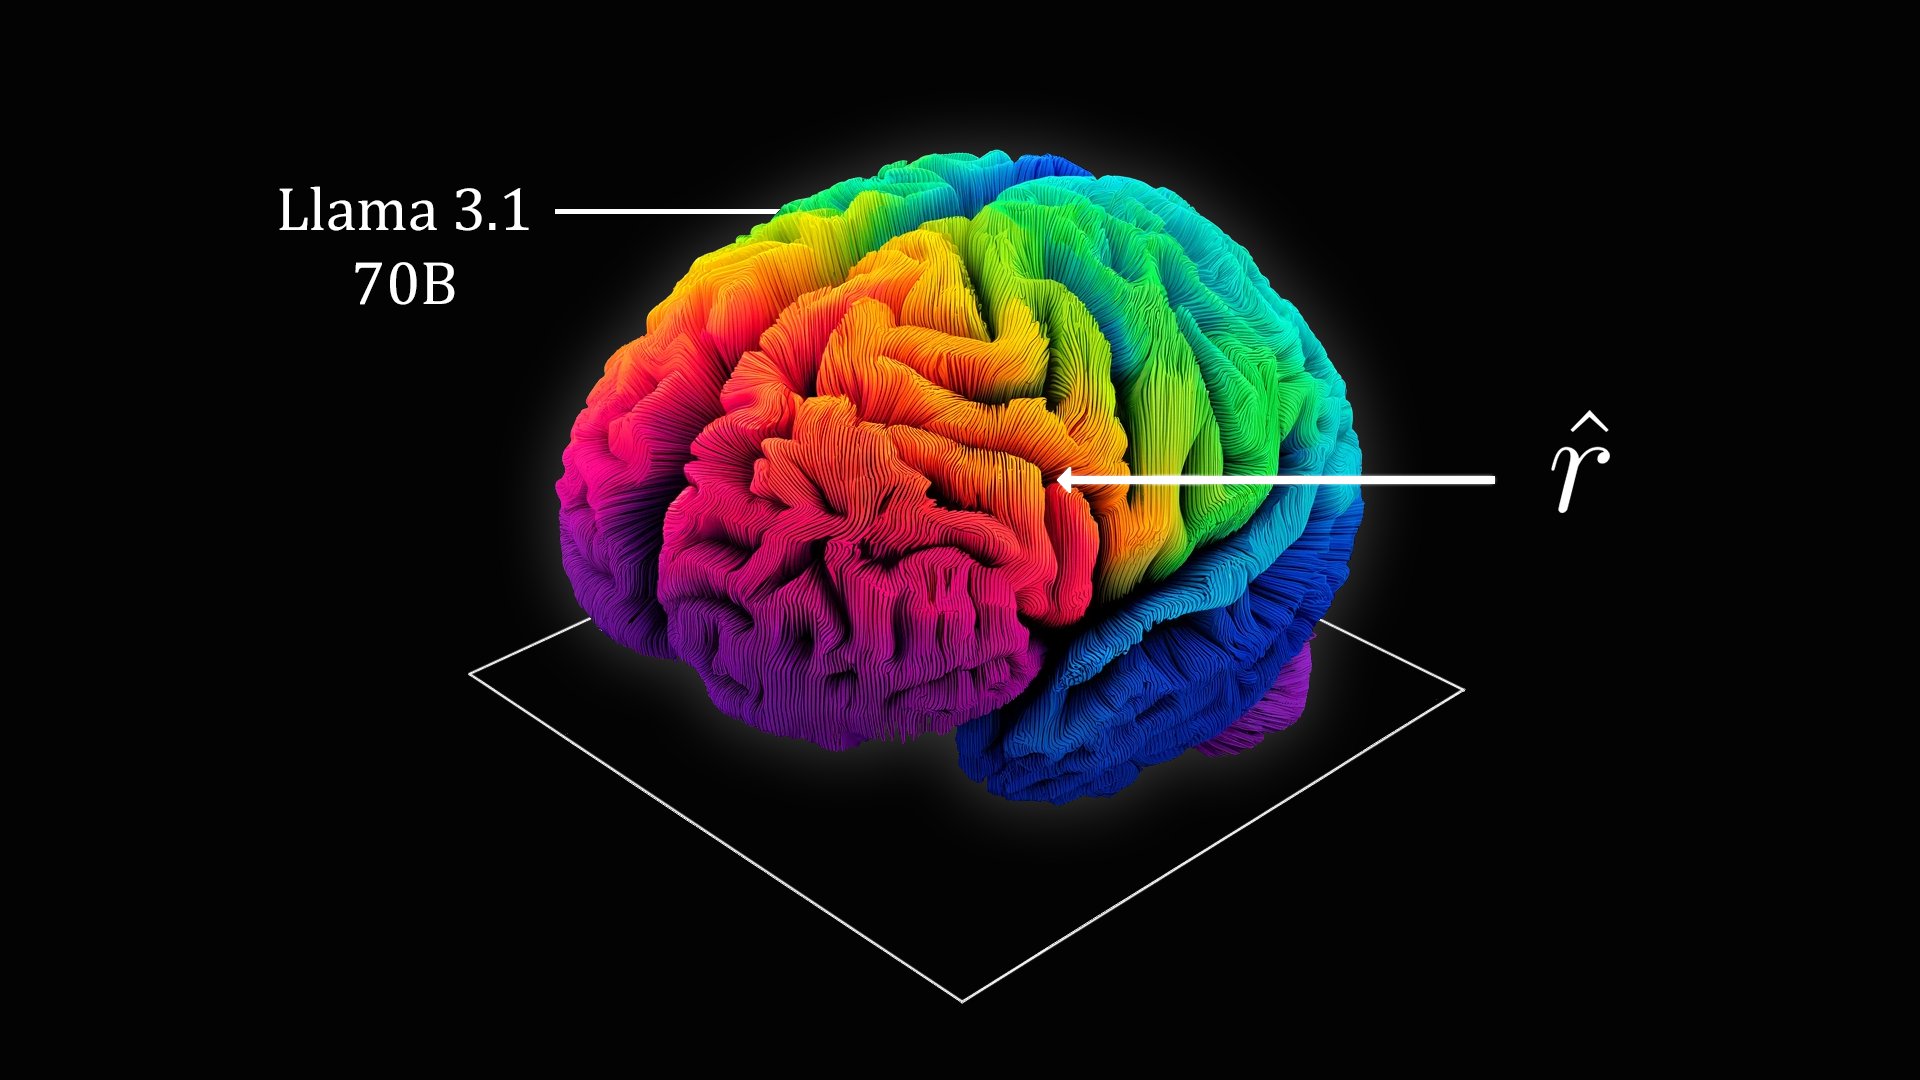
Llama 3.1 70B Instruct lorablated It's an uncensored Llama 3.1 70B Instruct using grimjim's recipe of LoRA + abliteration (lorablation). The model is fully uncensored in my tests and maintains a high level of quality. Model: https://
huggingface.co/mlabonne/Llama
-3.1-70B-Instruct-lorablated
… -

AutoQuant: Colab Tool for Model Quantization and Distribution
By
–
AutoQuant is a simple Colab notebook to make your own quants It supports GGUF, GPTQ, EXL2, AWQ, and HQQ quants. With GGUF, you can enter a list of precisions. It will conveniently quantize and push them one by one to HF. I just updated my abliterated Llama 3.1 8B using it.