Yes it'd be interesting to see the 8B model in 8-bit precision vs. the 4B model in BF16.
@maximelabonne
-
Phi-2 vs Phi-3: Model Comparison and Benchmark Relevance
By
–
I think they just want to compare it to the 4B model. But I agree, phi-2 isn't the best comparison point. It's funny it's still regularly used in benchmarks despite the release of phi-3.
-
Hype Cycles as Market Filters in AI Industry
By
–
These stupid hype cycles are at least a good filter
-
Distillation Unlocks New Applications for Model Optimization
By
–
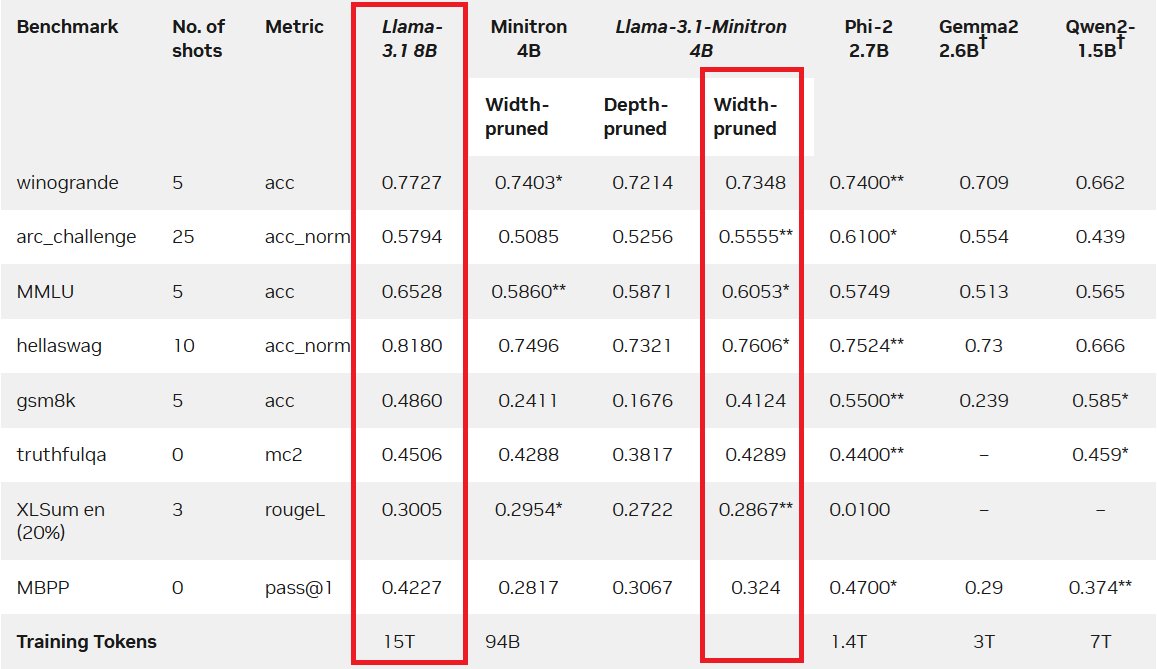
Okay, distillation is broken. Nvidia's width pruning + distillation shows just how effective distillation is for healing networks. This is unlocking a ton of applications: better quantization, model merging, abliteration, etc. We might finally see some real model editing.
-
LLM Datasets Project Reaches 1000 Stars Milestone
By
–
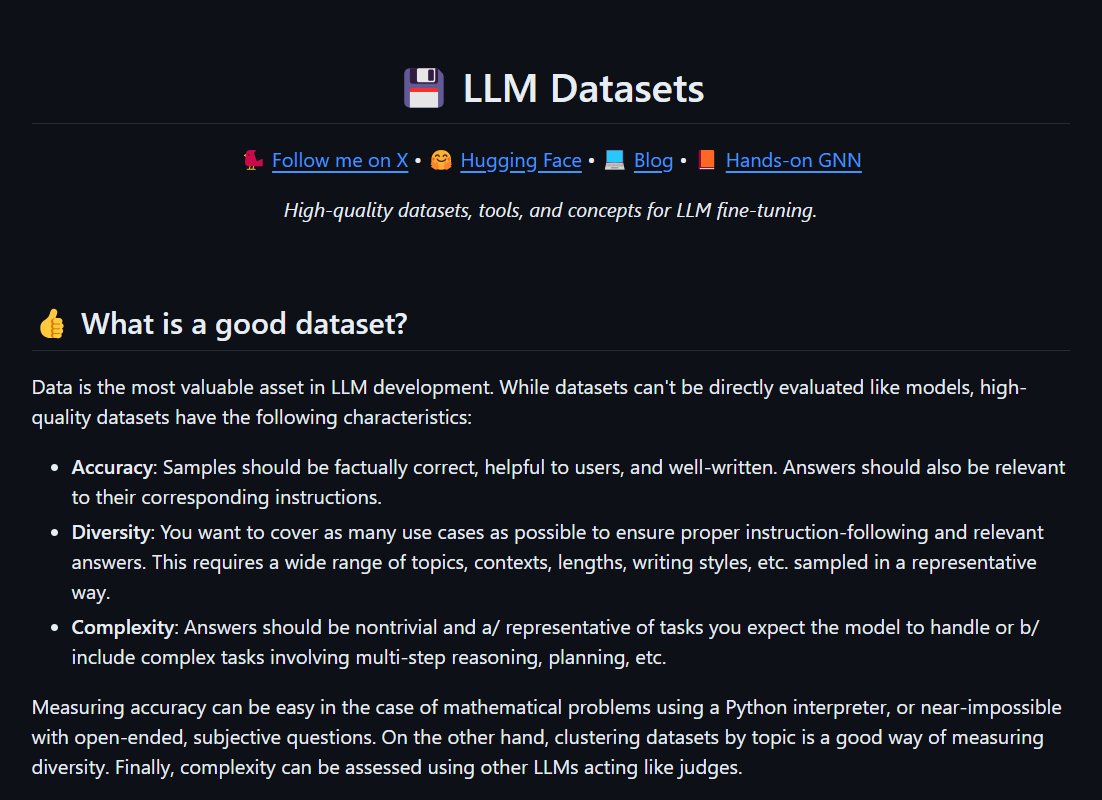
LLM datasets has reached over 1,000 stars It has a ton of high-quality datasets and tools for fine-tuning, data cleaning, generation, and exploration. I've been silently maintaining it over the past months. Special thanks to geronimi73, Bytes-Explorer, and euclaise for their
-
Supervised and Instruction Fine-Tuning: Terminology Clarification
By
–
Personally, I use supervised fine-tuning and instruction fine-tuning interchangeably. It bothered me last year because it wasn't super clear, but it feels like this is how it's used in the literature now
-
Hugging Face Acquires Startup to Handle BigLlama-3.1-1Q
By
–
Hugging Face had to acquire a startup to handle BigLlama. You know what it means… BigLlama-3.1-1Q
-
Model 1T Improved Download Upload Performance Feature
By
–
That's a really cool feature! The biggest problem with the 1T model was the download/upload. Great news 🙂
-
LM-Evaluation-Harness Aggregation Error Analysis
By
–
The funniest part is that manually averaging your scores doesn't give you the same result as lm-evaluation-harness's aggregation (~0.01% error).