Also enjoying the v0.3 of @LMStudioAI
, the new UI is slick
@maximelabonne
-
LM Studio v0.3 Released with Improved User Interface
By
–
-
Hallucinations Leaderboard: Measuring LLM Reliability and Accuracy
By
–
If you want to learn more hallucinations in LLM, I recommend the hallucinations leaderboard (cc @clefourrier
): https://
huggingface.co/spaces/halluci
nations-leaderboard/leaderboard
… It also comes with a nice paper from Hong et al. https://
arxiv.org/abs/2404.05904 -
Claude Family Models Excel with Strong Alignment Safety Measures
By
–
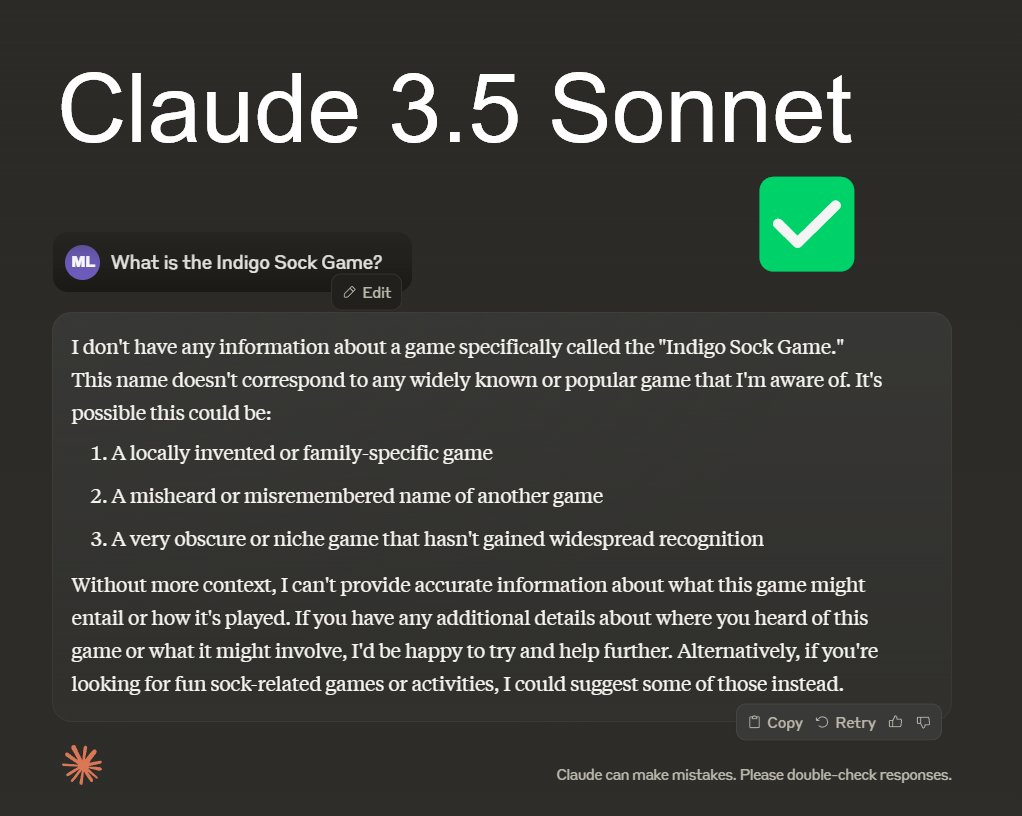
The Claude family from @AnthropicAI is really good at it: Claude 3.5 Sonnet, 3 Opus & Haiku all succeed. It feels like a heavy alignment stage with refusals is part of the explanation.
-
GPT-4 Outperforms 4o Versions in Question Answering
By
–
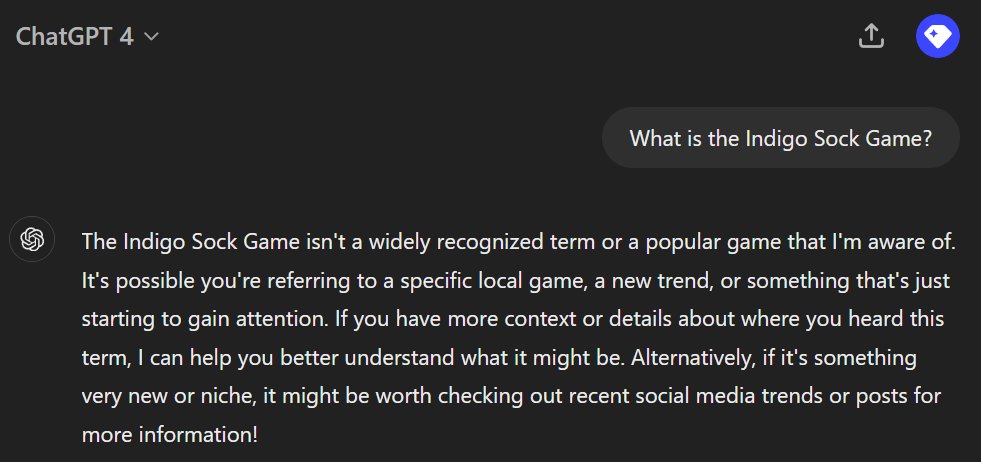
The old GPT-4 also correctly answers the question, while the 4o versions fail.
-

Gemma 2 Model Size Performance Variations and Arena Optimization
By
–
For example, Gemma 2 2B IT answers correctly while the 9B version fails. I'd imagine that models optimized for @lmsysorg Chatbot Arena would perform worse, but that's not always the case.
-
AI Model Hallucinations: Size Doesn’t Guarantee Factual Accuracy
By
–
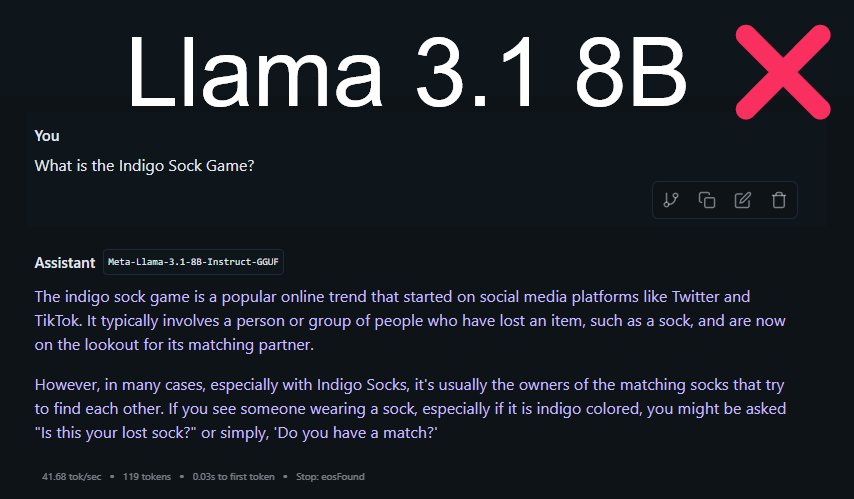
The "Indigo Sock Game" doesn't exist but most models will hallucinate it for you. Factuality hallucinations are fascinating because they often behave in unexpected ways. You'd think bigger models would perform better, but that's not necessarily true.
-

Llama 3.1 Fine-tuning: Code Allocation Breakdown
By
–
Yes, this is standard for general-purpose fine-tuning. Llama 3.1 uses 17% of code for pretraining and 14.89% for post-training.
-
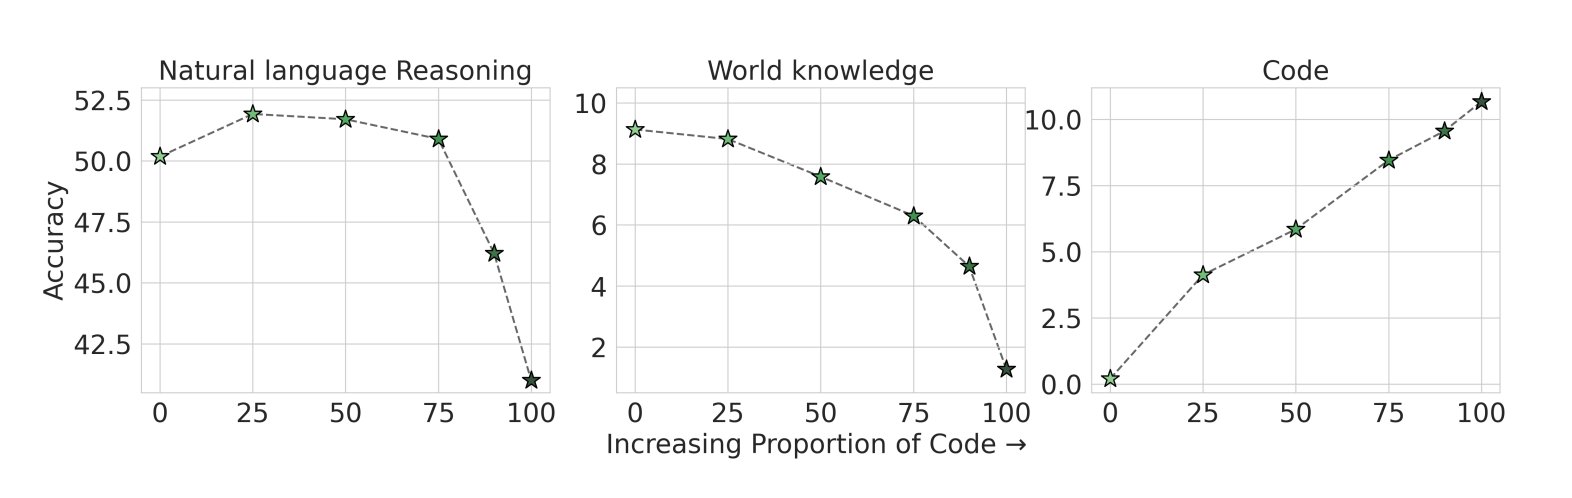
Code in Pretraining Data Improves Model Performance
By
–
Nice paper from @Cohere about the impact of code in the pretraining data: • Including code improves performance on non-code tasks. It would be nice to see the effect on math benchmarks. [1] • Optimal proportion is around 25% but there's not a lot of data points: what about
-

Phi-3.5 MoE: Official Mixture of Experts Model Performance
By
–
Super funny to see an official Phi MoE! Phixtral is a little project I made 8 months ago by combining 2-4 finetunes with MergeKit. It worked better than expected. The Phi-3.5 MoE looks great on benchmark, curious to see how it performs in practice. Model:
-
Correct AI Graph Interpretation Amid Plateau Claims
By
–
I don't agree with his ideas, but I don't have any issue with how he interpreted the graph. Some people have claimed that AI is plateauing and other wrong takes based on it. He's not guilty of that here.