The chat template in the tokenizer config was wrong. Just updating it gave something like +30-40 points on IFEval.
@maximelabonne
-
Model Comparison Methodologies and API Evaluation Fairness
By
–
The same can be done with any model. This is why researchers specify n-shot, CoT, etc. The model behind an API will be super useful and could even be better than any other model (in theory). But this comparison is wrong nonetheless.
-
Unknown AI practices raise ethical concerns and questions
By
–
We don't know what they do, but we know it's wrong.
-
Llama 3.1 capabilities comparison with other models
By
–
I'm not sure they do, but Llama 3.1 doesn't for example so you're comparing apples and oranges anyway
-
Researcher Score Transparency and AI Evaluation Methodology
By
–
Scores reported by researchers are not the same as answers provided by the API. They indicate when they use techniques like n-shot, CoT, etc. If they hide additional prompting techniques used to obtain these scores, it would be considered fraudulent.
-
Fair Model Comparison Requires Consistent Prompting Techniques
By
–
Yes, this is my point: we shouldn't compare different models based on different prompting techniques. We need reflection vs. reflection, CoT vs. CoT, etc.
-
Raw LM-Evaluation-Harness Testing Without System Prompt
By
–
It's "raw" lm-evaluation-harness, I didn't add the recommended system prompt.
-
L3.1 70B weights upload issue discussion
By
–
I haven't yet but does it mean they wrongly uploaded L3.1 70B's weights…?
-
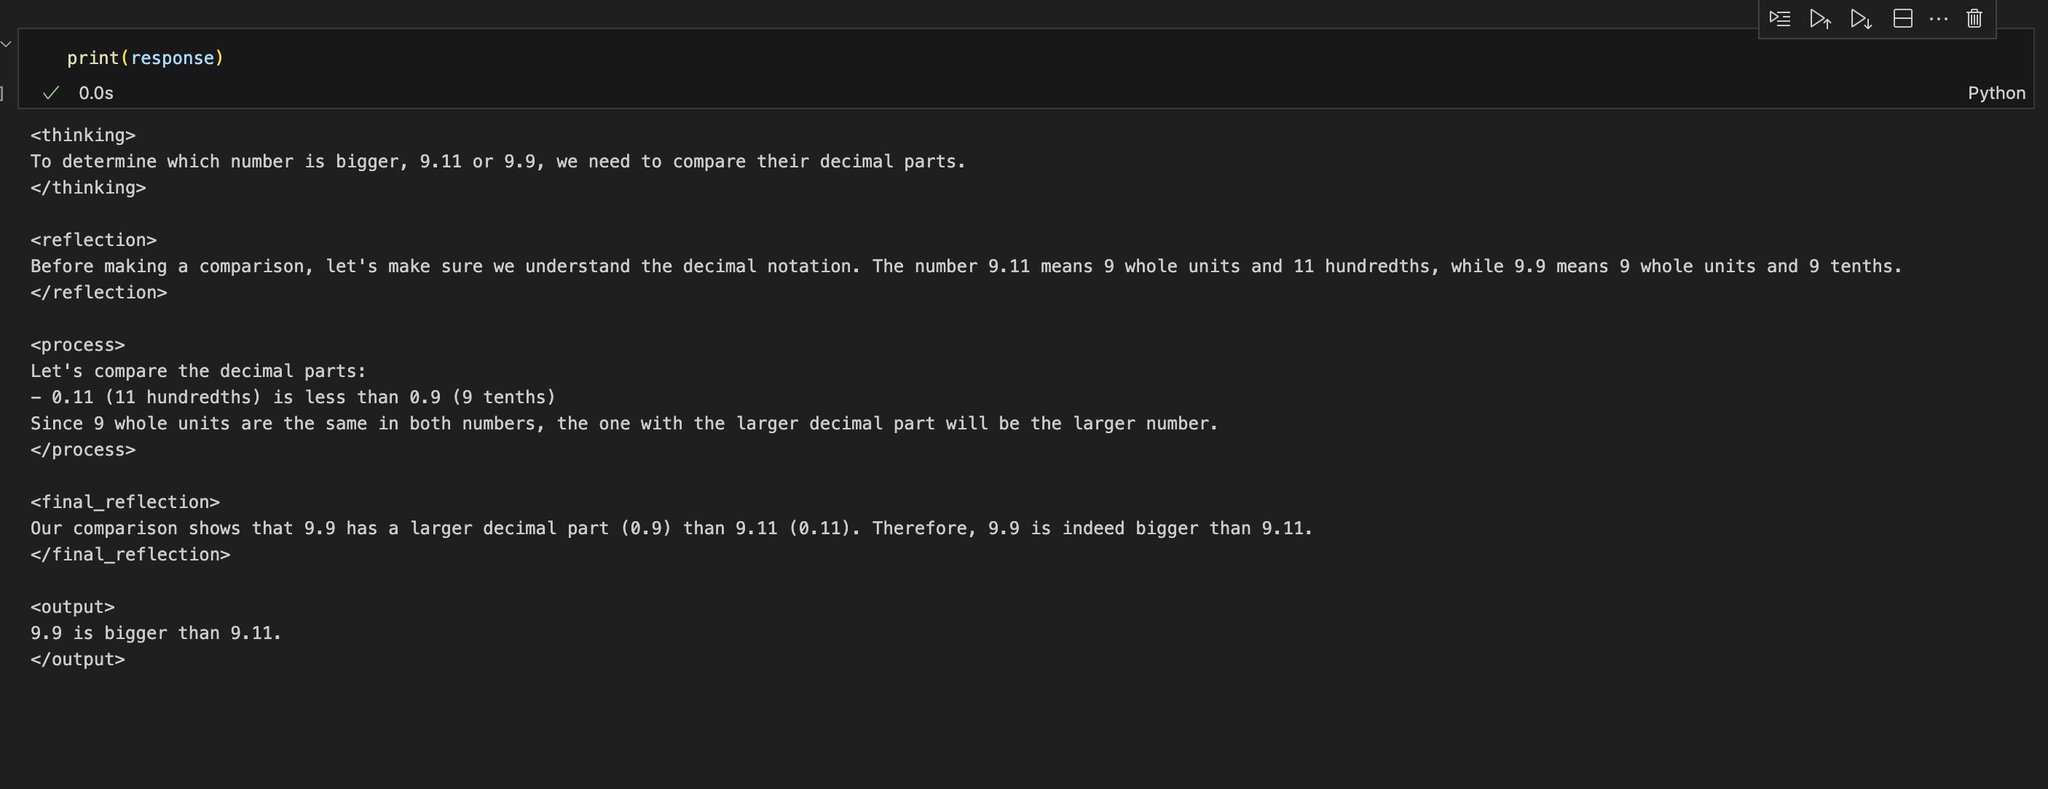
Reflection technique between AI models by Fernando Neto
By
–
Example from the great @FernandoNetoAi of reflection with another model.
-
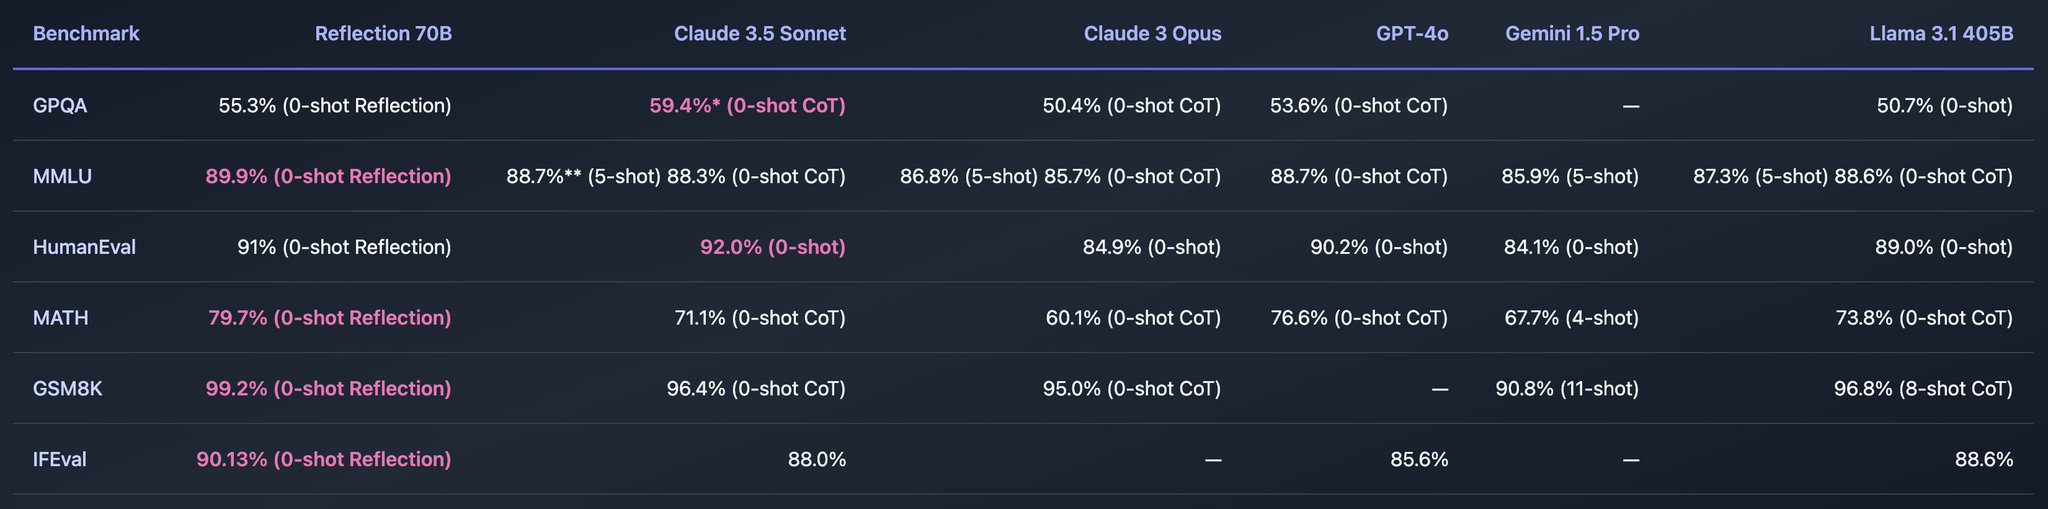
Reflection CoT Evaluation Methods Comparability Issues
By
–
This is super cool but I have a lot of questions. First, reflection = CoT on steroids. It means you can't compare these scores at all. Remember when people made fun of Gemini for providing CoT results for MMLU? This is a lot worse. Secondly, if you don't parse the output and