I agree. I'm mostly curious about the difference between replicating blocks vs. individual layers with Qwen2.5-34B-Instruct.
@maximelabonne
-
Distributed Layer Replication Improves Neural Network Output Quality
By
–
Yeah I agree. When you replicate entire blocks of several layers, the input/output difference dramatically changes, which might degrade the quality of the final output. Replicating individual layers in a distributed way tries to address this issue.
-
Echo Merge: Optimizing Layer Replication in AI Models
By
–
For the echo merge, the idea is that self-merges might be slightly "insane" because replicating blocks of several layers disrupts the information flow. By only replicating individual layers in a distributed way, I'm trying to minimize the input/output difference they introduce.
-
Echo Merge Experiment Tests Self-Merge Information Flow
By
–
I don't expect it to have superior performance in general, but in some narrow domains. The echo merge is an experiment to check if the "insanity" of these self-merges comes from a broken information flow.
-

BigQwen2.5-125B: Self-Merged Large Language Model
By
–
BigQwen2.5-125B I made a few self-merges with the new Qwen2.5 models: – The 125B model is based on Qwen2.5-72B-Instruct and follows Meta-Llama-3-120B-Instruct's (
https://
huggingface.co/mlabonne/Meta-
Llama-3-120B-Instruct
…) recipe, where blocks of 10 layers are repeated 6 times. – The 47B model is based on -
Meta LLaMA 3 Training Checkpoint Discussed in Official Blog
By
–
It's a checkpoint during training they talked about in this blog post https://
ai.meta.com/blog/meta-llam
a-3/
… -
Claude 3.5 Sonnet Thinking Tokens and MMLU Score Implications
By
–
Sonnet has thinking tokens, yes. We don't know if they used them to get the MMLU score here https://
anthropic.com/news/claude-3-
5-sonnet
… But if more and more API models do this, I'll have to add them at some point -
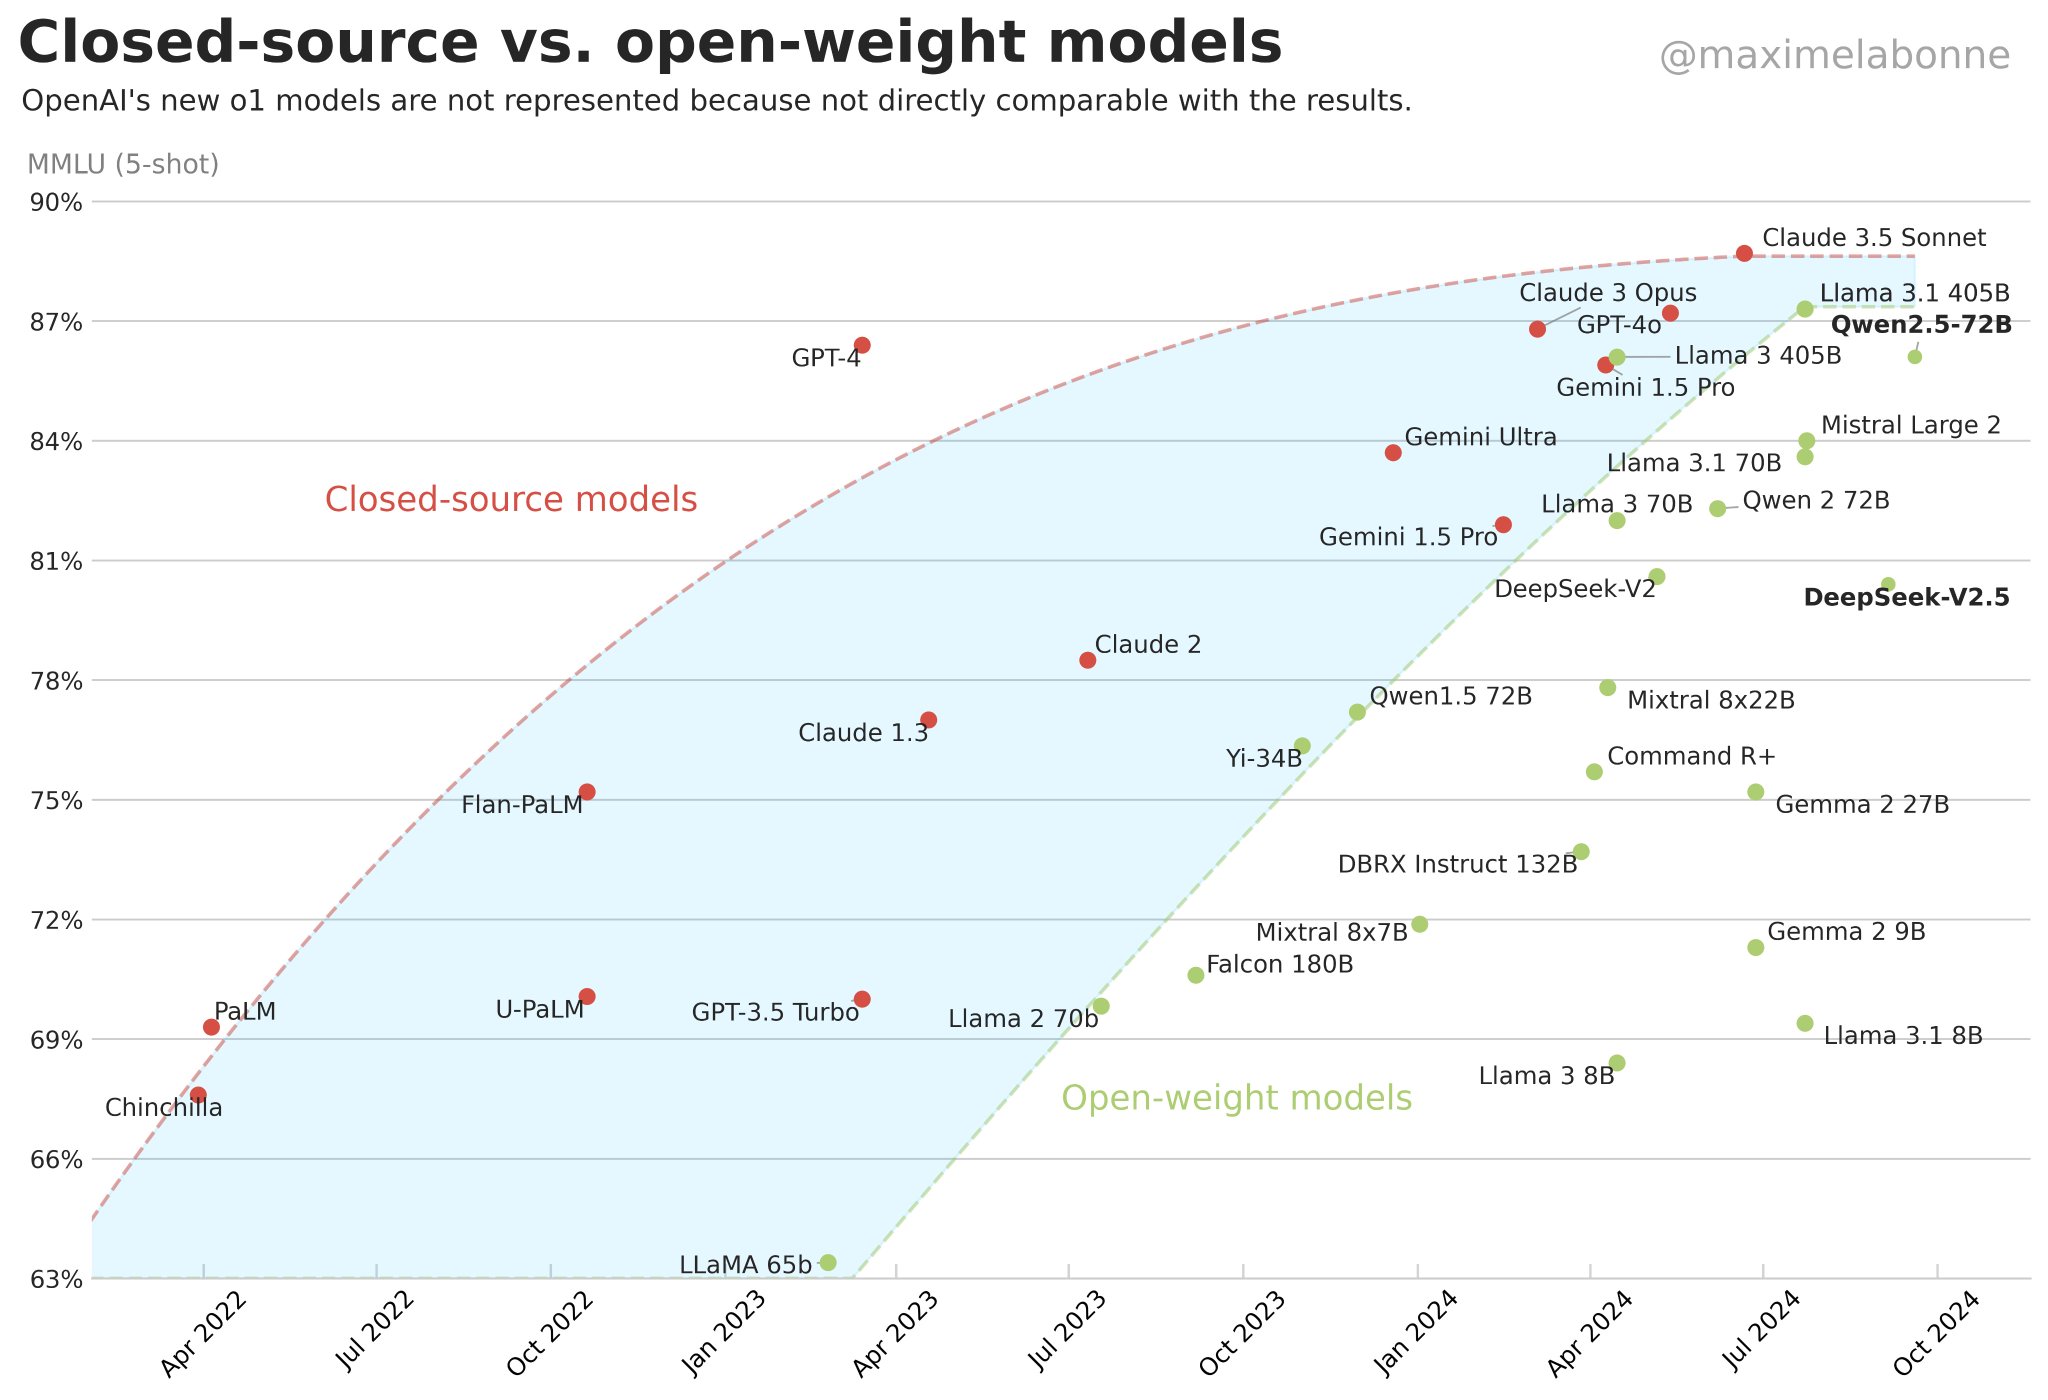
Qwen2.5 and DeepSeek-V2.5 Performance Comparison on MMLU
By
–
Updated version of the graph with @Alibaba_Qwen
's Qwen2.5-72B and @deepseek_ai
's DeepSeek-V2.5. I didn't add o1 because these models have built-in CoT reasoning and maybe other stuff that makes the comparison unfair. For example, Gemini Ultra's MMLU score goes from 83.7% with -
Arcee AI SEC Model for Financial Data Analysis Agent
By
–
I haven't used one but you might find inspiration from @arcee_ai
's SEC model https://
blog.arcee.ai/introducing-th
e-ultimate-sec-data-chat-agent-revolutionizing-financial-insights/
… -
Distinguishing Model Criticism from Endorsement in AI Research
By
–
I think you're misinterpreting my posts. I posted about this model to raise concerns about the methodology. This is completely different than endorsing and promoting it. I don't have to wait for independent benchmarks because I don't promote the results (it's the rest of the