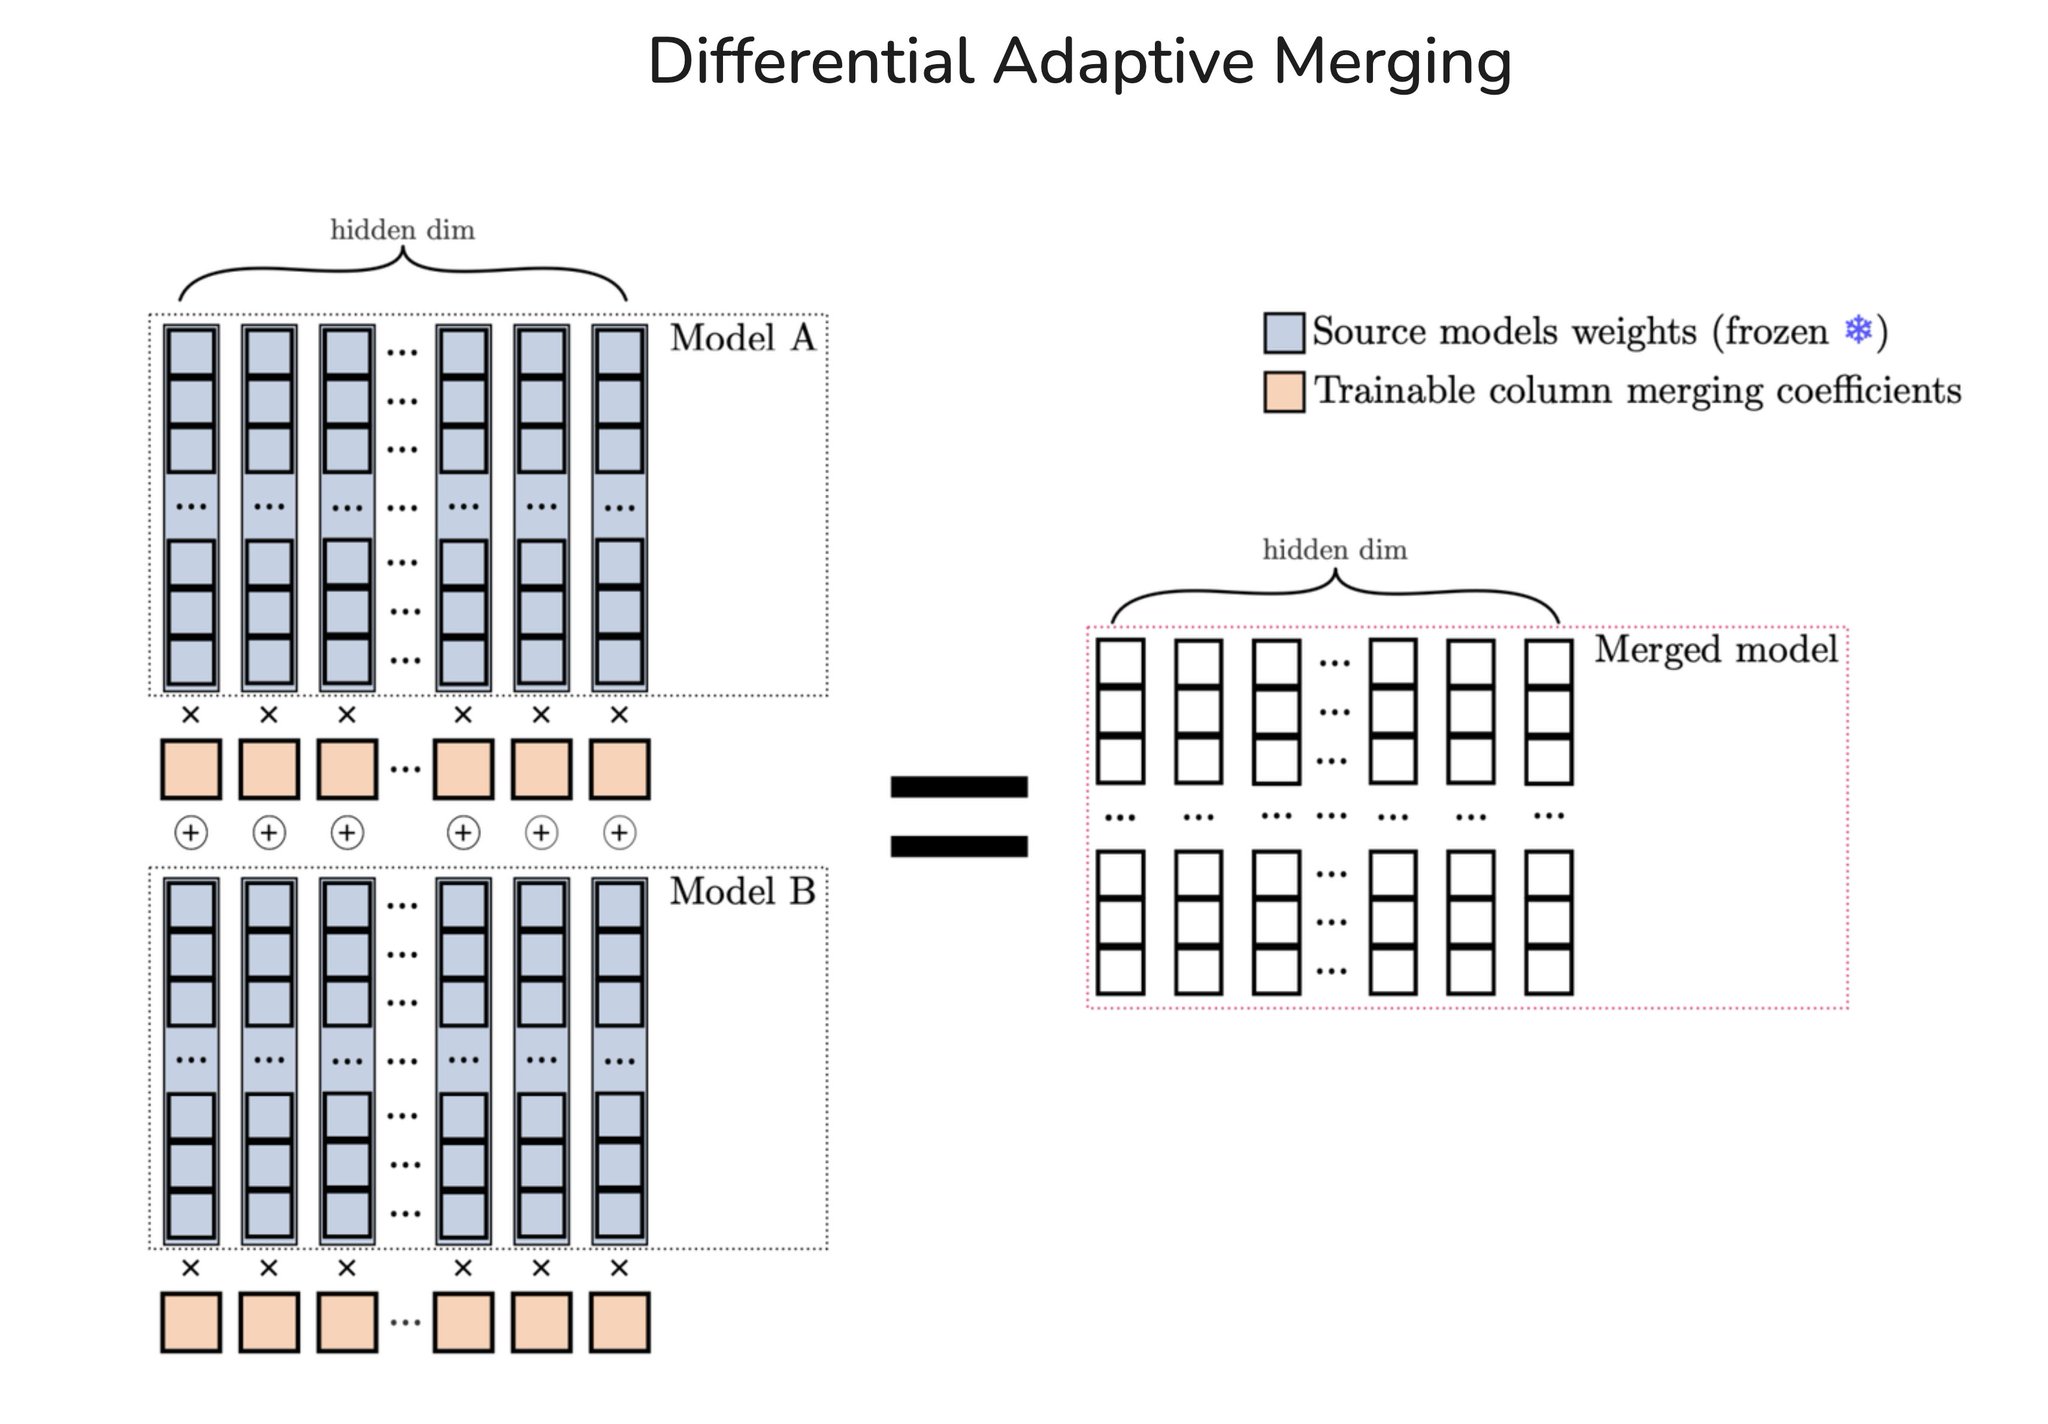
Differentiable Adaptive Merging I participated in a paper with @arcee_ai about a new automated merging technique (no manual parameter tuning!) Compared to other algorithms, like Evolutionary Merging, it is significantly faster to run and achieves the same level of performance.
@maximelabonne
-
Model Merging Community Innovation and Creative Naming Trends
By
–
The best part about model merging is how people build upon your models and come up with crazy names.
-
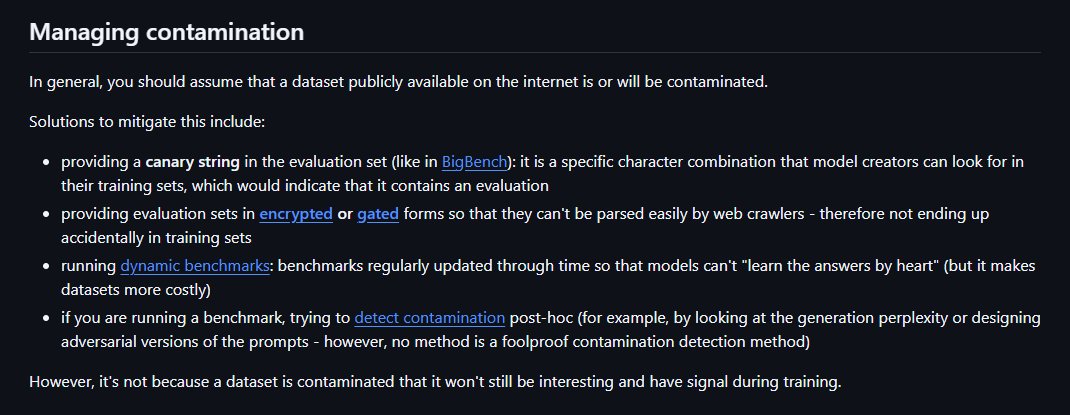
LLM Evaluation Guide: Benchmarks, Human Eval, and Judge Methods
By
–
Clémentine, @huggingface
's evaluation expert, made an excellent guide about LLM evaluation. It covers automatic benchmarks, human eval, and LLM-as-a-judge, including tips and tricks to create your own evals. -
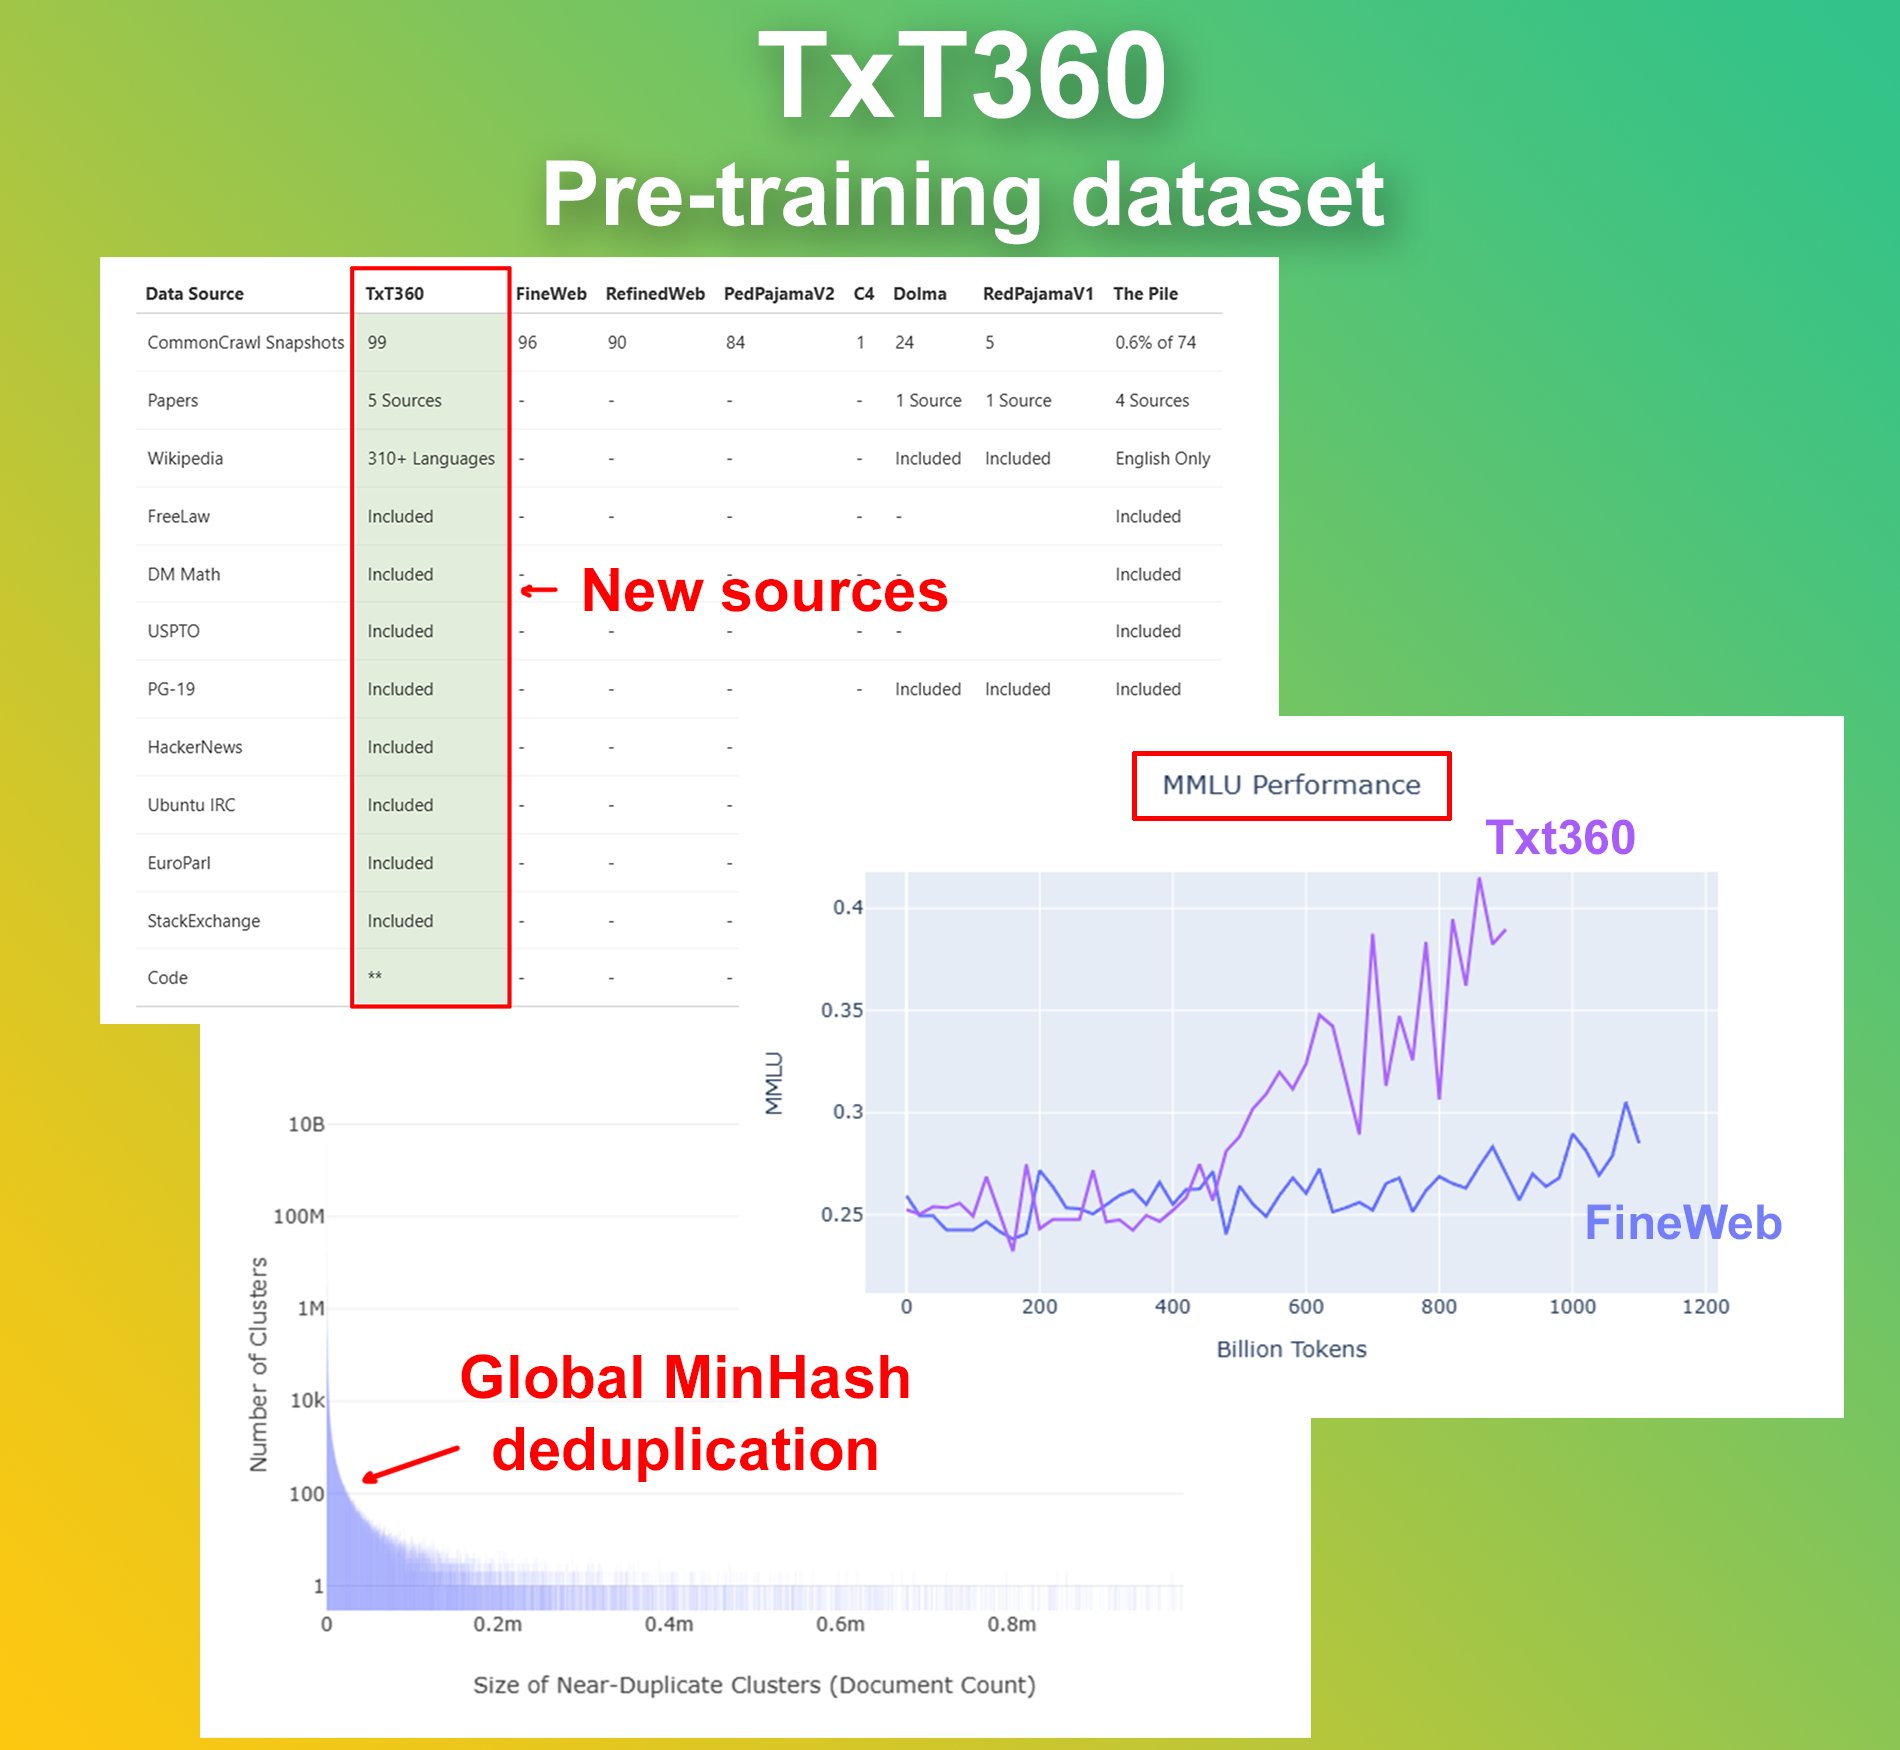
LLM360 releases TxT360: 15T token pre-training dataset
By
–
TxT360: new pre-training dataset with 15T tokens Impressive release from LLM360 with a new pre-training dataset of 15T tokens. It includes a lot of new sources compared to previous open-sourced pre-training datasets, like FreeLaw, PG-19 (books), etc. It's really interesting
-
SFT vs DPO: Finding the Sweet Spot in Model Training
By
–
In my experience, SFT is quite destructive, which is why I like DPO better. There might be a sweet spot with SFT and low LRs though. I haven't experimented with it that much tbh.
-
Testing Liquid AI Foundation Models Across Multiple Platforms
By
–
You can test LFMs today using the following links:
– Liquid AI Playground: https://
playground.liquid.ai
– Lambda: https://
lambda.chat/chatui/models/
/models/LiquidCloud
…
– Perplexity: https://
labs.perplexity.ai If you're interested, find more information in our blog post: -
LFM Architecture Enables New Foundation Model Design Space
By
–
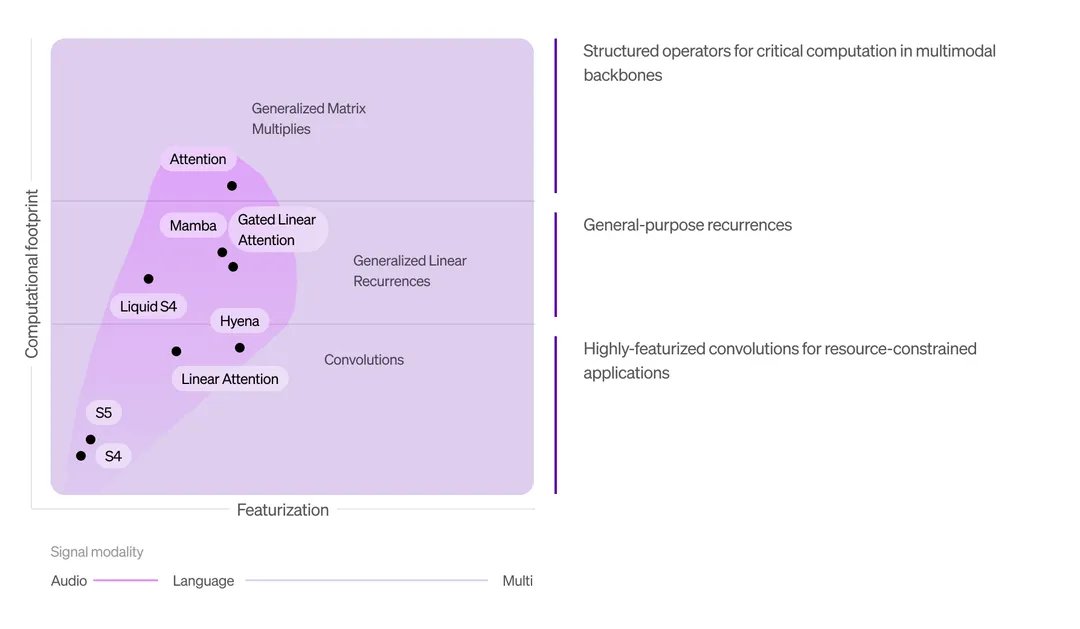
The LFM architecture opens a new design space for foundation models. This is not restricted to language, but can be applied to other modalities: audio, time series, images, etc. It can also be optimized for specific platforms, like @Apple
, @AMD
, @Qualcomm
, and @cerebras -
LFM-3B Achieves 32K Context Window with Promising RULER Scores
By
–
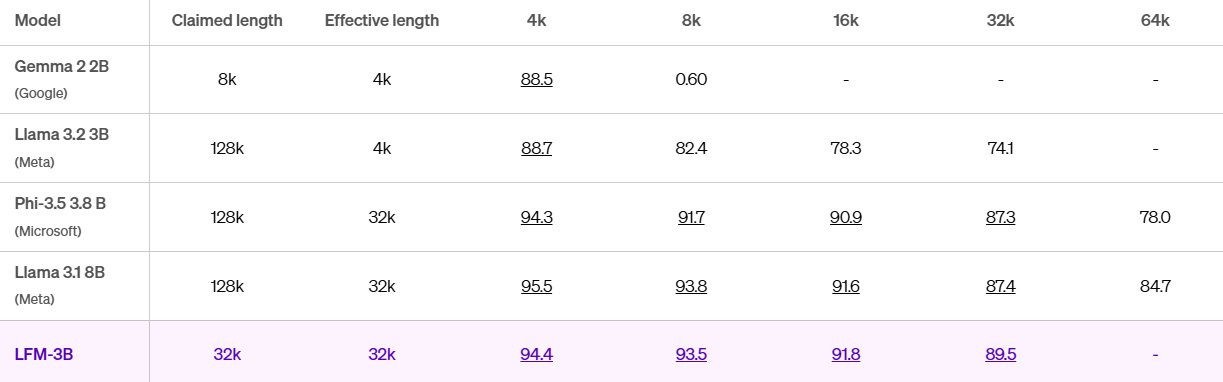
In this preview release, we focused on delivering the best-in-class 32k context window. These results are extremely promising, but we want to expand it to very, very long contexts. Here are our RULER scores (
https://
github.com/hsiehjackson/R
ULER
…) for LFM-3B ↓ -
LFM Architecture: Memory-Efficient LLM for Long Contexts
By
–
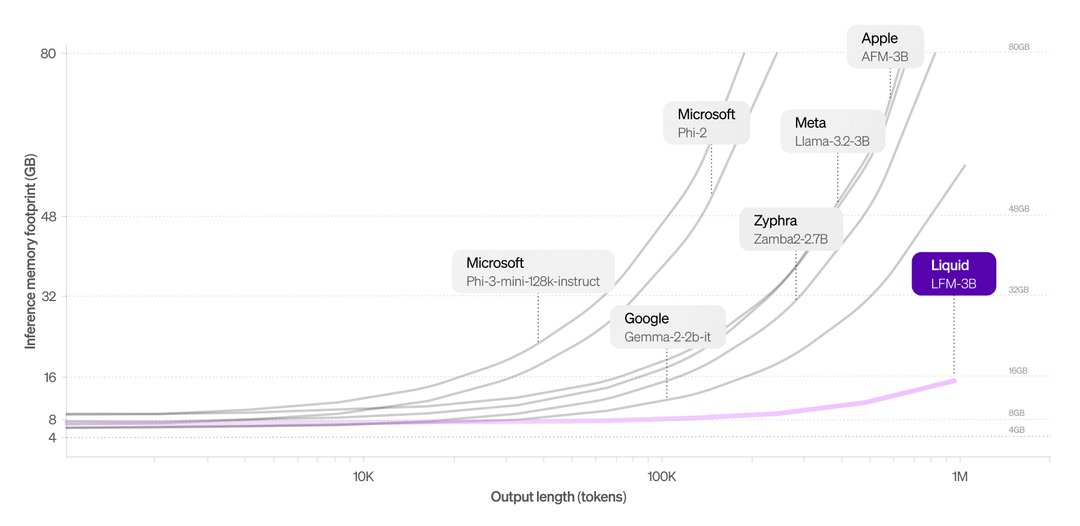
The LFM architecture is also super memory efficient. While the KV cache in transformer-based LLMs explodes with long contexts, we keep it minimal, even with 1M tokens. This unlocks new applications, like document and book analysis, directly in your browser or on your phone.
-
LFM optimization outperforms transformers at 1B to 40B scale
By
–
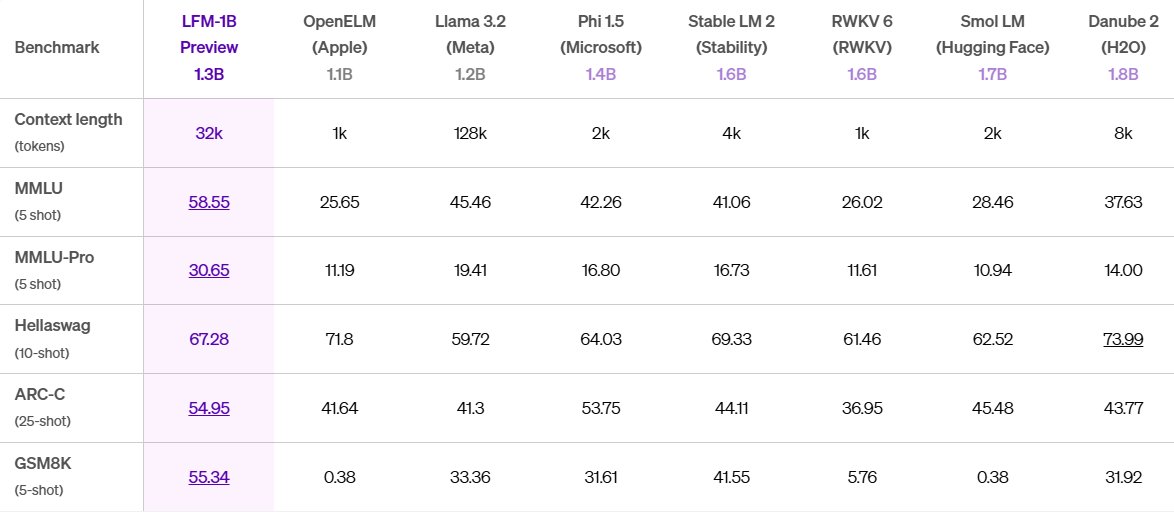
We optimized LFMs to maximize knowledge capacity and multi-step reasoning. As a result, our 1B and 3B models significantly outperform transformer-based models in various benchmarks. And it scales: our 40B MoE (12B activated) is competitive with much bigger dense or MoE models.