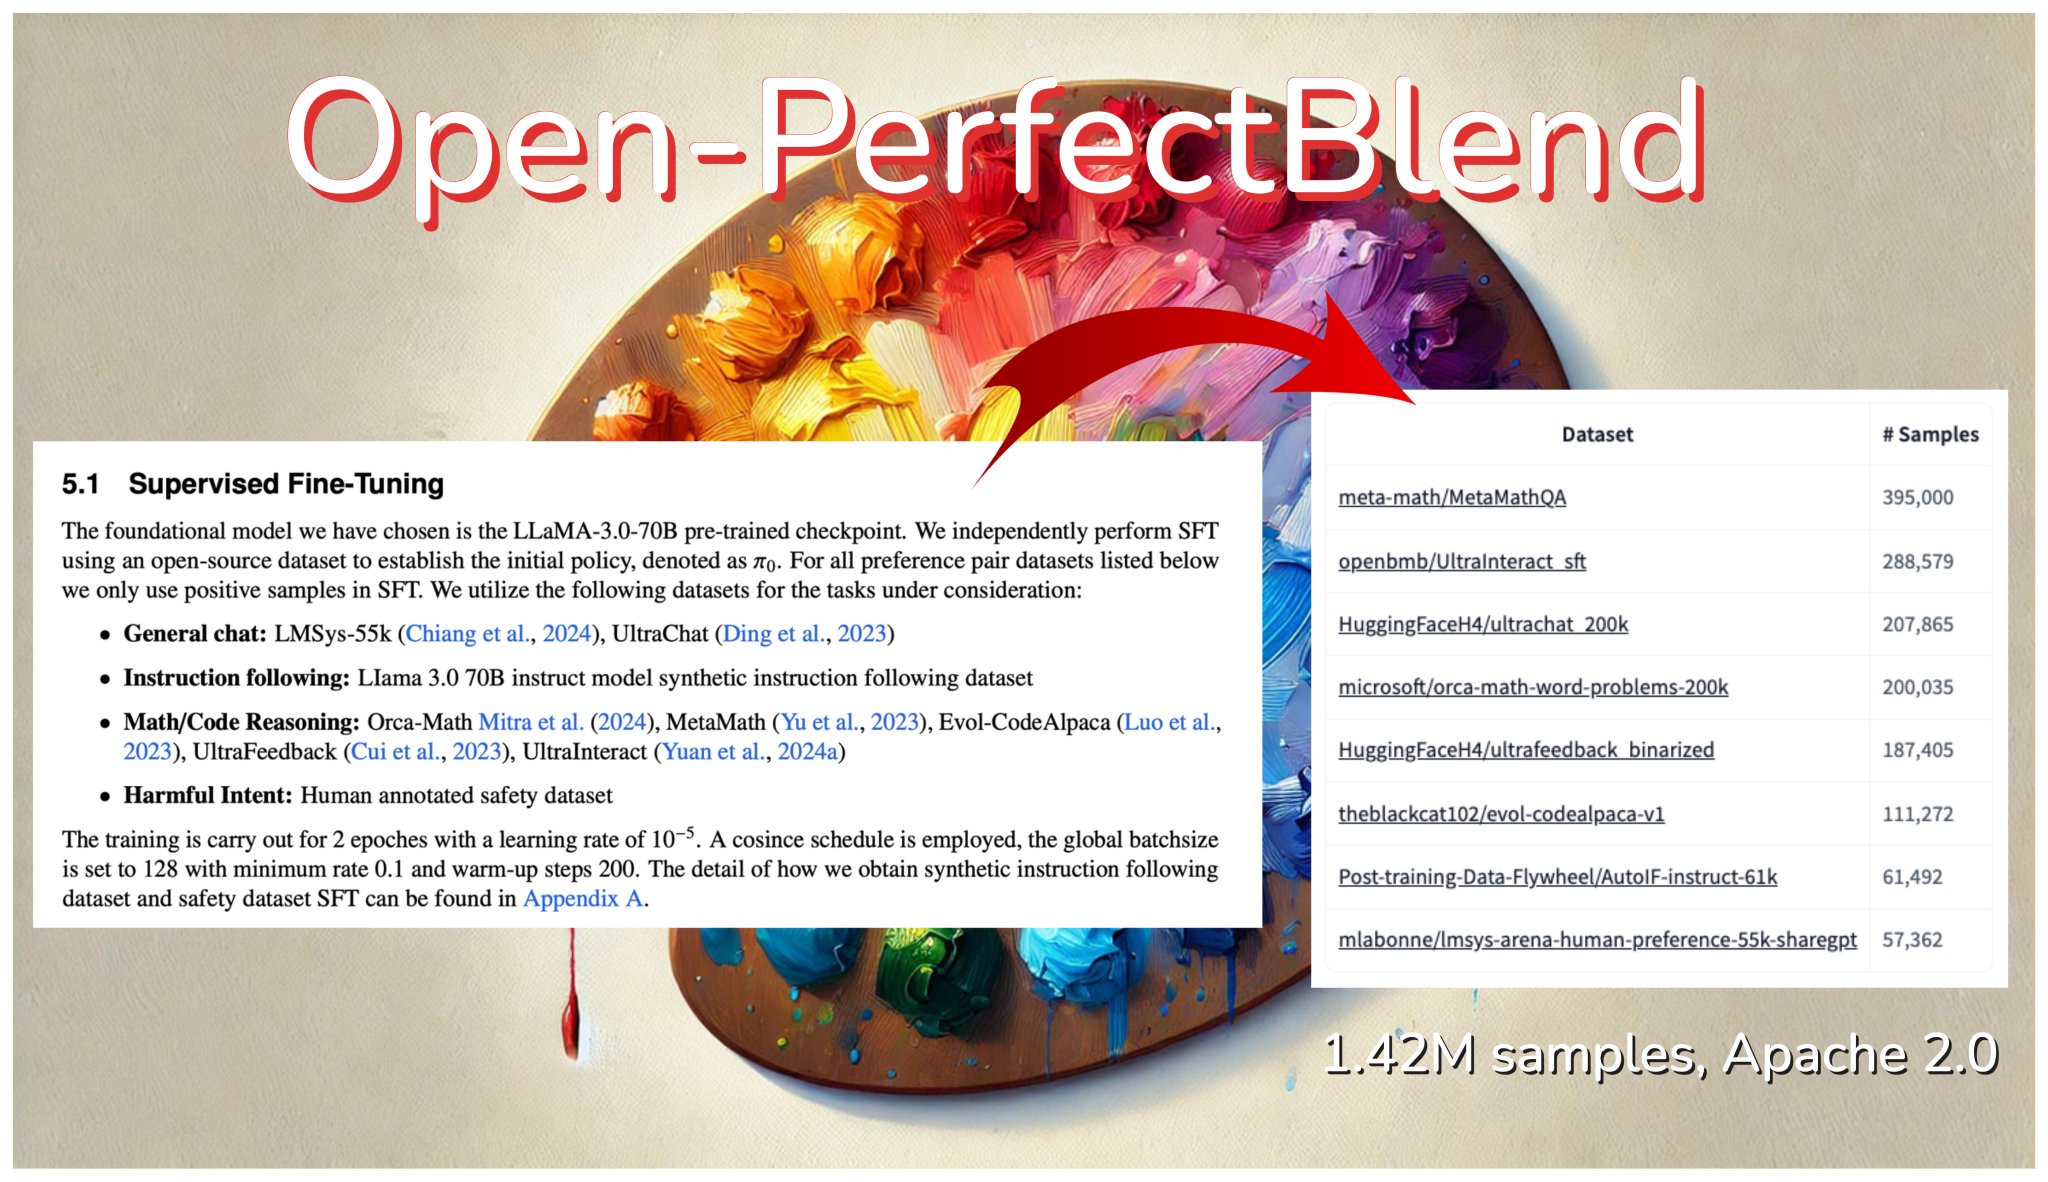
Open-PerfectBlend I reproduced the SFT dataset described in Meta's PerfectBlend paper: 1.42M samples with chat, math, code, and instruction-following samples. Give it a try for your next fine-tune! Dataset: https://
huggingface.co/datasets/mlabo
nne/open-perfectblend
… Paper: https://
arxiv.org/abs/2409.20370
@maximelabonne
-
Open-PerfectBlend: 1.42M Sample SFT Dataset Released
By
–
-
Nemotron: Nvidia’s Model and Benchmark Evaluation Issues
By
–
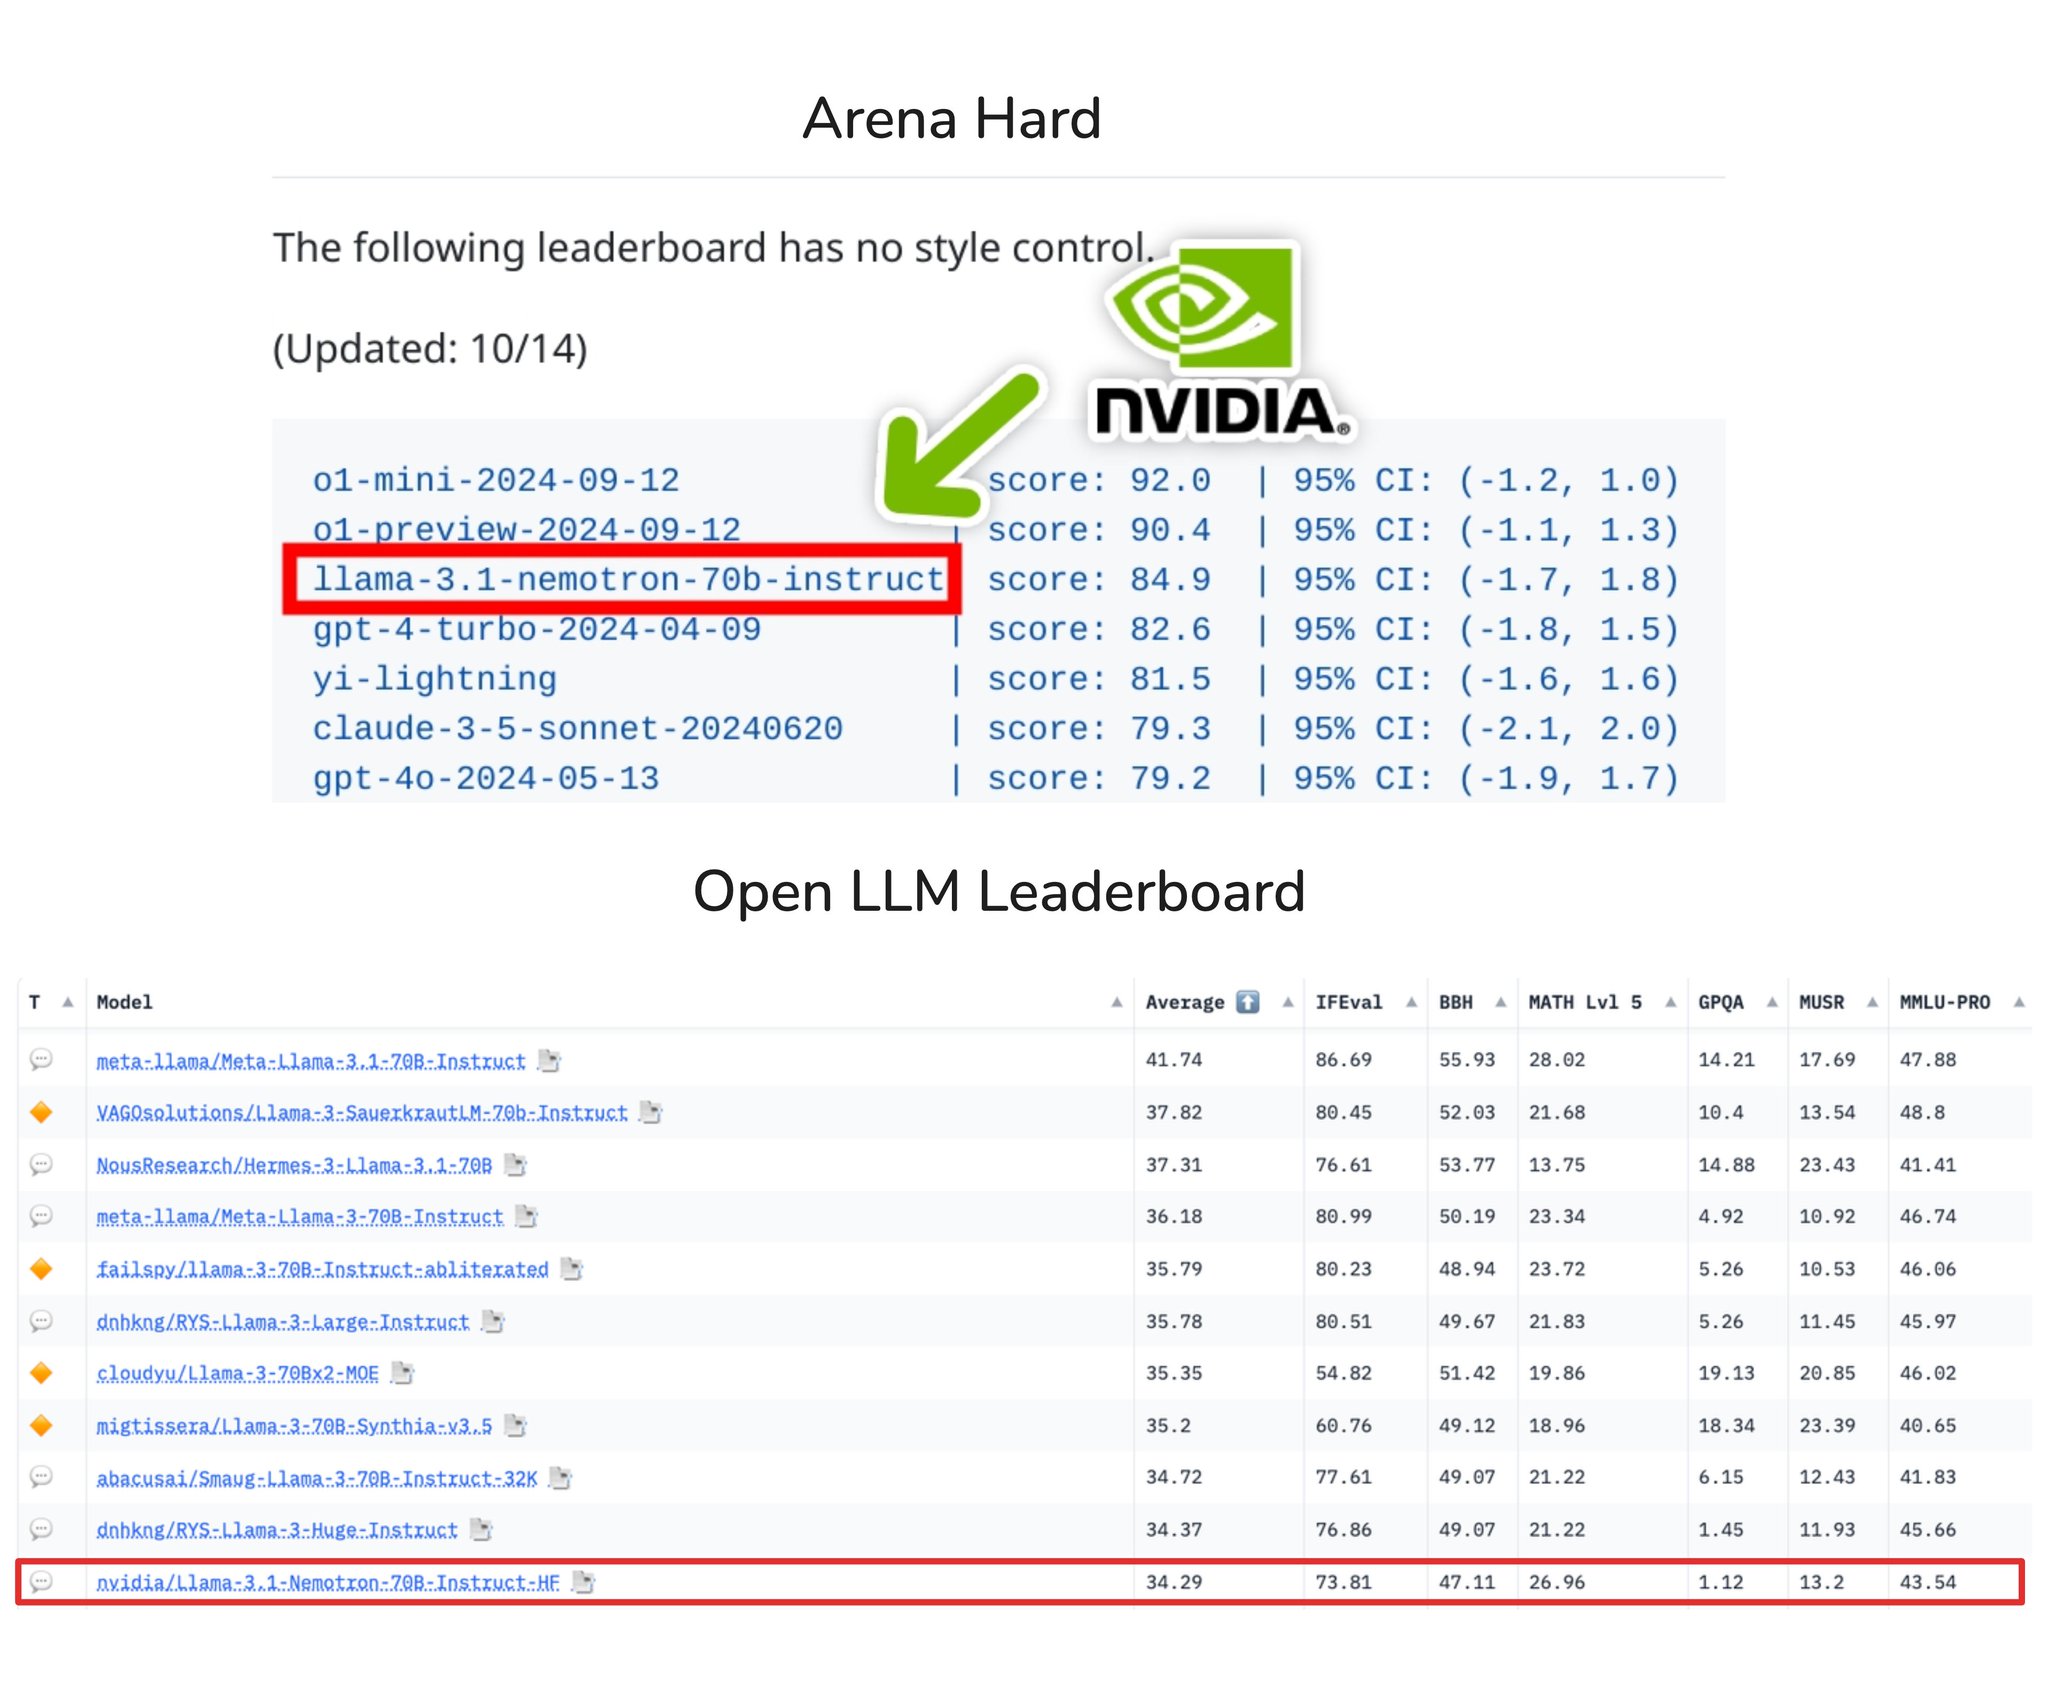
To be clear: imo, Nemotron is a good model and a valuable contribution. Nvidia was factual in their claims and we shouldn't overhype it. If this work reveals issues with these benchmarks, it's even better for the community.
-
Honest Model Evaluation Over Hype in AI Research
By
–
This is the opposite imo: they claimed good scores on three benchmarks and that's it. No grandiose claims in the model card or the paper. The team made a valuable contribution, let's just not overhype it.
-
Llama 3.1 Nemotron reveals benchmark evaluation disparities
By
–
Llama-3.1-Nemotron-70B is a good reminder that chat capabilities evaluated by Arena Hard, AlpacaEval, and MT-Bench correlate poorly with benchmarks like MMLU and GPQA. They also provide a useful but narrow view of human preferences. Blame the benchmarks, not the models
-
Open Source Community Methods Predate Academic Papers
By
–
Way before these papers, that's also how we did it in the open source community.
-
Data-Informed Merging Techniques in Machine Learning
By
–
There are only three alternatives in the data-informed merging family, so definitely room for more techniques
-
Open-source model merging technique simplifies parameter tuning
By
–
Hope you'll like this technique. This makes model merging 1/ simpler by removing parameter tuning and 2/ more computationally efficient than alternatives. You can play with it today. The code is open-sourced and available on GitHub
-

DAM Optimization Outperforms Techniques for SQL and German Tasks
By
–
Case study 2: SQL + German + Korean We combined three Llama-based models and optimized coefficients on three different datasets. DAM outperforms other techniques on average: in particular in German and SQL, but falls short in Korean.
-
DAM Model Merging: Japanese Math LLM Optimization Results
By
–
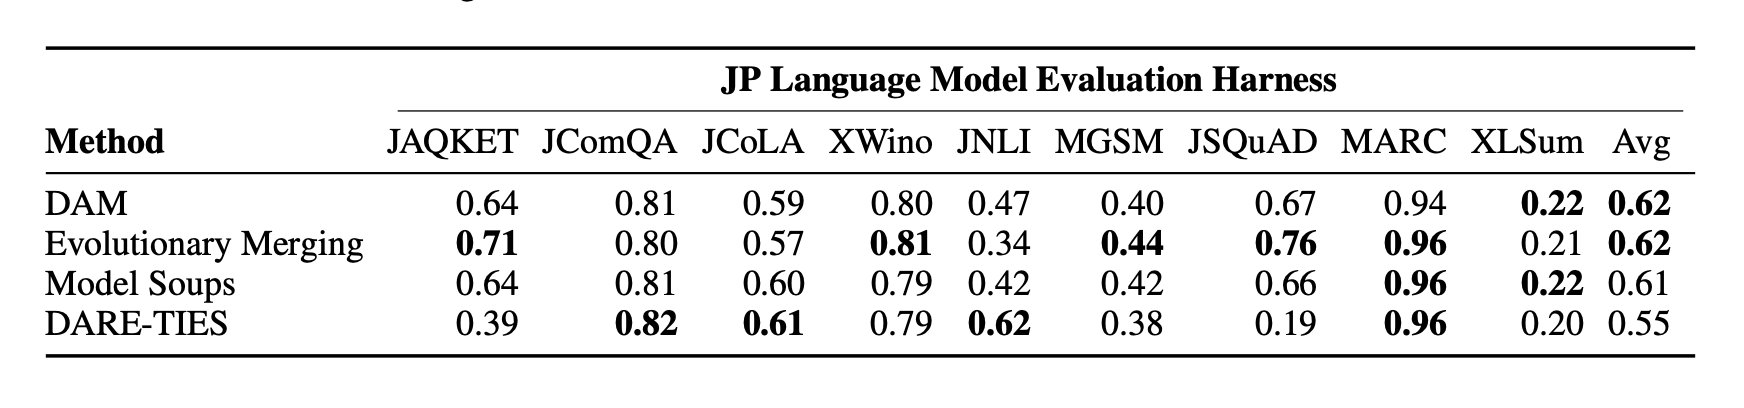
Case study 1: Japanese + Math model We combined shisa-gamma-7b, WizardMath-7B-V1 and Abel-7B-002 and optimized coefficients on Ichikara, MetaMathQA, and Orca-Math. DAM achieved the best average score across various tasks, matching Evolutionary Merging but with less
-
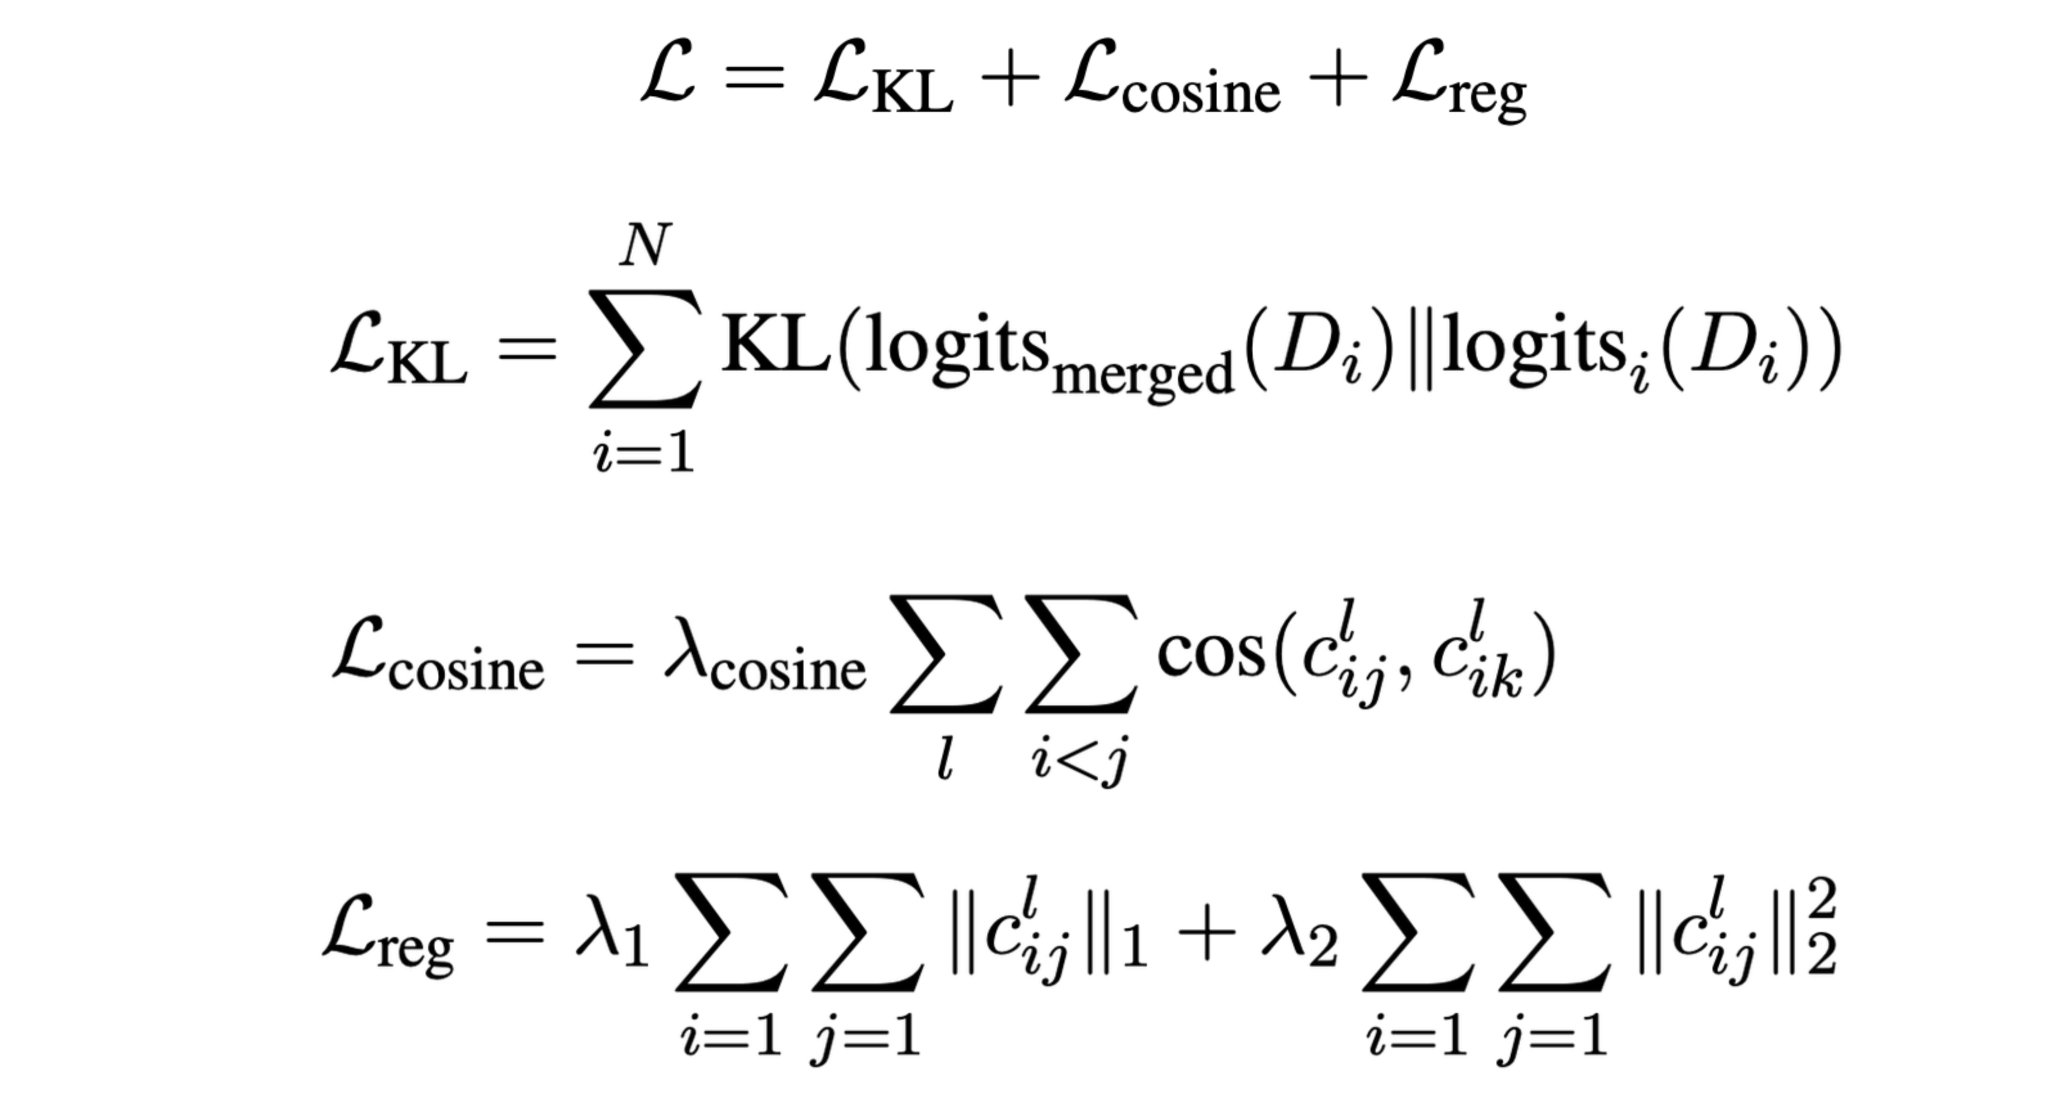
DAM: Scaling Coefficients for Source Model Weight Merging
By
–
DAM learns scaling coefficients for each column in the weight matrices of the source models. The objective function is optimized with gradient descent. It includes: – KL divergence to align the merged model's predictions with each expert source model
– Cosine similarity