I'd say it's traditional at this point. I would expect them to use something more RL like PPO but it's interesting they chose DPO instead. It also shows that, despite all the *PO papers, most labs still use DPO variants.
@maximelabonne
-
Dataset Diversity Requirements for Language Model Scaling
By
–
Isn't it also related to diversity in your dataset? 2B = not diverse enough to scale, 10B = maybe okay?
-
Tencent Releases Hunyuan Large Language Model with Multimodal Capabilities
By
–
Paper: https://
arxiv.org/abs/2411.02265 Model: https://
huggingface.co/tencent/Tencen
t-Hunyuan-Large
… -
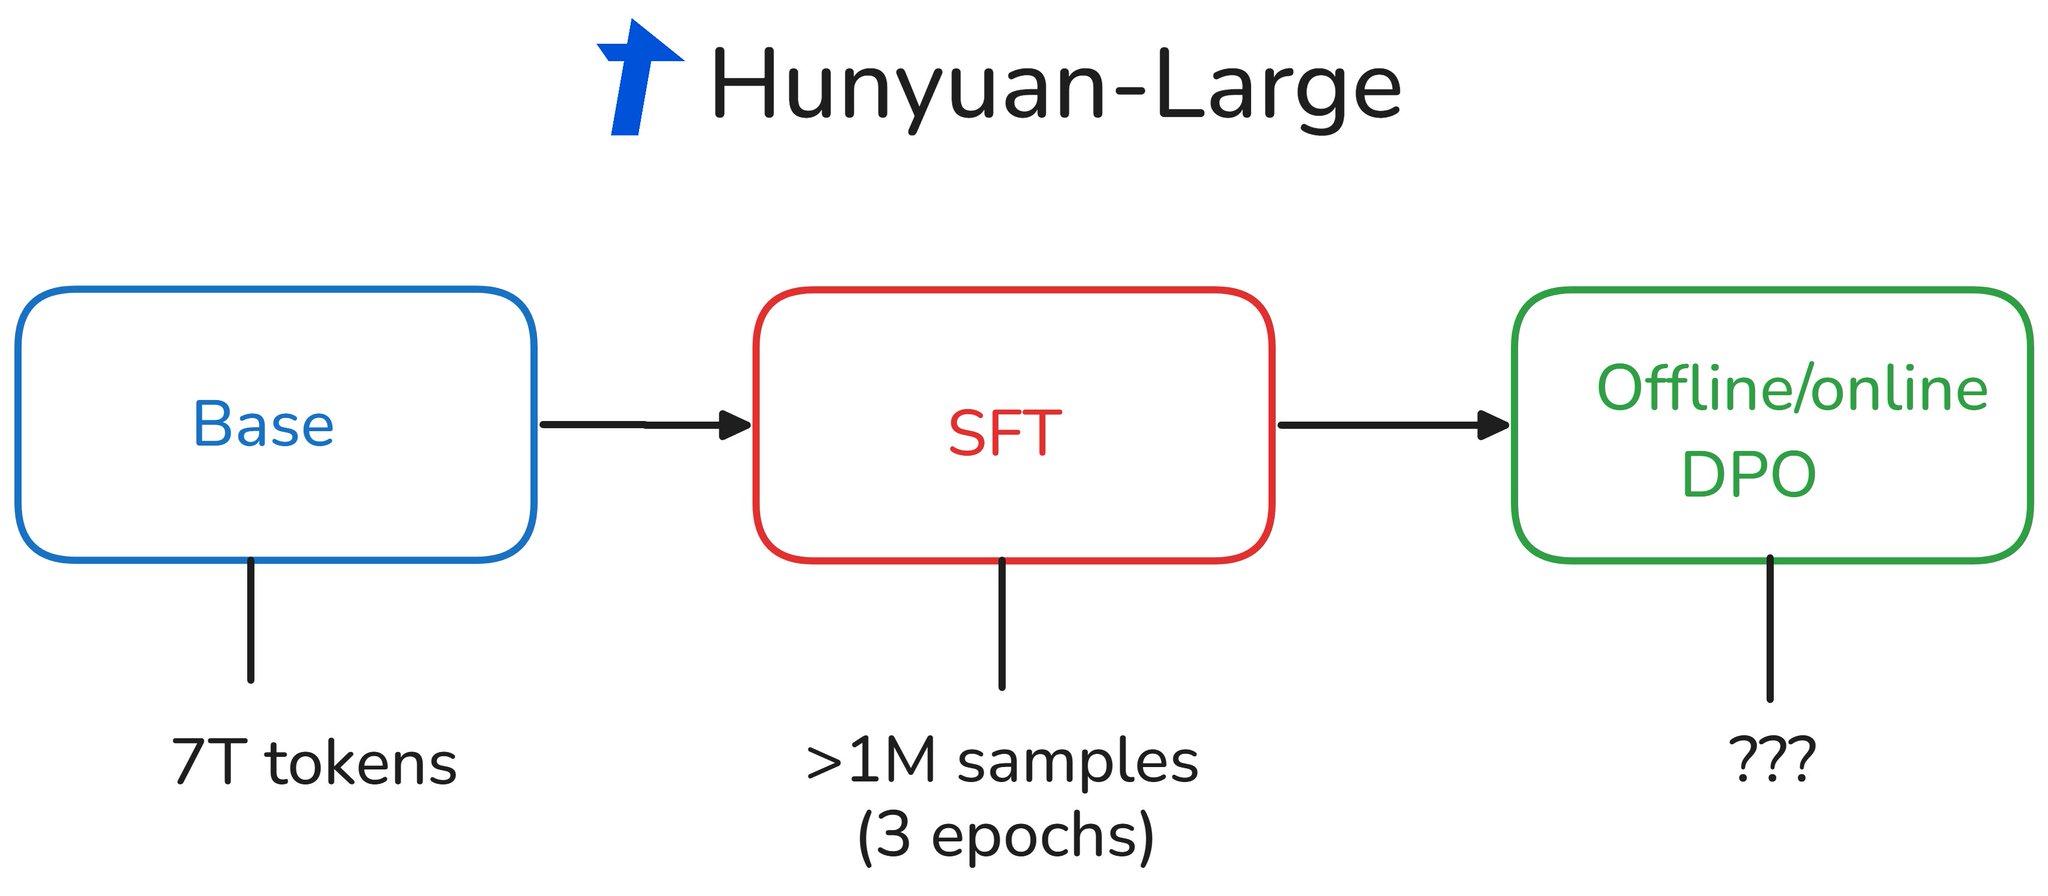
Hunyuan-Large Post-Training Pipeline: SFT and DPO Strategy
By
–
Interestingly, Hunyuan-Large follows a traditional post-training pipeline with SFT and DPO. SFT data is sourced from public sources and evolved to increase complexity Data quality is ensured through 3 stages: rules → 70B critique model → human review If I understood
-
French-Speaking AI: Awareness, Cultural Diversity and Model Transparency
By
–
The description mentions three objectives: – Raising awareness among citizens about generative AI and its challenges – Ensuring respect for the diversity of French-speaking cultures in conversational AI models – Contributing to the transparency of generative AI models
-
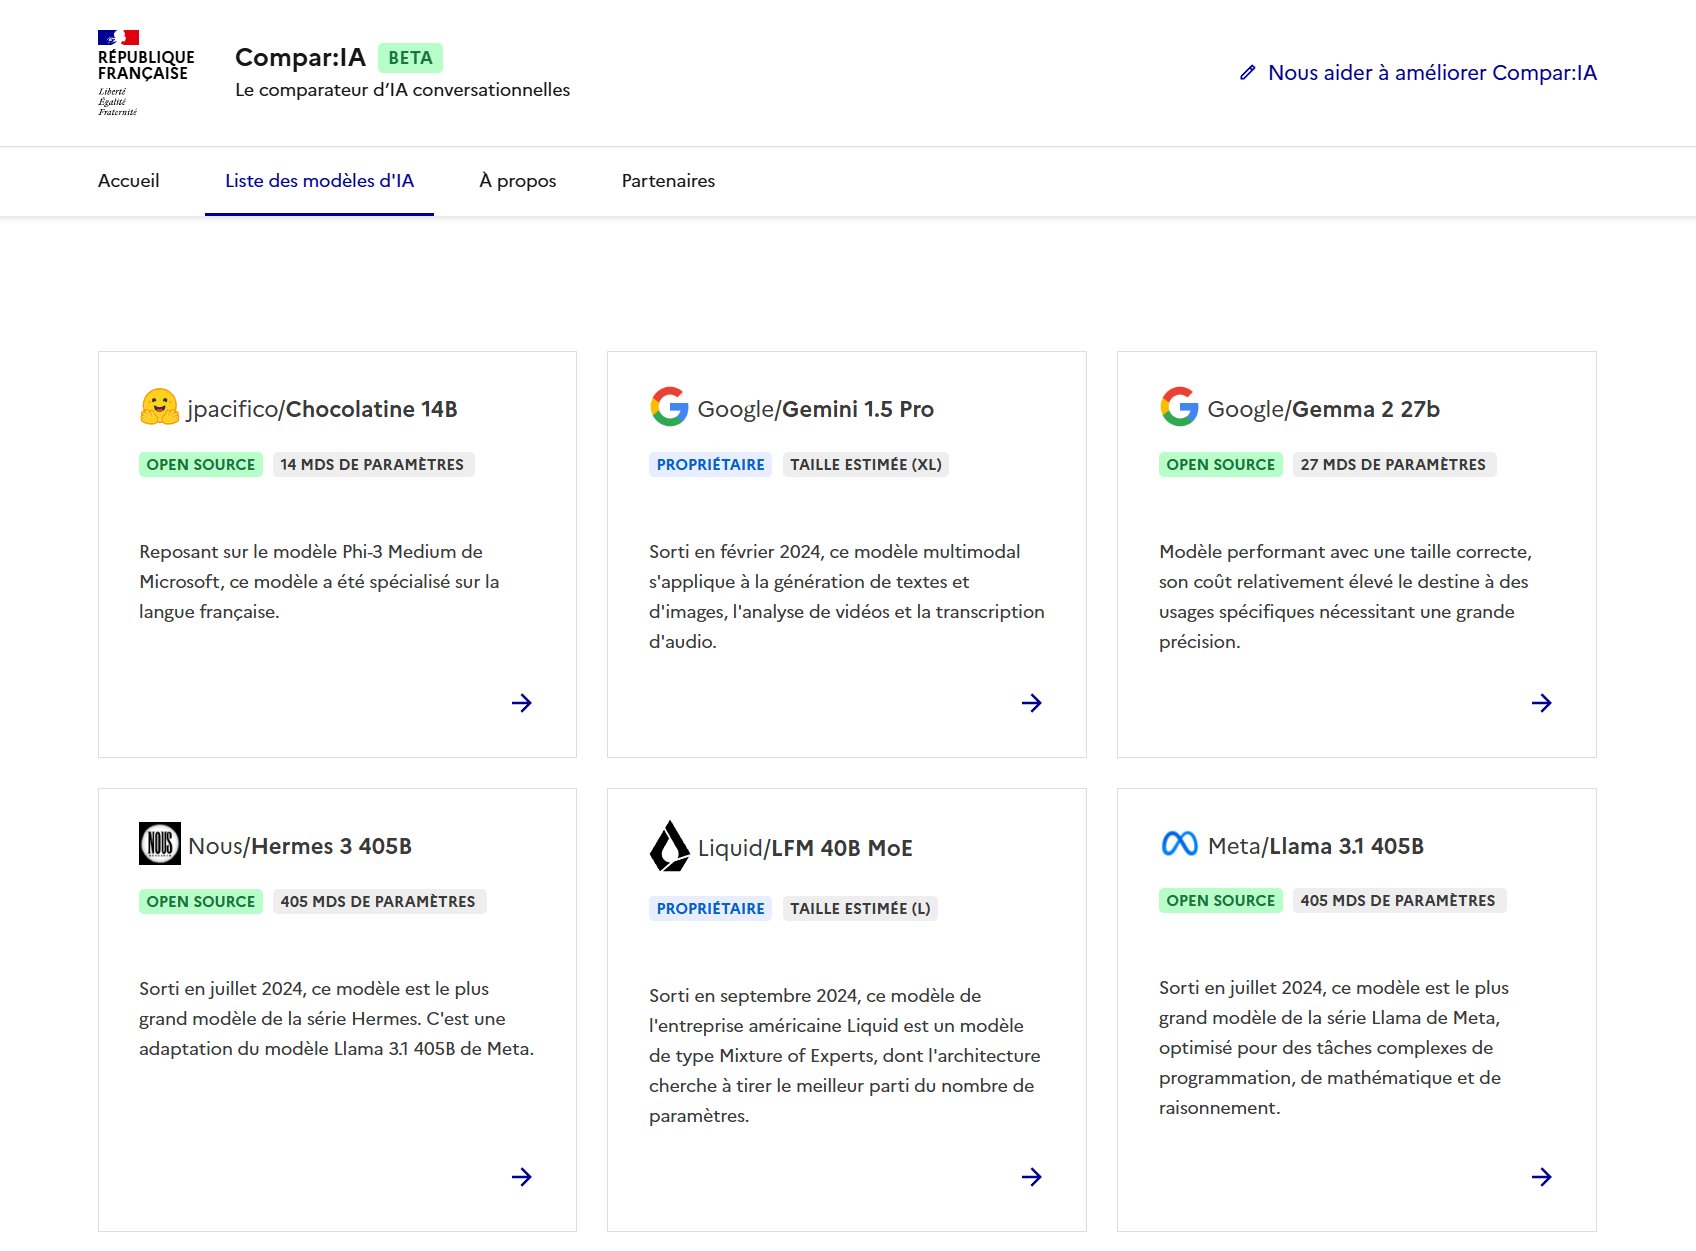
French Government Selects LFM 40B for LLM Comparison
By
–
Happy to see that LFM 40B has been selected by the French government (
@MinistereCC
) for its LLM comparison. Thanks to @_jpacifico for pointing it out (and congrats on Chocolatine). You can access it here: https://
comparia.beta.gouv.fr -

LLM Sampler: Visualizing Language Model Sampling Techniques
By
–
I also can't resist recommending LLM sampler again. It's a great website to visualize the effect of different techniques. https://
artefact2.github.io/llm-sampling/i
ndex.xhtml
… -
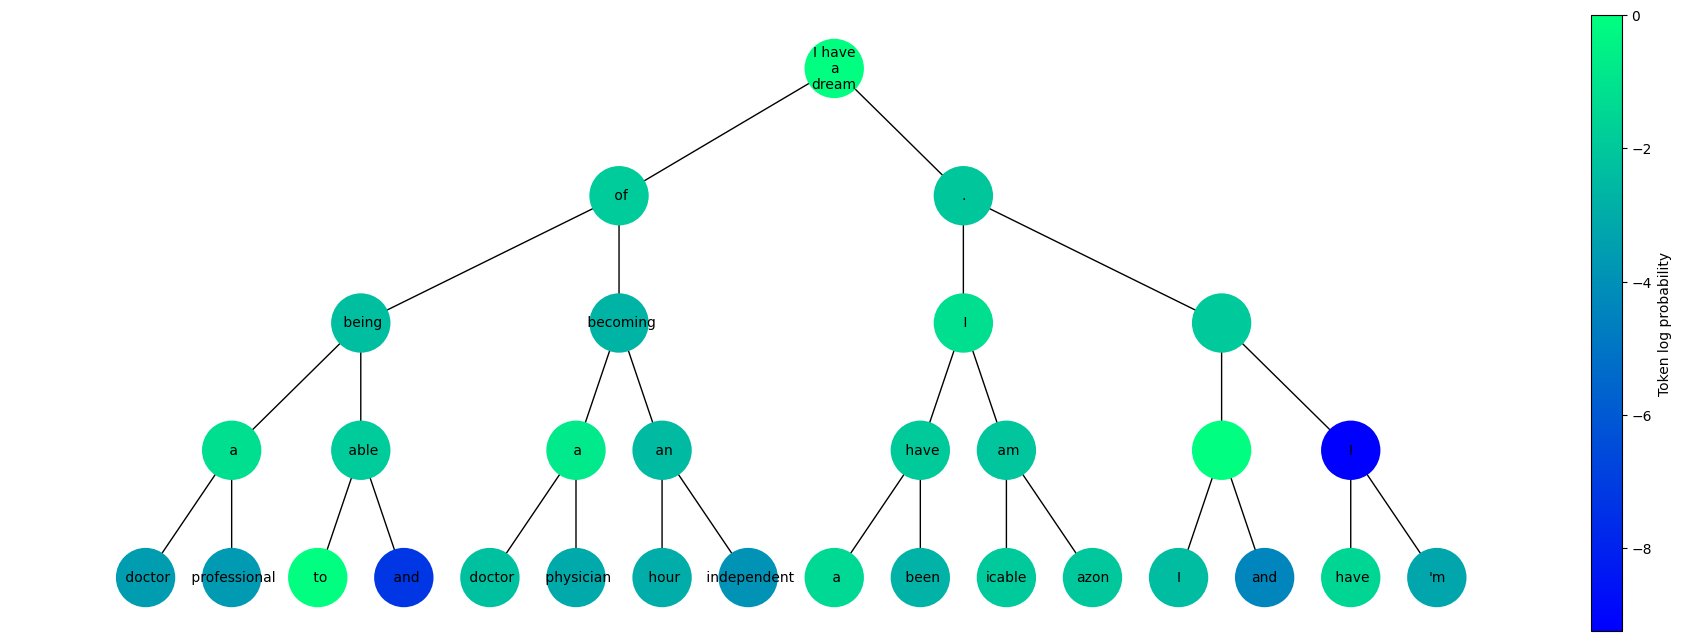
MCTS Sampling Technique Shows Promise in Language Models
By
–
I wrote it because I was playing with MCTS sampling back then. It was super slow and I didn't run evals to see if it actually performed better, but cool to see it's getting traction now.
-
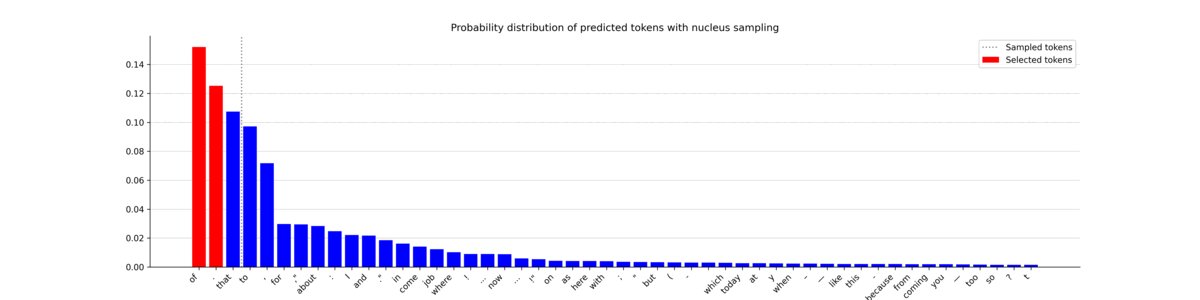
Top-k and Top-p Sampling Strategies for LLMs Explained
By
–
There's been a lot of interest around sampling recently with entropix.
— Maxime Labonne @ ICLR (@maximelabonne) 29 octobre 2024
I just uploaded my first LLM blog post to HF, which talked about top-k and top-p sampling with easy-to-understand visualizations and code.
📝 Article: https://t.co/cgoP59fED4 pic.twitter.com/DJ45ToDtPnThere's been a lot of interest around sampling recently with entropix. I just uploaded my first LLM blog post to HF, which talked about top-k and top-p sampling with easy-to-understand visualizations and code. Article: https://
huggingface.co/blog/mlabonne/
decoding-strategies
… -
ORPO vs SFT/DPO: Training Technique Comparison Analysis
By
–
I wouldn't necessarily recommend ORPO in practice vs. SFT/DPO, but 3k samples is very small.