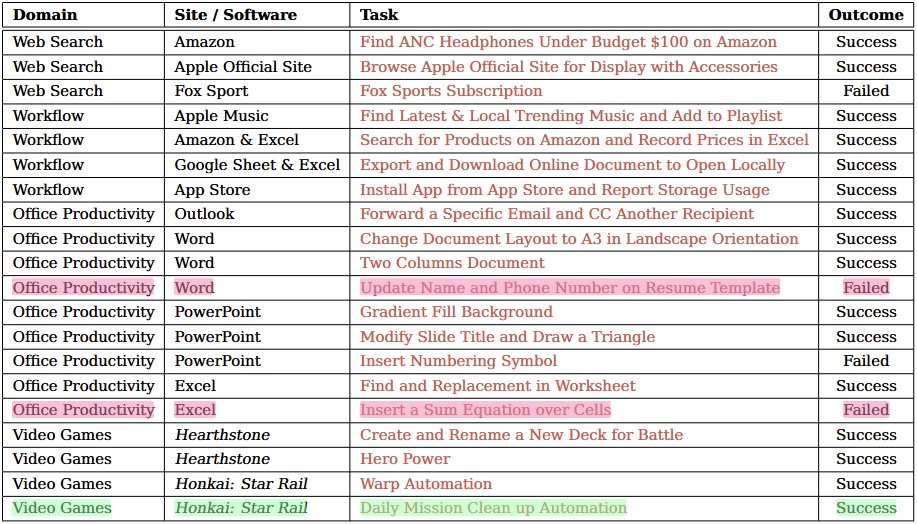
On this topic, an interesting study about Claude's agentic capabilities with GUI: https://
arxiv.org/abs/2411.10323 → Current benchmarks are too static and academic
→ Claude is bad at self-correcting mistakes
→ Honkai's daily mission is easier than Excel and Word
@maximelabonne
-
Claude’s GUI Agentic Capabilities: Benchmarks and Self-Correction Limitations
By
–
-
Claude GUI Agentic Capabilities Study Reveals Benchmark Limitations
By
–
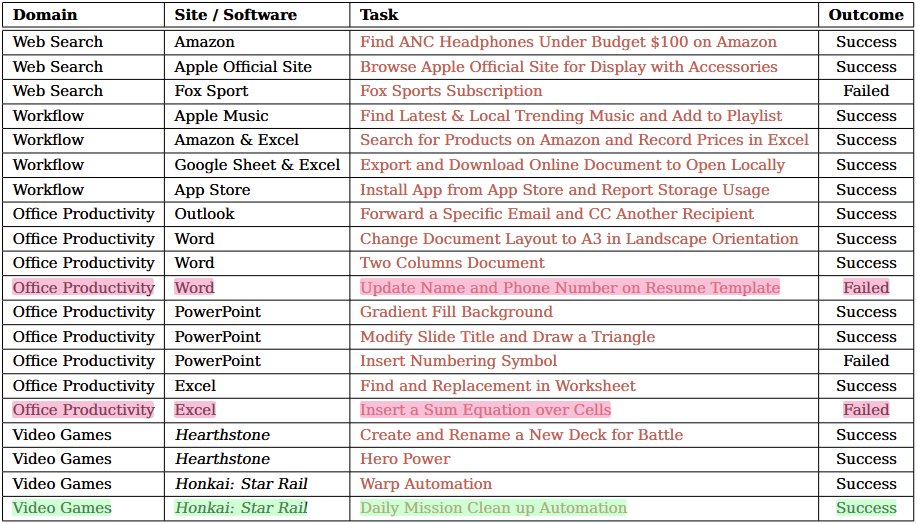
On this topic, an interesting study about Claude's agentic capabilities with GUI: https://
arxiv.org/abs/2411.10323 → Current benchmarks are too static and academic
→ Claude is bad at self-correcting mistakes
→ Honkai's daily mission is easier than Excel and Word -

9 AI datasets still dominated by humans: Value capture opportunities
By
–
Here are 9 AI datasets still dominated by humans It shows the insane amount of value left to capture Will these tasks be solved through ad-hoc LLM engineering by companies or directly by LLM providers? Thanks to @ldjconfirmed for the data!
-
Academic Paper on Language Model Optimization Omits Key Citation
By
–
Interestingly, they don't cite RLOO anywhere https://
arxiv.org/abs/2402.14740 -
Base Dataset Tag Feature Request for Dataset Management
By
–
I'd like to be able to have a "base_dataset" tag that works like "base_model". For example, this cleaned version https://
huggingface.co/datasets/mlabo
nne/orca-agentinstruct-1M-v1-cleaned
… should redirect to the original one. -

OpenCoder Releases RefineCoder Dataset and Training Pipeline
By
–
They also plan to release the pre-training dataset (RefineCoder), intermediate checkpoints, and the data cleaning pipeline. GitHub: https://
github.com/OpenCoder-llm/
OpenCoder-llm
… -

Two-stage SFT outperforms single stage setup in preference alignment
By
–
Also super interesting in terms of SFT: a two-stage setup outperforms a single stage with the same data. Curious to see if that's still the case post-pref alignment. In general, it feels like there's a missed opportunity with no experiment around DPO.
-
GitHub Stars Poor Predictor of Data Quality Due to Lack Diversity
By
–
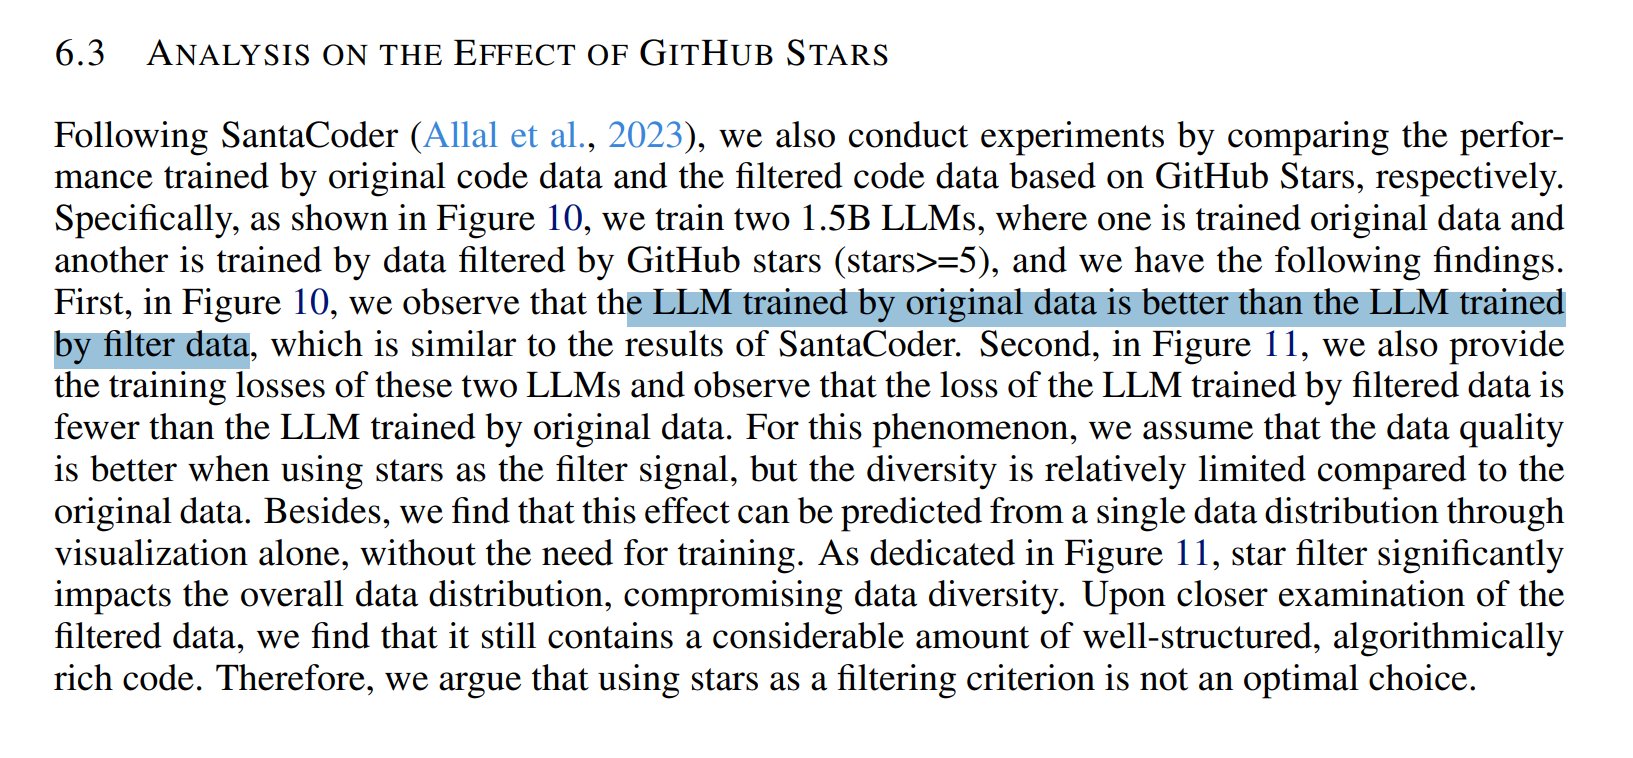
This was my favorite lesson from the SantaCoder paper: GitHub stars are poor predictors of data quality, probably because of a lack of diversity.
-
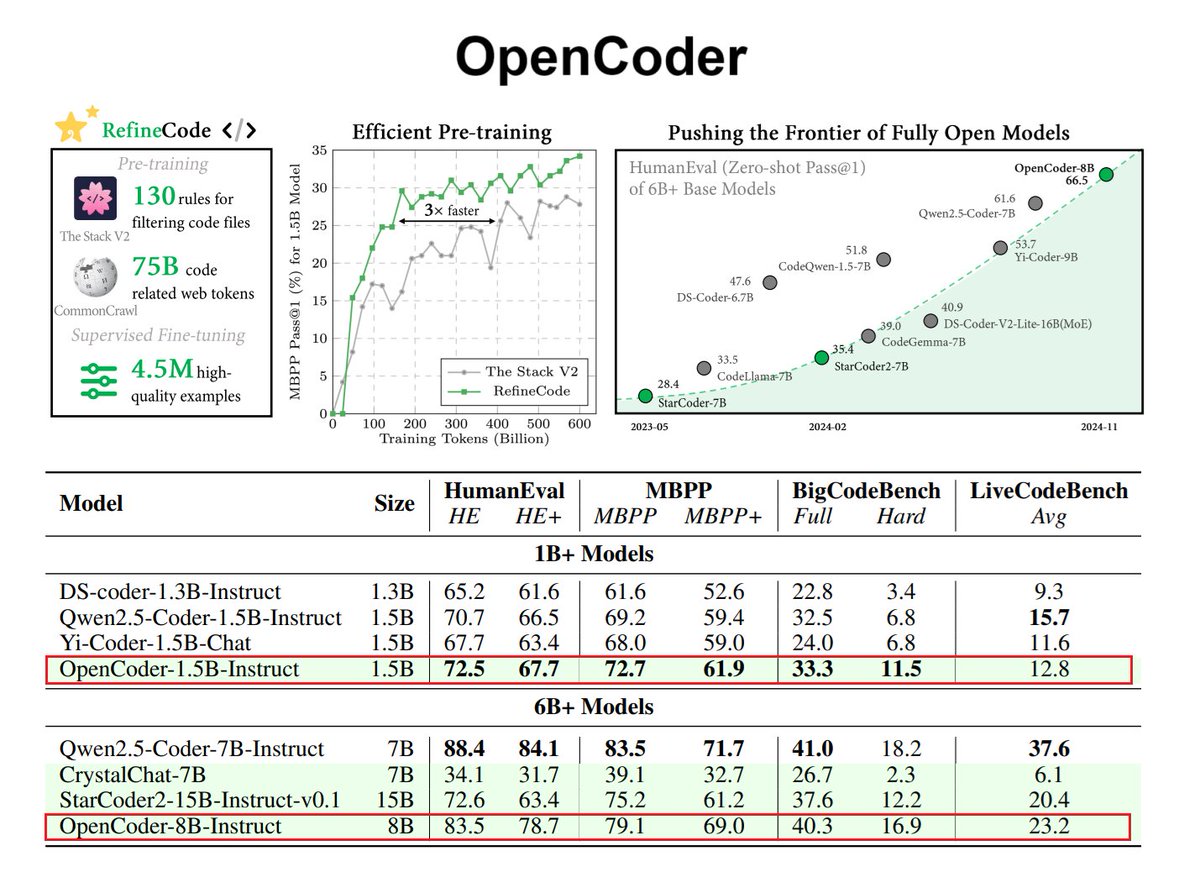
OpenCoder: Complete Open-Source Code Model Pipeline Released
By
–
OpenCoder doesn't get enough love They open-sourced the entire pipeline to create QwenCoder-level code models. This includes:
– Large datasets
– High-quality models
– Eval framework Tons of great lessons and observations in the paper Paper: https://
arxiv.org/abs/2411.04905