How superintelligent is an average intelligent human for whom time flows 1000X slower and gets to colaborate with 1000 copies? I was in convo yesterday doubting that AI can ever go beyond human when it is trained on human. Even if that were true (imo isn't) there's more+faster.
@karpathy
-
Mitigating Rare Pairings in Training Data Through Oversampling
By
–
(can be mitigated by e.g. oversampling the rare pairings during training or eventully solved with a data engine)
-
Neural Networks Exploiting Background Correlations in Price Predictions
By
–
Fun! "It appears that, even though the model predicts the same make/model for all of the images, the background can influence the predicted price by almost $10k!" Haha, neural nets are happy and eager to take advantage of all the easy correlations you allow them to latch on to 🙂
-
GitHub Copilot Dramatically Accelerates Coding Workflow
By
–
Nice read on reverse engineering of GitHub Copilot . Copilot has dramatically accelerated my coding, it's hard to imagine going back to "manual coding". Still learning to use it but it already writes ~80% of my code, ~80% accuracy. I don't even really code, I prompt. & edit.
-
FlashAttention Revert and torch.compile Integration Challenges
By
–
Ah, I reverted FlashAttention in this run because it made code messier. Will look into incorporating it back, but yes not sure how nicely it plays with torch.compile. The usual problem with taking on large dependencies you don't understand ;(
-
PyTorch Compile Optimization Reduces Iteration Time by 36%
By
–
To follow up, I had a chance to try it btw:
before: 212ms / iter
>>> model = torch.compile(model)
after: 135ms / iter
nice 🙂 -
Introducing #lossfunctiontumblr hashtag for Twitter discussions
By
–
let's introduce a hashtag and just use twitter? how about #lossfunctiontumblr ? 🙂
-
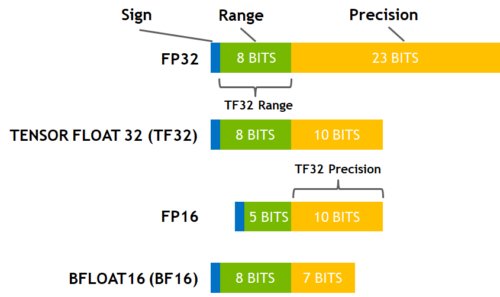
Mixed Precision Training: Complexity Beyond High Level Concepts
By
–
the high level picture is easy enough but keeping track of the mixed precision around the whole network, the dynamical behavior of the values and ranges, the support for them and their conversions across all the various kernels and library versions everywhere, is the nightmare
-
FP16 Efficiency and Gradient Scaling Considerations
By
–
yeah fp16 is a little more efficient atm for the code as I have it right now but then need gradient scaler ;s
-
Splitting minGPT into educational and efficient versions
By
–
Context I realized I have to split up minGPT because I can't properly simultaneously satisfy both 1) educational and 2) efficient in one repo. So I'm separately writing 1) the maximally educational minGPT (+video etc.) and 2) a more efficient (still ~clean) version that has teeth