Rough example, a decent GPT-2 (124M) pre-training reproduction would be 1 node of 8x A100 40GB for 32 hours, processing 8 GPU * 16 batch size * 1024 block size * 500K iters = ~65B tokens. I suspect this wall clock can still be improved ~2-3X+ without getting too exotic.
@karpathy
-
Future Plans for GPT-2 Implementation and Educational Content
By
–
I'd like to continue to make it faster, reproduce the other GPT-2 models, then scale up pre-training to bigger models/datasets, then improve the docs for finetuning (the practical use case). Also working on video lecture where I will build it from scratch, hoping out in ~2 weeks.
-
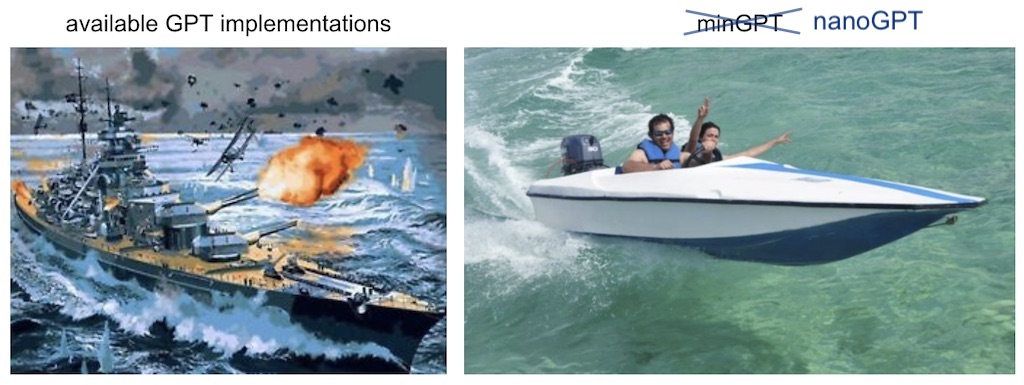
nanoGPT: Simplest Repository for Training Medium-Sized GPTs
By
–
Didn't tweet nanoGPT yet (quietly getting it to good shape) but it's trending on HN so here it is 🙂 : https://
github.com/karpathy/nanoG
PT
…
Aspires to be simplest, fastest repo for training/finetuning medium-sized GPTs. So far confirmed it reproduced GPT-2 (124M). 2 simple files of ~300 lines -
Long-term work on arxiv-sanity project iterations
By
–
for sure! would love to know a bit more under the hood. I've working on this problem for a _long_ time, arxiv-sanity versions 1,2,3,4,5 and all 😀
-
Encoding Mistakes in Retrieval-Augmented Models
By
–
or prompts, e.g. in retrieval-augmented models. but only if you call your `.encode()` wrong 🙂
-
Andrej Karpathy announces Zero to Hero course project
By
–
working on it! https://
karpathy.ai/zero-to-hero.h
tml
… -
Data Augmentation: Trivial in Vision, Non-Trivial in NLP
By
–
yes, the difference is data augmentation, which is trivial in vision and non-trivial in NLP
-
Chinchilla’s implications: Dataset size over model size in LLMs
By
–
Great post (5mo ago) "chinchilla's wild implications" giving context to LLM goldrush shifting from model size to dataset size following Chinchilla https://
lesswrong.com/posts/6Fpvch8R
R29qLEWNH/chinchilla-s-wild-implications
…
Subtle important detail: analysis assumes 1 epoch. Recent work (e.g. Galactica) gives hope for 1+ regime. -
MAML Meta-Learning and Software Architecture Design Principles
By
–
reminds me of MAML meta-learning (
https://
arxiv.org/abs/1703.03400) where the objective is to find weights of a network such that any new task finetunes fast. In Software 1.0 land, equivalent is writing code such that any new desired functionality is simple and doesn't need a refactor.