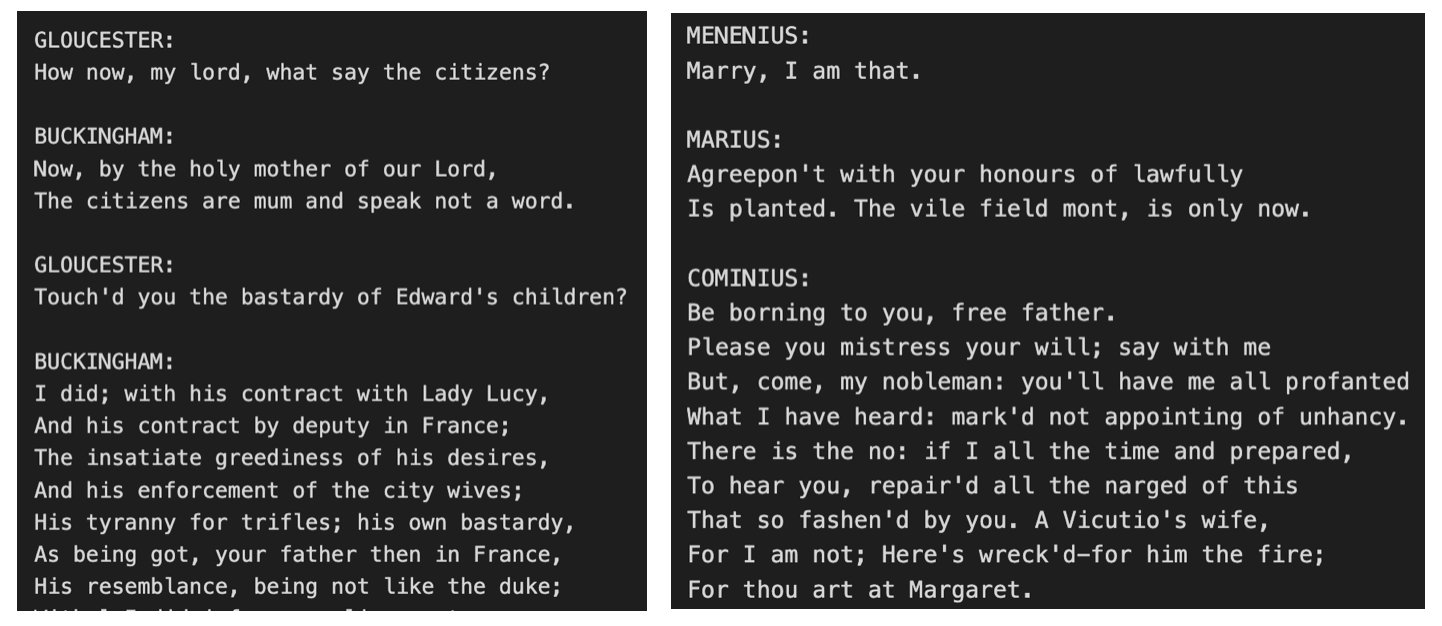
We get a ~10M parameter model trained for about 15 minutes on 1 GPU on all of Shakespeare concatenated into one 1MB file. We then sample infinite fake Shakespeare from our baby GPT. Can you spot which one is real? At only 10M params on 1M characters, from-scratch, I hope so 🙂
@karpathy
-

Building Transformers: Self-Attention, Training, and GPT-3 Comparison
By
–
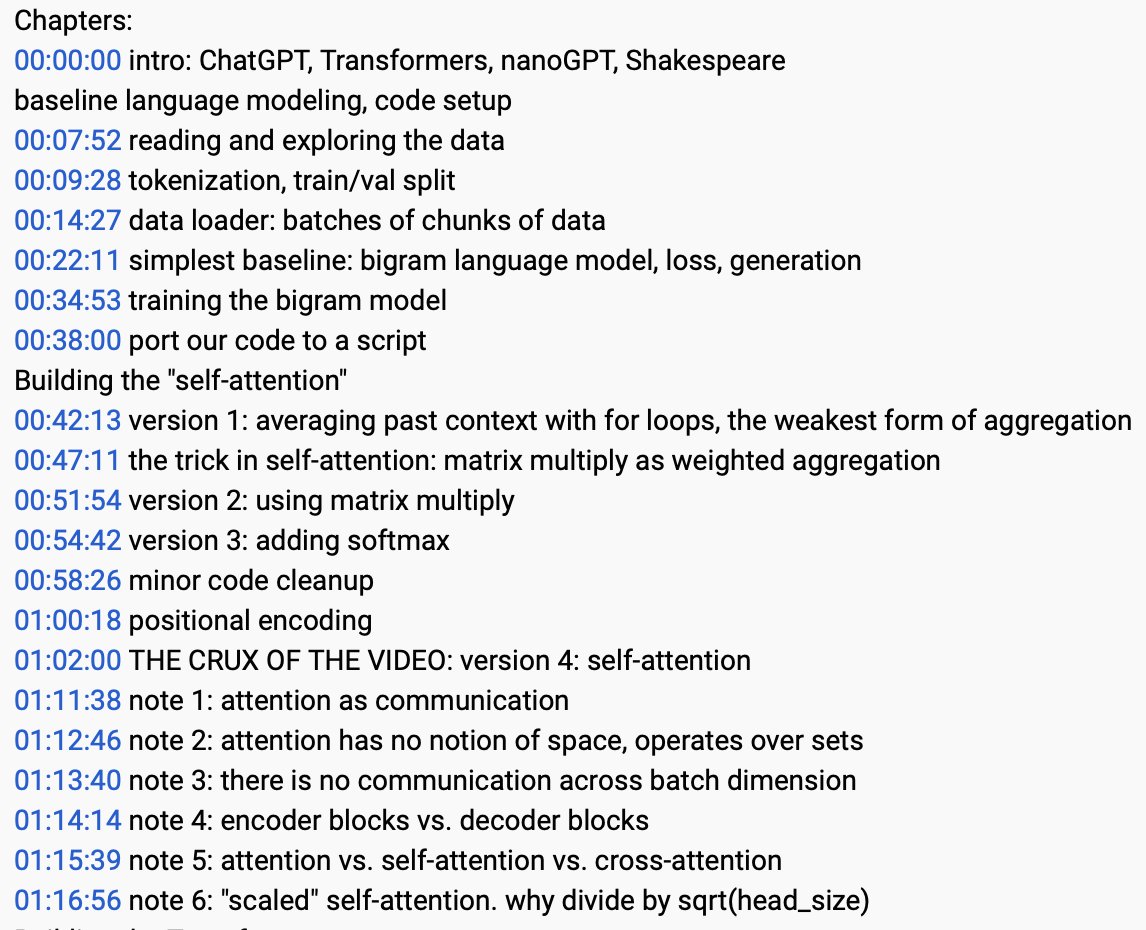
The second ~1hr builds up the Transformer: multi-headed self-attention, MLP, residual connections, layernorms. Then we train one and compare it to OpenAI's GPT-3 (spoiler: ours is around ~10K – 1M times smaller but the ~same neural net) and ChatGPT (i.e. ours is pretraining only)
-
Transformer Attention Mechanism: Baseline Model and Message Passing Introduction
By
–
First ~1 hour is 1) establishing a baseline (bigram) language model, and 2) introducing the core "attention" mechanism at the heart of the Transformer as a kind of communication / message passing between nodes in a directed graph.
-
Computer CoPilot Vision Now Tractable Through Text Translation
By
–
Computer CoPilot. Was very much the vision with OpenAI Universe https://
openai.com/blog/universe/ , though it was too early. Now feels tractable if you translate everything to/from text (e.g. like in WebGPT). Could be built e.g. as an extension of natbot https://
github.com/nat/natbot -
Essential Skills for Learning: Programming, Tensors, Math Basics
By
–
solid programming, familiarity (/willingness to learn) tensor processing (numpy or torch tensor), small few concepts from basic math and statistics (e.g. function gradient, gaussian distribution, etc.). I'll list this out on the page, ty.
-
Comparing Modern GPT Models to OpenAI’s Early GPT-2 Capabilities
By
–
It’s about as good as OpenAI’s baby GPT-2 from ~4 years ago. (Their paper at that time had models from 124M to 1.3B). Today’s bleeding edge GPTs reach scale (in model size and data size) that requires significant infrastructure and further finetuning to align them (RLHF etc).
-
Evolution from search engines to answer engines and beyond
By
–
Tired: search engine
Wired: answer engine
Inspired: ???
🙂 -
LLMs Need External Tools Like Humans Need Interaction
By
–
LLMs are like a person doing everything just in their head. People wouldn’t get very far like that alone. LLMs wouldn’t either.
-
Clarification on GPT-2 Model Size: 124M vs 1.3B Parameters
By
–
Careful this is the 124M model. The biggest GPT-2 was 1.3B
-
Neural Networks: Zero to Hero Series – Building Networks from Scratch
By
–
(This will be part of my ongoing series Neural Networks: Zero to Hero https://
karpathy.ai/zero-to-hero.h
tml
… , on building neural networks, from scratch, in code. I have tweeted some of these videos individually already)