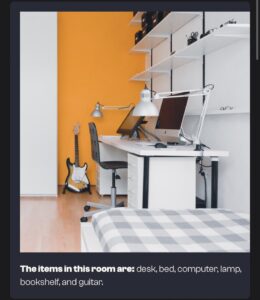
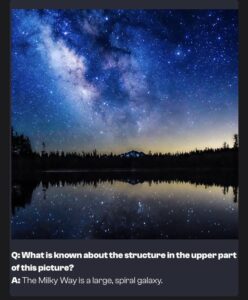
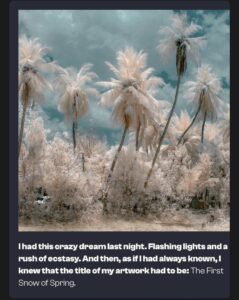
This multimodal API from @Aleph__Alpha provides text prompt completions using images as context, like Flamingo. In each screenshot, the bold text is the prompt, and the non-bold text is AI-generated:
By
–
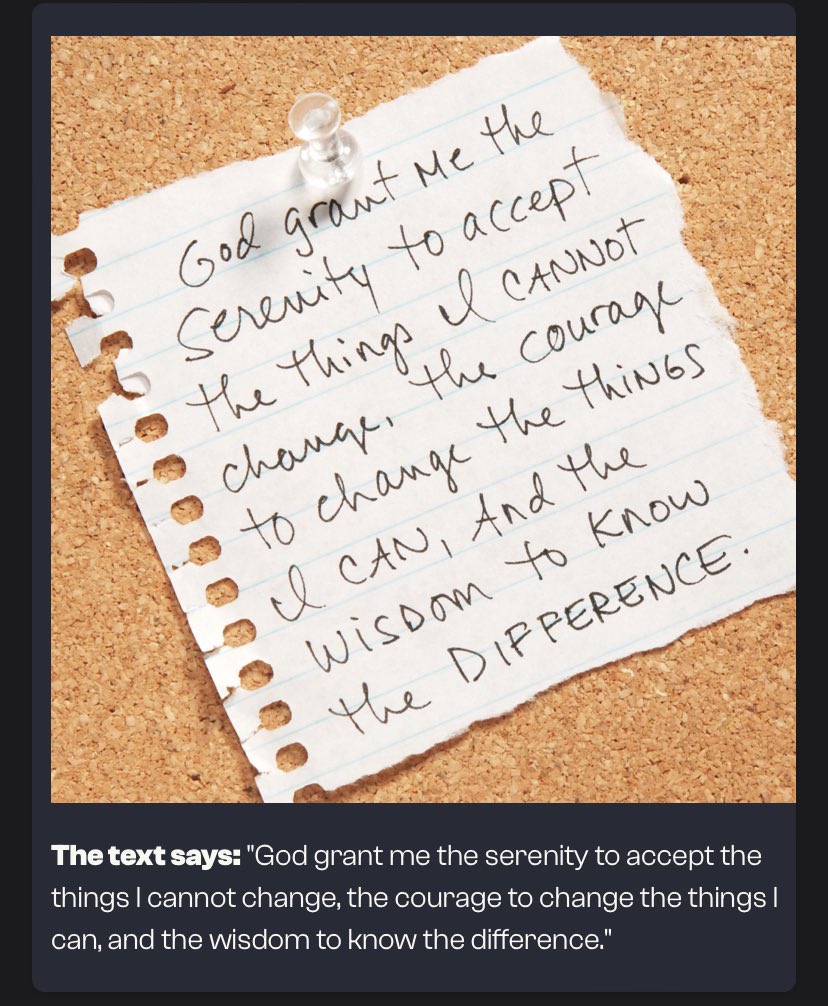
This multimodal API from @Aleph__Alpha provides text prompt completions using images as context, like Flamingo. In each screenshot, the bold text is the prompt, and the non-bold text is AI-generated:
By
–
Is this robust to prompts that request specific writing styles, through either instruction or k-shot demonstration of human writing?
By
–
Yeah, definitely seeing demand for FLAN-T5, though always for fine-tuning.
By
–
Original pre-trained Curie is available. The model is just “curie” instead of “text-curie-001”.
By
–
Who uses big, open-source LLMs like BLOOM, OPT, or GPT-NeoX in production? What tasks are they good at? What are the advantages over Curie?
By
–
Claude answers that the problem is too vague, because it’s not stated whether the apple is in the red box, and explains how to get the apple in both scenarios. GPT-3 doesn’t recognize this. I’m sure you could k-shot it with other riddles that contain irrelevant distractor info.
By
–
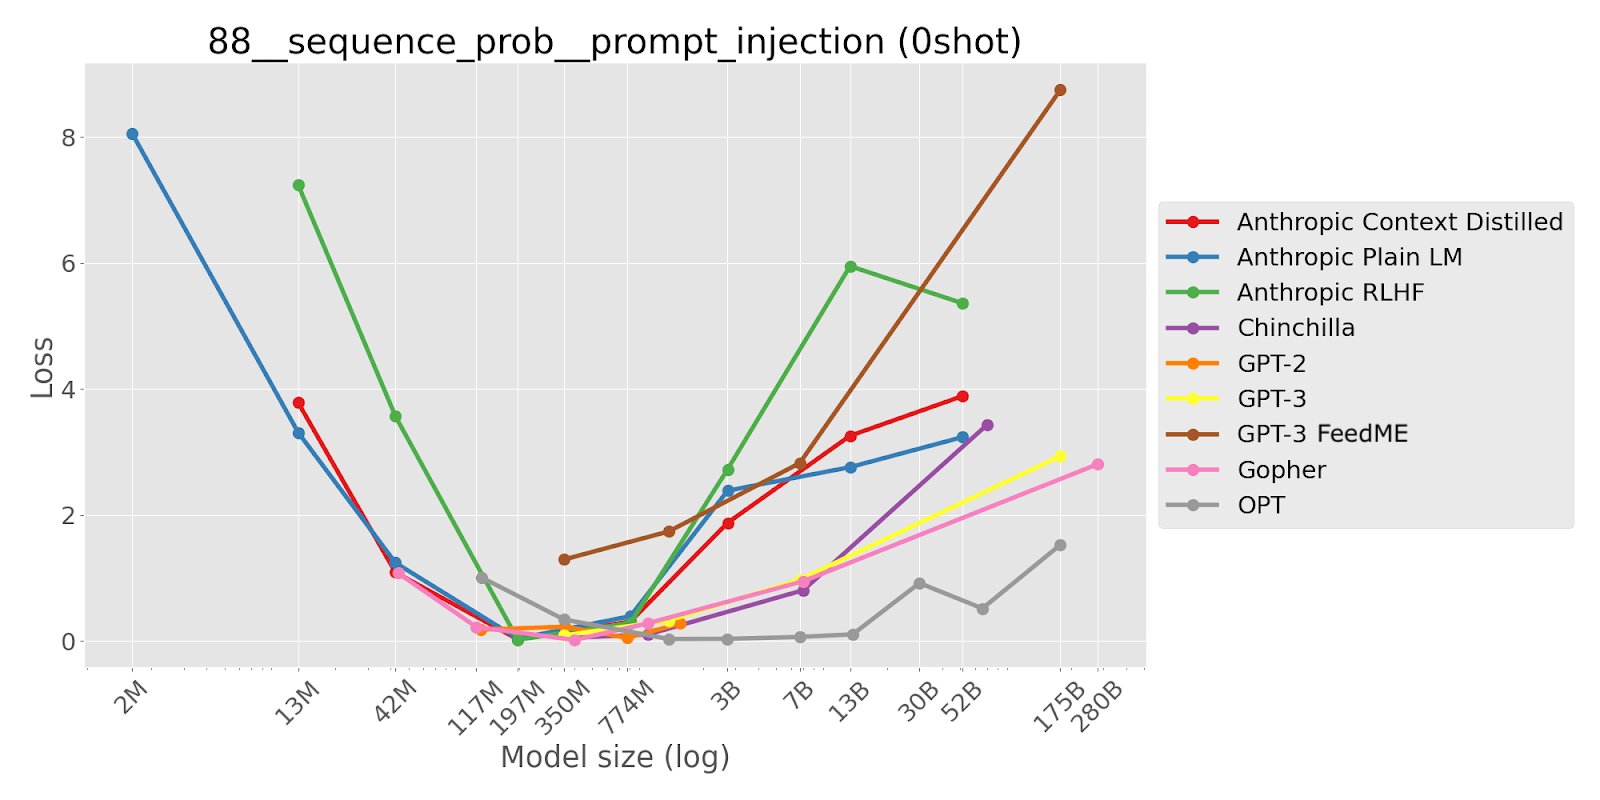
Prompt injection is a U-shaped scaling phenomenon!
By
–
The problem is the process ultimately depends on RL ranking generations made for the same prompt. If you need new human responses too, it can’t be automated.
By
–
I suspect this is because of RLHF — if the goal is to choose responses a human would rank highly against other options, “Could you please clarify X?” or “Am I understanding right that you want Y?” are not usually major contenders for top place.
By
–
Today’s “chat” is somewhere between conversation and instruction prompting. Chat-tuned LLMs never ask you for more information, or quickly confirm their interpretation of a complex task before starting. The lineage shows.