Instruction tuning makes this less essential a mental model than it used to be with pre-trained LLMs. You’re still “sculpting,” but you’re usually sculpting the data manifold RLHF-evaluated generations.
@goodside
-
k-shot learning constrains distribution over next tokens
By
–
It models a distribution over next tokens, yes — in a k-shot, each added example (ideally) constrains the distribution better. You’re appending to a search query in possible-text space that returns a more specific subset of texts.
-
Stable Diffusion terms full sentence prompts as ‘boomer prompts’
By
–
TIL in stable diffusion circles, where long lists of keyword tags are the norm, prompts with full English sentences are called "boomer prompts"
-
Claude vs ChatGPT comparison blog post by @goodside
By
–
If you haven't seen Claude in action, check out my blog post for @Scale_AI comparing Claude to ChatGPT: https://
scale.com/blog/chatgpt-v
s-claude
… -
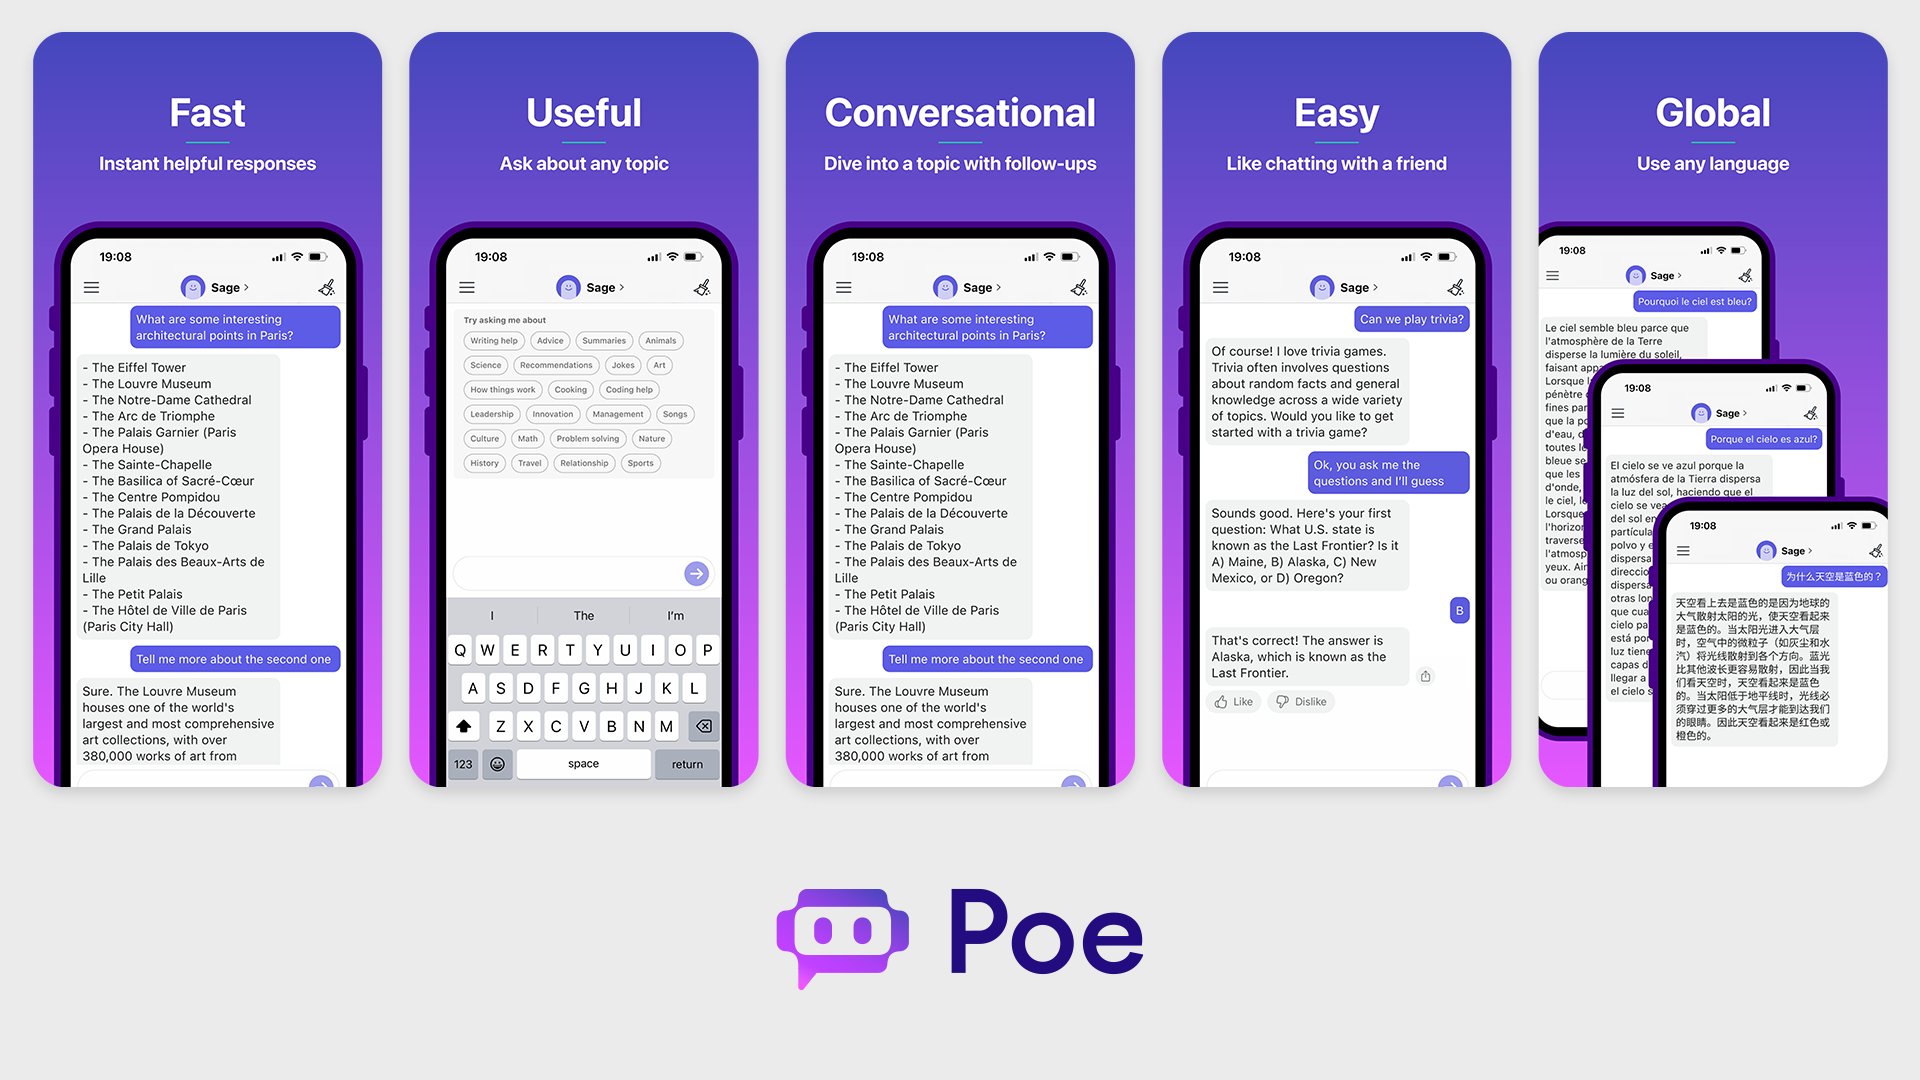
Poe iOS chat includes OpenAI and Anthropic Claude-like Heron bot
By
–
Poe chat is out on iOS, and includes *both* OpenAI and Anthropic models! If you want to talk to Claude (Anthropic's competitor to ChatGPT) install Poe and use the "Heron" bot — if it's not Claude, it's something very similar.
-
ChatGPT as synecdoche for all GPT-3 models bothers user
By
–
This bothers me too but I've given up on it. People outside LLMs use "ChatGPT" as a synecdoche for all GPT-3 models.
-
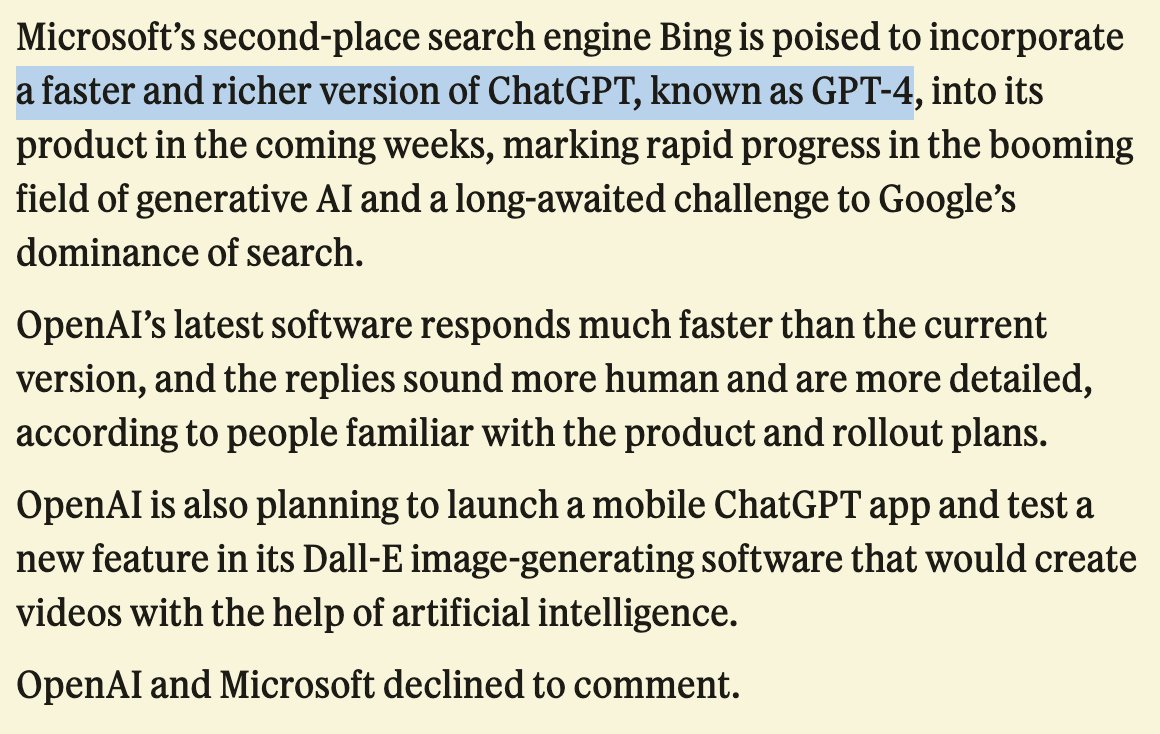
Microsoft Bing to incorporate OpenAI GPT-4, Semafor reports
By
–
Semafor reports Microsoft Bing will incorporate OpenAI's GPT-4: https://
semafor.com/article/02/01/
2023/chatgpt-is-about-to-get-even-better-and-microsofts-bing-could-win-big
… -
OpenAI releases web-only AI text detector
By
–
OpenAI just released a tool (web only, no API) for detecting AI-written text: https://
openai.com/blog/new-ai-cl
assifier-for-indicating-ai-written-text/
… -
Research sandbox for measuring functional correctness of generated code
By
–
In research contexts, inside a sandbox, to measure functional correctness of generated code e.g. in the original Codex paper: https://
arxiv.org/abs/2107.03374 -
Warning: Don’t run eval() on LLM-generated code without sandbox
By
–
PSA: Don’t run eval() on LLM-generated code outside of a sandbox VM, especially if you’re generating code with untrusted user input in the prompt.