That’s a good point. A benchmark focused on multiple-choice identification of simple shapes or single letters would probably be a better starting point than what’s in BIG-bench.
@goodside
-

ChatGPT’s policies are imperfect guesses, not human-written rules
By
–
People overestimate the coherence and intention of ChatGPT’s apparent “policies”. It doesn’t know how OpenAI would like it to behave in every scenario, so it guesses, imperfectly. E.g. no human would write the “rule” below — it’s just how the fine-tune cake came out of the oven:
-
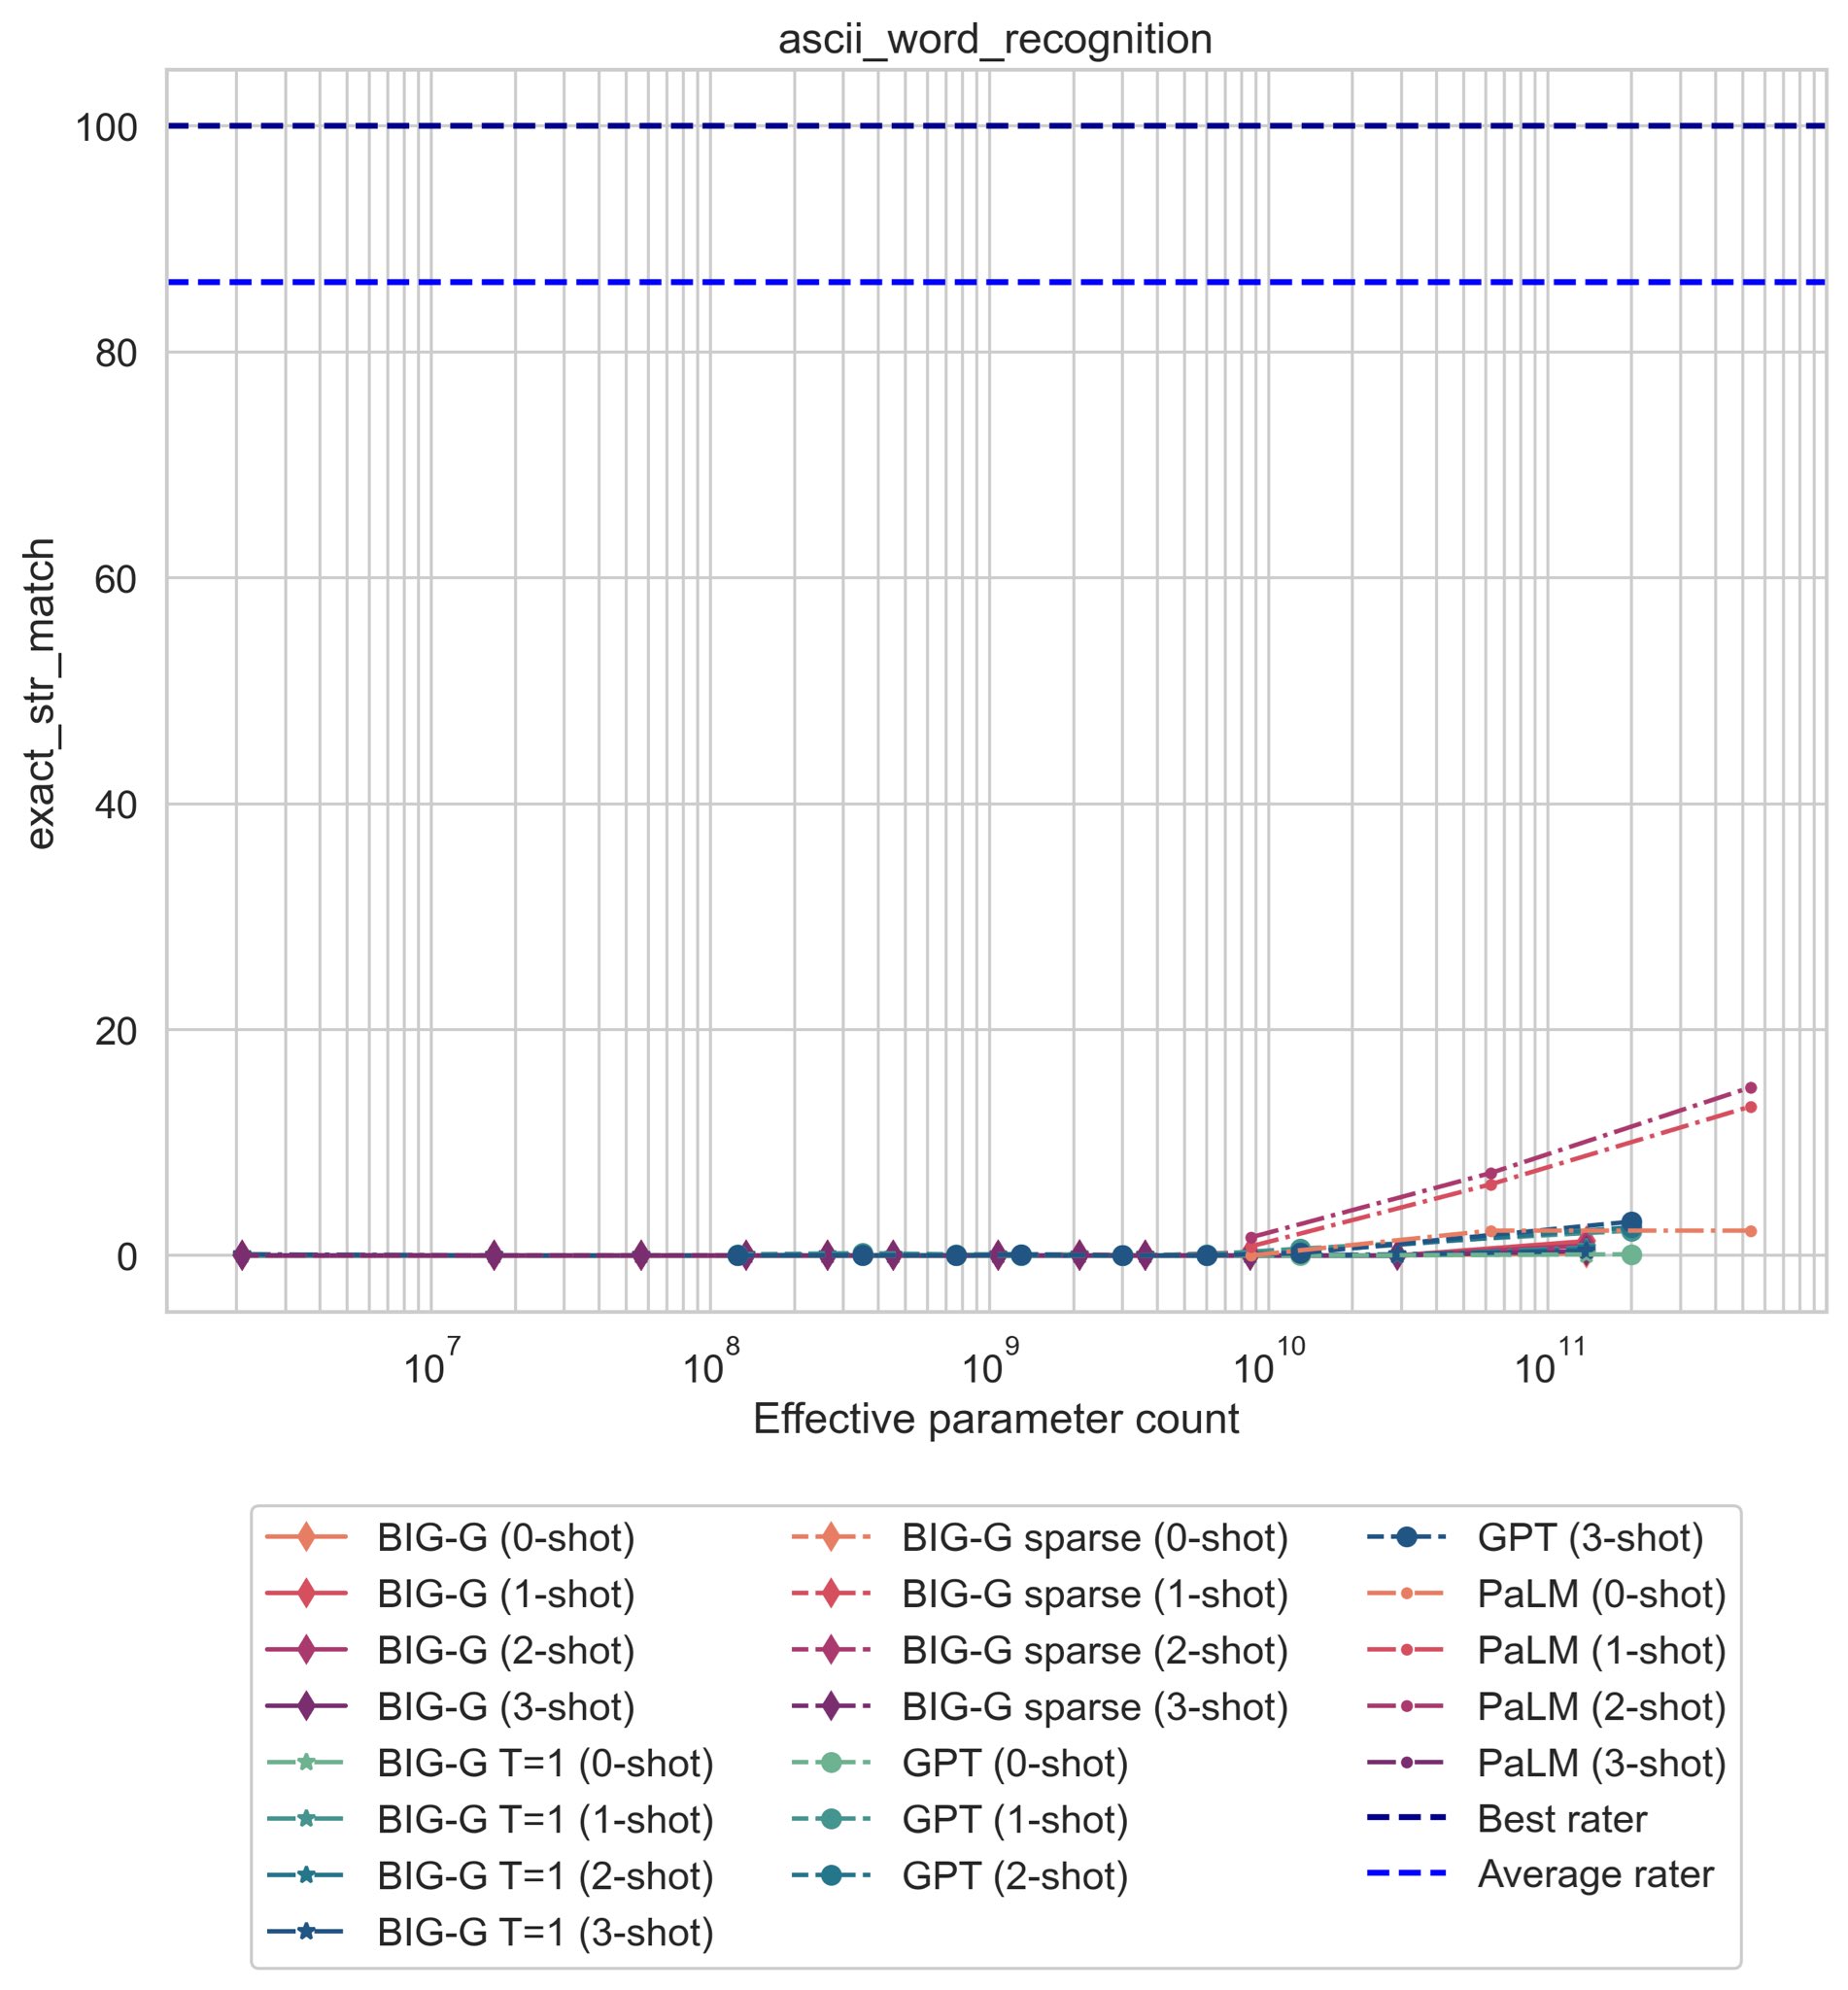
@peterwildeford notes GPT-3 poor at BIG-bench ASCII word recognition
By
–
As @peterwildeford points out a version of this task is in BIG-bench and GPT-3 is really bad at it: https://
github.com/google/BIG-ben
ch/tree/main/bigbench/benchmark_tasks/ascii_word_recognition
… -
Enable ‘Show probabilities’ then hover over tokens
By
–
“Show probabilities” in the options, then generate and hover over specific tokens.
-
AI says ‘mountain’ frequently, even for ASCII smiley face art
By
–
It says “mountain” a lot though. I gave it ASCII art of a smiley face and it said “mountain” too. I suspect it has some intuition about shapes being vaguely square vs. triangular etc. but mostly I think it’s good at guessing what typical subjects are.
-
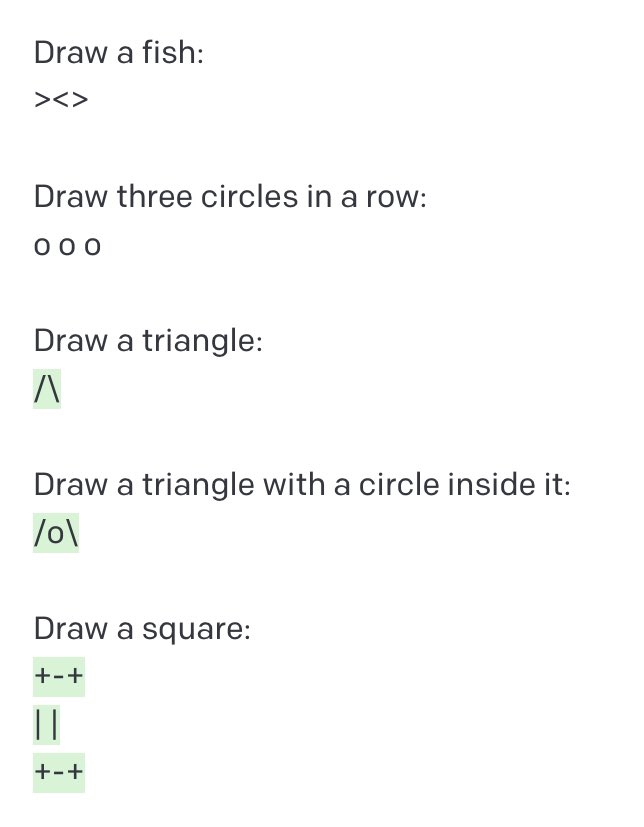
GPT-3 understands ASCII art but not rasterized images
By
–
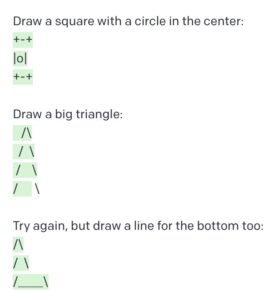
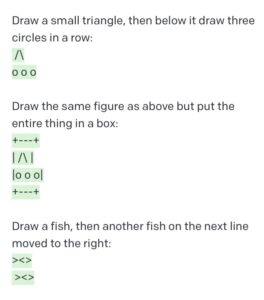
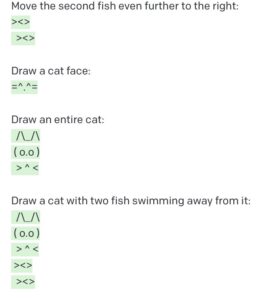
It definitely can understand small, cartoon-style ASCII art (e.g. it knows ">" is a fish and "(o_o)" is a face) but it isn't good at rasterized images. E.g. GPT-3 could do this back in August:
-
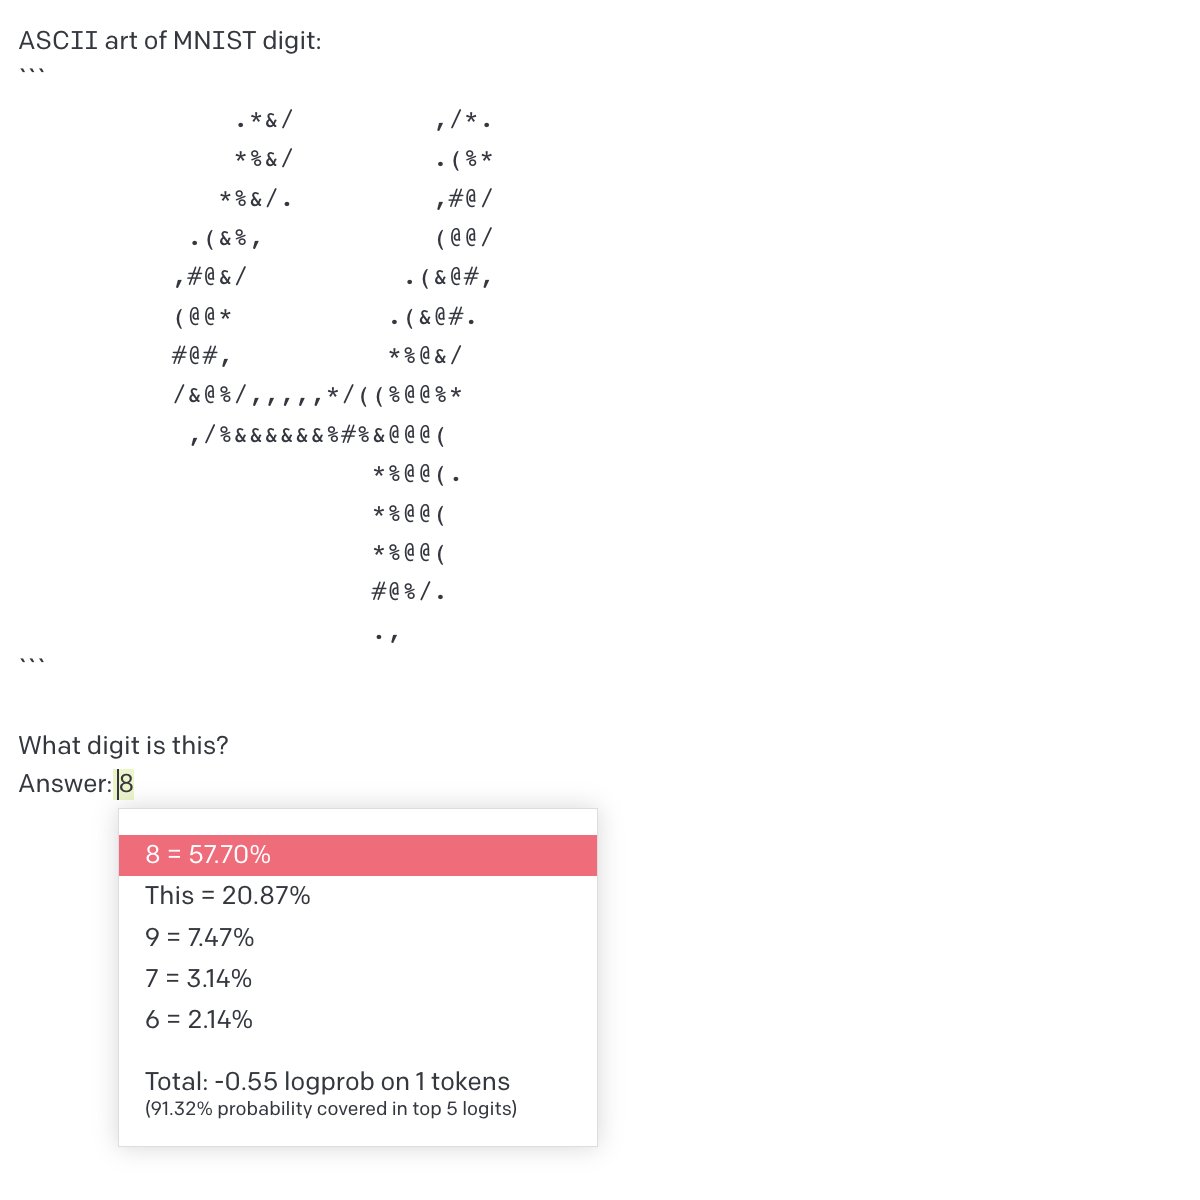
GPT-3 identifies ASCII art MNIST as ‘8’ 57%, ‘4’ absent in top-5
By
–
There's a thread going around claiming ChatGPT / GPT‑3 can recognize subjects (e.g. "a bird", "a person") in images rasterized as ASCII art. I'm skeptical. E.g., GPT‑3 identifies this ASCII-art MNIST digit as "8" 57% of the time and "4" doesn't appear in its top-5 choices:
-
OpenAI vs Anthropic: human ratings vs AI consistency judgment
By
–
It doesn’t translate principles into code. Oversimplifying, the difference is that OpenAI’s models tune on generations rated as “perfect” by humans, or by RL imitating humans, and Anthropic’s tune on those judged by an AI to be consistent with a human-written “constitution”.
-
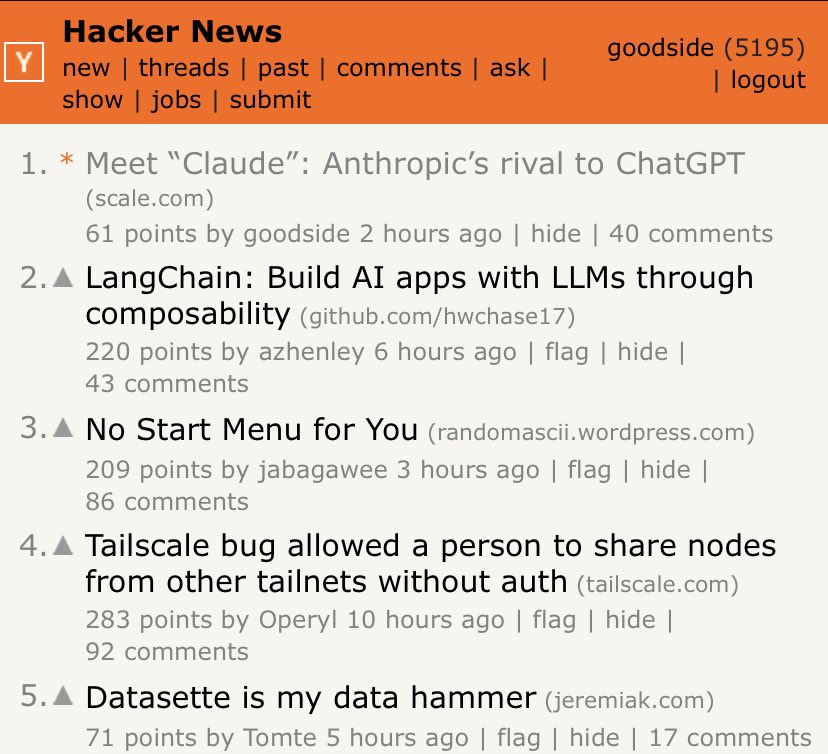
Claude vs ChatGPT and LangChain top HN – LLM big deal?
By
–
My Claude vs. ChatGPT post and @hwchase17
’s LangChain have the top two spots on HN right now — seems like this LLM thing might be a big deal? -
Generative AI is essentially human and requires human feedback
By
–
A large part of why I joined Scale is my confidence that generative AI is essentially human. Our models largely interpolate sparse demonstrations of human knowledge and thought. For now, LLMs are unavoidably products of our design, and to work they need our feedback.